Question: What additional economic information belongs in a factor model, and when is a historical return pattern useful for an investor?
The three-factor model separates market, size and value exposures. We extend it using a valuation argument: expected profitability and the investment required to support it matter alongside the price paid. This motivates FF5, while momentum, reversal and beta-sorted portfolios reveal both additional patterns and the limits of a single model.
The chapter moves from economic motivation to empirical comparison, then to replication, trading frictions and implementation. Its final rolling regressions show how uncertain and time-varying exposures can be. The next chapter uses that framework to study Avantis and a momentum ETF.
By the end you should be able to distinguish gross profitability from FF5 operating profitability, compare model-relative alphas, separate discovery from investability, and explain why an ETF cannot be assumed to reproduce an academic factor spread.
Prerequisite: the factor construction and regressions in Chapter 3. Sections 1–3 and 6–8 form the main route to the ETF case study. Reversals and the beta anomaly in Sections 4–5 are deeper examples of empirical-model evaluation.
Previous: The three-factor model · Next: From research to Avantis ETFs
Source
# ============================================================================
# Setup: Import Libraries
# ============================================================================

import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
import seaborn as sns
from scipy import stats
import statsmodels.api as sm
from statsmodels.stats.stattools import jarque_bera


try:
    plt.style.use('seaborn-v0_8-darkgrid')
except OSError:
    plt.style.use('default')
sns.set_palette("husl")
plt.rcParams["font.family"] = "DejaVu Sans"
np.random.seed(42)

print("Libraries imported successfully!")
from analysis_utils import AS_OF, END_EXCLUSIVE, load_french, load_prices, monthly_returns, coverage, fit_hac, mean_hac, nw_lags, load_beta_portfolios
Libraries imported successfully!
Setup: Load Factor and ETF Data
Before diving into the theory and analysis, we need to assemble our dataset. We download:
Fama-French factor returns (3-factor, 5-factor, momentum, short-term and long-term reversal) from Kenneth French’s data library
ETF price data (SPY, IWN, VTV) from Yahoo Finance — the same three ETFs used in the 3-Factor Tutorial
The combined dataset spans 2000–latest released month, a longer sample than the introductory notebook. The additional years are deliberate: momentum crashes, value drawdowns, and other regime changes require a longer history to observe.
Factor-only plots begin in 2000; ETF comparisons begin at the common available return month (VTV launched in 2004). FF3 and Carhart use the original FF3 SMB, while FF5 uses its own SMB. They are therefore not strictly nested: R² need not increase when switching from the original FF3 to FF5. Returns use adjusted month-end closes and current-vintage French releases. See Notebook 3 for the CIZ methodology change.
Source
download_ff_csv = load_french

# --- 3-Factor data ---
print("Downloading Fama-French 3-Factor data...")
ff3 = download_ff_csv("F-F_Research_Data_Factors_CSV.zip")
ff3.columns = ['Mkt_RF', 'SMB', 'HML', 'RF']

# --- 5-Factor data ---
print("Downloading Fama-French 5-Factor data...")
ff5 = download_ff_csv("F-F_Research_Data_5_Factors_2x3_CSV.zip")
ff5.columns = ['Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA', 'RF']

# --- Momentum factor ---
print("Downloading Momentum factor (UMD)...")
mom = download_ff_csv("F-F_Momentum_Factor_CSV.zip")
mom.columns = ['UMD']

# --- Short-Term Reversal factor ---
print("Downloading Short-Term Reversal factor (ST_Rev)...")
st_rev = download_ff_csv("F-F_ST_Reversal_Factor_CSV.zip")
st_rev.columns = ['ST_Rev']

# --- Long-Term Reversal factor ---
print("Downloading Long-Term Reversal factor (LT_Rev)...")
lt_rev = download_ff_csv("F-F_LT_Reversal_Factor_CSV.zip")
lt_rev.columns = ['LT_Rev']

# Merge everything on the common date index
factors = ff5.copy()
factors = factors.join(mom, how='inner')
factors = factors.join(st_rev, how='inner')
factors = factors.join(lt_rev, how='inner')

# Filter to analysis period
factors = factors.loc['2000-01-01':].join(ff3['SMB'].rename('SMB_FF3'), how='inner')
coverage('US combined factor sample', factors)

print(f"Combined factor dataset: {factors.shape[0]} months, {factors.shape[1]} columns")
print(f"Date range: {factors.index[0].date()} to {factors.index[-1].date()}")
print(f"Columns: {list(factors.columns)}")
print(f"\nFirst 5 rows:")
print(factors.head())

def run_ff_regression(y, X_cols, data, model_name="Model", stock_name="Stock"):
    columns = list(X_cols)
    if columns in [['Mkt_RF', 'SMB', 'HML'], ['Mkt_RF', 'SMB', 'HML', 'UMD']]:
        columns = ['SMB_FF3' if c == 'SMB' else c for c in columns]
    target = data['Stock_Excess_Return'] if y is None else y
    return fit_hac(target, data[columns])
Downloading Fama-French 3-Factor data...
Downloading Fama-French 5-Factor data...
Downloading Momentum factor (UMD)...
Downloading Short-Term Reversal factor (ST_Rev)...
Downloading Long-Term Reversal factor (LT_Rev)...
US combined factor sample: 321 observations, 2000-01-01 to 2026-09-01; as of 2026-10-31
Combined factor dataset: 321 months, 10 columns
Date range: 2000-01-01 to 2026-09-01
Columns: ['Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA', 'RF', 'UMD', 'ST_Rev', 'LT_Rev', 'SMB_FF3']
First 5 rows:
Mkt_RF SMB HML RMW CMA RF UMD ST_Rev \
Date
2000-01-01 -0.0474 0.0417 -0.0110 -0.0608 0.0448 0.0041 0.0184 0.0267
2000-02-01 0.0245 0.1854 -0.0973 -0.1893 -0.0106 0.0043 0.1805 -0.1329
2000-03-01 0.0521 -0.1553 0.0848 0.1162 -0.0120 0.0047 -0.0686 0.1007
2000-04-01 -0.0635 -0.0479 0.0645 0.0806 0.0560 0.0046 -0.0859 -0.0234
2000-05-01 -0.0439 -0.0386 0.0458 0.0406 0.0145 0.0050 -0.0893 -0.0877
LT_Rev SMB_FF3
Date
2000-01-01 0.0162 0.0512
2000-02-01 0.0736 0.2134
2000-03-01 -0.0485 -0.1739
2000-04-01 0.0023 -0.0603
2000-05-01 -0.0182 -0.0607
Source
etf_tickers = {'SPY': 'SPY (S&P 500)', 'IWN': 'IWN (Small Cap Value)',
               'VTV': 'VTV (Large Cap Value)'}
etf_dataframes = {}
for ticker in etf_tickers:
    returns = monthly_returns(load_prices(ticker)).rename('ETF_Return')
    edf = factors.join(returns, how='inner').dropna()
    edf['Stock_Excess_Return'] = edf['ETF_Return'] - edf['RF']
    etf_dataframes[ticker] = edf
common_idx = etf_dataframes['SPY'].index
for edf in etf_dataframes.values():
    common_idx = common_idx.intersection(edf.index)
etf_dataframes = {t: d.loc[common_idx].copy() for t, d in etf_dataframes.items()}
df = etf_dataframes['SPY'].copy()
coverage('Common ETF regression sample (limited by VTV inception)', df)
Common ETF regression sample (limited by VTV inception): 272 observations, 2004-02-01 to 2026-09-01; as of 2026-10-31
Section 1: The Fama-French 5-Factor Model
Key Definition: The Sharpe Ratio
Before we begin, one metric used frequently in this notebook is the Sharpe ratio, which measures risk-adjusted performance:
where is the mean excess return (or factor return) and is its standard deviation. A higher Sharpe ratio means better return per unit of risk. Compare ratios on the same return frequency, sample window and cost basis.
Note on inference: The Sharpe ratio is a descriptive statistic — it is just the sample mean divided by the sample standard deviation (both concepts from Section 1 of the Statistical Foundations notebook). A Sharpe ratio of 0.6 is not automatically “statistically significant.” To test whether a Sharpe ratio differs from zero, you need a t-test on the mean excess return — using an intercept-only regression with HAC errors. Alpha in a multi-factor regression tests a different, factor-adjusted mean. We derived Newey-West standard errors from first principles in Sections 7–9 of the Statistical Foundations notebook; here, we simply apply them.
To annualize from monthly data: multiply the monthly Sharpe ratio by as a conventional descriptive approximation. Serial dependence can invalidate this scaling as a true annual-horizon Sharpe ratio.
A Note on the Sample Period
This notebook uses 2000–latest released month data (vs. 2010–latest released month in the introductory notebook). The longer sample is deliberate: the additional factors (especially momentum and reversals) exhibit dramatic regime changes (e.g., the 2009 momentum crash, value’s 2018–2020 drawdown) that a shorter window would miss. As we saw in the Time Series Foundations notebook, the properties of financial returns can vary across regimes — volatility clustering and structural breaks are real concerns. The longer sample lets us observe these dynamics directly.
From 3 Factors to 5
In 2015, Fama and French extended their original model by adding two new factors motivated by a growing body of evidence that profitability and investment patterns predict stock returns independently of size and value.
The Two New Factors
RMW — Robust Minus Weak (Profitability)
Long stocks with robust (high) operating profitability, short stocks with weak (low) operating profitability
Operating profitability = (Revenue − COGS − SGA − Interest Expense) / Book Equity
Captures the empirical finding that profitable firms earn higher returns than unprofitable firms, controlling for other characteristics
The realized sample premium is calculated below; its estimate depends on the period.
CMA — Conservative Minus Aggressive (Investment)
Long stocks with conservative (low) asset growth, short stocks with aggressive (high) asset growth
Investment = Change in total assets / lagged total assets
Captures the finding that firms that invest aggressively tend to earn lower subsequent returns
The realized sample premium is calculated below; it is not a fixed expected payoff.
Why Add These Factors?
Fama and French (2015) presented three motivations for augmenting the original model:
Anomaly resolution. Many CAPM/3-factor anomalies (e.g., the profitability and asset-growth effects) disappear once you control for RMW and CMA.
Theoretical backing. A simple dividend discount model shows that — holding price constant — a stock’s expected return rises with expected profitability and falls with expected investment. This provides ex ante economic reasoning, not just empirical pattern-matching. We develop this derivation in full detail below — it is the theoretical heart of the five-factor model.
HML may become less central in FF5. In the 5-factor model, HML is often largely spanned by the other four factors in the original Fama-French samples, with a near-zero intercept. This is an influential but debated result in modern asset pricing, not a universally settled one (see below).
The HML Redundancy Debate
A striking result from Fama-French (2015): when you include RMW and CMA alongside the market and size factors, the mean HML return was largely explained by its exposures to the other factors in their sample. This is an intercept/spanning result, not a claim that all time-series variation disappears.
The result concerns the joint return covariance and mean structure. Value characteristics do not guarantee positive profitability exposure, and overlap with investment can vary by market and period. A factor-spanning regression, rather than a description of typical value companies, measures this relationship.
This does NOT mean value investing is dead. It means:
The economic channels through which value delivers returns may partly overlap with profitability and conservative investment.
Whether HML captures a distinct risk, or is merely a noisy proxy for RMW + CMA, remains actively debated. See Fama and French (2017) and Hou, Xue, and Zhang (2015) for opposing views.
The Dividend Discount Model Foundation of FF5
The theoretical cornerstone of the five-factor model — and what distinguishes it from a purely empirical exercise — is a dividend discount model (DDM) derivation presented in Section I of Fama & French (2015). This is worth developing carefully, because it provides the ex ante economic logic for why profitability, investment, and book-to-market should predict returns.
The Clean-Surplus Valuation Identity
Start from the standard present-value relation. The market value of a stock’s equity at time equals the discounted sum of expected future dividends:
where is the market value of equity, are dividends paid at , is the long-run average expected return (the discount rate, assumed constant for simplicity), and denotes expectations at time .
Now invoke the clean surplus accounting identity: all changes in book equity come either from earnings or dividends (and net share issuance, which we fold into dividends for simplicity):
where is book equity and is total equity earnings in period . Rearranging: , where is net investment in book equity.
Substituting into the DDM:
Dividing by Book Equity
Divide both sides by current book equity :
This equation motivates the characteristics used in the five-factor model; it does not derive its exact linear factor specification. The left-hand side is the market-to-book ratio (the inverse of book-to-market). The right-hand side depends on three things: expected profitability (), expected investment (), and the discount rate () — which is the expected return.
The Three Comparative Statics
Now hold different variables fixed and see what happens to :
| Holding fixed... | If this rises... | Then must... | Factor motivated |
|---|---|---|---|
| and (investment) | (profitability) ↑ | Rise (to keep equation balanced) | RMW (profitable → higher expected returns) |
| and (profitability) | (investment) ↑ | Fall (higher investment reduces numerator, so must be lower) | CMA (conservative investment → higher expected returns) |
| and | (book-to-market) ↑ | Rise (lower price for same cash flows → higher discount rate) | HML (value → higher expected returns) |
This is the key result. The valuation equation motivates a joint link between value, profitability, investment, and expected returns. The DDM doesn’t tell us why discount rates vary across stocks (risk? mispricing?), and the empirical mapping depends on additional assumptions about expectations, measurement, and implementation. But it does show why these characteristics are natural variables to examine together.
Why This Matters
Theoretical coherence. The CAPM derives expected returns from a single risk factor. FF3 was largely empirical — Fama and French acknowledged in 1993 that their factors “may or may not be risk factors.” The DDM derivation gives FF5 a value-theoretic foundation: the factors are not arbitrary; they map onto the primitives of the valuation equation.
HML redundancy clarified. The DDM shows that book-to-market can reflect a combination of profitability and investment information. Once you control for profitability (RMW) and investment (CMA) directly, book-to-market may have less independent information left in some samples — one reason the HML redundancy result appears in the literature.
It applies across different stories for discount rates. Whether you think expected return variation is driven by rational risk compensation (efficient markets) or systematic mispricing (behavioral finance), the DDM comparative statics remain informative. The equation is an accounting identity combined with present-value logic, but it does not by itself decide which economic mechanism dominates.
Connection to the q-factor model. Hou, Xue, and Zhang’s (2015) q-factor model arrives at similar factors from production-based asset pricing (firms’ investment Euler equations). The fact that two very different theoretical starting points — demand-side valuation (DDM) and supply-side production theory — both point to profitability and investment as key state variables is suggestive, though not a proof that every implementation captures the same underlying mechanism.
The valuation relation motivates joint empirical tests; it does not prove a realized factor premium or identify its cause. See Fama and French (2015).
Limitations of the DDM Motivation
The derivation is not without caveats:
Constant discount rates. The DDM derivation assumes a single constant . In reality, discount rates are time-varying. Lettau and Wachter (2007) and others have explored how time-varying discount rates complicate the clean mapping from characteristics to expected returns.
Clean surplus violations. In practice, accounting doesn’t perfectly satisfy the clean surplus relation (e.g., comprehensive income items bypass the income statement). This adds noise but doesn’t invalidate the qualitative predictions.
The model is silent on momentum. The DDM naturally motivates value, profitability, and investment — but not momentum. A recent price trend does not appear as a separate variable in this identity. Momentum therefore needs additional empirical and economic arguments; it remains a distinct extension examined below.
Expectations vs. realizations. The DDM involves expected future profitability and investment. We observe only realized (past) values. The implicit assumption is that past profitability and investment are reasonable proxies for expectations — reasonable but imperfect.
Source
# ============================================================================
# DDM Illustration: How Profitability, Investment, and B/M Map to Expected Returns
# ============================================================================
# This cell provides a numerical illustration of the Fama-French (2015) DDM
# comparative statics. We solve for the implied discount rate (expected return)
# under different assumptions about profitability and investment growth.
#
# The simplified DDM (Gordon Growth variant with clean surplus):
#   M = (Y - dB) / (r - g)   =>   r = (Y - dB)/M + g
# where Y = earnings, dB = net investment, M = market value, g = growth rate.
# Equivalently, dividing by book equity B:
#   M/B = (Y/B - dB/B) / (r - g)
# so:
#   r = (Y/B - dB/B) / (M/B) + g

import numpy as np
import matplotlib.pyplot as plt
import matplotlib.ticker as mticker

# --- Parameters ---
growth_rate = 0.02          # long-run nominal growth rate (g)
profitability_range = np.linspace(0.06, 0.20, 100)  # Y/B: ROE from 6% to 20%
investment_range = np.linspace(0.01, 0.11, 100)      # dB/B: reinvestment rate

# Fix one dimension and vary the other to show comparative statics

fig, axes = plt.subplots(1, 3, figsize=(16, 5))

# --- Panel A: Expected return vs. Profitability (Y/B) ---
# Fix: M/B = 1.5,  dB/B = 0.05
mb_fixed = 1.5
inv_fixed = 0.05
r_vs_prof = (profitability_range - inv_fixed) / mb_fixed + growth_rate

ax = axes[0]
ax.plot(profitability_range * 100, r_vs_prof * 100, color='#2166ac', linewidth=2.5)
ax.set_xlabel('Profitability (Y/B, %)', fontsize=11)
ax.set_ylabel('Implied Expected Return r (%)', fontsize=11)
ax.set_title('Panel A: Higher Profitability → Higher r\n(Motivates RMW)', fontsize=11, fontweight='bold')
ax.axhline(y=(0.10 - inv_fixed) / mb_fixed * 100 + growth_rate * 100, color='gray',
           linestyle='--', alpha=0.4)
ax.annotate('Holding M/B and investment fixed,\nhigher profitability requires\na higher discount rate',
            xy=(0.12 * 100, ((0.12 - inv_fixed) / mb_fixed + growth_rate) * 100),
            xytext=(0.08 * 100, ((0.17 - inv_fixed) / mb_fixed + growth_rate) * 100),
            fontsize=9, fontstyle='italic',
            arrowprops=dict(arrowstyle='->', color='gray'))
ax.yaxis.set_major_formatter(mticker.FormatStrFormatter('%.1f'))
ax.grid(True, alpha=0.3)

# --- Panel B: Expected return vs. Investment (dB/B) ---
# Fix: M/B = 1.5,  Y/B = 0.12
prof_fixed = 0.12
r_vs_inv = (prof_fixed - investment_range) / mb_fixed + growth_rate

ax = axes[1]
ax.plot(investment_range * 100, r_vs_inv * 100, color='#b2182b', linewidth=2.5)
ax.set_xlabel('Investment (ΔB/B, %)', fontsize=11)
ax.set_ylabel('Implied Expected Return r (%)', fontsize=11)
ax.set_title('Panel B: Higher Investment → Lower r\n(Motivates CMA)', fontsize=11, fontweight='bold')
ax.annotate('Holding M/B and profitability fixed,\nhigher investment (aggressive)\nrequires a lower discount rate',
            xy=(0.08 * 100, ((prof_fixed - 0.08) / mb_fixed + growth_rate) * 100),
            xytext=(0.04 * 100, ((prof_fixed - 0.10) / mb_fixed + growth_rate) * 100),
            fontsize=9, fontstyle='italic',
            arrowprops=dict(arrowstyle='->', color='gray'))
ax.yaxis.set_major_formatter(mticker.FormatStrFormatter('%.1f'))
ax.grid(True, alpha=0.3)

# --- Panel C: Expected return vs. B/M (inverse of M/B) ---
# Fix: Y/B = 0.12,  dB/B = 0.05
bm_range = np.linspace(0.3, 1.5, 100)   # B/M from 0.3 (growth) to 1.5 (deep value)
mb_range = 1.0 / bm_range
r_vs_bm = (prof_fixed - inv_fixed) / mb_range + growth_rate

ax = axes[2]
ax.plot(bm_range, r_vs_bm * 100, color='#1a9850', linewidth=2.5)
ax.set_xlabel('Book-to-Market (B/M)', fontsize=11)
ax.set_ylabel('Implied Expected Return r (%)', fontsize=11)
ax.set_title('Panel C: Higher B/M → Higher r\n(Motivates HML)', fontsize=11, fontweight='bold')
ax.annotate('Holding profitability and investment\nfixed, cheaper stocks (high B/M)\nhave higher expected returns',
            xy=(1.0, ((prof_fixed - inv_fixed) * 1.0 + growth_rate) * 100),
            xytext=(0.5, ((prof_fixed - inv_fixed) * 1.2 + growth_rate) * 100),
            fontsize=9, fontstyle='italic',
            arrowprops=dict(arrowstyle='->', color='gray'))
ax.yaxis.set_major_formatter(mticker.FormatStrFormatter('%.1f'))
ax.grid(True, alpha=0.3)

plt.suptitle('Dividend Discount Model: The Theoretical Foundation of the FF5 Factors\n'
             r'$r = \frac{Y/B\ -\ \Delta B/B}{M/B} + g$' + '    (simplified Gordon Growth DDM with clean surplus)',
             fontsize=12, y=1.08)
plt.tight_layout()
plt.show()

# --- Summary table ---
print("=" * 70)
print("DDM COMPARATIVE STATICS — NUMERICAL EXAMPLE")
print("=" * 70)
print(f"\nBaseline: Y/B = 12%,  ΔB/B = 5%,  M/B = 1.5,  g = 2%")
baseline_r = (0.12 - 0.05) / 1.5 + 0.02
print(f"  → Implied expected return: {baseline_r:.2%}\n")

scenarios = [
    ("High profitability (Y/B = 18%)",  0.18, 0.05, 1.5),
    ("Low profitability  (Y/B = 6%)",   0.06, 0.05, 1.5),
    ("Conservative inv.  (ΔB/B = 2%)",  0.12, 0.02, 1.5),
    ("Aggressive inv.    (ΔB/B = 10%)", 0.12, 0.10, 1.5),
    ("Deep value stock   (M/B = 0.8)",  0.12, 0.05, 0.8),
    ("Growth stock       (M/B = 3.0)",  0.12, 0.05, 3.0),
]

print(f"{'Scenario':<38} {'Y/B':>6} {'ΔB/B':>6} {'M/B':>6} {'r':>8}")
print("-" * 70)
for label, yb, db, mb in scenarios:
    r = (yb - db) / mb + growth_rate
    delta = r - baseline_r
    arrow = "↑" if delta > 0 else "↓"
    print(f"{label:<38} {yb:>5.0%} {db:>5.0%} {mb:>6.1f} {r:>7.2%} {arrow} ({delta:+.2%})")

print("\n→ These comparative statics motivate the factors under the imposed assumptions.")
print("  The DDM shows they are not ad hoc — they follow from present-value logic.")
print("Illustration only: fixed dividend-growth assumptions are imposed, not estimated.")
print("Treat Y and investment as next-period cash-flow components; sustained changes in reinvestment can also change growth.")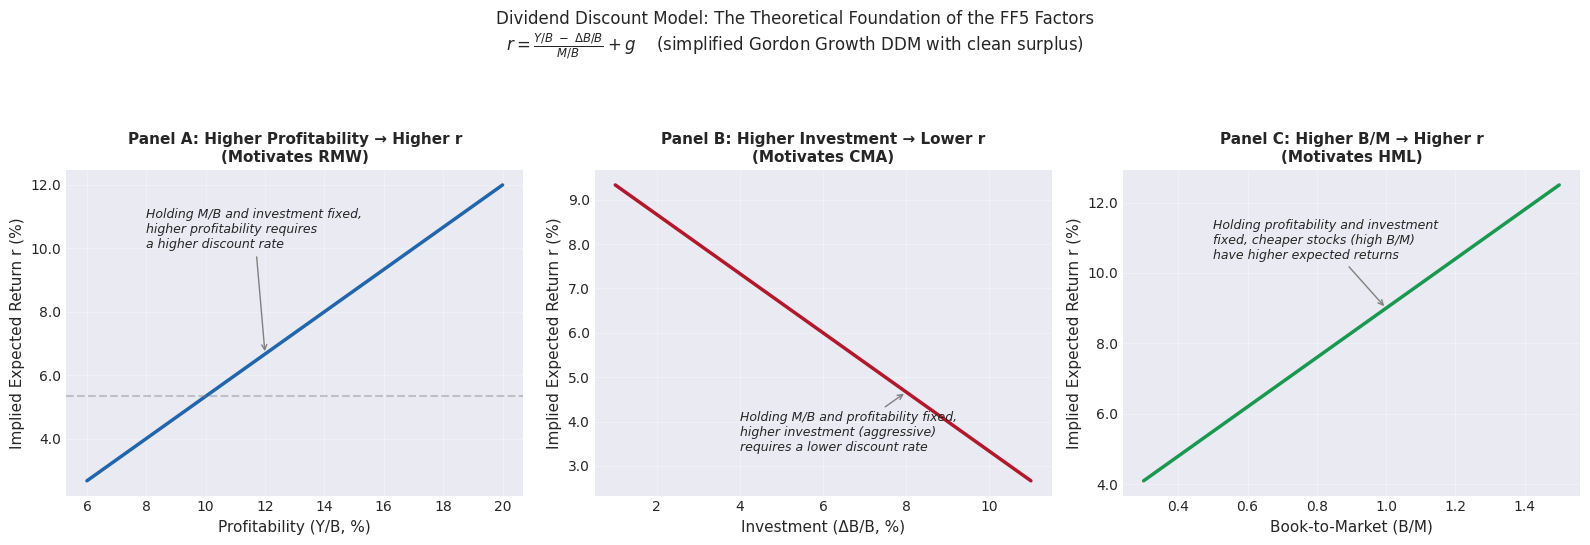
======================================================================
DDM COMPARATIVE STATICS — NUMERICAL EXAMPLE
======================================================================

Baseline: Y/B = 12%,  ΔB/B = 5%,  M/B = 1.5,  g = 2%
  → Implied expected return: 6.67%

Scenario                                  Y/B   ΔB/B    M/B        r
----------------------------------------------------------------------
High profitability (Y/B = 18%)           18%    5%    1.5  10.67% ↑ (+4.00%)
Low profitability  (Y/B = 6%)             6%    5%    1.5   2.67% ↓ (-4.00%)
Conservative inv.  (ΔB/B = 2%)           12%    2%    1.5   8.67% ↑ (+2.00%)
Aggressive inv.    (ΔB/B = 10%)          12%   10%    1.5   3.33% ↓ (-3.33%)
Deep value stock   (M/B = 0.8)           12%    5%    0.8  10.75% ↑ (+4.08%)
Growth stock       (M/B = 3.0)           12%    5%    3.0   4.33% ↓ (-2.33%)

→ These comparative statics motivate the factors under the imposed assumptions.
  The DDM shows they are not ad hoc — they follow from present-value logic.
Illustration only: fixed dividend-growth assumptions are imposed, not estimated.
Treat Y and investment as next-period cash-flow components; sustained changes in reinvestment can also change growth.
Empirical Analysis: Factor Summary Statistics
With the theoretical foundation in place, let’s examine the empirical properties of the five factors. We’ll look at summary statistics, risk-return profiles, and the correlation structure — all of which inform how the factors interact in a regression.
Performance convention: For factor spreads we plot as a hypothetical constant-notional return index. A zero-cost long-short factor has no uniquely defined invested capital: these plots omit collateral returns, financing, short-borrow costs and turnover, and are not ETF wealth paths. Mkt-RF is also an excess-return index. Annualized means and square-root-of-time volatilities are descriptive approximations.
# ============================================================================
# 5-Factor Model: Factor Summary Statistics
# ============================================================================

print("="*70)
print("FAMA-FRENCH 5-FACTOR SUMMARY STATISTICS (2000–latest released month)")
print("="*70)

factor_cols = ['Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA']
factor_stats = factors[factor_cols].describe().T
factor_stats['Annualized Mean'] = factors[factor_cols].mean() * 12
factor_stats['Annualized Std'] = factors[factor_cols].std() * np.sqrt(12)
factor_stats['Sharpe Ratio'] = factor_stats['Annualized Mean'] / factor_stats['Annualized Std']
factor_stats['HAC z (mean=0)'] = [mean_hac(factors[c]).tvalues[0] for c in factor_cols]

print("\nMonthly Statistics:")
print(factors[factor_cols].describe().round(4))

print("\n\nAnnualized Performance:")
print(factor_stats[['Annualized Mean', 'Annualized Std', 'Sharpe Ratio', 'HAC z (mean=0)']].round(4))

print("Largest realized arithmetic premium:", factor_stats['Annualized Mean'].idxmax())
print("Smallest realized arithmetic premium:", factor_stats['Annualized Mean'].idxmin())
print("These are sample estimates, not future premium forecasts.")
======================================================================
FAMA-FRENCH 5-FACTOR SUMMARY STATISTICS (2000–latest released month)
======================================================================
Monthly Statistics:
Mkt_RF SMB HML RMW CMA
count 321.0000 321.0000 321.0000 321.0000 321.0000
mean 0.0062 0.0016 0.0021 0.0035 0.0022
std 0.0452 0.0310 0.0343 0.0298 0.0223
min -0.1720 -0.1553 -0.1383 -0.1893 -0.0706
25% -0.0196 -0.0170 -0.0162 -0.0119 -0.0120
50% 0.0118 -0.0001 -0.0009 0.0035 0.0001
75% 0.0325 0.0191 0.0209 0.0158 0.0142
max 0.1358 0.1854 0.1286 0.1304 0.0900
Annualized Performance:
Annualized Mean Annualized Std Sharpe Ratio HAC z (mean=0)
Mkt_RF 0.0750 0.1567 0.4787 2.3993
SMB 0.0194 0.1075 0.1803 1.0338
HML 0.0255 0.1187 0.2150 0.9464
RMW 0.0418 0.1033 0.4043 2.1368
CMA 0.0270 0.0772 0.3496 1.5735
Largest realized arithmetic premium: Mkt_RF
Smallest realized arithmetic premium: SMB
These are sample estimates, not future premium forecasts.
Source
# ============================================================================
# Visualize: Factor risk-return profile
# ============================================================================

fig, axes = plt.subplots(1, 2, figsize=(16, 5.5))

factor_cols = ['Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA']
ann_means = factors[factor_cols].mean() * 12
ann_stds = factors[factor_cols].std() * np.sqrt(12)
sharpes = ann_means / ann_stds

colors = {'Mkt_RF': '#2c3e50', 'SMB': '#e74c3c', 'HML': '#2ecc71',
          'RMW': '#3498db', 'CMA': '#9b59b6'}

# --- Left: Risk-return scatter ---
ax = axes[0]
for col in factor_cols:
    ax.scatter(ann_stds[col], ann_means[col], s=120, color=colors[col],
               edgecolors='white', linewidth=1.5, zorder=3)
    ax.annotate(col, (ann_stds[col], ann_means[col]),
                textcoords="offset points", xytext=(8, 5), fontsize=10, fontweight='bold',
                color=colors[col])
ax.axhline(y=0, color='gray', linestyle='--', linewidth=0.8, alpha=0.5)
ax.set_xlabel('Annualized Volatility', fontsize=11)
ax.set_ylabel('Annualized Mean Return', fontsize=11)
ax.set_title('Factor Risk-Return Profile', fontweight='bold', fontsize=13)
ax.grid(True, alpha=0.3)

# --- Right: Sharpe ratio bar chart ---
ax2 = axes[1]
bar_colors = [colors[col] for col in factor_cols]
bars = ax2.bar(factor_cols, sharpes, color=bar_colors, edgecolor='white', width=0.55)
ax2.axhline(y=0, color='gray', linestyle='--', linewidth=0.8)
for bar, sr in zip(bars, sharpes):
    ax2.text(bar.get_x() + bar.get_width()/2,
             bar.get_height() + (0.01 if sr >= 0 else -0.04),
             f'{sr:.2f}', ha='center', fontsize=10, fontweight='bold')
ax2.set_ylabel('Sharpe Ratio', fontsize=11)
ax2.set_title('Factor Sharpe Ratios (Annualized)', fontweight='bold', fontsize=13)
ax2.grid(True, alpha=0.3, axis='y')

fig.suptitle('Fama-French 5-Factor Performance Overview', fontsize=14, fontweight='bold', y=1.02)
plt.tight_layout()
plt.show()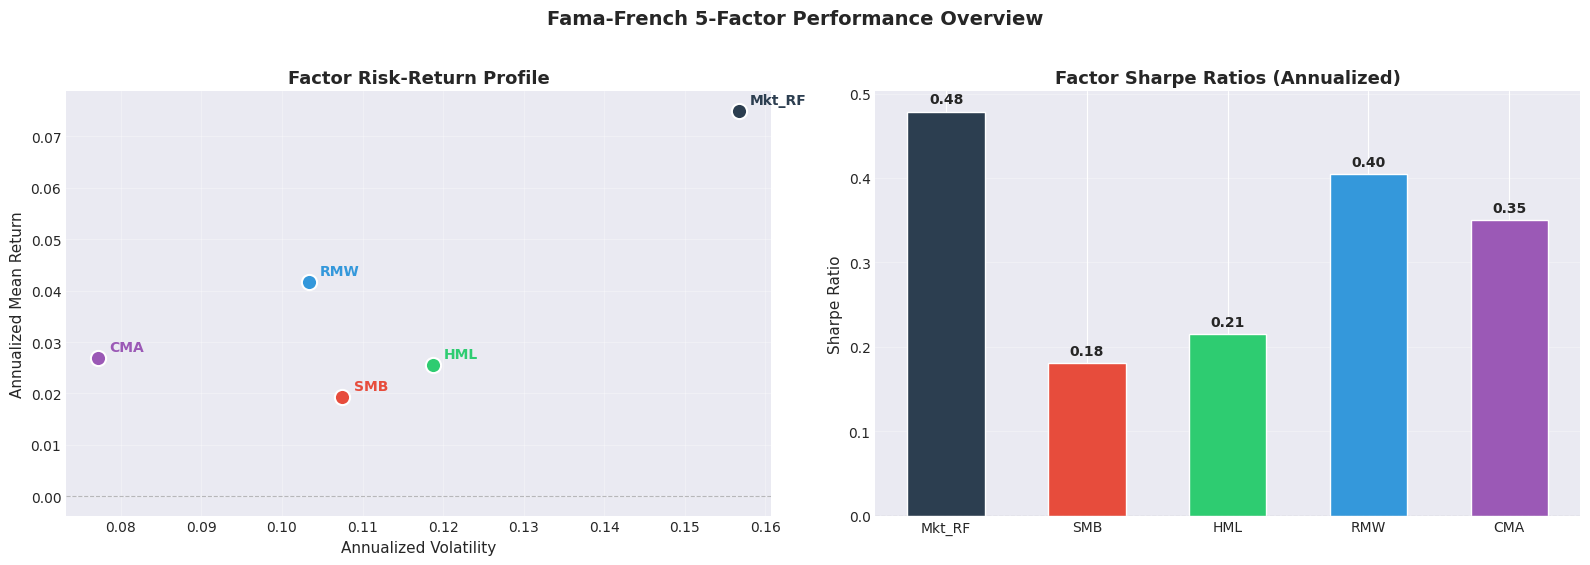
Source
# ============================================================================
# 5-Factor Model: Factor Correlation Matrix
# ============================================================================

print("FACTOR CORRELATION MATRIX")
print("="*70)

corr = factors[factor_cols].corr()
print(corr.round(3))

# Visualize
fig, ax = plt.subplots(figsize=(8, 6))
mask = np.triu(np.ones_like(corr, dtype=bool), k=1)
sns.heatmap(corr, annot=True, fmt='.2f', cmap='RdBu_r', center=0,
            mask=mask, square=True, ax=ax, vmin=-1, vmax=1,
            linewidths=0.5)
ax.set_title('Factor Correlation Matrix (2000–latest released month)', fontweight='bold', fontsize=13)
plt.tight_layout()
plt.show()

print(f"HML–CMA correlation: {corr.loc['HML', 'CMA']:.3f}")
print("Style factors are not constructed to be independent or market-neutral.")
FACTOR CORRELATION MATRIX
======================================================================
Mkt_RF SMB HML RMW CMA
Mkt_RF 1.000 0.257 -0.045 -0.343 -0.240
SMB 0.257 1.000 0.100 -0.431 0.047
HML -0.045 0.100 1.000 0.338 0.624
RMW -0.343 -0.431 0.338 1.000 0.257
CMA -0.240 0.047 0.624 0.257 1.000
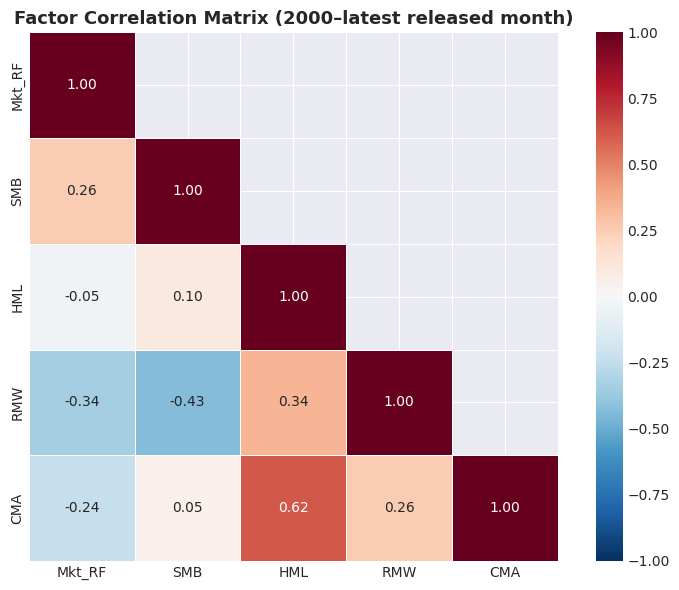
HML–CMA correlation: 0.624
Style factors are not constructed to be independent or market-neutral.
HML–CMA collinearity and specification sensitivity
Correlated regressors can widen confidence intervals without biasing OLS under exogeneity. VIF is a diagnostic, not a rule for deleting factors. A smaller p-value after dropping CMA does not make the new model more valid: omitted investment exposure may change the meaning of HML and alpha.
We report full and reduced models on the same sample. Check coefficient changes, intervals, adjusted R² and the omitted-factor test; a small R² difference alone is not evidence of economic redundancy. The DDM motivates investment as a characteristic but does not prove that every investment strategy earns a premium.
# ============================================================================
# Multicollinearity Diagnostics: VIF and the CMA Question
# ============================================================================
from statsmodels.stats.outliers_influence import variance_inflation_factor

# --- 1. Compute VIF for different factor sets ---
print("="*70)
print("VARIANCE INFLATION FACTORS (VIF)")
print("="*70)

# Full 6-factor set: Mkt_RF, SMB, HML, RMW, CMA, UMD
factor_sets = {
    '6-Factor (FF5 + UMD)': ['Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA', 'UMD'],
    '5-Factor (drop CMA)':  ['Mkt_RF', 'SMB', 'HML', 'RMW', 'UMD'],
    '5-Factor (drop HML)':  ['Mkt_RF', 'SMB', 'RMW', 'CMA', 'UMD'],
}

for set_name, cols in factor_sets.items():
    X = factors[cols].dropna()
    X_with_const = sm.add_constant(X)
    vifs = [variance_inflation_factor(X_with_const.values, i+1)  # +1 to skip constant
            for i in range(len(cols))]
    print(f"\n  {set_name}:")
    for col, vif in zip(cols, vifs):
        flag = " ⚠️" if vif > 5 else ""
        print(f"    {col:8s}  VIF = {vif:.2f}{flag}")

print("""
INTERPRETATION:
  A VIF > 5 suggests meaningful multicollinearity; > 10 is severe.
  In the full 6-factor set, HML and CMA will show elevated VIFs due
  to their shared value/investment information. Dropping either one
  reduces VIF across the board.
""")

# --- 2. Regression comparison: with and without CMA ---
print("="*70)
print("6-FACTOR vs 5-FACTOR (NO CMA): REGRESSION COMPARISON")
print("="*70)

cols_6f = ['Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA', 'UMD']
cols_5f_no_cma = ['Mkt_RF', 'SMB', 'HML', 'RMW', 'UMD']

for ticker, label in etf_tickers.items():
    edf = etf_dataframes[ticker]

    # 6-factor regression
    res6 = run_ff_regression(None, cols_6f, edf, model_name="6F", stock_name=label)
    # 5-factor regression (drop CMA)
    res5_no_cma = run_ff_regression(None, cols_5f_no_cma, edf, model_name="5F-noCMA", stock_name=label)

    print(f"\n{'='*70}")
    print(f"  {label}")
    print(f"{'='*70}")

    # 6-factor results
    names_6f = ['Alpha', 'Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA', 'UMD']
    print(f"\n  6-Factor (FF5 + UMD):")
    print(f"    {'':12s} {'Coef':>8s}  {'Std Err':>8s}  {'t-stat':>8s}  {'p-val':>8s}")
    for i, name in enumerate(names_6f):
        sig = '***' if res6.pvalues[i] < 0.01 else ('**' if res6.pvalues[i] < 0.05 else ('*' if res6.pvalues[i] < 0.10 else ''))
        print(f"    {name:12s} {res6.params[i]:8.4f}  {res6.bse[i]:8.4f}  {res6.tvalues[i]:8.2f}  {res6.pvalues[i]:8.4f} {sig}")
    print(f"    R² = {res6.rsquared:.4f}   Adj R² = {res6.rsquared_adj:.4f}")

    # 5-factor (no CMA) results
    names_5f = ['Alpha', 'Mkt_RF', 'SMB', 'HML', 'RMW', 'UMD']
    print(f"\n  5-Factor (drop CMA):")
    print(f"    {'':12s} {'Coef':>8s}  {'Std Err':>8s}  {'t-stat':>8s}  {'p-val':>8s}")
    for i, name in enumerate(names_5f):
        sig = '***' if res5_no_cma.pvalues[i] < 0.01 else ('**' if res5_no_cma.pvalues[i] < 0.05 else ('*' if res5_no_cma.pvalues[i] < 0.10 else ''))
        print(f"    {name:12s} {res5_no_cma.params[i]:8.4f}  {res5_no_cma.bse[i]:8.4f}  {res5_no_cma.tvalues[i]:8.2f}  {res5_no_cma.pvalues[i]:8.4f} {sig}")
    print(f"    R² = {res5_no_cma.rsquared:.4f}   Adj R² = {res5_no_cma.rsquared_adj:.4f}")

    # Summary comparison
    print(f"\n  Δ R²:          {res6.rsquared - res5_no_cma.rsquared:+.5f}")
    print(f"  Δ Adj R²:      {res6.rsquared_adj - res5_no_cma.rsquared_adj:+.5f}")

    # Compare HML standard errors
    hml_idx_6f = 3  # HML is 4th regressor (0=const, 1=Mkt, 2=SMB, 3=HML)
    hml_idx_5f = 3
    pct_change_se = (res6.bse[hml_idx_6f] - res5_no_cma.bse[hml_idx_5f]) / res5_no_cma.bse[hml_idx_5f] * 100
    print(f"  HML Std Err:   {res6.bse[hml_idx_6f]:.4f} (6F)  →  {res5_no_cma.bse[hml_idx_5f]:.4f} (5F)  [{pct_change_se:+.1f}%]")

print("Dropping CMA changes the specification. Compare actual estimates above;")
print("lower VIF alone does not establish more reliable economic inference.")
======================================================================
VARIANCE INFLATION FACTORS (VIF)
======================================================================
6-Factor (FF5 + UMD):
Mkt_RF VIF = 1.38
SMB VIF = 1.36
HML VIF = 2.03
RMW VIF = 1.61
CMA VIF = 1.81
UMD VIF = 1.22
5-Factor (drop CMA):
Mkt_RF VIF = 1.32
SMB VIF = 1.36
HML VIF = 1.29
RMW VIF = 1.61
UMD VIF = 1.20
5-Factor (drop HML):
Mkt_RF VIF = 1.36
SMB VIF = 1.31
RMW VIF = 1.42
CMA VIF = 1.15
UMD VIF = 1.15
INTERPRETATION:
A VIF > 5 suggests meaningful multicollinearity; > 10 is severe.
In the full 6-factor set, HML and CMA will show elevated VIFs due
to their shared value/investment information. Dropping either one
reduces VIF across the board.
======================================================================
6-FACTOR vs 5-FACTOR (NO CMA): REGRESSION COMPARISON
======================================================================
======================================================================
SPY (S&P 500)
======================================================================
6-Factor (FF5 + UMD):
Coef Std Err t-stat p-val
Alpha -0.0003 0.0001 -2.01 0.0446 **
Mkt_RF 0.9941 0.0057 174.55 0.0000 ***
SMB -0.1232 0.0070 -17.58 0.0000 ***
HML 0.0235 0.0089 2.62 0.0087 ***
RMW 0.0434 0.0129 3.35 0.0008 ***
CMA 0.0250 0.0112 2.23 0.0256 **
UMD -0.0021 0.0055 -0.38 0.7058
R² = 0.9964 Adj R² = 0.9963
5-Factor (drop CMA):
Coef Std Err t-stat p-val
Alpha -0.0003 0.0002 -1.93 0.0541 *
Mkt_RF 0.9925 0.0054 184.23 0.0000 ***
SMB -0.1239 0.0069 -18.06 0.0000 ***
HML 0.0334 0.0060 5.60 0.0000 ***
RMW 0.0450 0.0131 3.44 0.0006 ***
UMD -0.0007 0.0053 -0.13 0.8997
R² = 0.9963 Adj R² = 0.9962
Δ R²: +0.00008
Δ Adj R²: +0.00007
HML Std Err: 0.0089 (6F) → 0.0060 (5F) [+50.2%]
======================================================================
IWN (Small Cap Value)
======================================================================
6-Factor (FF5 + UMD):
Coef Std Err t-stat p-val
Alpha -0.0010 0.0005 -2.04 0.0416 **
Mkt_RF 0.9640 0.0129 74.59 0.0000 ***
SMB 0.8260 0.0237 34.84 0.0000 ***
HML 0.3764 0.0239 15.73 0.0000 ***
RMW 0.0342 0.0250 1.37 0.1710
CMA -0.0042 0.0325 -0.13 0.8980
UMD 0.0159 0.0189 0.84 0.3985
R² = 0.9818 Adj R² = 0.9813
5-Factor (drop CMA):
Coef Std Err t-stat p-val
Alpha -0.0010 0.0005 -2.04 0.0411 **
Mkt_RF 0.9643 0.0126 76.59 0.0000 ***
SMB 0.8261 0.0237 34.91 0.0000 ***
HML 0.3747 0.0193 19.43 0.0000 ***
RMW 0.0340 0.0250 1.36 0.1734
UMD 0.0157 0.0190 0.83 0.4093
R² = 0.9818 Adj R² = 0.9814
Δ R²: +0.00000
Δ Adj R²: -0.00007
HML Std Err: 0.0239 (6F) → 0.0193 (5F) [+24.1%]
======================================================================
VTV (Large Cap Value)
======================================================================
6-Factor (FF5 + UMD):
Coef Std Err t-stat p-val
Alpha -0.0004 0.0005 -0.85 0.3968
Mkt_RF 0.9028 0.0207 43.69 0.0000 ***
SMB -0.0730 0.0302 -2.42 0.0157 **
HML 0.3042 0.0299 10.18 0.0000 ***
RMW 0.0697 0.0313 2.23 0.0260 **
CMA 0.1813 0.0500 3.62 0.0003 ***
UMD -0.0187 0.0144 -1.30 0.1929
R² = 0.9512 Adj R² = 0.9501
5-Factor (drop CMA):
Coef Std Err t-stat p-val
Alpha -0.0004 0.0006 -0.75 0.4532
Mkt_RF 0.8913 0.0202 44.04 0.0000 ***
SMB -0.0781 0.0291 -2.68 0.0074 ***
HML 0.3758 0.0236 15.90 0.0000 ***
RMW 0.0812 0.0341 2.38 0.0173 **
UMD -0.0086 0.0162 -0.53 0.5961
R² = 0.9469 Adj R² = 0.9459
Δ R²: +0.00426
Δ Adj R²: +0.00415
HML Std Err: 0.0299 (6F) → 0.0236 (5F) [+26.4%]
Dropping CMA changes the specification. Compare actual estimates above;
lower VIF alone does not establish more reliable economic inference.
Model Comparison: 3-Factor vs. 5-Factor
We fit the original three-factor and extended five-factor models to the same ETF return samples. Does adding profitability and investment improve descriptive fit, and how do the estimated exposures and alpha change? The published FF3 and FF5 use different SMB constructions, so these specifications are not exactly nested. A change in an ETF’s HML coefficient is not a test of HML redundancy: that requires a separate regression of HML itself on the other factors.
print("="*70)
print("3-FACTOR vs 5-FACTOR MODEL COMPARISON")
print("="*70)

comparison_data = []

for ticker, label in etf_tickers.items():
    edf = etf_dataframes[ticker]

    # 3-Factor
    res3 = run_ff_regression(None, ['Mkt_RF', 'SMB', 'HML'], edf,
                              model_name="FF3", stock_name=label)
    # 5-Factor
    res5 = run_ff_regression(None, ['Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA'], edf,
                              model_name="FF5", stock_name=label)

    comparison_data.append({
        'ETF': ticker,
        'FF3 R²': res3.rsquared,
        'FF5 R²': res5.rsquared,
        'FF3 Adj R²': res3.rsquared_adj,
        'FF5 Adj R²': res5.rsquared_adj,
        'FF3 Alpha': res3.params[0],
        'FF5 Alpha': res5.params[0],
        'FF3 Alpha p': res3.pvalues[0],
        'FF5 Alpha p': res5.pvalues[0],
    })

    print(f"\n{'='*70}")
    print(f"  {label}")
    print(f"{'='*70}")
    print(f"\n  3-Factor Model:")
    print(f"    Alpha = {res3.params[0]:.6f}  (p = {res3.pvalues[0]:.4f})")
    print(f"    Mkt   = {res3.params[1]:.4f}  SMB = {res3.params[2]:.4f}  HML = {res3.params[3]:.4f}")
    print(f"    R² = {res3.rsquared:.4f}   Adj R² = {res3.rsquared_adj:.4f}")
    print(f"\n  5-Factor Model:")
    print(f"    Alpha = {res5.params[0]:.6f}  (p = {res5.pvalues[0]:.4f})")
    print(f"    Mkt   = {res5.params[1]:.4f}  SMB = {res5.params[2]:.4f}  HML = {res5.params[3]:.4f}")
    print(f"    RMW   = {res5.params[4]:.4f}  CMA = {res5.params[5]:.4f}")
    print(f"    R² = {res5.rsquared:.4f}   Adj R² = {res5.rsquared_adj:.4f}")
    print(f"\n    R² change: {res5.rsquared - res3.rsquared:+.4f}")

comp_df = pd.DataFrame(comparison_data)
print("\n\n" + "="*70)
print("SUMMARY TABLE")
print("="*70)
print(comp_df.to_string(index=False, float_format='%.4f'))
======================================================================
3-FACTOR vs 5-FACTOR MODEL COMPARISON
======================================================================
======================================================================
SPY (S&P 500)
======================================================================
3-Factor Model:
Alpha = -0.000180 (p = 0.2412)
Mkt = 0.9893 SMB = -0.1378 HML = 0.0136
R² = 0.9960 Adj R² = 0.9959
5-Factor Model:
Alpha = -0.000303 (p = 0.0416)
Mkt = 0.9946 SMB = -0.1228 HML = 0.0244
RMW = 0.0439 CMA = 0.0242
R² = 0.9964 Adj R² = 0.9963
R² change: +0.0004
======================================================================
IWN (Small Cap Value)
======================================================================
3-Factor Model:
Alpha = -0.000770 (p = 0.1541)
Mkt = 0.9650 SMB = 0.8174 HML = 0.5253
R² = 0.9793 Adj R² = 0.9791
5-Factor Model:
Alpha = -0.000981 (p = 0.0480)
Mkt = 0.9601 SMB = 0.8230 HML = 0.3688
RMW = 0.0303 CMA = 0.0018
R² = 0.9816 Adj R² = 0.9813
R² change: +0.0023
======================================================================
VTV (Large Cap Value)
======================================================================
3-Factor Model:
Alpha = -0.000263 (p = 0.6326)
Mkt = 0.8927 SMB = -0.1225 HML = 0.3715
R² = 0.9470 Adj R² = 0.9464
5-Factor Model:
Alpha = -0.000523 (p = 0.3237)
Mkt = 0.9074 SMB = -0.0696 HML = 0.3130
RMW = 0.0744 CMA = 0.1742
R² = 0.9509 Adj R² = 0.9500
R² change: +0.0039
======================================================================
SUMMARY TABLE
======================================================================
ETF FF3 R² FF5 R² FF3 Adj R² FF5 Adj R² FF3 Alpha FF5 Alpha FF3 Alpha p FF5 Alpha p
SPY 0.9960 0.9964 0.9959 0.9963 -0.0002 -0.0003 0.2412 0.0416
IWN 0.9793 0.9816 0.9791 0.9813 -0.0008 -0.0010 0.1541 0.0480
VTV 0.9470 0.9509 0.9464 0.9500 -0.0003 -0.0005 0.6326 0.3237
Source
# ============================================================================
# Visualize: 3-Factor vs 5-Factor model comparison
# ============================================================================

fig, axes = plt.subplots(1, 2, figsize=(16, 5.5))

tickers = list(etf_tickers.keys())
labels = [etf_tickers[t] for t in tickers]
short_labels = tickers

# Re-extract coefficients for plotting
coef_data_3f = {}
coef_data_5f = {}
for ticker in tickers:
    edf = etf_dataframes[ticker]
    res3 = run_ff_regression(None, ['Mkt_RF', 'SMB', 'HML'], edf)
    res5 = run_ff_regression(None, ['Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA'], edf)
    coef_data_3f[ticker] = {'Alpha': res3.params[0], 'Mkt_RF': res3.params[1],
                             'SMB': res3.params[2], 'HML': res3.params[3],
                             'R²': res3.rsquared}
    coef_data_5f[ticker] = {'Alpha': res5.params[0], 'Mkt_RF': res5.params[1],
                             'SMB': res5.params[2], 'HML': res5.params[3],
                             'RMW': res5.params[4], 'CMA': res5.params[5],
                             'R²': res5.rsquared}

# --- Left: R² comparison ---
ax = axes[0]
x_pos = np.arange(len(tickers))
width = 0.3
bars1 = ax.bar(x_pos - width/2, [coef_data_3f[t]['R²'] for t in tickers],
               width, label='3-Factor', color='#3498db', edgecolor='white')
bars2 = ax.bar(x_pos + width/2, [coef_data_5f[t]['R²'] for t in tickers],
               width, label='5-Factor', color='#e67e22', edgecolor='white')
for bar in list(bars1) + list(bars2):
    ax.text(bar.get_x() + bar.get_width()/2, bar.get_height() + 0.003,
            f'{bar.get_height():.3f}', ha='center', fontsize=9, fontweight='bold')
ax.set_xticks(x_pos)
ax.set_xticklabels(short_labels, fontsize=11)
ax.set_ylabel('R²', fontsize=11)
ax.set_title('Model Fit: 3-Factor vs 5-Factor', fontweight='bold', fontsize=13)
ax.legend(fontsize=10)
ax.grid(True, alpha=0.3, axis='y')
ax.set_ylim(0, 1.08)

# --- Right: Coefficient comparison for shared factors ---
ax2 = axes[1]
shared_factors = ['Mkt_RF', 'SMB', 'HML']
x_pos2 = np.arange(len(shared_factors))
group_width = 0.8
bar_w = group_width / len(tickers) / 2  # 2 models per ticker

color_3f = ['#3498db', '#2980b9', '#1a5276']
color_5f = ['#e67e22', '#d35400', '#a04000']

for i, ticker in enumerate(tickers):
    offset_3f = -group_width/2 + i * (group_width/len(tickers)) + bar_w * 0.1
    offset_5f = offset_3f + bar_w
    vals_3f = [coef_data_3f[ticker][f] for f in shared_factors]
    vals_5f = [coef_data_5f[ticker][f] for f in shared_factors]
    ax2.bar(x_pos2 + offset_3f, vals_3f, bar_w * 0.9, color=color_3f[i], alpha=0.7,
            label=f'{ticker} (3F)' if i == 0 else f'{ticker} (3F)')
    ax2.bar(x_pos2 + offset_5f, vals_5f, bar_w * 0.9, color=color_5f[i], alpha=0.7,
            label=f'{ticker} (5F)' if i == 0 else f'{ticker} (5F)')

ax2.set_xticks(x_pos2)
ax2.set_xticklabels(shared_factors, fontsize=11)
ax2.set_ylabel('Coefficient', fontsize=11)
ax2.set_title('How Betas Change: 3F → 5F', fontweight='bold', fontsize=13)
ax2.axhline(y=0, color='gray', linestyle='--', linewidth=0.8)
ax2.legend(fontsize=7, ncol=3, loc='upper right')
ax2.grid(True, alpha=0.3, axis='y')

fig.suptitle('3-Factor vs 5-Factor Model Comparison', fontsize=14, fontweight='bold', y=1.02)
plt.tight_layout()
plt.show()

print("Changes in asset HML coefficients do not test whether HML itself is spanned by the other factors.")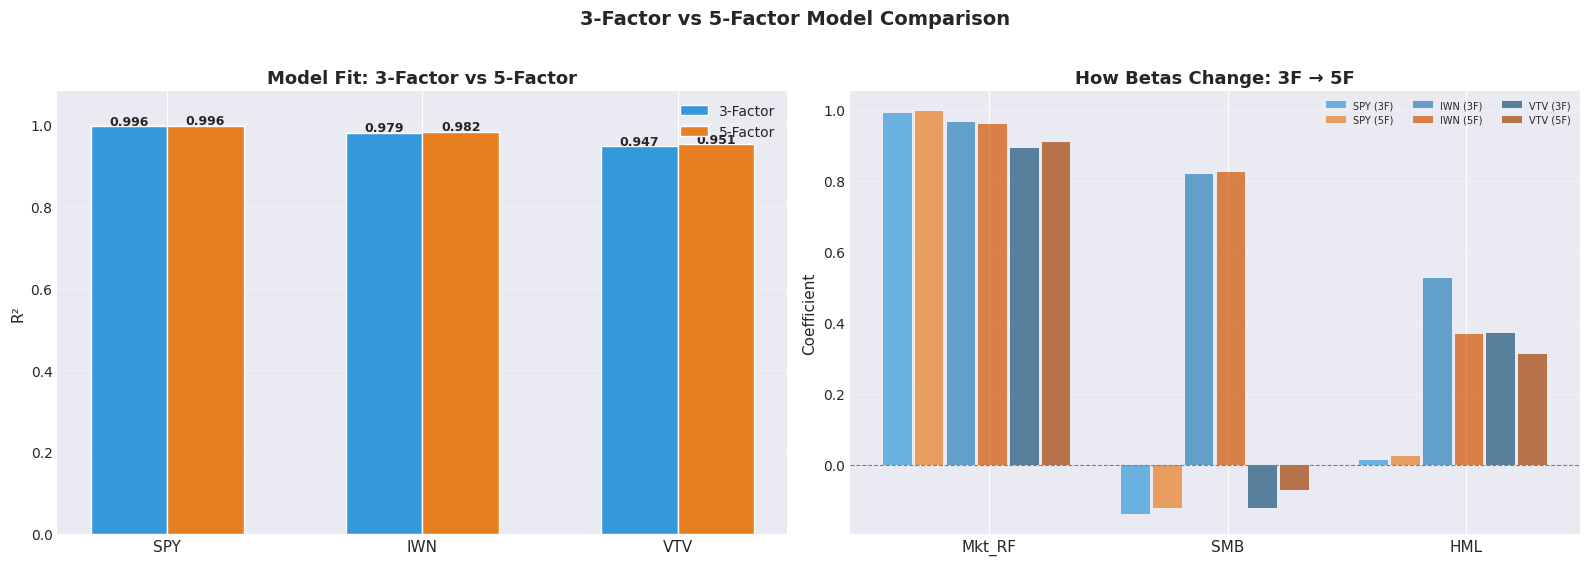
Changes in asset HML coefficients do not test whether HML itself is spanned by the other factors.
Interpreting the 3-Factor vs 5-Factor Comparison
Compare these results to the 3-factor regressions you ran in the 3-Factor Tutorial. The key question is: does adding RMW and CMA change the story?
What to look for:
R² improvement: The original FF3 and FF5 use different SMB series, so they are not strictly nested and R² can move either way. For broad-market ETFs like SPY, the improvement may be modest since the market factor dominates. For style ETFs like IWN (small value) or VTV (large value), the additional factors may capture meaningful variation.
Alpha changes: If alpha shrinks when moving from 3 to 5 factors, the estimated intercept is sensitive to the benchmark. This does not establish a causal explanation or identify skill. Recall from the 3-Factor Tutorial that alpha should be interpreted carefully: a statistically insignificant alpha means we cannot reject zero alpha; residual return variation remains.
RMW and CMA loadings:
IWN (small cap value) may show negative RMW — small value firms are often less profitable
VTV (large cap value) may show positive RMW — large value firms tend to be more profitable
Check CMA estimates and intervals; a value mandate does not force a positive investment loading
HML coefficient changes: Watch how β_HML changes between the 3- and 5-factor specifications. Due to the high correlation between HML and CMA, the HML loading may shrink when CMA is included.
Section 2: Momentum — The Carhart 4-Factor Model
Carhart adds a winners-minus-losers factor to the original FF3 specification:
The French momentum series sorts on prior returns over months through , skipping the most recent month to reduce short-term reversal effects. See the official momentum definition.
Underreaction to information, investor behaviour and conditional risk are competing explanations. A price-momentum loading does not identify which mechanism operates, and long-only momentum ETFs do not replicate the academic long-short spread.
Momentum crashes
Momentum can lose sharply during recoveries following market declines, when its short positions in past losers rebound. Daniel and Moskowitz document this mechanism across samples; it is not a promise that every crash or recovery has the same pattern. The numerical loss depends on the exact strategy, weighting and window. We calculate the worst compounded three-month loss of this downloaded series in the solution manual instead of importing a loss from a different strategy. Daniel and Moskowitz (2016).
The plots below show realized returns and descriptive risk statistics. A rolling 12-month return compounds monthly gross returns; it does not sum simple returns.
Source
# ============================================================================
# Momentum Factor Analysis
# ============================================================================

print("="*70)
print("MOMENTUM FACTOR (UMD) ANALYSIS")
print("="*70)

# Cumulative returns of all factors
fig, axes = plt.subplots(2, 2, figsize=(14, 10))

# Plot 1: Cumulative factor returns
ax = axes[0, 0]
for col, color, lbl in [('Mkt_RF', 'darkblue', 'Market'),
                          ('SMB', 'teal', 'SMB (Size)'),
                          ('HML', 'purple', 'HML (Value)'),
                          ('RMW', 'darkgreen', 'RMW (Profit.)'),
                          ('CMA', 'brown', 'CMA (Invest.)'),
                          ('UMD', 'red', 'UMD (Momentum)')]:
    cum = (1 + factors[col]).cumprod()
    ax.plot(factors.index, cum, label=lbl, linewidth=1.5, color=color)
ax.set_title('Cumulative Factor Returns (2000–latest released month)', fontweight='bold')
ax.set_ylabel('Hypothetical return index (start=1)')
ax.legend(fontsize=8, loc='upper left')
ax.set_yscale('log')
ax.grid(True, alpha=0.3)

# Plot 2: Momentum monthly returns
ax = axes[0, 1]
ax.bar(factors.index, factors['UMD'] * 100, color='red', alpha=0.6, width=25)
ax.set_title('Monthly Momentum Returns (UMD)', fontweight='bold')
ax.set_ylabel('Return (%)')
ax.grid(True, alpha=0.3)

# Plot 3: Rolling 12-month momentum return
ax = axes[1, 0]
rolling_mom = ((1 + factors['UMD']).rolling(12).apply(np.prod, raw=True) - 1) * 100
ax.plot(factors.index, rolling_mom, color='red', linewidth=1.5)
ax.axhline(0, color='black', linewidth=0.5, linestyle='--')
ax.fill_between(factors.index, rolling_mom, 0,
                where=rolling_mom < 0, color='red', alpha=0.3, label='Negative trailing returns')
ax.set_title('Rolling 12-Month Momentum Return', fontweight='bold')
ax.set_ylabel('Cumulative 12M Return (%)')
ax.legend()
ax.grid(True, alpha=0.3)

# Plot 4: Distribution of momentum returns vs market
ax = axes[1, 1]
ax.hist(factors['UMD'] * 100, bins=40, alpha=0.6, color='red', label='UMD', density=True)
ax.hist(factors['Mkt_RF'] * 100, bins=40, alpha=0.4, color='blue', label='Mkt-RF', density=True)
ax.set_title('Distribution: Momentum vs Market', fontweight='bold')
ax.set_xlabel('Monthly Return (%)')
ax.set_ylabel('Density')
ax.legend()
ax.grid(True, alpha=0.3)

plt.tight_layout()
plt.show()

# Momentum statistics
print(f"\nMomentum (UMD) Summary Statistics:")
print(f"  Mean monthly return:    {factors['UMD'].mean()*100:.2f}%")
print(f"  Monthly std dev:        {factors['UMD'].std()*100:.2f}%")
print(f"  Annualized return:      {factors['UMD'].mean()*1200:.2f}%")
print(f"  Annualized volatility:  {factors['UMD'].std()*np.sqrt(12)*100:.2f}%")
print(f"  Sharpe ratio:           {factors['UMD'].mean()/factors['UMD'].std()*np.sqrt(12):.2f}")
print(f"  Skewness:               {factors['UMD'].skew():.2f}")
print(f"  Kurtosis:               {factors['UMD'].kurtosis():.2f}")
print(f"  Worst month:            {factors['UMD'].min()*100:.2f}%")
print(f"  Best month:             {factors['UMD'].max()*100:.2f}%")

print('Inspect the reported skewness, tail outcomes and sample mean. Historical crash exposure does not establish a future premium.')
======================================================================
MOMENTUM FACTOR (UMD) ANALYSIS
======================================================================
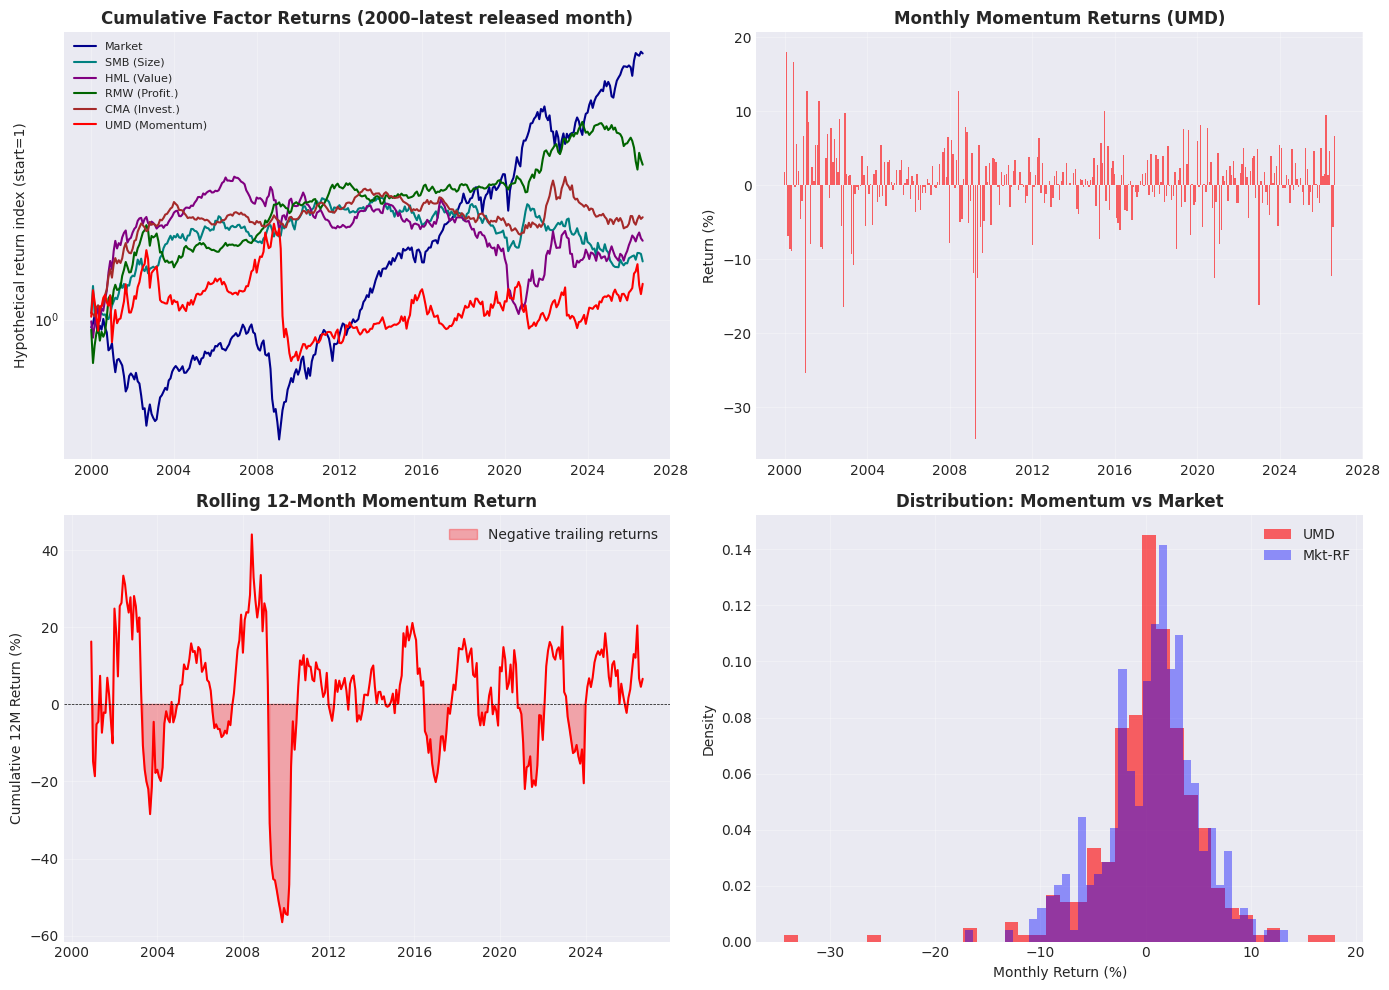
Momentum (UMD) Summary Statistics:
  Mean monthly return:    0.21%
  Monthly std dev:        5.10%
  Annualized return:      2.50%
  Annualized volatility:  17.66%
  Sharpe ratio:           0.14
  Skewness:               -1.44
  Kurtosis:               8.92
  Worst month:            -34.36%
  Best month:             18.05%
Inspect the reported skewness, tail outcomes and sample mean. Historical crash exposure does not establish a future premium.
# ============================================================================
# Carhart 4-Factor Model: Regression for all ETFs
# ============================================================================

print("="*70)
print("CARHART 4-FACTOR MODEL (FF3 + MOMENTUM)")
print("="*70)

carhart_cols = ['Mkt_RF', 'SMB', 'HML', 'UMD']

for ticker, label in etf_tickers.items():
    edf = etf_dataframes[ticker]
    res4 = run_ff_regression(None, carhart_cols, edf, stock_name=label)

    print(f"\n{label}")
    print("-" * 50)
    names = ['Alpha', 'Mkt_RF', 'SMB', 'HML', 'UMD']
    for i, name in enumerate(names):
        sig = '***' if res4.pvalues[i] < 0.01 else ('**' if res4.pvalues[i] < 0.05 else ('*' if res4.pvalues[i] < 0.10 else ''))
        print(f"  {name:10s} = {res4.params[i]:8.4f}  (t = {res4.tvalues[i]:6.2f}, p = {res4.pvalues[i]:.4f}) {sig}")
    print(f"  R² = {res4.rsquared:.4f}   Adj R² = {res4.rsquared_adj:.4f}")

print('Compare each UMD loading and interval. Value and momentum return correlations vary with the sample; diversification is not guaranteed.')
======================================================================
CARHART 4-FACTOR MODEL (FF3 + MOMENTUM)
======================================================================
SPY (S&P 500)
--------------------------------------------------
Alpha = -0.0002 (t = -1.12, p = 0.2612)
Mkt_RF = 0.9888 (t = 222.12, p = 0.0000) ***
SMB = -0.1380 (t = -17.51, p = 0.0000) ***
HML = 0.0129 (t = 2.23, p = 0.0261) **
UMD = -0.0020 (t = -0.43, p = 0.6690)
R² = 0.9960 Adj R² = 0.9959
IWN (Small Cap Value)
--------------------------------------------------
Alpha = -0.0008 (t = -1.42, p = 0.1549)
Mkt_RF = 0.9665 (t = 73.25, p = 0.0000) ***
SMB = 0.8180 (t = 34.13, p = 0.0000) ***
HML = 0.5275 (t = 23.88, p = 0.0000) ***
UMD = 0.0057 (t = 0.30, p = 0.7640)
R² = 0.9794 Adj R² = 0.9790
VTV (Large Cap Value)
--------------------------------------------------
Alpha = -0.0002 (t = -0.40, p = 0.6908)
Mkt_RF = 0.8891 (t = 44.98, p = 0.0000) ***
SMB = -0.1240 (t = -4.92, p = 0.0000) ***
HML = 0.3663 (t = 14.34, p = 0.0000) ***
UMD = -0.0133 (t = -0.84, p = 0.4007)
R² = 0.9471 Adj R² = 0.9463
Compare each UMD loading and interval. Value and momentum return correlations vary with the sample; diversification is not guaranteed.
Section 3: Profitability — Novy-Marx and Beyond
Gross profitability, , and the operating-profitability measure used for RMW are distinct signals. Novy-Marx’s research studies profitability alongside valuation; profitability can add information beyond a simple cheap-versus-expensive sort. See The Other Side of Value (2013), via the author’s research page.
French’s RMW instead uses operating profitability in size/profitability portfolios. The current definition and eligibility rules are given in the French FF5 description.
A characteristic correlation (cheap firms often have weaker profitability) is different from the correlation between factor returns. The latter is measured below and varies over time. Combining factor spreads illustrates diversification; it does not replicate a fund that jointly screens individual stocks.
“Quality” can combine profitability, leverage, earnings stability and other signals. Evaluate the actual definition rather than treating every quality fund as an RMW portfolio. Selecting signals after inspecting their backtests creates multiple-testing and selection bias; a weak standalone signal can still add conditional information, so individual p-values alone are not a sound selection rule.
Neither high profitability nor a positive realized RMW premium proves a risk-based or behavioural explanation. The DDM comparative statics are conditional on expected cash flows and valuation assumptions.
Source
# ============================================================================
# Profitability Factor Deep Dive
# ============================================================================

print("="*70)
print("PROFITABILITY FACTOR (RMW) DEEP DIVE")
print("="*70)

# RMW statistics
rmw = factors['RMW']
print(f"\nRMW (Robust Minus Weak) Summary:")
print(f"  Mean monthly:       {rmw.mean()*100:.2f}%")
print(f"  Annualized return:  {rmw.mean()*1200:.2f}%")
print(f"  Ann. volatility:    {rmw.std()*np.sqrt(12)*100:.2f}%")
print(f"  Sharpe ratio:       {rmw.mean()/rmw.std()*np.sqrt(12):.2f}")
print(f"  HAC z (mean=0):    {mean_hac(rmw).tvalues[0]:.2f}")
print(f"  Skewness:           {rmw.skew():.2f}")
print(f"  Correlation w/ HML: {factors['RMW'].corr(factors['HML']):.3f}")
print(f"  Correlation w/ UMD: {factors['RMW'].corr(factors['UMD']):.3f}")

# Interaction: Value × Profitability
# Compare the measured HML/RMW correlation and historical returns
fig, axes = plt.subplots(1, 3, figsize=(16, 5))

# Plot 1: RMW vs HML scatter
ax = axes[0]
ax.scatter(factors['HML'] * 100, factors['RMW'] * 100, alpha=0.4, s=30)
z = np.polyfit(factors['HML'], factors['RMW'], 1)
p = np.poly1d(z)
x_range = np.linspace(factors['HML'].min(), factors['HML'].max(), 100)
ax.plot(x_range * 100, p(x_range) * 100, 'r-', linewidth=2)
ax.set_xlabel('HML Return (%)')
ax.set_ylabel('RMW Return (%)')
ax.set_title('Value vs Profitability\n(Sample correlation, not a diversification guarantee)', fontweight='bold')
ax.grid(True, alpha=0.3)
corr_val = factors['HML'].corr(factors['RMW'])
ax.annotate(f'r = {corr_val:.2f}', xy=(0.05, 0.95), xycoords='axes fraction',
            fontsize=12, fontweight='bold', va='top')

# Plot 2: Cumulative returns of HML, RMW, and combined
ax = axes[1]
combined = (factors['HML'] + factors['RMW']) / 2  # Equal-weight combination
cum_hml = (1 + factors['HML']).cumprod()
cum_rmw = (1 + factors['RMW']).cumprod()
cum_combined = (1 + combined).cumprod()
ax.plot(factors.index, cum_hml, label='HML (Value)', color='purple', linewidth=1.5)
ax.plot(factors.index, cum_rmw, label='RMW (Profitability)', color='darkgreen', linewidth=1.5)
ax.plot(factors.index, cum_combined, label='50/50 Blend', color='black', linewidth=2, linestyle='--')
ax.set_title('Cumulative Returns:\nValue, Profitability, and Blend', fontweight='bold')
ax.set_ylabel('Hypothetical return index (start=1)')
ax.legend(fontsize=9)
ax.grid(True, alpha=0.3)

# Plot 3: Rolling correlation between HML and RMW
ax = axes[2]
rolling_corr = factors['HML'].rolling(36).corr(factors['RMW'])
ax.plot(factors.index, rolling_corr, color='darkred', linewidth=1.5)
ax.axhline(0, color='black', linewidth=0.5, linestyle='--')
ax.set_title('Rolling 36-Month Correlation\nHML vs RMW', fontweight='bold')
ax.set_ylabel('Correlation')
ax.grid(True, alpha=0.3)

plt.tight_layout()
plt.show()

print('Read the measured full-sample and rolling correlations. Correlations of characteristics, factor spreads and fund returns are different quantities.')
======================================================================
PROFITABILITY FACTOR (RMW) DEEP DIVE
======================================================================
RMW (Robust Minus Weak) Summary:
Mean monthly: 0.35%
Annualized return: 4.18%
Ann. volatility: 10.33%
Sharpe ratio: 0.40
HAC z (mean=0): 2.14
Skewness: -0.26
Correlation w/ HML: 0.338
Correlation w/ UMD: 0.033
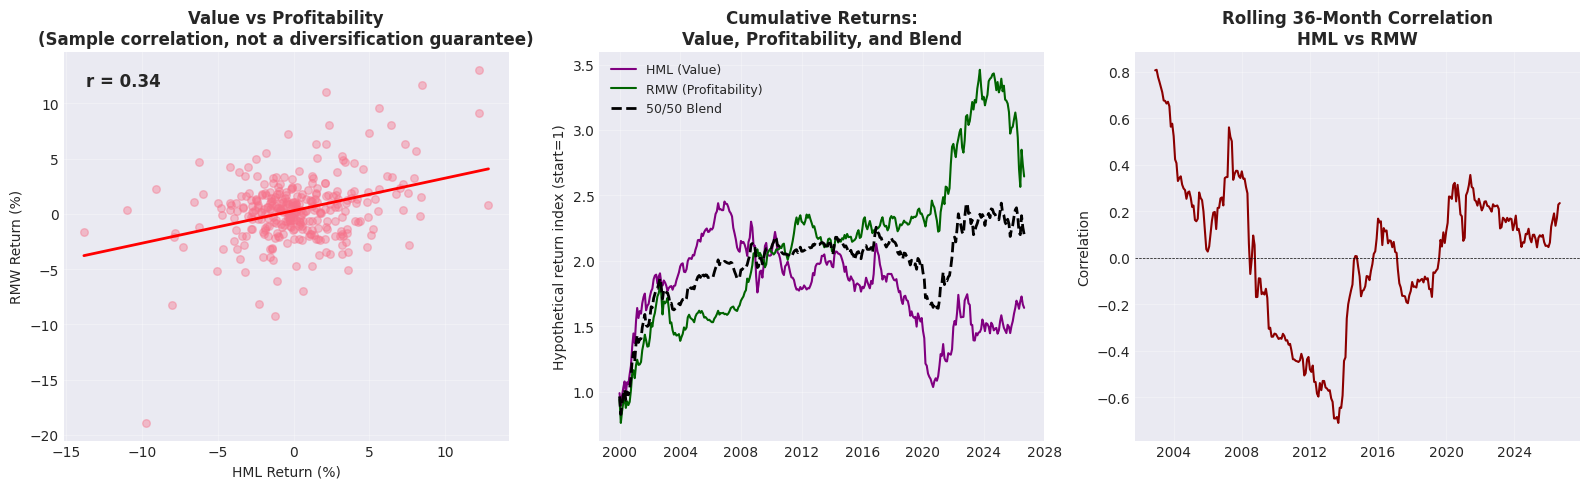
Read the measured full-sample and rolling correlations. Correlations of characteristics, factor spreads and fund returns are different quantities.
Section 4: Short-Term Reversals, Long-Term Reversals, and Mean Reversion
Cross-sectional sorts ask whether stocks with different past performance subsequently earn different returns. French supplies short-term reversal (prior month), momentum (prior months 2–12), and long-term reversal (prior months 13–60) return spreads. Their construction is documented in the Data Library.
Short-term reversal can reflect liquidity provision and price pressure; transaction costs are particularly important for high-turnover implementations. Long-term reversal overlaps with valuation effects but is not identical to HML. A losing stock or factor is not guaranteed to recover.
The final panel below plots the aggregate market’s autocorrelation as a different diagnostic. Market time-series autocorrelation cannot establish the cross-sectional reversal or momentum effects. All reported premiums are realized sample means, with HAC mean tests.
Source
# ============================================================================
# Reversal Factors Analysis
# ============================================================================

print("="*70)
print("SHORT-TERM AND LONG-TERM REVERSAL FACTORS")
print("="*70)

for col, name in [('ST_Rev', 'Short-Term Reversal'), ('LT_Rev', 'Long-Term Reversal')]:
    r = factors[col]
    tstat = mean_hac(r).tvalues[0]
    print(f"\n{name} ({col}):")
    print(f"  Mean monthly:       {r.mean()*100:.2f}%")
    print(f"  Annualized return:  {r.mean()*1200:.2f}%")
    print(f"  Ann. volatility:    {r.std()*np.sqrt(12)*100:.2f}%")
    print(f"  Sharpe ratio:       {r.mean()/r.std()*np.sqrt(12):.2f}")
    print(f"  t-stat:             {tstat:.2f}")

# Correlation with other factors
print("\n\nCORRELATION OF REVERSAL FACTORS WITH STANDARD FACTORS:")
rev_corr_cols = ['Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA', 'UMD', 'ST_Rev', 'LT_Rev']
print(factors[rev_corr_cols].corr()[['ST_Rev', 'LT_Rev']].round(3))

# Visualization
fig, axes = plt.subplots(2, 2, figsize=(14, 10))

# Plot 1: Cumulative reversal factor returns
ax = axes[0, 0]
cum_st = (1 + factors['ST_Rev']).cumprod()
cum_lt = (1 + factors['LT_Rev']).cumprod()
cum_mom = (1 + factors['UMD']).cumprod()
ax.plot(factors.index, cum_st, label='ST Reversal', color='orange', linewidth=1.5)
ax.plot(factors.index, cum_lt, label='LT Reversal', color='darkblue', linewidth=1.5)
ax.plot(factors.index, cum_mom, label='Momentum (UMD)', color='red', linewidth=1.5, linestyle='--')
ax.set_title('Reversal vs Momentum: Cumulative Returns', fontweight='bold')
ax.set_ylabel('Hypothetical return index (start=1)')
ax.legend()
ax.grid(True, alpha=0.3)

# Plot 2: Monthly return comparison
ax = axes[0, 1]
ax.scatter(factors['UMD'] * 100, factors['ST_Rev'] * 100, alpha=0.4, s=30, color='orange')
ax.set_xlabel('Momentum (UMD) Return (%)')
ax.set_ylabel('ST Reversal Return (%)')
corr_sm = factors['UMD'].corr(factors['ST_Rev'])
ax.set_title(f'Momentum vs ST Reversal (r = {corr_sm:.2f})', fontweight='bold')
ax.grid(True, alpha=0.3)
ax.axhline(0, color='gray', linewidth=0.5)
ax.axvline(0, color='gray', linewidth=0.5)

# Plot 3: LT Reversal vs HML
ax = axes[1, 0]
ax.scatter(factors['HML'] * 100, factors['LT_Rev'] * 100, alpha=0.4, s=30, color='purple')
ax.set_xlabel('HML (Value) Return (%)')
ax.set_ylabel('LT Reversal Return (%)')
corr_lh = factors['HML'].corr(factors['LT_Rev'])
ax.set_title(f'Value vs LT Reversal (r = {corr_lh:.2f})', fontweight='bold')
ax.grid(True, alpha=0.3)
ax.axhline(0, color='gray', linewidth=0.5)
ax.axvline(0, color='gray', linewidth=0.5)

# Plot 4: Autocorrelation of market returns at different lags
# Aggregate market autocorrelation is distinct from cross-sectional reversal sorts.
ax = axes[1, 1]
mkt_returns = factors['Mkt_RF']
lags = list(range(1, 61))  # 1 to 60 months
autocorrs = [mkt_returns.autocorr(lag=l) for l in lags]
colors_ac = ['orange' if l <= 1 else ('red' if l <= 12 else 'darkblue') for l in lags]
ax.bar(lags, autocorrs, color=colors_ac, alpha=0.7, width=0.8)
ax.axhline(0, color='black', linewidth=0.5)
# Add significance band (approximate 95% CI for white noise)
n_obs = len(mkt_returns)
sig_bound = 1.96 / np.sqrt(n_obs)
ax.axhline(sig_bound, color='gray', linewidth=0.8, linestyle='--', alpha=0.6)
ax.axhline(-sig_bound, color='gray', linewidth=0.8, linestyle='--', alpha=0.6)
ax.set_xlabel('Lag (months)')
ax.set_ylabel('Autocorrelation')
ax.set_title('Market Return Autocorrelation by Lag\n(orange=1mo, red=2-12mo, blue=13-60mo)', fontweight='bold')
ax.grid(True, alpha=0.3, axis='y')

plt.tight_layout()
plt.show()

print('Read the reported reversal correlations. Aggregate market autocorrelation is not a test of cross-sectional momentum or reversal.')
======================================================================
SHORT-TERM AND LONG-TERM REVERSAL FACTORS
======================================================================
Short-Term Reversal (ST_Rev):
Mean monthly: 0.14%
Annualized return: 1.65%
Ann. volatility: 13.31%
Sharpe ratio: 0.12
t-stat: 0.78
Long-Term Reversal (LT_Rev):
Mean monthly: 0.06%
Annualized return: 0.75%
Ann. volatility: 10.10%
Sharpe ratio: 0.07
t-stat: 0.34
CORRELATION OF REVERSAL FACTORS WITH STANDARD FACTORS:
        ST_Rev  LT_Rev
Mkt_RF   0.330   0.113
SMB      0.134   0.404
HML      0.036   0.528
RMW     -0.057  -0.201
CMA     -0.182   0.526
UMD     -0.261   0.016
ST_Rev   1.000   0.086
LT_Rev   0.086   1.000
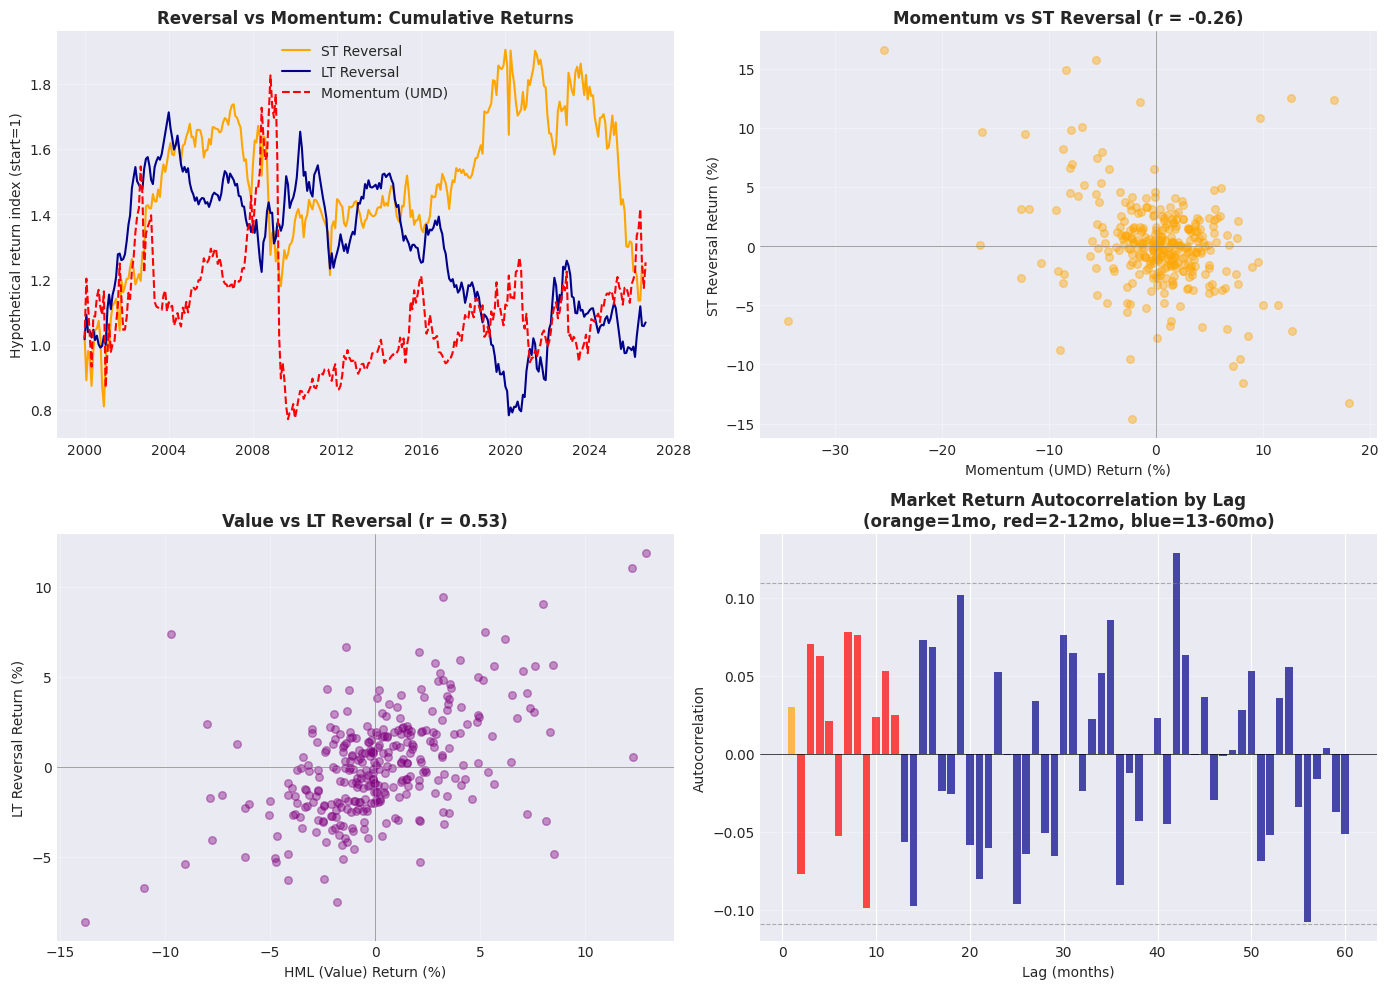
Read the reported reversal correlations. Aggregate market autocorrelation is not a test of cross-sectional momentum or reversal.
Section 5: The Beta Anomaly and Betting Against Beta
The CAPM predicts . Empirical security-market-line studies often find a weaker beta–return relationship than this predicts. Leverage constraints are one explanation: constrained investors can seek higher exposure through high-beta securities, affecting prices. This does not establish that broad indexing is inefficient for every investor or that low-beta strategies must outperform.
Frazzini and Pedersen construct BAB using low- and high-beta stock portfolios, scaling each side to comparable predicted market exposure. See Betting Against Beta (2014). Market neutrality is an estimated property, not a guarantee, and a nonzero spread return is not necessarily alpha relative to additional factors.
Here we use French’s value-weighted beta deciles. The SML is descriptive: full-sample realized betas are estimated regressors, so a fitted line through ten portfolio means is not a formal cross-sectional pricing test.
For a BAB-like illustration, we scale the extreme-decile excess returns by betas estimated over the previous 60 months, shifted one month. This avoids using future returns to set historical leverage. It is a decile proxy, not a replication of the paper’s stock-level construction. Both simple and scaled spreads use the same post-warmup sample for performance comparison.
The proxy omits borrowing spreads, short availability, transaction costs and estimation risk. Novy-Marx and Velikov’s implementation critique is relevant to interpretation, but its findings do not turn our proxy into a tested live strategy. Betting Against Betting Against Beta (2022), author publication list.
Source
# ============================================================================
# The Beta Anomaly: Empirical Security Market Line
# ============================================================================

print("="*70)
print("THE BETA ANOMALY — FLAT SECURITY MARKET LINE")
print("="*70)

# ---- Download beta-sorted decile portfolios from Ken French ----
# This file contains monthly returns for 10 portfolios sorted by pre-ranking
# market beta. We'll use value-weighted returns.

download_beta_portfolios = load_beta_portfolios

print("Downloading beta-sorted decile portfolios from Ken French...")
beta_ports = download_beta_portfolios()

# Filter to our analysis period
beta_ports = beta_ports.loc['2000-01-01':]
beta_ports = beta_ports.loc[beta_ports.index.intersection(factors.index)]
print(f"Beta-sorted decile portfolios: {beta_ports.shape[0]} months")
print(f"Deciles: D1 (lowest beta) through D10 (highest beta)\n")

# ---- Compute average excess returns and realized betas ----
rf_aligned = factors.loc[beta_ports.index, 'RF']
mkt_aligned = factors.loc[beta_ports.index, 'Mkt_RF']

avg_excess_returns = []
realized_betas = []
decile_labels = []

print(f"{'Decile':<10s} {'Avg Excess Ret (ann %)':>22s} {'Realized Beta':>14s} "
      f"{'Volatility (ann %)':>20s} {'Sharpe Ratio':>13s}")
print("-" * 82)

for col in beta_ports.columns:
    excess = beta_ports[col] - rf_aligned

    # Realized beta from regression on market
    X = sm.add_constant(mkt_aligned.values)
    res = sm.OLS(excess.values, X).fit()
    beta_hat = res.params[1]

    ann_ret = excess.mean() * 12 * 100
    ann_vol = excess.std() * np.sqrt(12) * 100
    sharpe = excess.mean() / excess.std() * np.sqrt(12)

    avg_excess_returns.append(ann_ret)
    realized_betas.append(beta_hat)
    decile_labels.append(col)

    print(f"{col:<10s} {ann_ret:22.2f} {beta_hat:14.2f} {ann_vol:20.2f} {sharpe:13.2f}")

avg_excess_returns = np.array(avg_excess_returns)
realized_betas = np.array(realized_betas)

# ---- The Punchline: Plot the Empirical SML ----
fig, axes = plt.subplots(1, 2, figsize=(16, 7))

# Left panel: Empirical SML vs CAPM prediction
ax = axes[0]
ax.scatter(realized_betas, avg_excess_returns, s=120, c='darkblue', zorder=5,
           edgecolors='white', linewidth=1.5)

for i, label in enumerate(decile_labels):
    ax.annotate(label, (realized_betas[i], avg_excess_returns[i]),
                textcoords="offset points", xytext=(8, 5), fontsize=9,
                fontweight='bold', color='darkblue')

# Theoretical CAPM line: passes through (0, 0) and (1, market premium)
mkt_premium_ann = mkt_aligned.mean() * 12 * 100
beta_range = np.linspace(0, max(realized_betas) * 1.1, 100)
capm_line = beta_range * mkt_premium_ann
ax.plot(beta_range, capm_line, 'r--', linewidth=2, label='CAPM Prediction',
        alpha=0.8)

# Best-fit line through the data
slope, intercept = np.polyfit(realized_betas, avg_excess_returns, 1)
fit_line = slope * beta_range + intercept
ax.plot(beta_range, fit_line, 'b-', linewidth=2.5,
        label=f'Empirical Fit (slope={slope:.1f})', alpha=0.9)

ax.set_xlabel('Realized Market Beta', fontsize=12, fontweight='bold')
ax.set_ylabel('Average Annualized Excess Return (%)', fontsize=12, fontweight='bold')
ax.set_title('The Empirical Security Market Line\n(Beta-Sorted Decile Portfolios, 2000–latest released month)',
             fontsize=13, fontweight='bold')
ax.legend(fontsize=11, loc='upper left')
ax.grid(True, alpha=0.3)

# Right panel: Sharpe ratio by decile
ax = axes[1]
sharpe_ratios = []
for col in beta_ports.columns:
    excess = beta_ports[col] - rf_aligned
    sharpe_ratios.append(excess.mean() / excess.std() * np.sqrt(12))

colors = plt.cm.RdYlGn_r(np.linspace(0.1, 0.9, 10))
bars = ax.bar(range(1, 11), sharpe_ratios, color=colors, edgecolor='black',
              linewidth=0.8)
ax.set_xlabel('Beta Decile (1=Lowest, 10=Highest)', fontsize=12, fontweight='bold')
ax.set_ylabel('Sharpe Ratio', fontsize=12, fontweight='bold')
ax.set_title('Risk-Adjusted Returns by Beta Decile\n(Higher is Better)',
             fontsize=13, fontweight='bold')
ax.set_xticks(range(1, 11))
ax.axhline(0, color='black', linewidth=0.5)
ax.grid(True, alpha=0.3, axis='y')

# Add value labels on bars
for bar, sr in zip(bars, sharpe_ratios):
    ax.text(bar.get_x() + bar.get_width() / 2, bar.get_height() + 0.01,
            f'{sr:.2f}', ha='center', va='bottom', fontsize=9, fontweight='bold')

plt.tight_layout()
plt.show()

# ---- Construct a simple BAB-like factor ----
print("\n" + "="*70)
print("SIMPLE BAB FACTOR: LONG LOW-BETA (D1) − SHORT HIGH-BETA (D10)")
print("="*70)

bab_simple = (beta_ports['D1'] - rf_aligned) - (beta_ports['D10'] - rf_aligned)
# More properly: BAB = (1/beta_low)(D1 - RF) - (1/beta_high)(D10 - RF)
# but for illustration the simple spread is instructive

# Estimate each beta from the prior 60 months, with a one-month information lag.
# This decile proxy is not the stock-level Frazzini–Pedersen BAB replication.
low_excess = beta_ports['D1'] - rf_aligned
high_excess = beta_ports['D10'] - rf_aligned
rolling_variance = mkt_aligned.rolling(60).var()
beta_low = (low_excess.rolling(60).cov(mkt_aligned) / rolling_variance).shift(1)
beta_high = (high_excess.rolling(60).cov(mkt_aligned) / rolling_variance).shift(1)
valid = (beta_low > 0.1) & (beta_high > 0.1)
bab_leveraged = (low_excess / beta_low - high_excess / beta_high).where(valid).dropna()
coverage('BAB-like proxy (prior 60-month beta scaling)', bab_leveraged)
bab_simple_comparable = bab_simple.loc[bab_leveraged.index]

for name, ret in [('Simple (D1 − D10)', bab_simple_comparable),
                   ('Lagged-beta decile proxy', bab_leveraged)]:
    ann_ret = ret.mean() * 12 * 100
    ann_vol = ret.std() * np.sqrt(12) * 100
    sharpe = ret.mean() / ret.std() * np.sqrt(12)
    tstat = mean_hac(ret).tvalues[0]
    cum = (1 + ret).cumprod()
    maxdd = (cum / cum.cummax().clip(lower=1) - 1).min() * 100
    print(f"\n  {name}:")
    print(f"    Ann. Return:   {ann_ret:7.2f}%")
    print(f"    Ann. Vol:      {ann_vol:7.2f}%")
    print(f"    Sharpe Ratio:  {sharpe:7.2f}")
    print(f"    t-statistic:   {tstat:7.2f}")
    print(f"    Max Drawdown:  {maxdd:7.1f}%")

# ---- Alpha test: regress BAB on FF5 + Momentum ----
print("\n" + "="*70)
print("DOES BAB HAVE ALPHA AFTER FF5 + MOMENTUM?")
print("="*70)

bab_aligned = bab_leveraged.reindex(factors.index).dropna()
ff_aligned = factors.loc[bab_aligned.index, ['Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA', 'UMD']]

X_ff = sm.add_constant(ff_aligned.values)
res_bab = sm.OLS(bab_aligned.values, X_ff).fit(
    cov_type='HAC', cov_kwds={'maxlags': 6, 'use_correction': True}, use_t=False
)

coef_names = ['Alpha'] + list(ff_aligned.columns)
print(f"\n{'Factor':<10s} {'Coef':>8s} {'t-stat':>8s} {'p-value':>9s}")
print("-" * 38)
for i, name in enumerate(coef_names):
    print(f"{name:<10s} {res_bab.params[i]:8.4f} {res_bab.tvalues[i]:8.2f} "
          f"{res_bab.pvalues[i]:9.4f}")
print(f"\nR² = {res_bab.rsquared:.3f}")
print(f"Alpha (annualized) = {res_bab.params[0] * 12 * 100:.2f}%")

# ---- Cumulative BAB vs individual factors ----
fig, axes = plt.subplots(1, 2, figsize=(16, 6))

ax = axes[0]
cum_bab = (1 + bab_leveraged).cumprod()
cum_mkt = (1 + factors.loc[bab_leveraged.index, 'Mkt_RF']).cumprod()
cum_hml = (1 + factors.loc[bab_leveraged.index, 'HML']).cumprod()
cum_rmw = (1 + factors.loc[bab_leveraged.index, 'RMW']).cumprod()

ax.plot(cum_bab.index, cum_bab, linewidth=2.5, label='BAB (Leveraged)', color='darkblue')
ax.plot(cum_mkt.index, cum_mkt, linewidth=1.5, label='Mkt-RF', color='red', alpha=0.7)
ax.plot(cum_hml.index, cum_hml, linewidth=1.5, label='HML', color='green', alpha=0.7)
ax.plot(cum_rmw.index, cum_rmw, linewidth=1.5, label='RMW', color='purple', alpha=0.7)
ax.set_title('Cumulative Returns: BAB vs Major Factors', fontsize=13, fontweight='bold')
ax.set_ylabel('Hypothetical return index (start=1)')
ax.legend(fontsize=10)
ax.grid(True, alpha=0.3)

# Drawdown of BAB
ax = axes[1]
dd_bab = (cum_bab / cum_bab.cummax().clip(lower=1) - 1) * 100
ax.fill_between(dd_bab.index, dd_bab, 0, alpha=0.4, color='darkblue')
ax.plot(dd_bab.index, dd_bab, linewidth=1, color='darkblue')
ax.set_title('BAB Factor Drawdowns', fontsize=13, fontweight='bold')
ax.set_ylabel('Drawdown (%)')
ax.grid(True, alpha=0.3)

plt.tight_layout()
plt.show()

print(f"Empirical cross-sectional slope {slope:.2f}; sample CAPM slope {mkt_premium_ann:.2f}.")
print(f"Proxy HAC alpha p-value: {res_bab.pvalues[0]:.4f}.")
print("This descriptive decile proxy omits trading, stock-borrow and financing spreads.")
print("Predetermined beta scaling avoids full-sample lookahead, but estimated exposures")
print("can change and the spread need not be market neutral out of sample.")
======================================================================
THE BETA ANOMALY — FLAT SECURITY MARKET LINE
======================================================================
Downloading beta-sorted decile portfolios from Ken French...
Beta-sorted decile portfolios: 321 months
Deciles: D1 (lowest beta) through D10 (highest beta)
Decile Avg Excess Ret (ann %) Realized Beta Volatility (ann %) Sharpe Ratio
----------------------------------------------------------------------------------
D1 7.09 0.50 11.67 0.61
D2 6.27 0.60 12.38 0.51
D3 8.24 0.78 14.06 0.59
D4 9.00 0.94 16.35 0.55
D5 8.11 0.97 16.66 0.49
D6 9.48 1.09 18.68 0.51
D7 8.95 1.19 19.95 0.45
D8 11.56 1.30 22.26 0.52
D9 12.22 1.48 25.96 0.47
D10 8.54 1.67 31.29 0.27
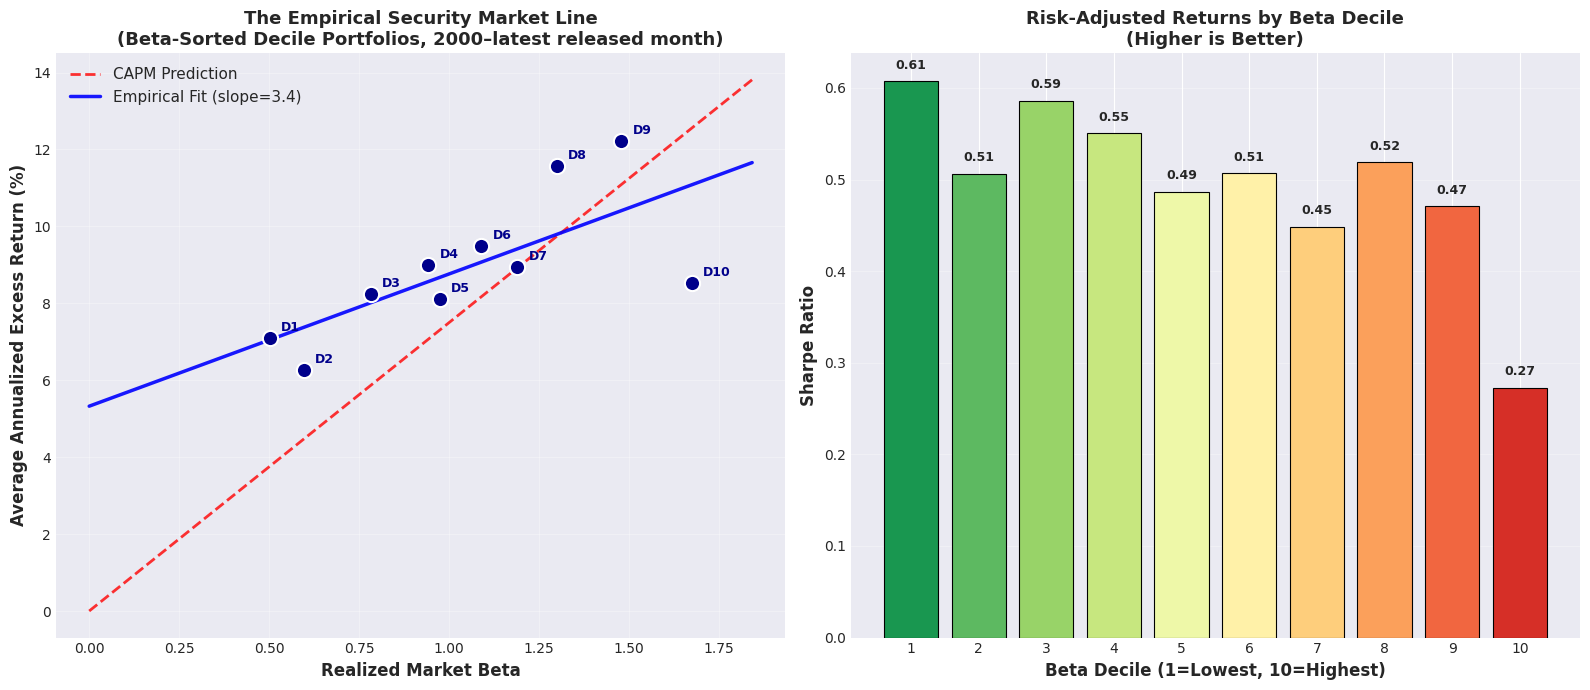
======================================================================
SIMPLE BAB FACTOR: LONG LOW-BETA (D1) − SHORT HIGH-BETA (D10)
======================================================================
BAB-like proxy (prior 60-month beta scaling): 261 observations, 2005-01-01 to 2026-09-01; as of 2026-10-31

  Simple (D1 − D10):
    Ann. Return:     -5.16%
    Ann. Vol:        27.98%
    Sharpe Ratio:    -0.18
    t-statistic:     -0.92
    Max Drawdown:    -90.1%

  Lagged-beta decile proxy:
    Ann. Return:      4.70%
    Ann. Vol:        23.08%
    Sharpe Ratio:     0.20
    t-statistic:      1.12
    Max Drawdown:    -49.6%

======================================================================
DOES BAB HAVE ALPHA AFTER FF5 + MOMENTUM?
======================================================================

Factor         Coef   t-stat   p-value
--------------------------------------
Alpha       -0.0018    -0.55    0.5792
Mkt_RF       0.2824     2.58    0.0100
SMB         -0.6975    -3.84    0.0001
HML          0.1727     0.77    0.4402
RMW          1.1290     5.61    0.0000
CMA          0.9079     2.82    0.0048
UMD          0.1973     1.64    0.1012

R² = 0.348
Alpha (annualized) = -2.11%
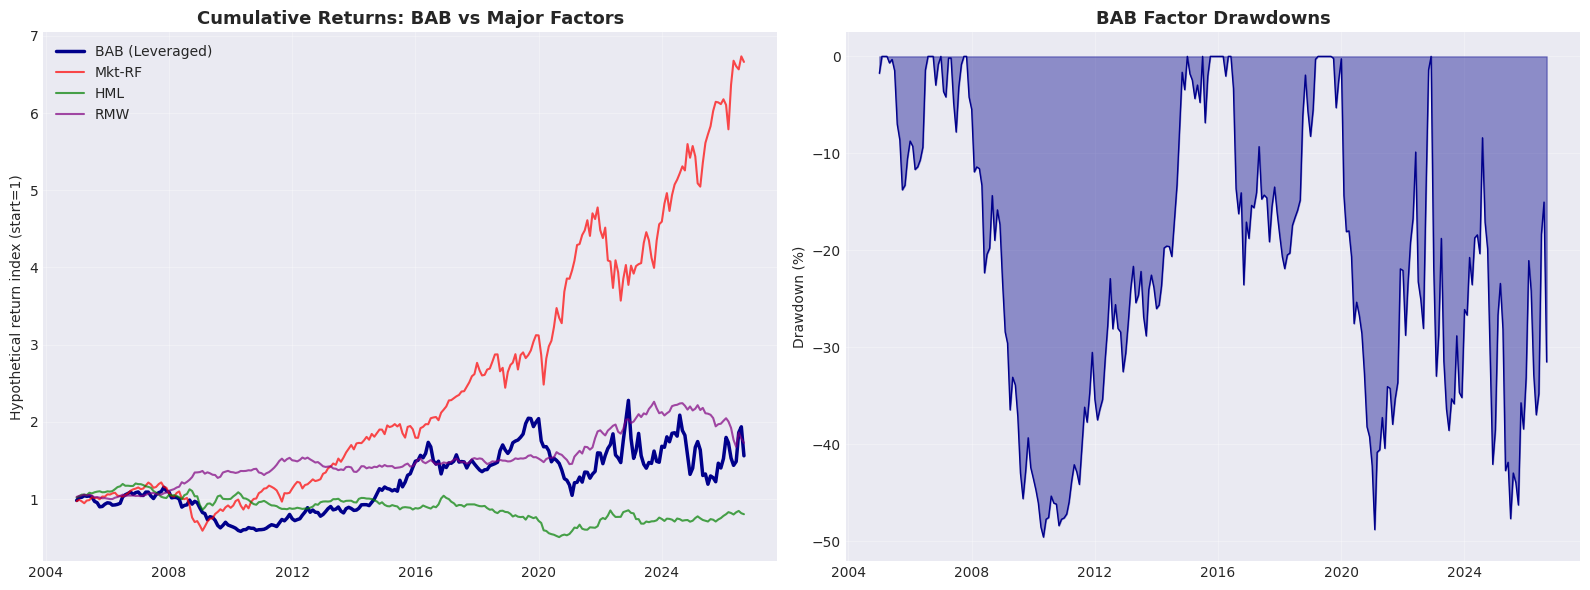
Empirical cross-sectional slope 3.44; sample CAPM slope 7.50.
Proxy HAC alpha p-value: 0.5792.
This descriptive decile proxy omits trading, stock-borrow and financing spreads.
Predetermined beta scaling avoids full-sample lookahead, but estimated exposures
can change and the spread need not be market neutral out of sample.
Section 6: Meta-Research — Replication, Discovery and Investability
These are separate questions:
Replication: Can a published result be reproduced with matching data and definitions?
Out-of-sample persistence: Does the signal predict returns after its research sample?
Investability: Does an implementable portfolio retain a useful return after costs?
Chen and Zimmermann’s Open Source Asset Pricing project supplies replication code and data. Its 28 October 2026 update moved to CRSP CIZ and updated data distribution and code. This notebook does not rerun that signal library; the new release is research context, not another computed dataset here. Different replication studies use different universes, definitions, weights and significance thresholds, so a single failure rate does not settle the entire literature.
Chen and Velikov’s 2023 JFQA paper (not Journal of Finance) examines 204 anomalies after spread costs, publication effects and changes in trading technology. Its published abstract reports approximately 4 basis points per month for the average anomaly and around 20 basis points per month for several combinations. These are results for the paper’s designs and cost assumptions, not expected returns for Avantis, Dimensional or any particular ETF. Published paper.
Chen, Lopez-Lira and Zimmermann compare published predictors with mechanical searches of accounting ratios. The version checked for this review is arXiv v7, revised 29 December 2025; it reports similar post-sample predictability for many categories. That finding challenges a particular selection process, not the usefulness of all economic theory. Versioned paper.
Novy-Marx and Velikov’s Assaying Anomalies remains listed under working papers on the author’s research page. It provides a testing framework; no paper offers an unconditional whitelist of profitable future factors.
The subperiod table below describes time variation in realized premiums. It does not identify a causal efficiency break in 2005, distinguish risk compensation from mispricing, or measure current valuation spreads. Those claims require additional data and research designs.
Source
# ============================================================================
# Research Deep Dive: Factor Performance Across Decades
# ============================================================================

print("="*70)
print("FACTOR PERFORMANCE BY DECADE")
print("="*70)

factor_cols_all = ['Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA', 'UMD']

# Define sub-periods
periods = {
    '2000-2004': ('2000-01-01', '2004-12-31'),
    '2005-2009': ('2005-01-01', '2009-12-31'),
    '2010-2014': ('2010-01-01', '2014-12-31'),
    '2015-2019': ('2015-01-01', '2019-12-31'),
    '2020-2024': ('2020-01-01', '2024-12-31'),
    f'2025–{factors.index[-1]:%Y-%m} (partial)': ('2025-01-01', AS_OF.strftime('%Y-%m-%d')),
}

decade_returns = {}
for period_name, (start, end) in periods.items():
    sub = factors.loc[start:end, factor_cols_all]
    ann_ret = sub.mean() * 12 * 100  # Annualized, in %
    decade_returns[period_name] = ann_ret

decade_df = pd.DataFrame(decade_returns).T
print("\nAnnualized Returns by Sub-Period (%):")
print(decade_df.round(2))

# Visualization
fig, axes = plt.subplots(2, 1, figsize=(14, 10))

# Plot 1: Heatmap of factor returns by period
ax = axes[0]
sns.heatmap(decade_df, annot=True, fmt='.1f', cmap='RdYlGn', center=0,
            ax=ax, linewidths=0.5, cbar_kws={'label': 'Annualized Return (%)'})
ax.set_title('Factor Returns by Sub-Period (%)\n'
             'Green = positive return, Red = negative return', fontweight='bold', fontsize=12)
ax.set_ylabel('')

# Plot 2: HML return index; this is not a valuation spread
ax = axes[1]
# Show the value factor's "death and resurrection"
hml_cum = (1 + factors['HML']).cumprod()
ax.plot(factors.index, hml_cum, color='purple', linewidth=2, label='HML Cumulative')
ax.set_title('The Value Factor: Drawdown and Recovery (2000–latest released month)', fontweight='bold', fontsize=12)
ax.set_ylabel('Hypothetical return index (start=1)')
ax.grid(True, alpha=0.3)

# Annotate key periods
ax.axvspan('2018-01-01', '2020-09-01', alpha=0.15, color='red', label='Value drawdown')
ax.axvspan('2020-10-01', '2022-12-31', alpha=0.15, color='green', label='Value recovery')
ax.legend()

plt.tight_layout()
plt.show()

print("Compare realized means across periods; the latest block is incomplete.")
print("Subperiod differences are not by themselves a structural-break test or forecast.")
======================================================================
FACTOR PERFORMANCE BY DECADE
======================================================================
Annualized Returns by Sub-Period (%):
Mkt_RF SMB HML RMW CMA UMD
2000-2004 -3.04 12.61 15.38 10.24 13.46 5.20
2005-2009 -0.37 1.51 0.52 6.38 -0.17 -3.18
2010-2014 15.54 1.47 -0.62 0.91 3.02 4.07
2015-2019 10.75 -2.18 -4.08 1.79 -2.63 2.29
2020-2024 12.83 -1.78 -0.29 7.51 0.44 2.86
2025–2026-09 (partial) 12.62 -3.58 7.83 -12.83 0.94 6.02
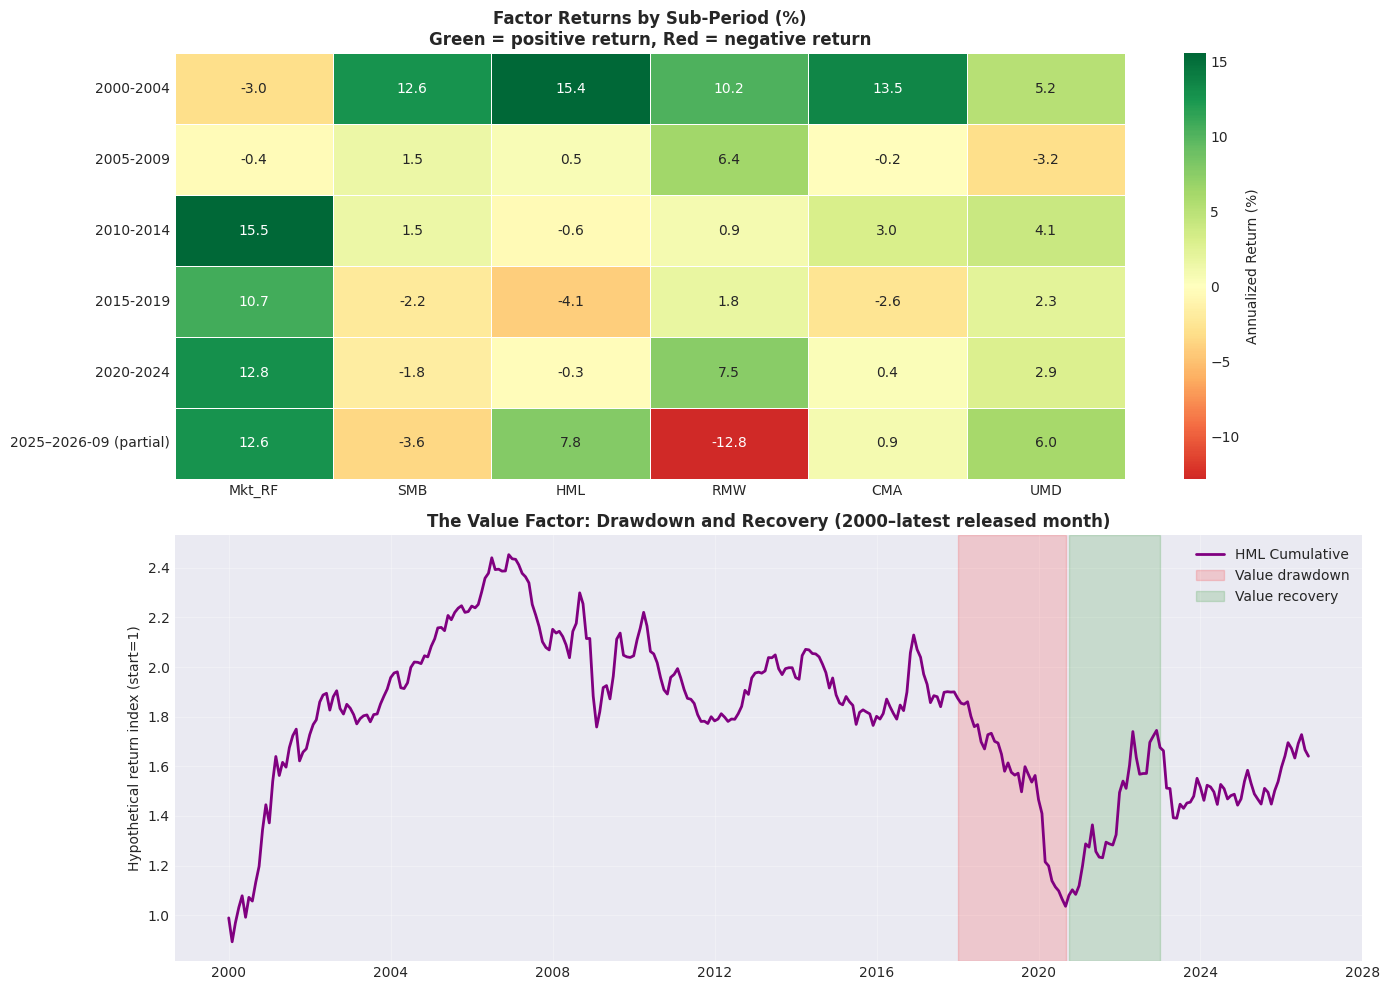
Compare realized means across periods; the latest block is incomplete.
Subperiod differences are not by themselves a structural-break test or forecast.
Source
# ============================================================================
# The "Kitchen Sink" Model: 5 Factors + Momentum on Our ETFs
# ============================================================================

print("="*70)
print("COMPREHENSIVE MODEL: FF5 + MOMENTUM")
print("="*70)
print("\nAdding UMD to the 5-factor model gives us the broadest")
print("specification considered here. Let's see how each ETF maps onto all six factors.\n")

full_cols = ['Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA', 'UMD']
full_names = ['Alpha', 'Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA', 'UMD']

all_params = {}
all_pvals = {}
all_r2 = {}

for ticker, label in etf_tickers.items():
    edf = etf_dataframes[ticker]
    res = run_ff_regression(None, full_cols, edf, stock_name=label)
    all_params[ticker] = res.params
    all_pvals[ticker] = res.pvalues
    all_r2[ticker] = res.rsquared

    print(f"\n{label}")
    print("-" * 60)
    for i, name in enumerate(full_names):
        sig = '***' if res.pvalues[i] < 0.01 else ('**' if res.pvalues[i] < 0.05 else ('*' if res.pvalues[i] < 0.10 else ''))
        print(f"  {name:10s} = {res.params[i]:9.5f}  (t={res.tvalues[i]:6.2f}, p={res.pvalues[i]:.4f}) {sig}")
    print(f"  R² = {res.rsquared:.4f}   Adj R² = {res.rsquared_adj:.4f}")

# Visualization: Factor loadings comparison
fig, ax = plt.subplots(figsize=(12, 6))
x = np.arange(len(full_names) - 1)  # Exclude alpha for visualization
width = 0.25

for i, (ticker, label) in enumerate(etf_tickers.items()):
    params_no_alpha = all_params[ticker][1:]  # Skip alpha
    bars = ax.bar(x + i * width, params_no_alpha, width, label=label, alpha=0.8)
    # Add significance markers
    for j, bar in enumerate(bars):
        p = all_pvals[ticker][j + 1]
        if p < 0.01:
            ax.text(bar.get_x() + bar.get_width()/2, bar.get_height(),
                    '***', ha='center', va='bottom', fontsize=8)

ax.set_xlabel('Factor')
ax.set_ylabel('Factor Loading (β)')
ax.set_title('Factor Loadings: FF5 + Momentum\n(*** = significant at 1% level, Newey-West SEs)',
             fontweight='bold', fontsize=12)
ax.set_xticks(x + width)
ax.set_xticklabels(full_names[1:])
ax.axhline(0, color='black', linewidth=0.5)
ax.legend()
ax.grid(True, alpha=0.3, axis='y')

plt.tight_layout()
plt.show()

print("""
INTERPRETATION GUIDE:
- Bar height = factor sensitivity (positive = tilts toward that factor)
- *** = statistically significant at 1% level
- SPY should be dominated by Mkt_RF ≈ 1, everything else near zero
- IWN should show positive SMB, positive HML, and possibly negative UMD
- VTV should show positive HML, possibly positive RMW
""")
======================================================================
COMPREHENSIVE MODEL: FF5 + MOMENTUM
======================================================================
Adding UMD to the 5-factor model gives us the broadest
specification considered here. Let's see how each ETF maps onto all six factors.
SPY (S&P 500)
------------------------------------------------------------
Alpha = -0.00029 (t= -2.01, p=0.0446) **
Mkt_RF = 0.99406 (t=174.55, p=0.0000) ***
SMB = -0.12317 (t=-17.58, p=0.0000) ***
HML = 0.02347 (t= 2.62, p=0.0087) ***
RMW = 0.04337 (t= 3.35, p=0.0008) ***
CMA = 0.02500 (t= 2.23, p=0.0256) **
UMD = -0.00206 (t= -0.38, p=0.7058)
R² = 0.9964 Adj R² = 0.9963
IWN (Small Cap Value)
------------------------------------------------------------
Alpha = -0.00104 (t= -2.04, p=0.0416) **
Mkt_RF = 0.96402 (t= 74.59, p=0.0000) ***
SMB = 0.82597 (t= 34.84, p=0.0000) ***
HML = 0.37638 (t= 15.73, p=0.0000) ***
RMW = 0.03425 (t= 1.37, p=0.1710)
CMA = -0.00417 (t= -0.13, p=0.8980)
UMD = 0.01594 (t= 0.84, p=0.3985)
R² = 0.9818 Adj R² = 0.9813
VTV (Large Cap Value)
------------------------------------------------------------
Alpha = -0.00045 (t= -0.85, p=0.3968)
Mkt_RF = 0.90282 (t= 43.69, p=0.0000) ***
SMB = -0.07301 (t= -2.42, p=0.0157) **
HML = 0.30416 (t= 10.18, p=0.0000) ***
RMW = 0.06971 (t= 2.23, p=0.0260) **
CMA = 0.18126 (t= 3.62, p=0.0003) ***
UMD = -0.01873 (t= -1.30, p=0.1929)
R² = 0.9512 Adj R² = 0.9501
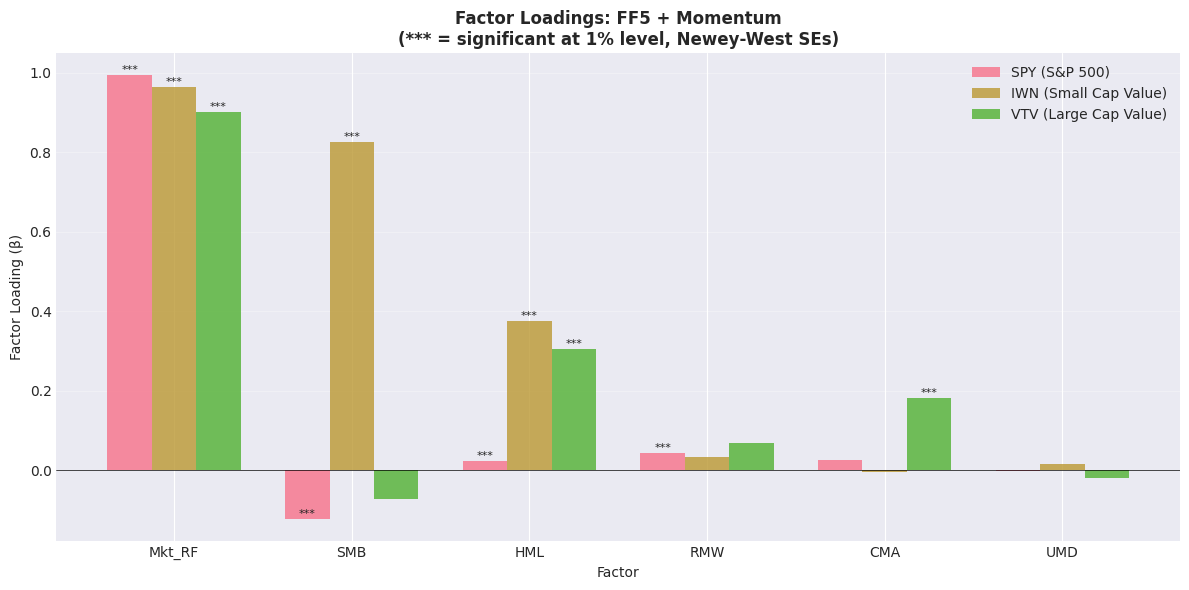
INTERPRETATION GUIDE:
- Bar height = factor sensitivity (positive = tilts toward that factor)
- *** = statistically significant at 1% level
- SPY should be dominated by Mkt_RF ≈ 1, everything else near zero
- IWN should show positive SMB, positive HML, and possibly negative UMD
- VTV should show positive HML, possibly positive RMW
Section 7: Implementation and Scenario Analysis
Academic spreads and investable products differ in stock universe, weighting, turnover, shorting, financing, fees and taxes. A long-only integrated fund can net trades across signals, but lower turnover alone does not establish superior net performance. Mixing separate funds can dilute exposures; that is a measurable portfolio-design question, not a universal prohibition.
Keep product assessment separate from factor theory. Examine mandate, diversification, trading costs, live tracking behaviour and uncertainty. An estimated factor beta is a conditional sensitivity, not the fraction of returns caused by that factor. A positive model-relative alpha need not reflect skill; an insignificant alpha does not prove a manager adds no value.
A clearly hypothetical comparison
The next cell compares a market portfolio with a factor tilt under assumed, constant annual drifts and tracking error. The tilt and benchmark share the same market shocks. Independent simulations of their market components would incorrectly inflate relative-performance uncertainty.
The scenarios include negative, zero and positive net tilt premiums. They are not research estimates, manager forecasts or recommendations. The simulation omits parameter uncertainty, structural changes, taxes and changing correlations; probabilities are conditional on the imposed model. We verify simulated relative-wealth probabilities against their analytical normal-model counterparts.
Source
# Hypothetical continuous-time lognormal model, annual time steps.
rng = np.random.default_rng(42)
n_simulations, years = 20_000, 30
market_drift, market_vol, tracking_error = 0.08, 0.16, 0.04
market_shocks = rng.normal(size=(n_simulations, years))
tracking_shocks = rng.normal(size=(n_simulations, years))
market_log = (market_drift - market_vol**2 / 2) + market_vol * market_shocks
market_terminal = np.exp(market_log.sum(axis=1))
scenarios = [-0.01, 0.0, 0.01, 0.02]
fig, axes = plt.subplots(1, 4, figsize=(18, 4.5), sharey=True)
for ax, net_premium in zip(axes, scenarios):
    # Shared market path; independent tracking component only.
    relative_log = net_premium - tracking_error**2 / 2 + tracking_error * tracking_shocks
    tilted_terminal = np.exp((market_log + relative_log).sum(axis=1))
    probability = np.mean(tilted_terminal > market_terminal)
    analytical = stats.norm.cdf((net_premium - tracking_error**2 / 2) * np.sqrt(years) / tracking_error)
    assert abs(probability - analytical) < 0.02
    ax.hist(np.log10(tilted_terminal / market_terminal), bins=50, density=True, alpha=0.7)
    ax.axvline(0, color='black', linestyle='--')
    ax.set_title(f'Assumed net premium {net_premium:+.0%}\nP(outperform) = {probability:.1%}')
    ax.set_xlabel('Log10(relative terminal wealth)')
    print(f'Net drift {net_premium:+.1%}: simulated {probability:.2%}; analytical {analytical:.2%}')
axes[0].set_ylabel('Density')
fig.suptitle('Hypothetical 30-year relative performance — shared market paths')
plt.tight_layout()
plt.show()
print('These probabilities depend entirely on imposed parameters, not estimates from ETF data.')
Net drift -1.0%: simulated 6.83%; analytical 6.96%
Net drift +0.0%: simulated 46.00%; analytical 45.64%
Net drift +1.0%: simulated 90.18%; analytical 89.61%
Net drift +2.0%: simulated 99.62%; analytical 99.57%
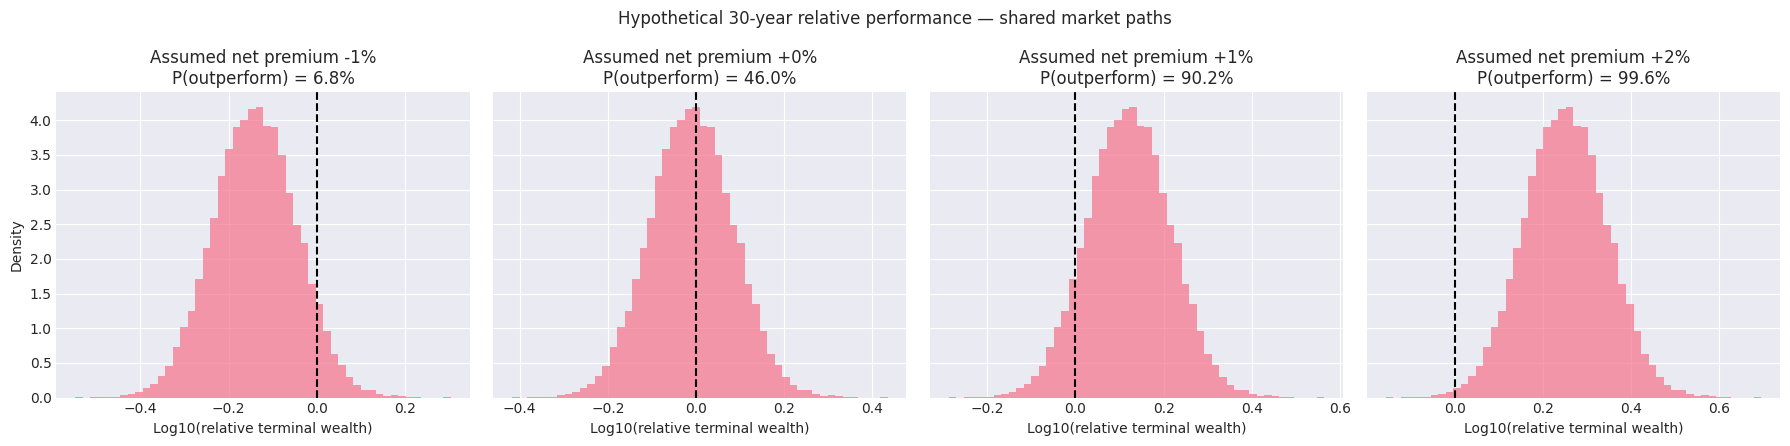
These probabilities depend entirely on imposed parameters, not estimates from ETF data.
Section 8: Rolling-Window Analysis — Time-Varying Factor Exposures
Why Rolling Windows?
The regressions so far estimate constant factor loadings over the full sample. But in the Time Series Foundations notebook we saw that financial data can exhibit regime changes and structural breaks — the statistical properties of returns are not necessarily stable over 20+ years. Factor exposures can change over time due to:
Changes in the index methodology or fund holdings
Market regime shifts (e.g., value rotation vs. growth dominance)
Varying sector composition within size/value groups
Volatility clustering (Section 4 of the Time Series notebook) — high-volatility regimes may alter factor sensitivities
Rolling-window regressions fit the model over a moving window (e.g., 36 months) and let us see how betas evolve. This is a powerful diagnostic tool and is used extensively by practitioners. It connects directly to the stationarity question from Section 2 of the Time Series notebook: if factor loadings are non-stationary, a full-sample regression gives us an average loading that may not reflect the current regime.
Why plain OLS inside each window? In the 3-Factor tutorial we used Newey-West standard errors to account for autocorrelation over the full sample. Inside each 36-month rolling window, the primary goal is estimating the point estimates (betas), not conducting hypothesis tests. OLS point estimates do not change with the covariance estimator; unbiasedness still requires exogeneity (Section 5 of the Statistical Foundations notebook), so Newey-West would change only the standard errors, not the estimated betas. Moreover, with only 36 observations the Newey-West long-run variance estimate becomes unreliable (few lags, few observations per lag). For these reasons, practitioners typically use plain OLS inside rolling windows and reserve HAC corrections for the full-sample inference.
Source
# Rolling estimates use only the window ending at the labelled month.
window = 36
roll_cols = ['Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA', 'UMD']
roll_names = ['Alpha monthly'] + roll_cols
for ticker, label in etf_tickers.items():
    edf = etf_dataframes[ticker]
    estimates, bounds, dates = [], [], []
    for i in range(window, len(edf)+1):
        d = edf.iloc[i-window:i]
        res = fit_hac(d.Stock_Excess_Return, d[roll_cols])
        estimates.append(res.params)
        bounds.append(res.conf_int())
        dates.append(edf.index[i-1])
    assert dates[-1] == edf.index[-1]
    estimates, bounds = np.asarray(estimates), np.asarray(bounds)
    fig, axes = plt.subplots(4, 2, figsize=(13, 11), sharex=True)
    for j, name in enumerate(roll_names):
        ax = axes.flat[j]
        ax.plot(dates, estimates[:,j], color='darkblue', linewidth=1)
        ax.fill_between(dates, bounds[:,j,0], bounds[:,j,1], alpha=.15, color='steelblue')
        ax.axhline(0, color='gray', linewidth=.6)
        ax.set_title(name)
    axes.flat[-1].set_visible(False)
    fig.suptitle(f'{label}: rolling {window}-month coefficients and pointwise 95% HAC intervals')
    fig.tight_layout()
    plt.show()
print('Overlapping windows are dependent; these exploratory intervals are not simultaneous bands or a structural-break test.')
print('Apparent beta shifts combine estimation noise and possible exposure changes. Passive funds can have nonzero model-relative alpha.')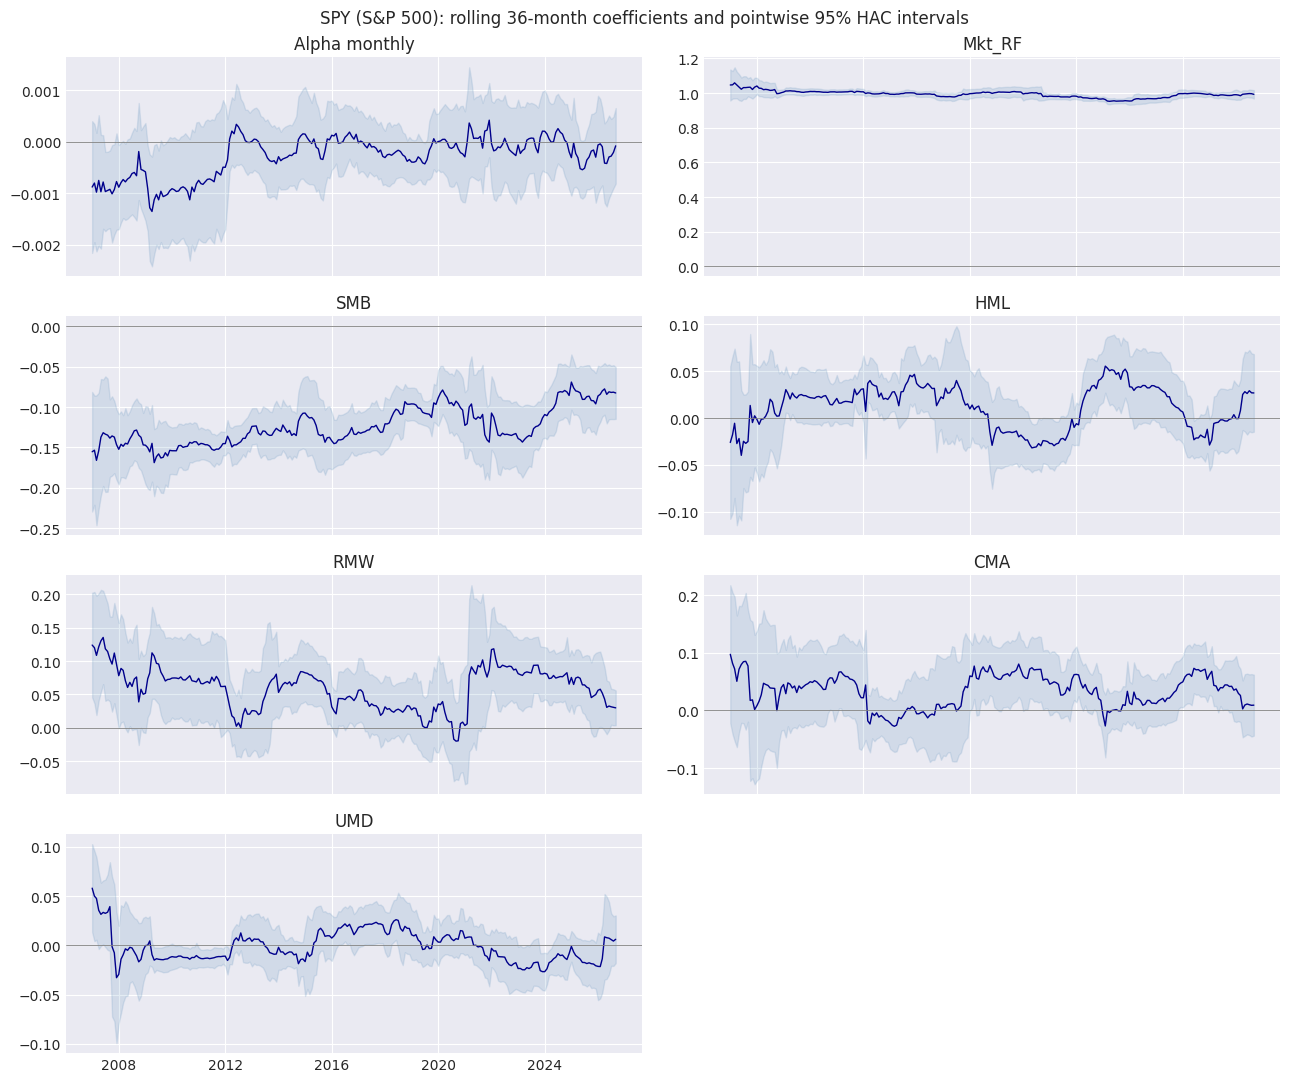
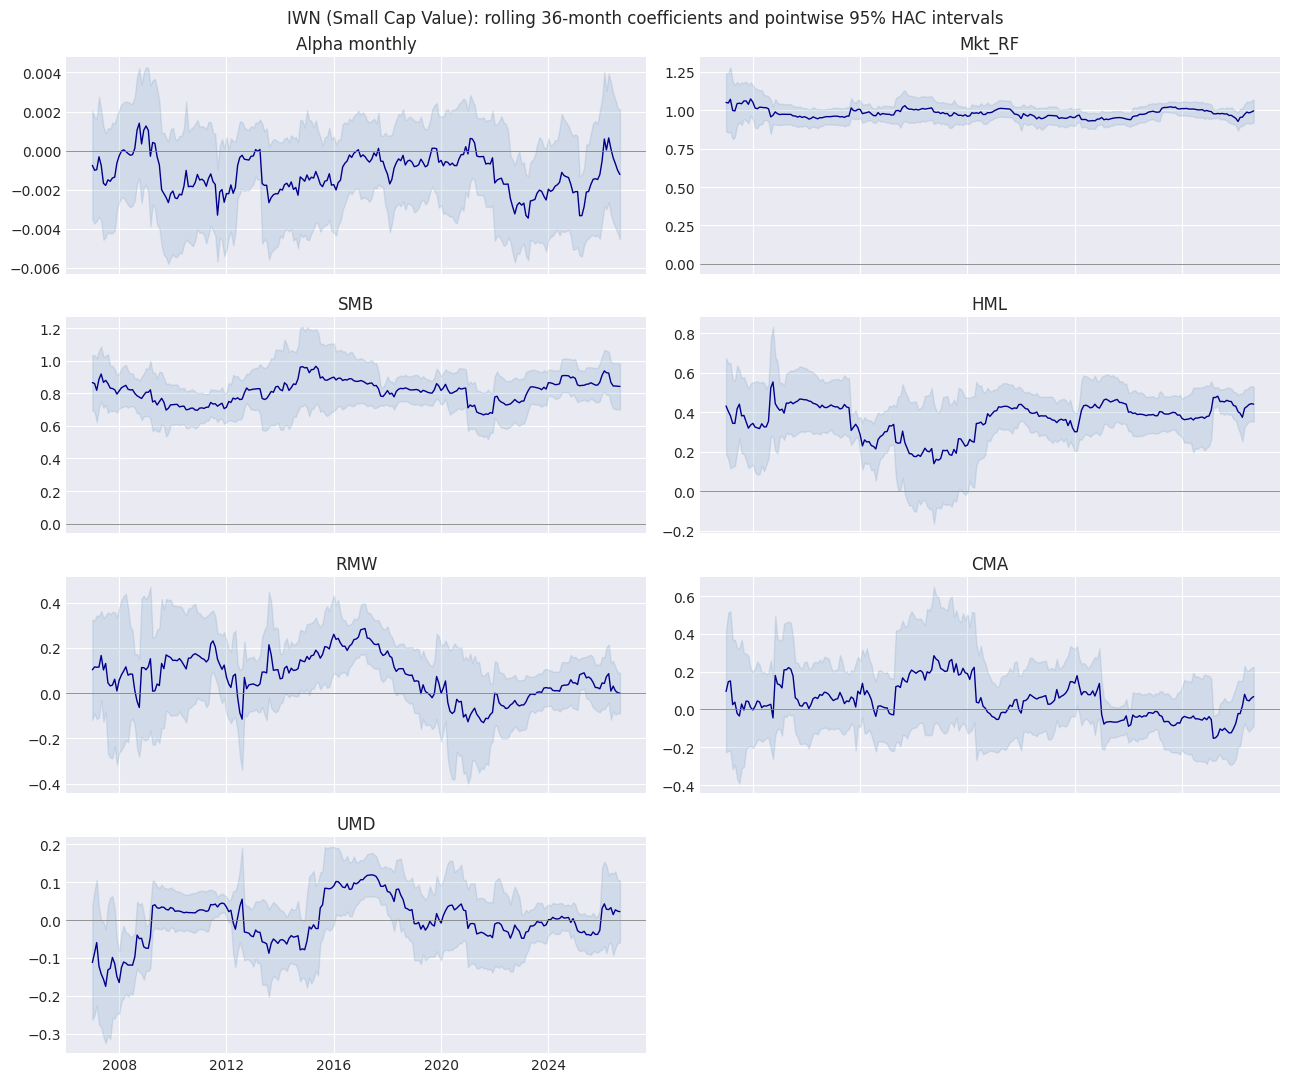
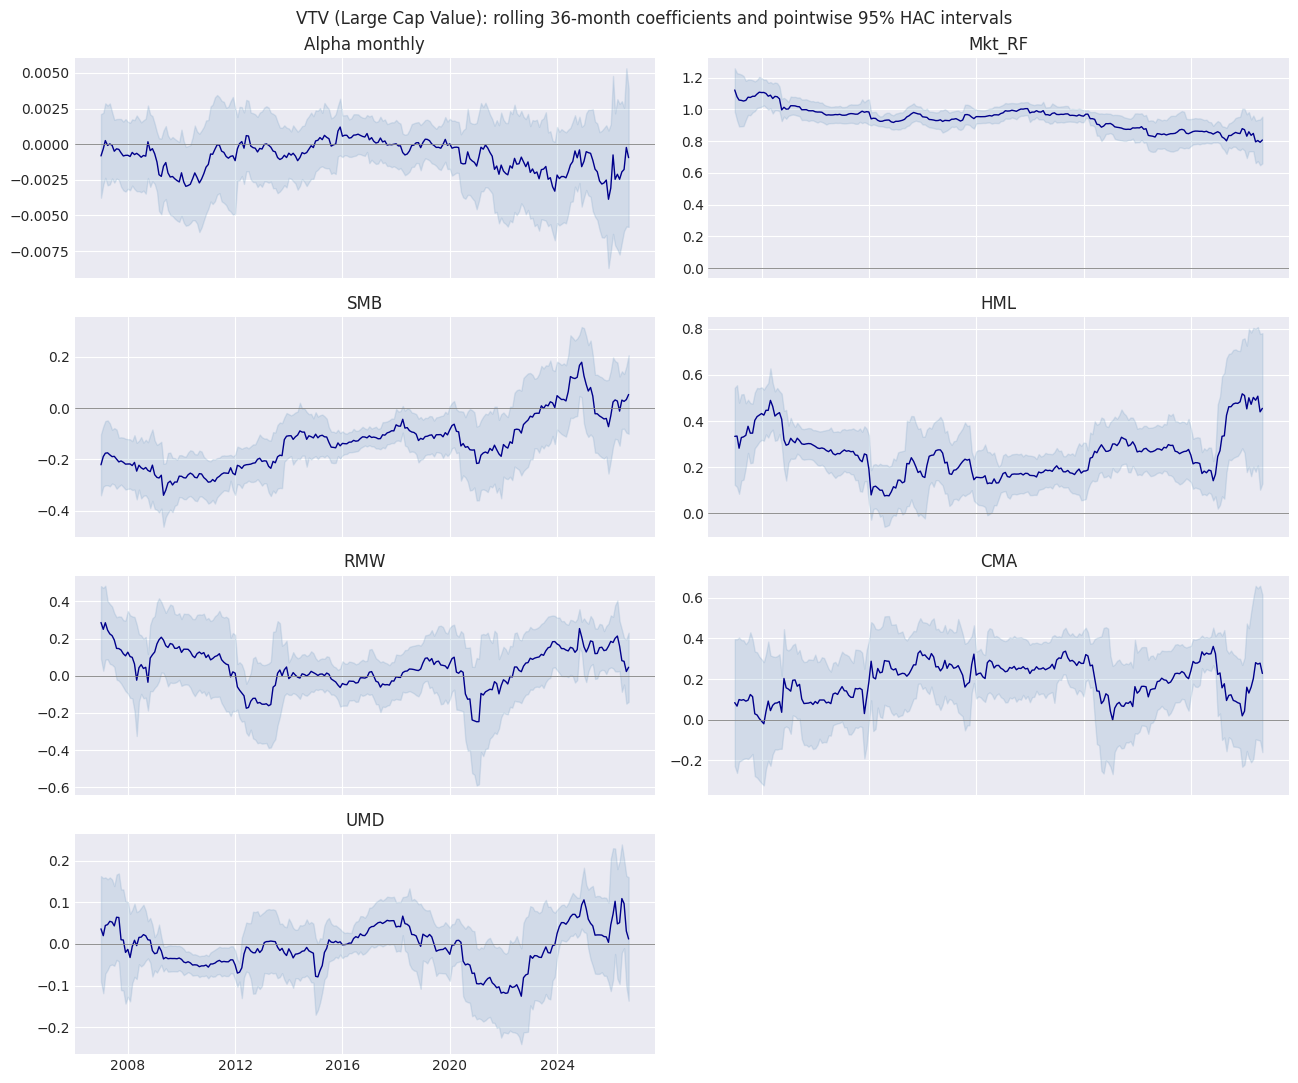
Overlapping windows are dependent; these exploratory intervals are not simultaneous bands or a structural-break test.
Apparent beta shifts combine estimation noise and possible exposure changes. Passive funds can have nonzero model-relative alpha.
Section 9: From an empirical factor to an investable fund
The models now have economic content as well as statistical machinery. Valuation relates price to expected cash flows; profitability and investment help interpret those cash flows. Momentum supplies a different empirical pattern. The evidence must then survive alternative samples, definitions and implementation costs.
An academic long–short portfolio is useful for identifying a return dimension. A diversified long-only ETF must instead choose which stocks to overweight, by how much, and when to trade. Its manager may use related company characteristics without reproducing the exact research factor definitions. This is why an ETF’s objective and its regression coefficients must be studied together.
Chapter 5 follows that translation for Avantis UCITS funds and a momentum ETF: first the economic rationale and mandates, then testable exposure questions, then the return evidence. The exercises below offer further practice with model comparison and robustness.
Primary sources are linked beside the concepts they support. For a focused reading sequence, revisit the FF5 valuation discussion, Novy-Marx profitability evidence, the momentum-crash study, and the replication/cost evidence in Section 6.
Exercises
Test your understanding of the advanced topics covered in this notebook. These exercises extend the hands-on skills from the 3-Factor Tutorial exercises — if any of the regression mechanics feel unfamiliar, revisit the earlier notebook first.
Exercise 1: 5-Factor Model on a New ETF (Hands-On)
Download return data for IWM (iShares Russell 2000 ETF — small-cap blend, no explicit value tilt) and run the full 5-factor regression.
How does IWM’s SMB loading compare to IWN’s? Is this what you expected?
Does IWM have a significant HML loading? Why or why not?
What happens to IWM’s alpha when you move from 3 factors to 5 factors?
# Starter code:
iwm_returns = monthly_returns(load_prices('IWM'))
# ... compute monthly excess returns, then:
# res3 = run_ff_regression(None, ['Mkt_RF', 'SMB', 'HML'], iwm_df)
# res5 = run_ff_regression(None, ['Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA'], iwm_df)
Exercise 2: Rolling Sharpe Ratios for Combined Strategies (Hands-On)
Using equal-weight combinations of HML, RMW and UMD from Sections 2–3:
Compute the rolling 36-month Sharpe ratio for (a) HML alone, (b) Value + Profitability, and (c) Value + Profitability + Momentum.
Plot all three on the same chart. During which periods does the combined strategy most clearly outperform single factors?
Is there any period where all three strategies have a negative rolling Sharpe ratio simultaneously?
# Starter code:
# rolling_sharpe = ret_series.rolling(36).mean() / ret_series.rolling(36).std() * np.sqrt(12)
Exercise 3: Momentum Crash Anatomy (Discussion + Hands-On)
Identify the worst 3-month period for the momentum factor (UMD) in our sample. What calendar months were they?
What was the market (Mkt-RF) doing during those months? Was this consistent with the Daniel & Moskowitz (2016) narrative of momentum crashing during market recoveries?
If you had held an equal-weight combination of UMD and HML, how would the compounded three-month loss differ? Also compare peak-to-trough drawdowns; these are different quantities.
# Starter code:
# rolling_3m_mom = (1 + factors['UMD']).rolling(3).apply(np.prod, raw=True) - 1
# worst_end = rolling_3m_mom.idxmin()
# print(f"Worst 3-month period ending: {worst_end}")
Exercise 4: The Beta Anomaly — Subsample Robustness (Discussion + Hands-On)
The beta anomaly (flat or negative SML) was documented in data going back to the 1930s. But does it hold in every subperiod? This connects to the stationarity discussion in the Time Series Foundations notebook — if the anomaly is non-stationary, our full-sample estimates may be misleading.
Split the beta-sorted decile portfolios into two halves: 2000–2011 and 2012–latest available. Plot the empirical SML for each subperiod. Is the anomaly consistent, or does it appear mainly in one era?
Regress the unscaled low-minus-high beta proxy (D1 − D10) on FF5 + Momentum separately for each subperiod. Does the alpha change sign or significance?
Discussion: Frazzini and Pedersen argue leverage constraints drive the BAB premium. Did anything change about leverage availability (e.g., the rise of leveraged ETFs, zero-commission brokers) between the two subperiods that might affect the premium?
# Starter code:
# beta_first = beta_ports.loc['2000':'2011']
# beta_second = beta_ports.loc['2012':]
# For each half, recompute avg excess returns and realized betas, then plot.- Fama, E. F., & French, K. R. (2015). A five-factor asset pricing model. Journal of Financial Economics, 116(1), 1–22. 10.1016/j.jfineco.2014.10.010
- Chen, A. Y., & Velikov, M. (2023). Zeroing in on the Expected Returns of Anomalies. Journal of Financial and Quantitative Analysis, 58(3), 968–1004. 10.1017/S0022109022000874