Question: How do valuation and profitability research become an actual fund, and what can we learn by measuring that fund’s returns?
Chapters 3–4 used factor portfolios as research tools. Here we follow the next steps: translate an economic idea into stock selection and weights, identify what different funds are trying to do, form testable exposure questions, and examine live return evidence.
The case study uses three Avantis UCITS funds—AVWS, AVWC and AVEM—and IWMO, a momentum ETF traded on Xetra as IS3R.DE. They illustrate different universes and portfolio-construction choices. This is a comparison of mechanisms and evidence, not a ranking of providers.
By the end you should be able to explain why price and profitability are evaluated together, distinguish a fund’s mandate from its regression coefficients, derive how portfolio exposures combine, and recognise when historical optimisation outruns the available evidence.
Previous: Profitability, investment and evidence · Reference: Data and methods
Source
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
import statsmodels.api as sm
from scipy.optimize import minimize_scalar
from statsmodels.stats.diagnostic import acorr_ljungbox
from IPython.display import display
from analysis_utils import (AS_OF, load_french, load_prices, monthly_returns,
                            usd_prices, fit_hac, nw_lags, coverage)
plt.style.use('seaborn-v0_8-whitegrid')
plt.rcParams["font.family"] = "DejaVu Sans"
pd.set_option('display.max_columns', 12)
print(f'Analysis cutoff: {AS_OF:%Y-%m-%d}; returns in decimals unless labelled %.')
Analysis cutoff: 2026-10-31; returns in decimals unless labelled %.
1. Why value and profitability belong together
The valuation argument in Chapter 4 compares the price paid today with expected future distributions. Holding expected cash flows fixed, a lower price implies a higher discount rate. Holding price fixed, stronger expected distributable cash flows imply a higher discount rate. Profitability and reinvestment help interpret those cash flows; a low price alone can also reflect a weak business.
A simple accounting identity makes the joint perspective concrete:
where is market equity, is book equity and is a chosen profit measure. These are deliberately simplified hypothetical companies:
| Company | Price/book | Profit/book | Profit/price |
|---|---|---|---|
| A: low valuation, weak profits | 1.0 | 4% | 4% |
| B: low valuation, stronger profits | 1.0 | 12% | 12% |
| C: higher valuation, stronger profits | 2.0 | 12% | 6% |
A price/book-only comparison treats A and B alike; a profitability-only comparison treats B and C alike. Reading the two measures together distinguishes both pairs. These ratios are not expected stock returns: future profits, growth, reinvestment, financing, accounting quality and risk still matter. The example explains an economic consideration, not Avantis’s proprietary scoring rule.
This is the intellectual connection from Fama–French’s value evidence through profitability research to systematic fund construction. Avantis describes an approach using market prices and company financial information, with trading decisions weighing prospective benefits against costs and risks. Its implementation is a manager’s interpretation of that research, not the published FF5 equation converted directly into fund weights. Avantis: How We Invest.
2. From a research factor to a long-only portfolio
HML compares a long value basket with a short growth basket. A long-only fund can instead hold both but overweight the first relative to a benchmark. In a two-basket illustration, let be the benchmark’s value weight and the fund’s extra value weight:
Subtracting gives
An active weight of 10 percentage points therefore gives only one-tenth of this particular value–growth spread, before implementation differences. The fund also retains broad equity risk. This is why holding a factor-oriented ETF is not equivalent to investing all your capital in an academic long–short factor. The real French HML construction controls for size through intersecting portfolios, so the two-basket example is an illustration rather than an exact replication.
Several decisions lie between the research and the realised result:
| Decision | Why it matters |
|---|---|
| Universe | Developed markets, emerging markets and a small-cap subset offer different stocks and risks. |
| Joint stock selection | A valuation/profitability rule can select different companies from separate value and profitability sleeves. |
| Weighting and constraints | Size, liquidity, diversification and concentration limits affect the strength of the tilt. |
| Trading | A desirable target can still be expensive to reach; turnover and bid–ask spreads affect implementation. |
| Measurement | Accounting characteristics and regression loadings measure different objects. |
An ETF is the exchange-traded vehicle. Whether its strategy tracks an index or makes active systematic decisions is a separate question. Two ETFs can share a factor label while holding different portfolios and producing different exposures.
3. The funds and the questions they let us ask
The three Avantis funds apply related valuation/profitability ideas to different universes. The official product descriptions identify the intended strategies; the questions in the final column are our empirical hypotheses, not promises from the issuer.
| Fund in this notebook | Intended universe and emphasis | Question for the return data |
|---|---|---|
| AVWS | Developed-market small-cap equities, with value and profitability considerations | Do we observe size and value exposure, and how precisely can it be estimated? |
| AVWC | Developed-market equities across capitalisations, with valuation and profitability tilts | How does a broad portfolio’s exposure differ from the more targeted AVWS portfolio? |
| AVEM | Emerging-market equities across capitalisations, with valuation and profitability tilts | What do exposures look like against an emerging-market factor benchmark? |
| IWMO | A developed-market equity momentum index strategy | Does its return history show momentum exposure, and does adding it change the portfolio’s risks? |
Sources: Avantis’s global small-cap value, global equity and emerging markets factsheets (September 2026); MSCI World Momentum Index and linked ETF.
Here AVEM means the Xetra-listed UCITS product AVEM.DE, not the separate US-listed fund sharing that short ticker. AVWC’s name includes “Global,” but its stated universe is developed markets. The ETF’s listing currency is not its underlying investment universe.
What would count as evidence?
First compare estimated loadings with the hypotheses, including their intervals. Then ask whether the answer changes with the benchmark, sample or covariance method. Finally distinguish exposure evidence from return-premium evidence: a positive value loading establishes neither positive future HML returns nor a manager’s skill.
A profitability-aware process need not yield a positive FF5 RMW coefficient. That coefficient measures conditional covariance with one particular long–short return series, after controlling for the other factors. Different accounting definitions, joint selection, constraints, correlated regressors and sampling noise can break a simple one-to-one mapping. A negative estimate calls for investigation; it does not by itself prove that the fund ignores profitability. Holdings and portfolio-characteristic data would address the process more directly than return regressions alone.
4. Construct comparable returns
French developed-market and emerging-market factors are USD returns. AVWS, AVWC and IWMO are matched to developed-market FF5 plus momentum; AVEM uses emerging-market FF5. A global fund can hold securities outside its comparison region, so region matching remains an approximation. The EM specification deliberately omits momentum; its absence is not a measured zero exposure.
Yahoo adjusted closes approximate distribution-reinvested market-price returns. Fund expenses are embedded in observed fund performance; investor commissions, spreads, tax and portfolio rebalancing costs are not deducted. EUR/USD daily closes are not synchronised with Xetra closes, which adds measurement noise. FX may be carried forward for at most four calendar days. Vendor history starts can differ from fund inception dates.
The loading cell reports coverage. The regression window can end before the price history because factor releases lag exchange prices. Complete month-end returns make the economic comparison meaningful: we must explain the same interval on both sides of the equation.
Source
dm = load_french('Developed_5_Factors_CSV.zip').rename(columns={'Mkt-RF': 'Mkt_RF'})
dm_mom = load_french('Developed_Mom_Factor_CSV.zip')
dm_mom.columns = ['UMD']
dm = dm.join(dm_mom, how='inner')
em = load_french('Emerging_5_Factors_CSV.zip').rename(columns={'Mkt-RF': 'Mkt_RF'})
ff5_cols = ['Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA']
dm_cols = ff5_cols + ['UMD']
coverage('Developed FF5 + momentum', dm)
coverage('Emerging FF5', em)
tickers = {'AVWS': 'AVWS.DE', 'AVWC': 'AVWC.DE', 'AVEM': 'AVEM.DE', 'IWMO': 'IS3R.DE'}
fx = load_prices('EURUSD=X', start='2014-09-01')
prices_eur = {name: load_prices(ticker, start='2014-09-01') for name, ticker in tickers.items()}
prices_usd = {name: usd_prices(p, fx).rename(name) for name, p in prices_eur.items()}
returns = {name: monthly_returns(p) for name, p in prices_usd.items()}
for name, p in prices_usd.items():
    coverage(name + ' USD prices', p)
    coverage(name + ' complete monthly returns', returns[name])
Developed FF5 + momentum: 431 observations, 1990-11-01 to 2026-09-01; as of 2026-10-31
Emerging FF5: 447 observations, 1989-07-01 to 2026-09-01; as of 2026-10-31
AVWS USD prices: 517 observations, 2024-10-14 to 2026-10-30; as of 2026-10-31
AVWS complete monthly returns: 24 observations, 2024-11-01 to 2026-10-01; as of 2026-10-31
AVWC USD prices: 517 observations, 2024-10-14 to 2026-10-30; as of 2026-10-31
AVWC complete monthly returns: 24 observations, 2024-11-01 to 2026-10-01; as of 2026-10-31
AVEM USD prices: 407 observations, 2025-03-24 to 2026-10-30; as of 2026-10-31
AVEM complete monthly returns: 19 observations, 2025-04-01 to 2026-10-01; as of 2026-10-31
IWMO USD prices: 3,064 observations, 2014-10-06 to 2026-10-30; as of 2026-10-31
IWMO complete monthly returns: 144 observations, 2014-11-01 to 2026-10-01; as of 2026-10-31
4.1 Inspect the prices before interpreting the model
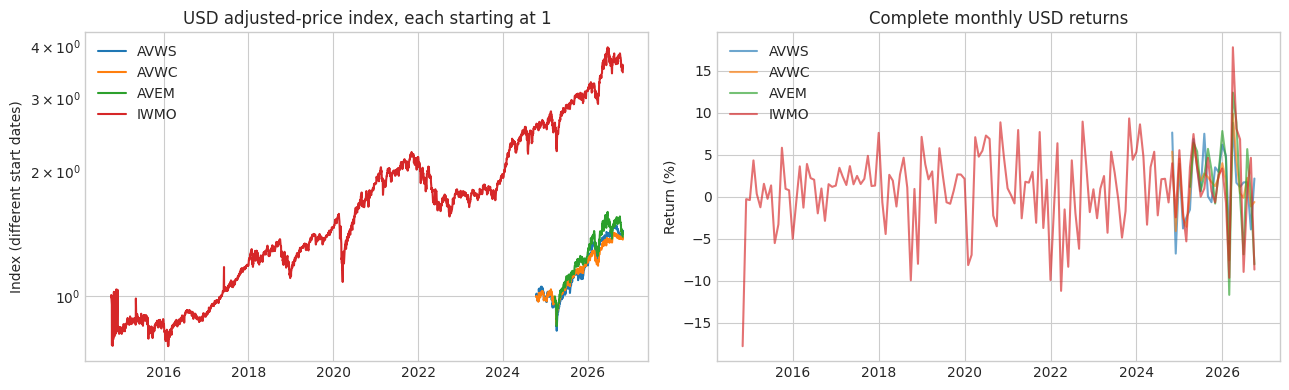
Large daily moves are flagged for inspection and retained. Deleting all moves above a threshold (or the following day) can remove genuine crashes and bias both volatility and factor loadings. Unverified vendor errors remain a limitation. For the older momentum series, we also show a fixed post-2018 sensitivity window; this is not a claim that all earlier observations are wrong.
The plots use raw available USD price histories, without dropping sessions to match a factor calendar. Regressions and portfolio statistics below use monthly returns throughout.
Source
flags = []
for name, p in prices_usd.items():
    daily = p.pct_change(fill_method=None).dropna()
    for date, value in daily[daily.abs() > .10].items():
        flags.append({'Fund': name, 'Date': date, 'Daily return %': value * 100})
print(f'{len(flags)} daily moves above 10% in absolute value; none automatically removed.')
if flags:
    display(pd.DataFrame(flags))
fig, axes = plt.subplots(1, 2, figsize=(13, 4))
for name, p in prices_usd.items():
    axes[0].plot(p.index, p / p.iloc[0], label=name)
    axes[1].plot(returns[name].index, returns[name] * 100, label=name, alpha=.65)
axes[0].set(title='USD adjusted-price index, each starting at 1', ylabel='Index (different start dates)')
axes[0].set_yscale('log')
axes[1].set(title='Complete monthly USD returns', ylabel='Return (%)')
for ax in axes: ax.legend()
plt.tight_layout()
plt.show()
15 daily moves above 10% in absolute value; none automatically removed.
5. Estimate exposures and their uncertainty
For each fund, regress monthly USD return minus regional RF on the corresponding factors. Alpha is reported as 12 × monthly intercept, an arithmetic annualisation, not a realised CAGR. The primary intervals use Bartlett Newey–West covariance, the sample-size lag heuristic, an correction, and normal critical values. These are asymptotic intervals; a short sample with six factors can make them poorly calibrated.
The tables print observations, residual degrees of freedom and lag length. We show lag and HC3 sensitivity rather than interpreting a large or a single p-value as validation. Dropping CMA is a specification sensitivity, not a conclusion that investment is irrelevant.
The specification is
with UMD omitted for AVEM’s five-factor specification. Read the output in this order: sample length → loadings and intervals → alpha and its uncertainty → sensitivity. This keeps a high R² from becoming a substitute for economic interpretation.
Source
regional_results, regional_data, regional_columns = {}, {}, {}
summary, coefficient_rows, sensitivity_rows = [], [], []
for name, r in returns.items():
    region, cols = (em, ff5_cols) if name == 'AVEM' else (dm, dm_cols)
    d = region.join(r, how='inner').dropna()
    y = d[name] - d['RF']
    res = fit_hac(y, d[cols])
    regional_results[name], regional_data[name], regional_columns[name] = res, d, cols
    summary.append({'Fund': name, 'First month': str(d.index[0].date()), 'Last month': str(d.index[-1].date()),
                    'Months': len(d), 'Residual df': int(res.df_resid), 'HAC lag': nw_lags(len(d)),
                    'Alpha %/yr': 1200 * res.params[0], 'Alpha p': res.pvalues[0], 'R²': res.rsquared})
    for j, label in enumerate(['Alpha monthly'] + cols):
        low, high = res.conf_int()[j]
        coefficient_rows.append({'Fund': name, 'Term': label, 'Estimate': res.params[j],
                                 '95% low': low, '95% high': high, 'p': res.pvalues[j]})
    for lag in sorted({0, 1, nw_lags(len(d)), min(6, len(d)-1)}):
        alt = fit_hac(y, d[cols], lags=lag)
        sensitivity_rows.append({'Fund': name, 'Covariance': f'HAC({lag})', 'Alpha SE %/yr': 1200*alt.bse[0], 'Alpha p': alt.pvalues[0]})
    hc3 = sm.OLS(y.to_numpy(), sm.add_constant(d[cols].to_numpy())).fit(cov_type='HC3', use_t=True)
    sensitivity_rows.append({'Fund': name, 'Covariance': 'HC3 + approximate t', 'Alpha SE %/yr': 1200*hc3.bse[0], 'Alpha p': hc3.pvalues[0]})
regional_summary = pd.DataFrame(summary).set_index('Fund')
coefficients = pd.DataFrame(coefficient_rows)
display(regional_summary.round(4))

print('Displayed p=0.0000 means rounded below 0.00005, not an exact zero probability.')Displayed p=0.0000 means rounded below 0.00005, not an exact zero probability.
5.1 Read the estimates against the hypotheses
The next table focuses on the proposed size, value and momentum exposures. An interval wholly above zero supports positive conditional exposure in this sample under the stated inference assumptions. An interval crossing zero leaves the sign less precisely determined. Neither outcome establishes a future premium.
Notice the different histories: the newer Avantis funds have far fewer observations than IWMO. More observations improve the opportunity to learn, but also cover different market regimes. Compare mandates first, and avoid interpreting unequal-history alpha estimates as a league table.
Source
questions = [('AVWS', 'SMB'), ('AVWS', 'HML'), ('AVWC', 'HML'), ('AVEM', 'HML'), ('AVEM', 'RMW'), ('IWMO', 'UMD')]
focus_rows = []
for fund, term in questions:
    row = coefficients[(coefficients.Fund == fund) & (coefficients.Term == term)].iloc[0]
    low, high = row['95% low'], row['95% high']
    evidence = 'Above zero' if low > 0 else ('Below zero' if high < 0 else 'Crosses zero')
    focus_rows.append({'Fund': fund, 'Factor': term, 'Months': len(regional_data[fund]),
                       'Loading': row.Estimate, '95% low': low, '95% high': high, 'Interval': evidence})
display(pd.DataFrame(focus_rows).round(3))5.2 Is the interpretation sensitive to the method?
HAC bandwidths and HC3 change uncertainty while leaving the fitted coefficients unchanged. Removing CMA changes the regression itself, so coefficients and alpha may also change. The table and graph below distinguish those two experiments.
For a short fund history, examine whether the evidence for alpha survives a different covariance approximation before drawing an economic conclusion. For IWMO, compare the full history with the post-2018 window because the early prices contain unresolved jumps. This is a sensitivity analysis, not evidence that one selected window is the truth.
Source
fig, ax = plt.subplots(figsize=(11, 5))
positions = np.arange(len(dm_cols))
for i, name in enumerate(tickers):
    rows = coefficients[(coefficients.Fund == name) & coefficients.Term.isin(dm_cols)].set_index('Term').reindex(dm_cols)
    est = rows['Estimate'].to_numpy()
    ax.errorbar(positions + (i-1.5)*.17, est,
                yerr=np.vstack([est-rows['95% low'], rows['95% high']-est]),
                fmt='o', capsize=3, label=name, alpha=.85)
ax.axhline(0, color='black', linewidth=.7)
ax.set_xticks(positions, dm_cols)
ax.set(title='Regional factor loadings with 95% HAC intervals', ylabel='Regression coefficient')
ax.legend()
plt.tight_layout()
plt.show()
print('AVEM momentum is missing by specification, not zero. Betas are not portfolio weights.')
rows = []
for name, d in regional_data.items():
    cols = regional_columns[name]
    for label, subset, selected in [('Full', d, cols), ('Without CMA', d, [x for x in cols if x != 'CMA'])]:
        res = fit_hac(subset[name]-subset.RF, subset[selected])
        rows.append({'Fund': name, 'Specification': label, 'N': len(subset), 'Alpha %/yr': 1200*res.params[0], 'Alpha p': res.pvalues[0], 'Adjusted R²': res.rsquared_adj})
    if name == 'IWMO':
        subset = d.loc['2018-01-01':]
        res = fit_hac(subset[name]-subset.RF, subset[cols])
        rows.append({'Fund': name, 'Specification': 'Full, post-2018', 'N': len(subset), 'Alpha %/yr': 1200*res.params[0], 'Alpha p': res.pvalues[0], 'Adjusted R²': res.rsquared_adj})
display(pd.DataFrame(rows).round(4))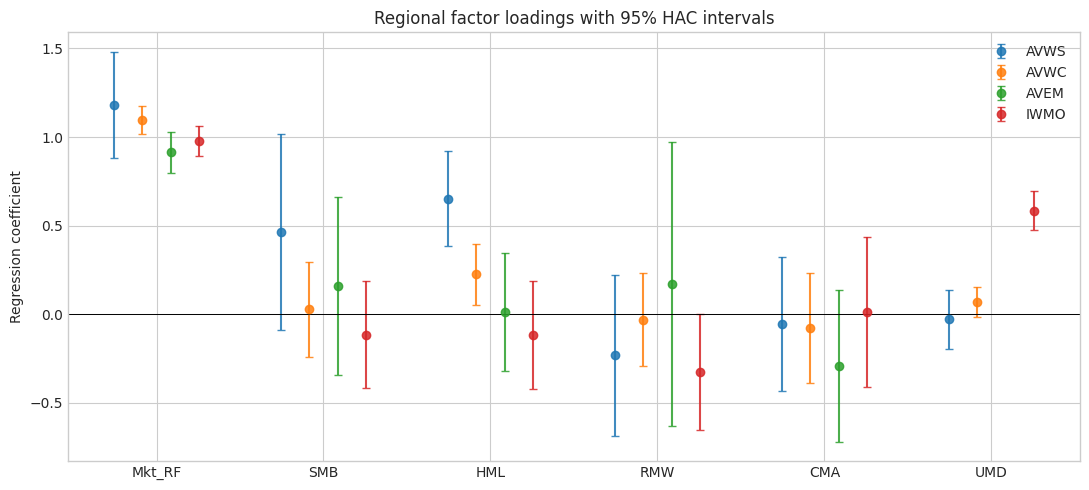
AVEM momentum is missing by specification, not zero. Betas are not portfolio weights.
Source
display(pd.DataFrame(sensitivity_rows).round(4))
print('HC3 with a t reference is a small-sample sensitivity, not an exact correction for serial dependence.')
Output
HC3 with a t reference is a small-sample sensitivity, not an exact correction for serial dependence.
6. What changes when the funds are combined?
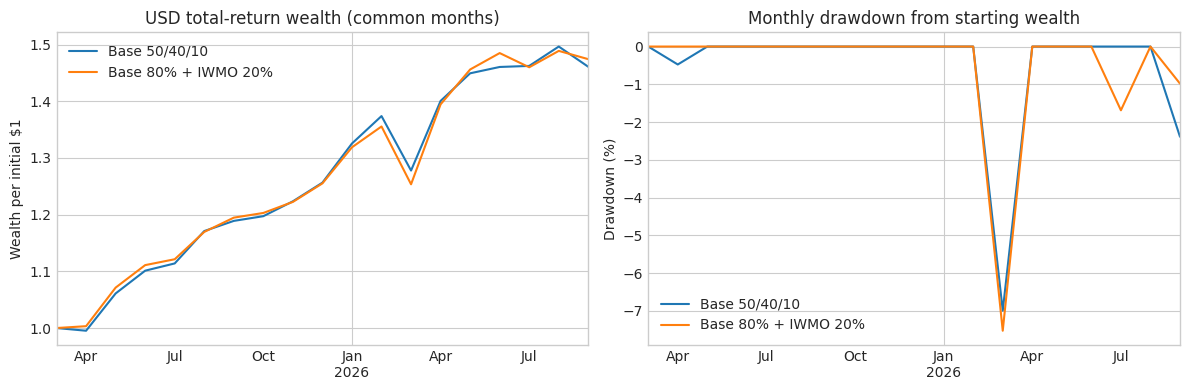
The base portfolio is 50% AVWS / 40% AVWC / 10% AVEM. We compare it with a portfolio that assigns 20% to IWMO and scales the base weights by 80%. These are fixed target weights, rebalanced monthly before each return. All comparisons use exactly the same months and the same USD risk-free series.
Realised wealth compounds total returns. Sharpe uses excess returns; its square-root-of-12 annualisation is conventional and does not correct for serial dependence. Drawdown includes starting wealth of one. Monthly observations can miss larger intramonth drawdowns. Short-sample CAGR and Sharpe are descriptive, not forecasts.
The weights are a teaching example chosen before this optimisation exercise, not a market-cap benchmark or a recommendation. Adding momentum changes both the factor mixture and the risk of deviating from the original portfolio. Whether it diversifies this sample depends on covariances as well as standalone volatility:
Owning more fund names is not enough. The holdings can overlap, and a fund with useful standalone characteristics can still raise portfolio risk at a particular weight.
Source
common = pd.concat(returns, axis=1, sort=True).join(dm, how='inner').dropna()
coverage('Common portfolio sample', common)
assert np.allclose(common.RF, em.RF.reindex(common.index))
assets = list(tickers)
asset_returns = common[assets]
base_weights = pd.Series({'AVWS': .5, 'AVWC': .4, 'AVEM': .1, 'IWMO': 0.})
weights20 = base_weights * .8
weights20['IWMO'] = .2
portfolios = pd.DataFrame({'Base 50/40/10': asset_returns @ base_weights,
                           'Base 80% + IWMO 20%': asset_returns @ weights20})

def performance(series, rf):
    wealth = (1 + series).cumprod()
    excess = series - rf
    return pd.Series({'Months': len(series), 'CAGR %': 100*(wealth.iloc[-1]**(12/len(series))-1),
                      'Volatility %/yr': 100*series.std(ddof=1)*np.sqrt(12),
                      'Excess Sharpe': excess.mean()/excess.std(ddof=1)*np.sqrt(12),
                      'Max monthly drawdown %': 100*(wealth/wealth.cummax().clip(lower=1)-1).min()})
performance_table = pd.DataFrame({name: performance(series, common.RF) for name, series in pd.concat([asset_returns, portfolios], axis=1).items()}).T
display(performance_table.round(3))
wealth = (1+portfolios).cumprod()
baseline = pd.DataFrame(1., index=[common.index[0]-pd.offsets.MonthBegin(1)], columns=wealth.columns)
wealth = pd.concat([baseline, wealth])
fig, axes = plt.subplots(1, 2, figsize=(12, 4))
wealth.plot(ax=axes[0], title='USD total-return wealth (common months)')
(100*(wealth/wealth.cummax()-1)).plot(ax=axes[1], title='Monthly drawdown from starting wealth')
axes[0].set_ylabel('Wealth per initial $1')
axes[1].set_ylabel('Drawdown (%)')
plt.tight_layout()
plt.show()
Common portfolio sample: 18 observations, 2025-04-01 to 2026-09-01; as of 2026-10-31
6.1 Why the portfolio coefficients add up
For portfolio attribution, every constituent is fitted to the same developed-market factors on the common sample. This makes weighted constituent OLS coefficients equal the portfolio coefficients; it also makes AVEM’s regional mismatch explicit. Regional coefficients from Section 5 cannot be mixed as if they described one common benchmark.
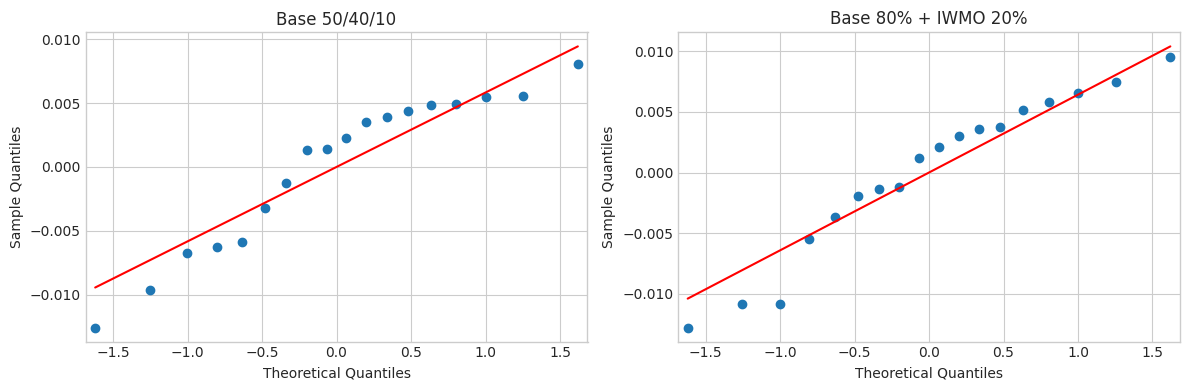
Ljung–Box p-values and QQ plots identify possible misspecification; neither passing a test nor using HAC establishes that the model is correct. Normal QQ departures do not invalidate OLS point estimates by themselves.
With fixed monthly weights summing to one, a shared sample and the same regressor matrix ,
where contains alpha and all loadings, and is the vector of excess returns. This is OLS linearity, not an additional financial assumption. The code verifies the identity. Confidence intervals do not combine by weighting individual standard errors: residual cross-covariances also matter.
Source
common_models = {name: fit_hac(common[name]-common.RF, common[dm_cols]) for name in assets}
portfolio_models = {name: fit_hac(r-common.RF, common[dm_cols]) for name, r in portfolios.items()}
for name, weights in [('Base 50/40/10', base_weights), ('Base 80% + IWMO 20%', weights20)]:
    weighted_params = sum(weights[a]*common_models[a].params for a in assets)
    np.testing.assert_allclose(weighted_params, portfolio_models[name].params, atol=1e-12)
profile = pd.DataFrame({name: res.params for name, res in portfolio_models.items()}, index=['Alpha monthly']+dm_cols)
display(profile.round(4))
fig, axes = plt.subplots(1, 2, figsize=(12, 4))
for ax, (name, res) in zip(axes, portfolio_models.items()):
    sm.qqplot(res.resid, line='s', ax=ax)
    ax.set_title(name)
    print(name, 'Residual df:', int(res.df_resid))
    display(acorr_ljungbox(res.resid, lags=[min(3, len(common)//5)], return_df=True))
    reduced = fit_hac(portfolios[name]-common.RF, common[[x for x in dm_cols if x != 'CMA']])
    print(f'Full / no-CMA annual alpha: {1200*res.params[0]:.3f}% / {1200*reduced.params[0]:.3f}%')
plt.tight_layout()
plt.show()Base 50/40/10 Residual df: 11
Full / no-CMA annual alpha: -2.926% / -3.248%
Base 80% + IWMO 20% Residual df: 11
Full / no-CMA annual alpha: -1.666% / -2.837%
7. Why estimating an allocation is harder than estimating exposures
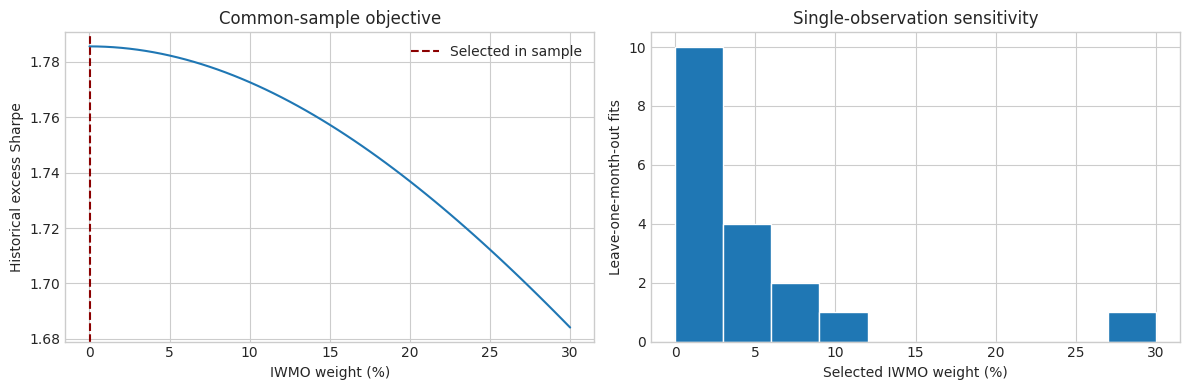
Choose an IWMO weight between 0% and 30%, scaling the base portfolio proportionally. The objective maximises historical excess-return Sharpe on the common monthly sample. We evaluate both endpoints as well as the optimiser candidate and a dense grid. Selecting and evaluating on the same history creates optimism; this is an illustration of estimation risk, not an out-of-sample strategy test.
Leave-one-month-out fits reveal how much a single observation can move the selected weight. They are sensitivity checks, not independent backtests or confidence intervals. The short shared history does not support credible performance validation.
Source
base = portfolios['Base 50/40/10']
momentum = common.IWMO

def portfolio_at(w, base=base, momentum=momentum):
    return (1-w)*base + w*momentum

def select_weight(b, m, rf):
    def objective(w):
        e = (1-w)*b + w*m - rf
        sd = e.std(ddof=1)
        if not np.isfinite(sd) or sd <= 0:
            raise ValueError('Sharpe undefined for zero/invalid volatility')
        return -np.sqrt(12)*e.mean()/sd
    result = minimize_scalar(objective, bounds=(0., .30), method='bounded')
    if not result.success:
        raise RuntimeError(result.message)
    candidates = [0., .30, float(result.x)] + list(np.linspace(0, .30, 301))
    return min(candidates, key=objective)

best_w = select_weight(base, momentum, common.RF)
grid = np.linspace(0, .30, 61)
grid_sharpe = [performance(portfolio_at(w), common.RF)['Excess Sharpe'] for w in grid]
loo = [select_weight(base.drop(date), momentum.drop(date), common.RF.drop(date)) for date in common.index]
print(f'In-sample selected IWMO weight: {best_w:.4%}; base weight: {1-best_w:.1%}')
print(f'Leave-one-month-out selected weights: {min(loo):.1%} to {max(loo):.1%}')
display(pd.DataFrame([performance(portfolio_at(w), common.RF) for w in [0., .20, best_w, .30]], index=['Baseline: 0%', 'Scenario: 20%', f'Selected: {best_w:.4%}', 'Boundary: 30%']).round(3))
fig, axes = plt.subplots(1, 2, figsize=(12, 4))
axes[0].plot(100*grid, grid_sharpe)
axes[0].axvline(100*best_w, color='darkred', linestyle='--', label='Selected in sample')
axes[0].set(xlabel='IWMO weight (%)', ylabel='Historical excess Sharpe', title='Common-sample objective')
axes[0].legend()
axes[1].hist(np.array(loo)*100, bins=np.linspace(0, 30, 11), edgecolor='white')
axes[1].set(xlabel='Selected IWMO weight (%)', ylabel='Leave-one-month-out fits', title='Single-observation sensitivity')
plt.tight_layout()
plt.show()
In-sample selected IWMO weight: 0.0163%; base weight: 100.0%
Leave-one-month-out selected weights: 0.0% to 30.0%
8. What makes these ETFs interesting—and what we have learned
The economic idea is systematic: compare the price of a business with information about the cash flows it can support, apply that reasoning across a diversified universe, and account for the costs of changing the portfolio. Avantis provides concrete examples of how related research can inform different long-only mandates. The small-cap, broad developed-market and emerging-market funds are different applications of that idea, not interchangeable packages of FF5 factors.
Our regressions add an empirical layer. They let us ask whether live return behaviour resembles the proposed tilts, how strong those exposures are, and how sensitive the answer is to the benchmark and sample. A large coefficient with a wide interval is a different finding from a modest coefficient estimated precisely. The negative or imprecise profitability coefficients also show why a process description cannot be read straight off a single RMW estimate.
The portfolio exercise then connects fund selection back to the statistics: common samples and shared benchmarks are essential for attribution, covariance determines diversification, and maximising a noisy historical Sharpe ratio can produce unstable weights. The shared fund history in this edition is only 18 months, so the allocation experiment illustrates estimation risk rather than establishing an optimal mix.
A fund’s investment rationale, its measured exposure, and the evidence for a lasting net premium therefore remain separate questions. You now have a framework for investigating each: read the mandate and implementation rules; inspect appropriate holdings or return evidence; and evaluate long-horizon, independent performance with realistic costs.
Questions to carry into your own analysis
Two funds have the same HML loading but different profitability definitions and holdings. What has the regression established, and what additional evidence would distinguish their processes?
Why might AVWS and AVWC have different size exposures even when their managers use related valuation ideas?
If a momentum allocation raises CAGR but lowers excess Sharpe in one sample, what does that say about an investor’s objective—and what does it leave unresolved?
What data would you need before treating the weight selected in Section 7 as a forward-looking decision?
The worked solutions reinforce the statistical tools from the earlier chapters. Data and methods collects the source definitions and conventions used throughout the book.