This is a reference companion to Chapters 1–4. Attempt an exercise before reading its solution; compare the reasoning as well as the numerical answer.
| Chapter | Exercises | Main skill |
|---|---|---|
| 1. Statistical foundations | 5 | Derivation, covariance estimation and simulation |
| 2. Financial time series | 4 | Dependence diagnostics and their interpretation |
| 3. The three-factor model | 5 | Estimation, uncertainty and economic interpretation |
| 4. Beyond three factors | 4 | Model comparison, diversification and subsample evidence |
Solutions use the same return conventions as the chapters. Market-dependent answers are calculated from the displayed sample, so their numerical values can change when the data are refreshed. The mathematical reasoning should continue to apply.
Source
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
from scipy import stats
import statsmodels.api as sm
from statsmodels.tsa.stattools import acf, pacf, adfuller
from statsmodels.stats.diagnostic import acorr_ljungbox, het_arch
from IPython.display import display
from analysis_utils import (AS_OF, load_french, load_prices, monthly_returns,
                            load_beta_portfolios, fit_hac, nw_lags, coverage)
plt.style.use('seaborn-v0_8-darkgrid')
plt.rcParams["font.family"] = "DejaVu Sans"
np.random.seed(42)
print(f'As of {AS_OF:%Y-%m-%d}; source returns are decimals.')
As of 2026-10-31; source returns are decimals.
Source
# One shared loader and explicit HAC inference policy across the course.
def download_ff_csv(filename):
    return load_french(filename)

def run_ff_regression(y, factor_names, data, name='Asset'):
    if y is None:
        raise ValueError('Provide the response explicitly')
    res = fit_hac(y, data[factor_names])
    print(name, 'N =', len(data), 'HAC lags =', nw_lags(len(data)))
    print(res.summary())
    return res
Source
ff3 = load_french('F-F_Research_Data_Factors_CSV.zip').rename(columns={'Mkt-RF': 'Mkt_RF'})
ff3_full = ff3.loc['2000-01-01':].copy()
ff3_short = ff3.loc['2010-01-01':].copy()
ff5 = load_french('F-F_Research_Data_5_Factors_2x3_CSV.zip', start='2000-01-01').rename(columns={'Mkt-RF': 'Mkt_RF'})
mom = load_french('F-F_Momentum_Factor_CSV.zip', start='2000-01-01')
mom.columns = ['UMD']
factors = ff5.join(mom, how='inner').join(ff3.SMB.rename('SMB_FF3'), how='inner')
coverage('FF3 full', ff3_full)
coverage('FF3 short', ff3_short)
coverage('FF5 + momentum', factors)
FF3 full: 321 observations, 2000-01-01 to 2026-09-01; as of 2026-10-31
FF3 short: 201 observations, 2010-01-01 to 2026-09-01; as of 2026-10-31
FF5 + momentum: 321 observations, 2000-01-01 to 2026-09-01; as of 2026-10-31
Part 1: Statistical Foundations (Notebook 01) — Solutions
Exercise 1: Hand Computation
Problem: Given and :
Compute mean, variance, std dev of and
Compute and
Set up the design matrix and compute via the normal equations
# ============================================================================
# NB01 Exercise 1 — Hand Computation (verified with NumPy)
# ============================================================================

x = np.array([2, 5, 3, 8, 7], dtype=float)
y = np.array([4, 7, 5, 10, 9], dtype=float)
n = len(x)

# ── Part 1: Mean, Variance, Standard Deviation ──
mean_x = x.sum() / n
mean_y = y.sum() / n

var_x = ((x - mean_x)**2).sum() / (n - 1)   # sample variance (Bessel's correction)
var_y = ((y - mean_y)**2).sum() / (n - 1)

std_x = np.sqrt(var_x)
std_y = np.sqrt(var_y)

print("PART 1: Descriptive Statistics")
print("=" * 50)
print(f"  x = {x}")
print(f"  y = {y}")
print(f"\n  mean(x) = {x.sum()}/{n} = {mean_x:.2f}")
print(f"  mean(y) = {y.sum()}/{n} = {mean_y:.2f}")
print(f"\n  var(x)  = Σ(xᵢ − x̄)² / (n−1) = {((x - mean_x)**2).sum():.2f} / {n-1} = {var_x:.4f}")
print(f"  var(y)  = {((y - mean_y)**2).sum():.2f} / {n-1} = {var_y:.4f}")
print(f"\n  std(x)  = √{var_x:.4f} = {std_x:.4f}")
print(f"  std(y)  = √{var_y:.4f} = {std_y:.4f}")

# Verify
print(f"\n  Verify with NumPy:  std(x, ddof=1) = {x.std(ddof=1):.4f}  ✓")

# ── Part 2: Covariance and Correlation ──
cov_xy = ((x - mean_x) * (y - mean_y)).sum() / (n - 1)
corr_xy = cov_xy / (std_x * std_y)

print(f"\nPART 2: Covariance and Correlation")
print("=" * 50)
print(f"  Cov(x,y) = Σ(xᵢ-x̄)(yᵢ-ȳ)/(n-1) = {((x-mean_x)*(y-mean_y)).sum():.2f}/{n-1} = {cov_xy:.4f}")
print(f"  Corr(x,y) = Cov(x,y)/(s_x · s_y) = {cov_xy:.4f}/({std_x:.4f}·{std_y:.4f}) = {corr_xy:.4f}")
print(f"\n  Verify: np.corrcoef = {np.corrcoef(x, y)[0, 1]:.4f}  ✓")

# ── Part 3: Normal Equations ──
X = np.column_stack([np.ones(n), x])   # design matrix with intercept
XtX     = X.T @ X
XtX_inv = np.linalg.inv(XtX)
Xty     = X.T @ y
beta_hat = XtX_inv @ Xty

print(f"\nPART 3: OLS via Normal Equations")
print("=" * 50)
print(f"  Design matrix X (n×2):\n{X}")
print(f"\n  X'X =\n{XtX}")
print(f"\n  (X'X)⁻¹ =\n{XtX_inv}")
print(f"\n  X'y = {Xty}")
print(f"\n  β̂ = (X'X)⁻¹ X'y = [{beta_hat[0]:.6f}, {beta_hat[1]:.6f}]")
print(f"\n  Interpretation:  ŷ = {beta_hat[0]:.4f} + {beta_hat[1]:.4f} · x")
print(f"    → intercept ≈ {beta_hat[0]:.2f}, slope ≈ {beta_hat[1]:.2f}")

# Quick sanity check: slope should be close to Cov(x,y)/Var(x)
print(f"\n  Sanity: Cov(x,y)/Var(x) = {cov_xy/var_x:.6f}  (should match slope)  ✓")
PART 1: Descriptive Statistics
==================================================
x = [2. 5. 3. 8. 7.]
y = [ 4. 7. 5. 10. 9.]
mean(x) = 25.0/5 = 5.00
mean(y) = 35.0/5 = 7.00
var(x) = Σ(xᵢ − x̄)² / (n−1) = 26.00 / 4 = 6.5000
var(y) = 26.00 / 4 = 6.5000
std(x) = √6.5000 = 2.5495
std(y) = √6.5000 = 2.5495
Verify with NumPy: std(x, ddof=1) = 2.5495 ✓
PART 2: Covariance and Correlation
==================================================
Cov(x,y) = Σ(xᵢ-x̄)(yᵢ-ȳ)/(n-1) = 26.00/4 = 6.5000
Corr(x,y) = Cov(x,y)/(s_x · s_y) = 6.5000/(2.5495·2.5495) = 1.0000
Verify: np.corrcoef = 1.0000 ✓
PART 3: OLS via Normal Equations
==================================================
Design matrix X (n×2):
[[1. 2.]
[1. 5.]
[1. 3.]
[1. 8.]
[1. 7.]]
X'X =
[[ 5. 25.]
[ 25. 151.]]
(X'X)⁻¹ =
[[ 1.16153846 -0.19230769]
[-0.19230769 0.03846154]]
X'y = [ 35. 201.]
β̂ = (X'X)⁻¹ X'y = [2.000000, 1.000000]
Interpretation: ŷ = 2.0000 + 1.0000 · x
→ intercept ≈ 2.00, slope ≈ 1.00
Sanity: Cov(x,y)/Var(x) = 1.000000 (should match slope) ✓
Exercise 2: CLT in Action — Beta(0.5, 0.5) Distribution
Problem: Repeat the CLT experiment with — a bimodal distribution. Show that sample means become normal as grows.
# ============================================================================
# NB01 Exercise 2 — CLT with Beta(0.5, 0.5)
# ============================================================================

np.random.seed(42)
n_sims = 5000
a, b = 0.5, 0.5
mu_beta  = a / (a + b)                          # = 0.5
var_beta = (a * b) / ((a + b)**2 * (a + b + 1)) # = 0.125

sample_sizes = [5, 30, 100]

fig, axes = plt.subplots(1, len(sample_sizes) + 1, figsize=(18, 4))

# Panel 0: Show the raw Beta(0.5, 0.5) density (bimodal)
x_grid = np.linspace(0.001, 0.999, 500)
axes[0].plot(x_grid, stats.beta.pdf(x_grid, a, b), 'k-', linewidth=2)
axes[0].set_title('Beta(0.5, 0.5) density\n(bimodal!)', fontweight='bold')
axes[0].set_xlabel('x')
axes[0].set_ylabel('Density')
axes[0].grid(True, alpha=0.3)

# Panels 1–3: Histograms of standardised sample means
for i, n in enumerate(sample_sizes):
    means = np.array([np.random.beta(a, b, size=n).mean() for _ in range(n_sims)])
    z = (means - mu_beta) / np.sqrt(var_beta / n)   # standardise to N(0,1) if CLT holds

    ax = axes[i + 1]
    ax.hist(z, bins=50, density=True, alpha=0.6, color='steelblue', edgecolor='white')

    # Overlay N(0,1) density
    t_grid = np.linspace(-4, 4, 200)
    ax.plot(t_grid, stats.norm.pdf(t_grid), 'r-', linewidth=2, label='N(0,1)')

    ax.set_title(f'n = {n}', fontweight='bold', fontsize=13)
    ax.set_xlabel('Standardised z')
    ax.legend(fontsize=9)
    ax.set_xlim(-4, 4)
    ax.grid(True, alpha=0.3)

fig.suptitle('CLT Demonstration: Beta(0.5, 0.5) — Sample Means Become Normal',
             fontweight='bold', fontsize=13, y=1.03)
plt.tight_layout()
plt.show()

# Symmetry is distinct from the absolute third moment in Berry–Esseen.
print("The bounded Beta distribution has finite moments and satisfies the iid CLT.")
print("Its signed third central moment is zero, but E[|X-mu|^3] is positive.")
print("Symmetry removes a skewness term in an Edgeworth expansion; it does not make the Berry–Esseen bound zero.")
print("Inspect the histograms: visual similarity at a given n is not a universal error bound.")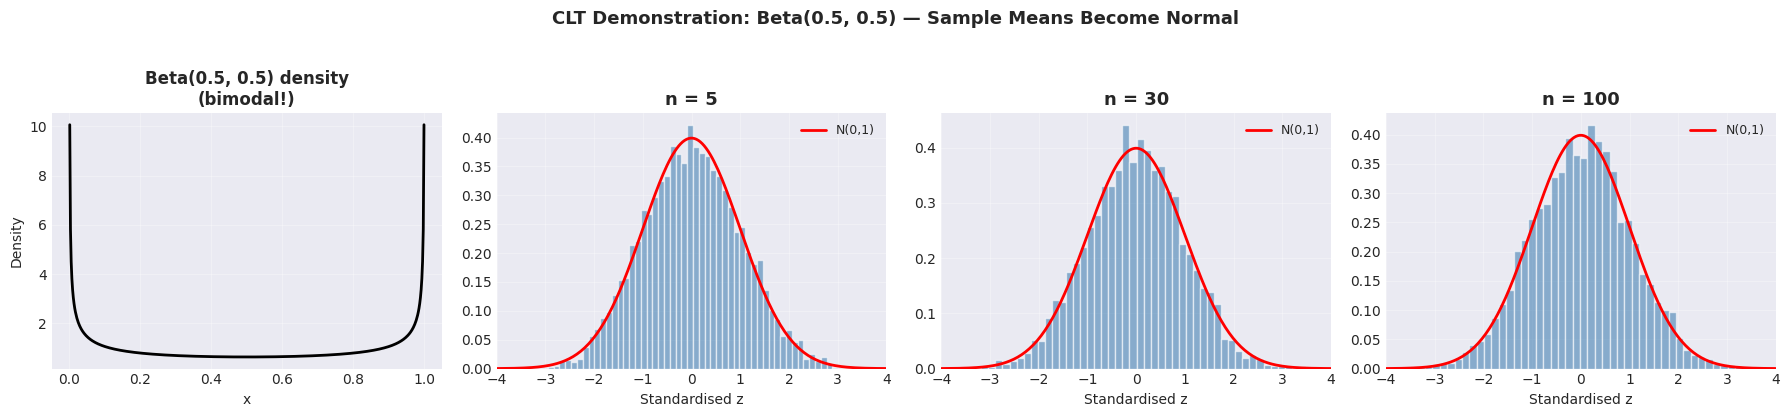
The bounded Beta distribution has finite moments and satisfies the iid CLT.
Its signed third central moment is zero, but E[|X-mu|^3] is positive.
Symmetry removes a skewness term in an Edgeworth expansion; it does not make the Berry–Esseen bound zero.
Inspect the histograms: visual similarity at a given n is not a universal error bound.
Exercise 3: Sandwich estimator comparison
Use the five observations from Notebook 01 Section 5 and multiply the final two outcomes by three. This is a deterministic perturbation, not a controlled experiment that isolates heteroscedasticity. Compare Classic, HC0 and lag-one HAC covariance mechanically.
x_orig = np.array([2., -1., 3., 0., 1.])
y_orig = np.array([3., -2., 4., 1., 0.])
y_changed = y_orig * np.array([1, 1, 1, 3, 3])
res = sm.OLS(y_changed, sm.add_constant(x_orig)).fit()
# No finite-sample correction here, to match the hand-derived HC0/HAC formula.
hc0 = res.get_robustcov_results(cov_type='HC0', use_t=False)
hac = res.get_robustcov_results(cov_type='HAC', maxlags=1, use_correction=False, use_t=False)
comparison = pd.DataFrame({'Classic': res.bse, 'HC0': hc0.bse, 'HAC(1), uncorrected': hac.bse}, index=['Intercept', 'Slope']).T
comparison['Slope SE change %'] = 100*(comparison.Slope/res.bse[1]-1)
display(comparison.round(5))
print('Largest absolute slope-SE change:', comparison['Slope SE change %'].abs().idxmax())
print('Five observations illustrate mechanics; robust asymptotic inference is unreliable here.')Largest absolute slope-SE change: HC0
Five observations illustrate mechanics; robust asymptotic inference is unreliable here.
Exercise 4: Monte Carlo — Varying the Autocorrelation (Challenge)
Problem: Run Monte Carlo simulations with and plot rejection rates for Classic OLS vs Newey-West.
# ============================================================================
# NB01 Exercise 4 — Monte Carlo: Rejection Rate vs Autocorrelation
# ============================================================================

np.random.seed(0)
num_mc = 2000
n_mc = 150
rho_values = [0.0, 0.3, 0.6, 0.9]

results_mc = []  # list of (rho, classic_rate, nw_rate)

for rho in rho_values:
    reject_classic = 0
    reject_nw = 0

    for sim in range(num_mc):
        x_mc = np.random.randn(n_mc) * 0.04

        # AR(1) errors with heteroscedasticity and fat tails
        innov = stats.t.rvs(df=5, size=n_mc + 500)
        eps = np.zeros(n_mc + 500)
        for t in range(n_mc + 500):
            eps[t] = rho * eps[t-1] + innov[t] if t > 0 else innov[t]
        eps = eps[-n_mc:] * (0.01 + 0.4 * np.abs(x_mc))

        y_mc = 0.0 + 0.0 * x_mc + eps   # true β = 0

        X_mc = sm.add_constant(x_mc)
        res_mc = sm.OLS(y_mc, X_mc).fit()
        lag_mc = int(np.floor(4 * (n_mc / 100) ** (2/9)))
        res_nw_mc = res_mc.get_robustcov_results(cov_type='HAC', maxlags=lag_mc, use_correction=True, use_t=False)

        if res_mc.pvalues[1] < 0.05:
            reject_classic += 1
        if res_nw_mc.pvalues[1] < 0.05:
            reject_nw += 1

    rate_c = reject_classic / num_mc * 100
    rate_nw = reject_nw / num_mc * 100
    results_mc.append((rho, rate_c, rate_nw))
    print(f"  ρ = {rho:.1f}:  Classic = {rate_c:.1f}%,  Newey-West = {rate_nw:.1f}%")

# ── Plot ──
rhos    = [r[0] for r in results_mc]
classic = [r[1] for r in results_mc]
nw      = [r[2] for r in results_mc]

fig, ax = plt.subplots(figsize=(8, 5))
ax.plot(rhos, classic, 'o-', color='#d9534f', linewidth=2, markersize=8, label='Classic OLS')
ax.plot(rhos, nw,      's-', color='#5cb85c', linewidth=2, markersize=8, label='Newey-West HAC')
ax.axhline(5, color='black', linestyle='--', linewidth=1.5, label='Nominal 5% level')
ax.set_xlabel('Autocorrelation coefficient ρ', fontsize=12)
ax.set_ylabel('Rejection rate (%)', fontsize=12)
ax.set_title('False Rejection Rate Under H₀ vs Autocorrelation Strength\n'
             f'({num_mc} simulations, n={n_mc}, heteroscedastic t(5) errors)',
             fontweight='bold', fontsize=12)
ax.set_xticks(rho_values)
ax.set_ylim(0, max(classic + nw + [5]) * 1.25)
ax.legend(fontsize=10)
ax.grid(True, alpha=0.3)
plt.tight_layout()
plt.show()

print('Monte Carlo standard errors, percentage points:')
for rho, classic_rate, hac_rate in results_mc:
    print(rho, [round(100*np.sqrt((r/100)*(1-r/100)/num_mc), 2) for r in [classic_rate, hac_rate]])
print('HAC is asymptotic and need not attain the nominal 5% size in this design.')
print('The slope score is x_t*epsilon_t: iid mean-zero x can weaken score dependence even when errors are persistent.')
ρ = 0.0: Classic = 17.8%, Newey-West = 6.2%
ρ = 0.3: Classic = 18.6%, Newey-West = 6.3%
ρ = 0.6: Classic = 17.8%, Newey-West = 6.9%
ρ = 0.9: Classic = 19.6%, Newey-West = 7.5%
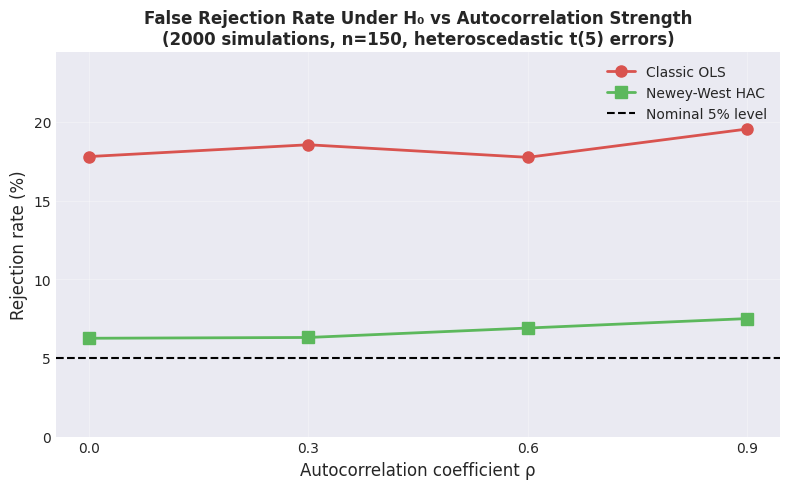
Monte Carlo standard errors, percentage points:
0.0 [np.float64(0.86), np.float64(0.54)]
0.3 [np.float64(0.87), np.float64(0.54)]
0.6 [np.float64(0.85), np.float64(0.57)]
0.9 [np.float64(0.89), np.float64(0.59)]
HAC is asymptotic and need not attain the nominal 5% size in this design.
The slope score is x_t*epsilon_t: iid mean-zero x can weaken score dependence even when errors are persistent.
Exercise 5: Why does a dependent-data CLT matter?
The iid CLT cannot be invoked just because return autocorrelations are small. Nonlinear dependence, including dependence in squared returns, can remain.
One sufficient theorem assumes strict stationarity, and for some . Regression inference applies the relevant multivariate CLT to the score , alongside exogeneity and a nonsingular regressor moment matrix. Return ACF plots do not establish these conditions.
A random-walk level has time-varying variance, so a stationary covariance sequence and its usual long-run variance formula are not applicable. Ordinary stationary HAC does not fix a spurious levels regression. Differences may have an appropriate stationary model, but this must be justified. ADF rejection alone does not prove mixing, constant moments or valid regression inference.
Part 2: Time-Series Foundations (Notebook 02) — Solutions
Exercise 1: Stationarity on a New Series (AAPL)
Problem: Download daily AAPL prices, compute log returns, run ADF tests on prices and returns, and plot rolling moments.
# ============================================================================
# NB02 Exercise 1 — Stationarity: AAPL Prices vs Log Returns
# ============================================================================

prices = load_prices('AAPL').loc['2015-01-01':]
coverage('AAPL daily prices', prices)

log_returns = np.log(prices / prices.shift(1)).dropna()

# ── Part 1: ADF tests ──
print("ADF TEST RESULTS")
print("=" * 60)

adf_price = adfuller(prices.values, maxlag=20, autolag='AIC')
print(f"\nAAPL PRICES:")
print(f"  ADF statistic:  {adf_price[0]:.4f}")
print(f"  p-value:        {adf_price[1]:.4f}")
print(f"  Conclusion:     {'Reject unit root' if adf_price[1] < 0.05 else 'Do not reject unit root'}")

adf_ret = adfuller(log_returns.values, maxlag=20, autolag='AIC')
print(f"\nAAPL LOG RETURNS:")
print(f"  ADF statistic:  {adf_ret[0]:.4f}")
print(f"  p-value:        {adf_ret[1]:.6f}")
print(f"  Conclusion:     {'Reject unit root' if adf_ret[1] < 0.05 else 'Do not reject unit root'}")

print('ADF uses a constant, AIC lag selection and a unit-root null; it does not test full stationarity.')

# ── Part 2: Rolling 60-day mean and std dev ──
fig, axes = plt.subplots(2, 2, figsize=(15, 8))

axes[0, 0].plot(prices.index, prices, color='darkblue', linewidth=0.8)
axes[0, 0].set_title('AAPL Daily Close Price', fontweight='bold')
axes[0, 0].set_ylabel('Price ($)')
axes[0, 0].grid(True, alpha=0.3)

axes[0, 1].plot(log_returns.index, log_returns * 100, color='steelblue', linewidth=0.5, alpha=0.7)
axes[0, 1].set_title('AAPL Daily Log Returns', fontweight='bold')
axes[0, 1].set_ylabel('Return (%)')
axes[0, 1].grid(True, alpha=0.3)

rolling_mean = log_returns.rolling(60).mean() * 100
axes[1, 0].plot(rolling_mean.index, rolling_mean, color='darkred', linewidth=1)
axes[1, 0].axhline(log_returns.mean() * 100, color='black', linestyle='--', alpha=0.5,
                     label=f'Full-sample mean = {log_returns.mean()*100:.3f}%')
axes[1, 0].set_title('Rolling 60-Day Mean of Log Returns', fontweight='bold')
axes[1, 0].set_ylabel('Mean return (%)')
axes[1, 0].legend(fontsize=9)
axes[1, 0].grid(True, alpha=0.3)

rolling_std = log_returns.rolling(60).std() * 100
axes[1, 1].plot(rolling_std.index, rolling_std, color='darkorange', linewidth=1)
axes[1, 1].axhline(log_returns.std() * 100, color='black', linestyle='--', alpha=0.5,
                     label=f'Full-sample std = {log_returns.std()*100:.3f}%')
axes[1, 1].set_title('Rolling 60-Day Std Dev (Volatility)', fontweight='bold')
axes[1, 1].set_ylabel('Std dev (%)')
axes[1, 1].legend(fontsize=9)
axes[1, 1].grid(True, alpha=0.3)

plt.suptitle('AAPL: Stationarity Analysis', fontweight='bold', fontsize=14, y=1.01)
plt.tight_layout()
plt.show()

print('Rolling moments are diagnostics. Changing conditional volatility is compatible with stationary GARCH, but neither the plot nor ADF proves that model.')
AAPL daily prices: 2,975 observations, 2015-01-02 to 2026-10-30; as of 2026-10-31
ADF TEST RESULTS
============================================================
AAPL PRICES:
ADF statistic: 1.1635
p-value: 0.9957
Conclusion: Do not reject unit root
AAPL LOG RETURNS:
ADF statistic: -17.6225
p-value: 0.000000
Conclusion: Reject unit root
ADF uses a constant, AIC lag selection and a unit-root null; it does not test full stationarity.
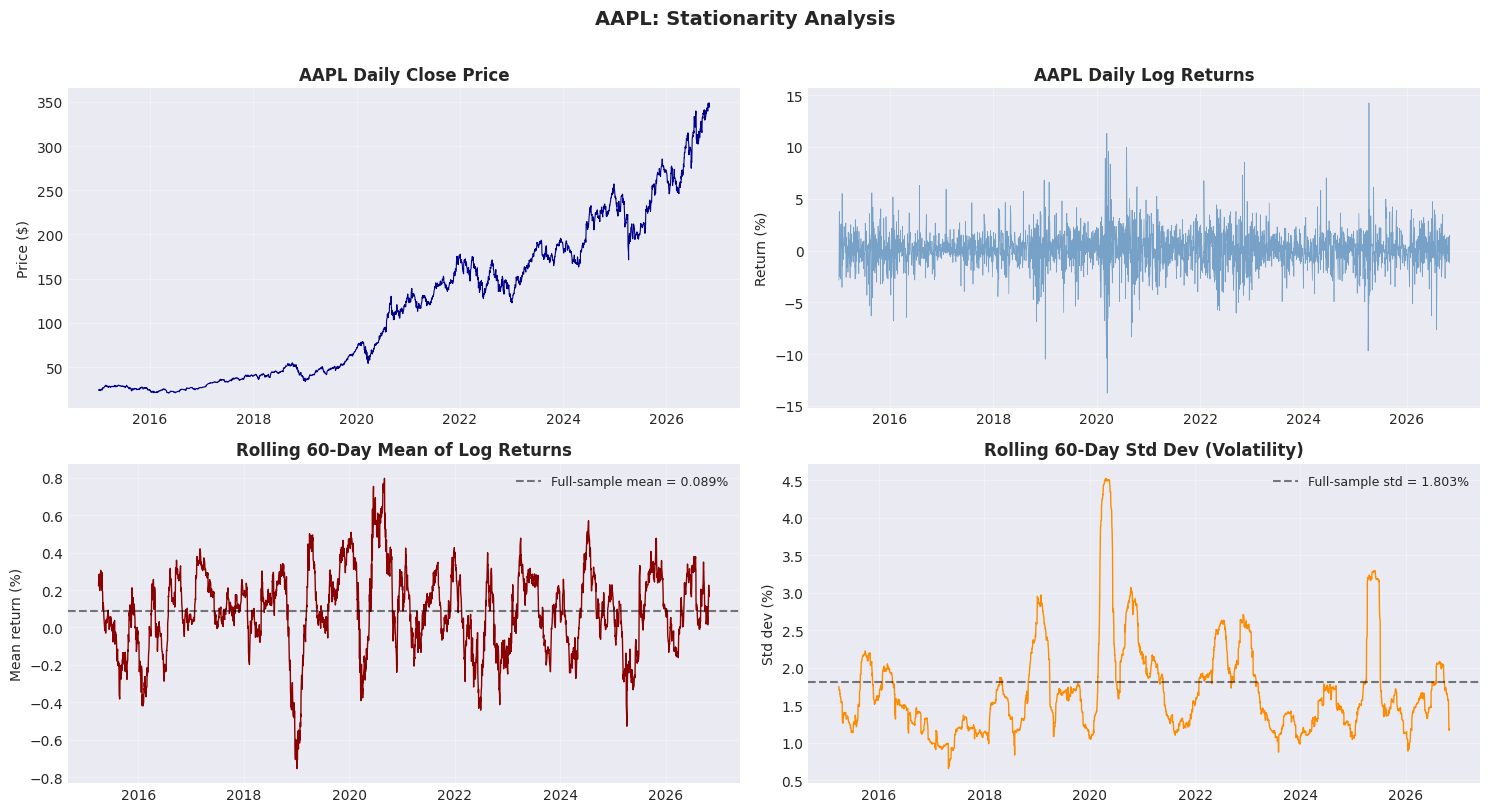
Rolling moments are diagnostics. Changing conditional volatility is compatible with stationary GARCH, but neither the plot nor ADF proves that model.
Exercise 2: Interpreting ACF plots
| Process | Population ACF of | Population ACF of |
|---|---|---|
| iid, mean-zero Gaussian noise | Zero after lag zero | Zero after lag zero |
| Stationary mean-zero Gaussian AR(1), | ||
| Stationary GARCH returns with martingale-difference innovations and finite required moments | Zero after lag zero | Can show persistent positive dependence |
White noise alone means uncorrelated observations; it does not imply independence or independent squares. The first row requires iid Gaussian noise. Sample ACFs fluctuate: about 5% of individual lags can exceed pointwise 95% bands even under the null, and those bands are not a joint test.
Volatility clustering motivates heteroscedasticity-robust inference. HAC also allows score autocorrelation, but is not logically necessary from clustering alone: a martingale-difference regression score can have zero serial covariance, making HC appropriate under other regularity conditions. Inspect residuals and scores; do not infer a regression covariance structure solely from raw-return ACFs.
Exercise 3: Sample-period sensitivity of ARCH tests
Split monthly Mkt-RF into 2000–2011 and 2012–latest. Fit a mean in each window, then apply ARCH(6) to its residuals. Compare estimates and sample lengths; do not assume the later period is calmer.
fig, axes = plt.subplots(1, 2, figsize=(13, 4))
for ax, (label, series) in zip(axes, [('2000–2011', ff3_full.Mkt_RF.loc[:'2011-12']), ('2012–latest', ff3_full.Mkt_RF.loc['2012-01':])]):
    lm, p, f, fp = het_arch((series-series.mean()).to_numpy(), nlags=6, ddof=1)
    print(f'{label}: N={len(series)}, monthly SD={series.std():.2%}, ARCH LM={lm:.3f}, p={p:.4g}')
    ax.plot(series.index, 100*series)
    ax.set(title=label, ylabel='Market excess return (%)')
plt.tight_layout()
plt.show()
print('Differences reflect both the sample and test power. Non-rejection does not establish constant conditional variance.')
2000–2011: N=144, monthly SD=4.87%, ARCH LM=18.059, p=0.006087
2012–latest: N=177, monthly SD=4.17%, ARCH LM=26.758, p=0.0001608
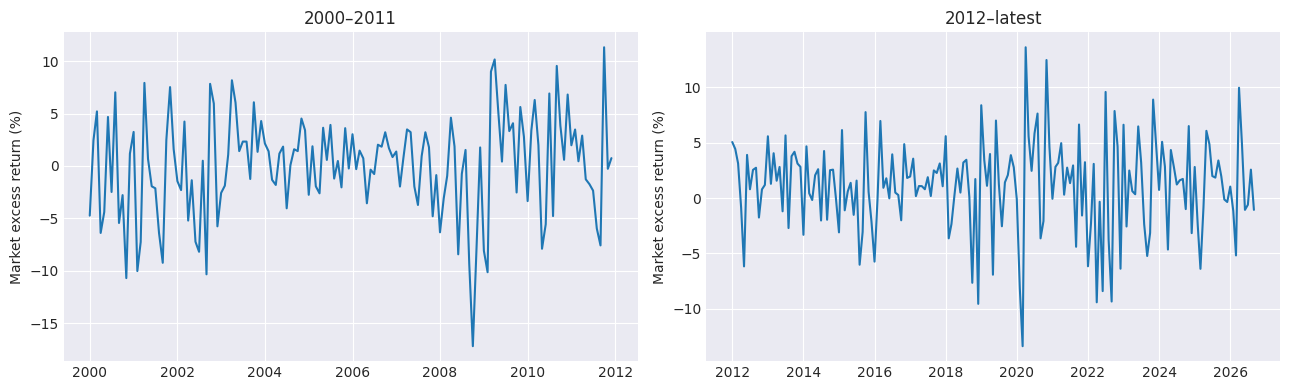
Differences reflect both the sample and test power. Non-rejection does not establish constant conditional variance.
Exercise 4: Does an apparent long-run variance plateau establish mixing?
No. For a covariance-stationary scalar process, absolute summability is sufficient for a finite long-run variance and variance-based consistency of the sample mean. A signed partial sum can appear stable because positive and negative covariances cancel, even if absolute summability has not been established.
A finite sample estimates only finitely many noisy covariances. Neither an apparent plateau of signed sums nor of absolute sums proves an infinite-series condition. Even population absolute summability does not, by itself, imply strong mixing or a CLT. A theorem must impose suitable dependence and moment conditions on the relevant regression scores. Structural breaks threaten stationarity; long-memory processes can violate covariance summability. Stationarity, covariance summability and mixing are distinct properties.
For a random-walk level, variance depends on time; there is no stationary lag-only covariance sequence to insert in this formula. Consistency for a finite long-run variance requires that such a target exist, alongside appropriate estimator conditions. A structural break violates the single stationary model, but does not logically imply failure of every mixing condition. Inspect subsamples and break-sensitive specifications, report their dates, and do not treat a post-break window as automatically stable.
Part 3 — Fama–French 3-factor model
Exercise 1: Predicting loadings
| Fund type | Qualitative expectation |
|---|---|
| QQQ | Broad equity exposure; large-cap/growth orientation suggests negative SMB and HML, subject to the sample. |
| IWM | Positive size exposure; a blend mandate does not force HML to zero. |
| Daily 2× S&P 500 ETF | Approximately twice the daily index exposure before costs, not exactly twice its monthly return or beta. |
These are hypotheses, not estimated values. Daily leverage resets, financing, path dependence and compounding affect monthly exposure. Large-cap benchmarks can have nonzero size and value coefficients.
Exercise 2 — Comparing ETFs (Hands-On)
Problem: Run the FF3 regression on IWN (Small Cap Value). Compare its and to SPY and VTV.
tickers = ['SPY', 'IWN', 'VTV']
monthly_etfs = pd.concat({tic: monthly_returns(load_prices(tic)) for tic in tickers}, axis=1)
comparison_data = ff3_short.join(monthly_etfs, how='inner').dropna()
coverage('Common ETF comparison', comparison_data)
results_dict = {tic: fit_hac(comparison_data[tic]-comparison_data.RF, comparison_data[['Mkt_RF','SMB','HML']]) for tic in tickers}
rows = []
for tic, res in results_dict.items():
    rows.append({'ETF': tic, 'Alpha %/yr': 1200*res.params[0], 'Alpha p': res.pvalues[0], 'Market beta': res.params[1], 'SMB': res.params[2], 'HML': res.params[3], 'R²': res.rsquared})
comparison_table = pd.DataFrame(rows).set_index('ETF')
display(comparison_table.round(4))
print('Highest sample R²:', comparison_table['R²'].idxmax())
print('IWN minus SPY SMB:', results_dict['IWN'].params[2]-results_dict['SPY'].params[2])
print('High R² measures within-sample fit, not superior investment performance.')
Common ETF comparison: 201 observations, 2010-01-01 to 2026-09-01; as of 2026-10-31
Highest sample R²: SPY
IWN minus SPY SMB: 0.9622475945491108
High R² measures within-sample fit, not superior investment performance.
Exercise 3 — Sensitivity of Newey-West Standard Errors
Problem: Re-fit the SPY regression with maxlags=0, default, and maxlags=8. How sensitive are conclusions to lag choice?
d = comparison_data
base = sm.OLS((d.SPY-d.RF).to_numpy(), sm.add_constant(d[['Mkt_RF','SMB','HML']].to_numpy())).fit()
rows = []
for lag in sorted({0, nw_lags(len(d)), 8, 12}):
    r = fit_hac(d.SPY-d.RF, d[['Mkt_RF','SMB','HML']], lags=lag)
    rows.append({'Lag': lag, 'Monthly alpha': r.params[0], 'Alpha SE': r.bse[0], 'Alpha p': r.pvalues[0], 'SMB SE': r.bse[2]})
display(pd.DataFrame(rows).round(6))
np.testing.assert_allclose(fit_hac(d.SPY-d.RF, d[['Mkt_RF','SMB','HML']], lags=0).cov_params(), base.get_robustcov_results(cov_type='HC1').cov_params())
print('Lag zero with n/(n-k) correction equals HC1; uncorrected lag zero equals HC0.')
print('Coefficients stay fixed. HAC standard errors need not increase monotonically with lag length.')Lag zero with n/(n-k) correction equals HC1; uncorrected lag zero equals HC0.
Coefficients stay fixed. HAC standard errors need not increase monotonically with lag length.
Exercise 4: Economic versus statistical significance
The stated monthly alpha is 0.03% with p = 0.04, so it rejects zero at a nominal 5% level under the inference method that produced that p-value. Its arithmetic annualisation is 0.36%, or 36 basis points.
Thirty-six basis points can be economically meaningful. Compare it with uncertainty, implementation costs and the relevant alternative, not an arbitrary cutoff. If alpha is estimated from observed fund returns, recurring fund expenses are already reflected; subtracting the expense ratio again double counts them. Investor spreads, trading costs and tax remain separate.
Switching from classical to HAC covariance leaves the alpha estimate unchanged but can make its standard error and p-value either larger or smaller. Without the data and covariance estimates, the direction is unknown. A p-value of 0.04 is also fragile to specification changes and multiple testing. Alpha depends on the model and period; it does not establish skill or a repeatable future return.
Exercise 5 — Extending to Another Asset (Challenge)
Problem: Download a stock of your choice, compute monthly excess returns, run the FF3 regression with Newey-West SEs, and interpret the results with diagnostics.
aapl_monthly = monthly_returns(load_prices('AAPL')).rename('AAPL')
d = ff3_short.join(aapl_monthly, how='inner').dropna()
coverage('AAPL FF3', d)
r = fit_hac(d.AAPL-d.RF, d[['Mkt_RF','SMB','HML']])
display(pd.DataFrame({'Estimate': r.params, 'SE': r.bse, 'p': r.pvalues, '95% low': r.conf_int()[:,0], '95% high': r.conf_int()[:,1]}, index=['Alpha monthly','Mkt_RF','SMB','HML']).round(5))
print(f'Annualised arithmetic alpha: {1200*r.params[0]:.2f}%; R²: {r.rsquared:.4f}')
fig, axes = plt.subplots(1, 2, figsize=(11, 4))
sm.qqplot(r.resid, line='s', ax=axes[0])
axes[1].plot(d.index, 100*r.resid)
axes[1].set(title='AAPL FF3 residuals', ylabel='Monthly residual (%)')
plt.tight_layout()
plt.show()
display(acorr_ljungbox(r.resid, lags=[6,12], return_df=True))
print('Single-stock alpha mixes model omissions and stock-specific outcomes; it does not identify skill.')
AAPL FF3: 201 observations, 2010-01-01 to 2026-09-01; as of 2026-10-31
Annualised arithmetic alpha: 10.74%; R²: 0.4082
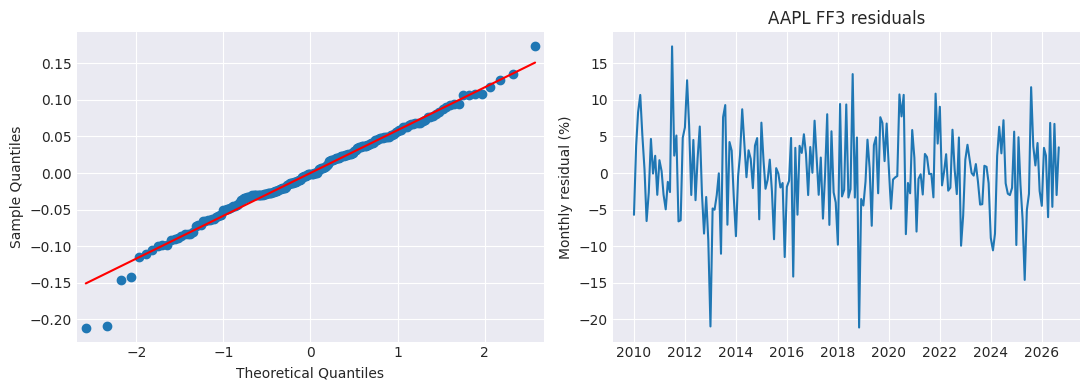
Single-stock alpha mixes model omissions and stock-specific outcomes; it does not identify skill.
Part 4 — Advanced Factor Models (Notebook 04)
Exercise 1 — 5-Factor Model on IWM
Problem: Run the full 5-factor regression on IWM (Russell 2000 small-cap blend). Compare SMB loading to IWN, check HML significance, and compare 3-factor vs 5-factor alpha.
small = pd.concat({tic: monthly_returns(load_prices(tic)) for tic in ['IWM','IWN']}, axis=1)
d = factors.join(small, how='inner').dropna()
coverage('Common small-cap comparison', d)
rows = []
for tic in ['IWM','IWN']:
    for label, cols in [('FF3', ['Mkt_RF','SMB_FF3','HML']), ('FF5', ['Mkt_RF','SMB','HML','RMW','CMA'])]:
        r = fit_hac(d[tic]-d.RF, d[cols])
        rows.append({'ETF': tic, 'Model': label, 'Alpha %/yr': 1200*r.params[0], 'Alpha p': r.pvalues[0], 'SMB': r.params[2], 'HML': r.params[3], 'HML p': r.pvalues[3], 'R²': r.rsquared})
display(pd.DataFrame(rows).round(4))
print('FF3 uses its own SMB. Published FF3 and FF5 are not exactly nested, so R² need not increase.')
print('Compare measured SMB and HML estimates; a blend mandate does not imply zero HML exposure.')
Common small-cap comparison: 314 observations, 2000-08-01 to 2026-09-01; as of 2026-10-31
FF3 uses its own SMB. Published FF3 and FF5 are not exactly nested, so R² need not increase.
Compare measured SMB and HML estimates; a blend mandate does not imply zero HML exposure.
Exercise 2 — Rolling Sharpe Ratios for Combined Strategies
Problem: Compute 36-month rolling Sharpe ratios for (a) HML alone, (b) Value + Profitability, (c) Value + Profitability + Momentum. Plot and compare.
# ============================================================================
# NB04 Exercise 2 — Rolling Sharpe Ratios
# ============================================================================

# Build strategy returns (equal-weight combinations)
strats = pd.DataFrame({
    'HML only':        factors['HML'],
    'Value + Prof':    (factors['HML'] + factors['RMW']) / 2,
    'Val + Prof + Mom':(factors['HML'] + factors['RMW'] + factors['UMD']) / 3,
})

# Rolling 36-month annualised Sharpe ratio
window = 36
rolling_sharpe = (strats.rolling(window).mean() / strats.rolling(window).std()) * np.sqrt(12)
rolling_sharpe = rolling_sharpe.dropna()

# Plot
fig, ax = plt.subplots(figsize=(14, 5.5))
colors = ['#1f77b4', '#ff7f0e', '#2ca02c']
for col, c in zip(rolling_sharpe.columns, colors):
    ax.plot(rolling_sharpe.index, rolling_sharpe[col], label=col, linewidth=1.2, color=c)

ax.axhline(0, color='black', linewidth=0.5)
ax.fill_between(rolling_sharpe.index, 0, rolling_sharpe.min(axis=1),
                where=rolling_sharpe.min(axis=1) < 0, alpha=0.1, color='red')
ax.set_title('36-Month Rolling Sharpe Ratios: Single vs Combined Factor Strategies',
             fontweight='bold', fontsize=13)
ax.set_ylabel('Annualised Sharpe Ratio')
ax.legend(loc='upper right', framealpha=0.9)
ax.grid(True, alpha=0.3)
plt.tight_layout()
plt.show()

# Analysis
print("SUMMARY STATISTICS")
print("=" * 60)
print(f"{'Strategy':>25s}  {'Mean SR':>8s}  {'Std SR':>8s}  {'% < 0':>8s}")
print("-" * 60)
for col in rolling_sharpe.columns:
    sr = rolling_sharpe[col]
    print(f"{col:>25s}  {sr.mean():8.3f}  {sr.std():8.3f}  {(sr < 0).mean()*100:7.1f}%")

# Check if all three are simultaneously negative
all_neg = (rolling_sharpe < 0).all(axis=1)
if all_neg.any():
    periods = rolling_sharpe.index[all_neg]
    print(f"\nFirst/last months with all three negative (not necessarily consecutive):")
    print(f"  {periods[0].strftime('%Y-%m')} to {periods[-1].strftime('%Y-%m')} "
          f"({all_neg.sum()} months)")
else:
    print("\nNo period where ALL three strategies are simultaneously negative.")

print('The displayed sample determines whether diversification improved Sharpe or stability.')
print('These overlapping rolling windows are dependent and are not independent performance tests.')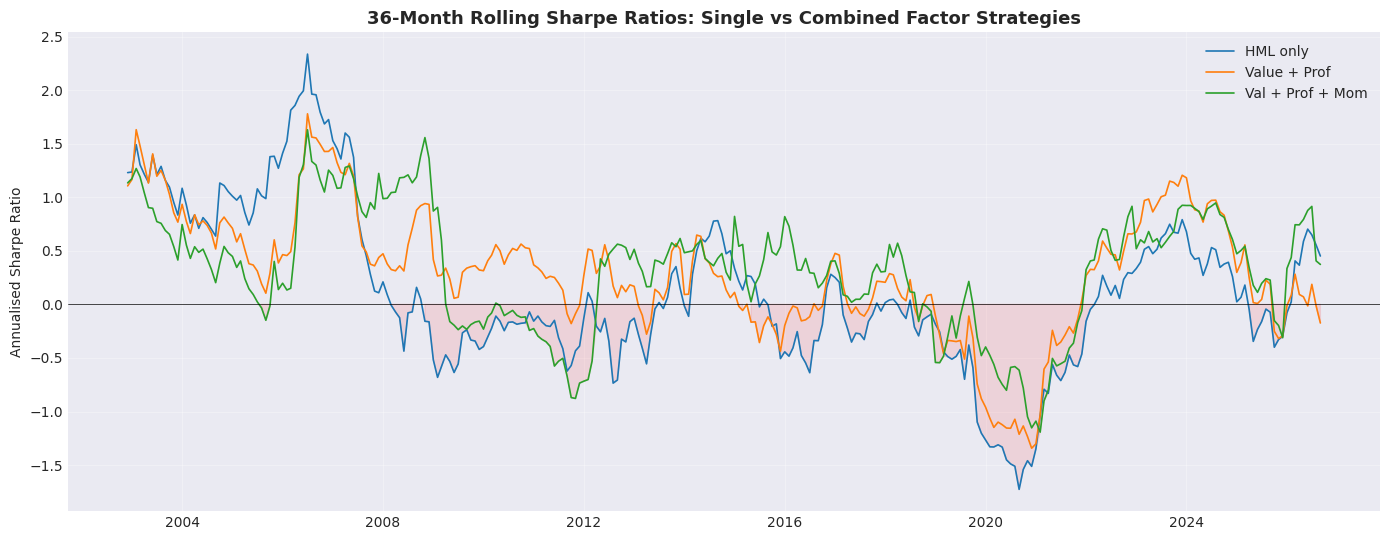
SUMMARY STATISTICS
============================================================
                 Strategy   Mean SR    Std SR     % < 0
------------------------------------------------------------
                 HML only     0.135     0.734     50.3%
             Value + Prof     0.305     0.577     26.9%
         Val + Prof + Mom     0.320     0.557     27.3%

First/last months with all three negative (not necessarily consecutive):
  2011-09 to 2025-12 (41 months)
The displayed sample determines whether diversification improved Sharpe or stability.
These overlapping rolling windows are dependent and are not independent performance tests.
Exercise 3: Momentum crash anatomy
Find the worst compounded three-month UMD return. Compare market total return and an equal-weight UMD/HML combination in those same months. Distinguish the three-month loss from peak-to-trough drawdown. Spread-factor compounding here is a hypothetical constant-notional index convention, not a traded fund return net of financing and costs.
rolling_3m = (1+factors.UMD).rolling(3).apply(np.prod, raw=True)-1
worst_end = rolling_3m.idxmin()
worst_start = worst_end-pd.DateOffset(months=2)
hedged = (factors.UMD+factors.HML)/2
crash = factors.loc[worst_start:worst_end, ['UMD','HML']].copy()
crash['Market total'] = (factors.Mkt_RF+factors.RF).reindex(crash.index)
crash['UMD + HML'] = hedged.reindex(crash.index)
print('Worst UMD window:', worst_start.date(), 'to', worst_end.date())
display((100*crash).round(2))
losses = (1+crash).prod()-1
print('Compounded three-month returns (%):')
display((100*losses).round(2))
print(f'Combination minus UMD return: {100*(losses["UMD + HML"]-losses.UMD):.2f} percentage points')
fig, axes = plt.subplots(1, 2, figsize=(13, 4))
near = pd.DataFrame({'UMD': factors.UMD, 'HML': factors.HML, 'UMD + HML': hedged, 'Market total': factors.Mkt_RF+factors.RF}).loc[worst_start-pd.DateOffset(months=6):worst_end+pd.DateOffset(months=6)]
(1+near).cumprod().plot(ax=axes[0], title='Hypothetical indices around the crash')
for name, series in [('UMD', factors.UMD), ('UMD + HML', hedged)]:
    wealth = (1+series).cumprod()
    dd = wealth/wealth.cummax().clip(lower=1)-1
    axes[1].plot(dd.index, dd*100, label=name)
    print(f'{name} full-sample max drawdown: {dd.min():.2%}')
axes[1].set(title='Drawdown over time', ylabel='Drawdown (%)')
axes[1].legend()
plt.tight_layout()
plt.show()
print('Compare the displayed market rebound with the momentum-crash mechanism; diversification is not a guaranteed hedge.')
Worst UMD window: 2009-03-01 to 2009-05-01
Compounded three-month returns (%):
UMD            -49.37
HML              9.50
Market total    26.38
UMD + HML      -23.02
dtype: float64
Combination minus UMD return: 26.35 percentage points
UMD full-sample max drawdown: -57.78%
UMD + HML full-sample max drawdown: -40.69%
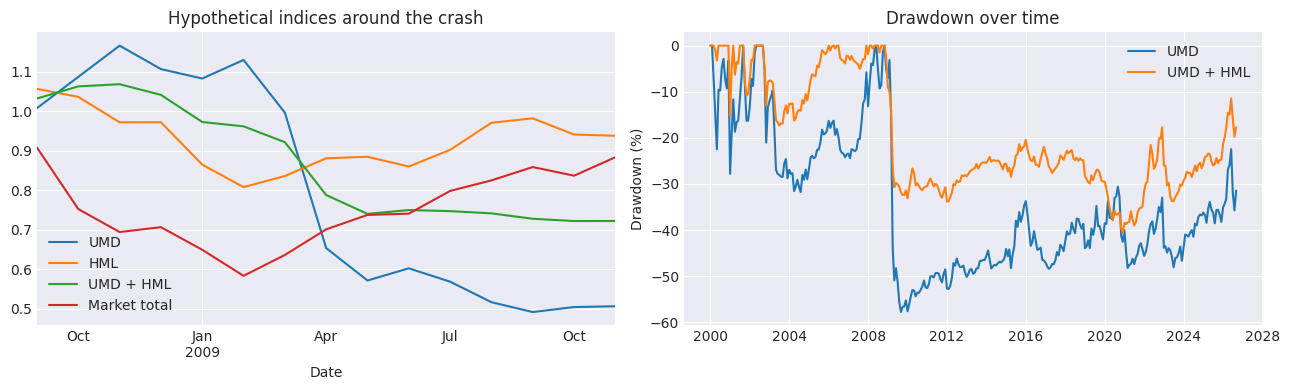
Compare the displayed market rebound with the momentum-crash mechanism; diversification is not a guaranteed hedge.
Exercise 4: Beta anomaly across subperiods
Use true value-weighted beta deciles (not the quintiles in the same file). Split 2000–2011 and 2012–latest. Compare descriptive security-market lines and control a simple D1-minus-D10 spread for FF5 plus momentum. This unscaled spread is not the published beta-neutral BAB strategy.
beta_ports = load_beta_portfolios().loc['2000-01-01':]
common_idx = beta_ports.index.intersection(factors.index)
beta_ports = beta_ports.loc[common_idx]
rf_aligned = factors.RF.reindex(common_idx)
mkt_aligned = factors.Mkt_RF.reindex(common_idx)

# ── Step 2: Split into two subperiods ──
split_date = '2011-12-31'
periods = {
    '2000–2011': (beta_ports.loc[:split_date], rf_aligned.loc[:split_date], mkt_aligned.loc[:split_date]),
    '2012–latest': (beta_ports.loc['2012-01-01':], rf_aligned.loc['2012-01-01':], mkt_aligned.loc['2012-01-01':]),
}

fig, axes = plt.subplots(1, 2, figsize=(16, 6))

for ax, (period_name, (bp, rf, mkt)) in zip(axes, periods.items()):
    avg_excess = []
    realized_betas = []
    for col in bp.columns:
        excess = bp[col] - rf
        X = sm.add_constant(mkt.values)
        res = sm.OLS(excess.values, X).fit()
        realized_betas.append(res.params[1])
        avg_excess.append(excess.mean() * 12 * 100)

    avg_excess = np.array(avg_excess)
    realized_betas = np.array(realized_betas)

    ax.scatter(realized_betas, avg_excess, s=120, c='darkblue', zorder=5,
               edgecolors='white', linewidth=1.5)
    for i, label in enumerate(bp.columns):
        ax.annotate(label, (realized_betas[i], avg_excess[i]),
                    textcoords="offset points", xytext=(8, 5), fontsize=9)

    # CAPM line
    mkt_prem = mkt.mean() * 12 * 100
    beta_range = np.linspace(0, max(realized_betas) * 1.1, 100)
    ax.plot(beta_range, beta_range * mkt_prem, 'r--', linewidth=2, label='CAPM', alpha=0.7)

    # Empirical fit
    slope, intercept = np.polyfit(realized_betas, avg_excess, 1)
    ax.plot(beta_range, slope * beta_range + intercept, 'b-', linewidth=2.5,
            label=f'Empirical (slope={slope:.1f})', alpha=0.9)

    ax.set_xlabel('Realized Beta', fontsize=11)
    ax.set_ylabel('Ann. Excess Return (%)', fontsize=11)
    ax.set_title(f'Empirical SML: {period_name}\n(CAPM slope={mkt_prem:.1f})',
                 fontweight='bold', fontsize=12)
    ax.legend(fontsize=9)
    ax.grid(True, alpha=0.3)

plt.suptitle('Beta Anomaly Subsample Robustness', fontsize=14, fontweight='bold', y=1.02)
plt.tight_layout()
plt.show()

# ── Step 3: BAB alpha in each subperiod ──
print("\n" + "=" * 60)
print("UNSCALED D1–D10 SPREAD ALPHA BY SUBPERIOD (FF5 + Momentum controls)")
print("=" * 60)

factor_cols_full = ['Mkt_RF', 'SMB', 'HML', 'RMW', 'CMA', 'UMD']

for period_name, (bp, rf, mkt) in periods.items():
    # Simple BAB = D1 excess - D10 excess
    bab = (bp['D1'] - rf) - (bp['D10'] - rf)
    ff = factors.loc[bab.index, factor_cols_full].dropna()
    bab = bab.loc[ff.index]

    X_ff = sm.add_constant(ff.values)
    res_bab = fit_hac(bab, ff, lags=6)

    alpha_ann = res_bab.params[0] * 12 * 100
    print(f"\n  {period_name} ({len(bab)} months)")
    print(f"    Alpha (ann.): {alpha_ann:+.2f}%   t = {res_bab.tvalues[0]:.2f}   "
          f"p = {res_bab.pvalues[0]:.4f}")
    sig = "SIGNIFICANT" if res_bab.pvalues[0] < 0.05 else "NOT significant"
    print(f"    Conclusion:   {sig}")

print('Compare estimated slopes with the CAPM reference; do not assume their signs.')
print('A significant spread intercept is conditional on this model and sample; this is not published BAB.')
print('Changes in access to leverage could affect demand for high-beta stocks, but this two-period comparison cannot identify that causal mechanism.')
print('A fitted cross-sectional line through ten noisy estimated betas is descriptive, without an errors-in-variables correction or pricing test.')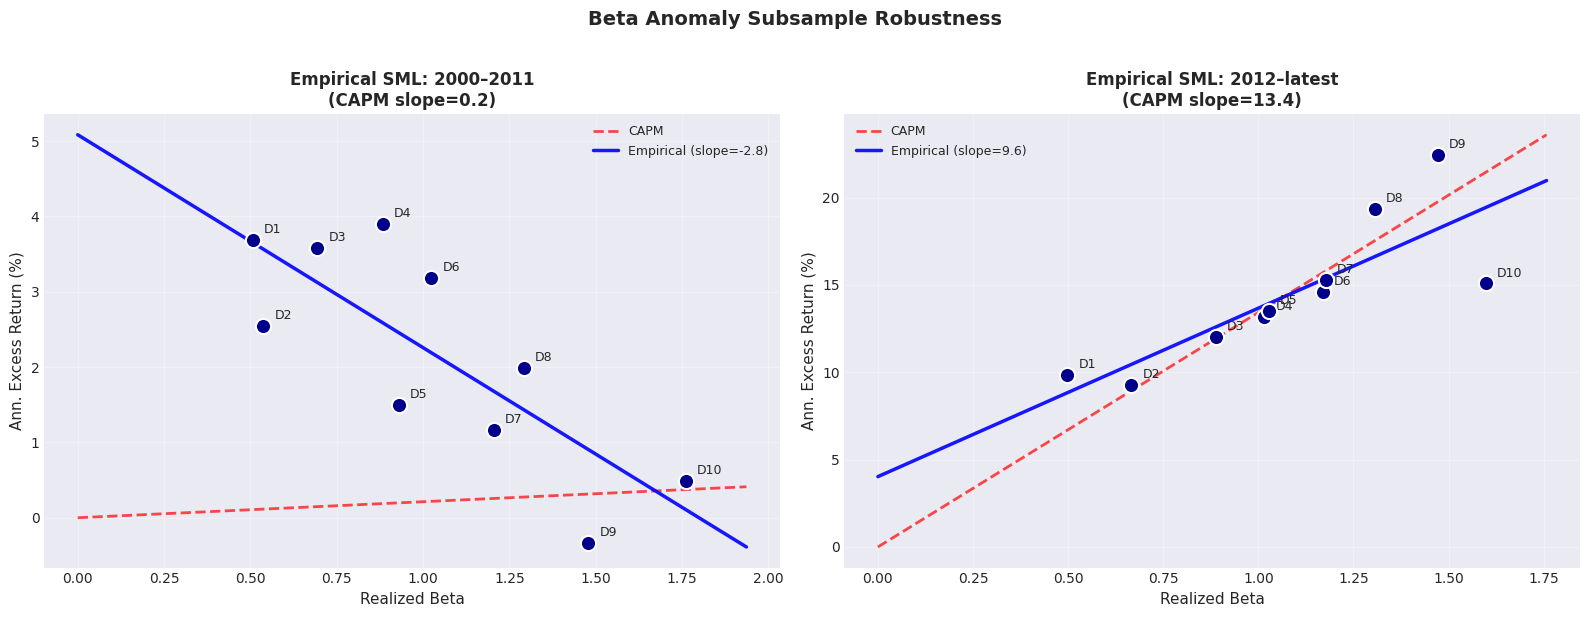
============================================================
UNSCALED D1–D10 SPREAD ALPHA BY SUBPERIOD (FF5 + Momentum controls)
============================================================

  2000–2011 (144 months)
    Alpha (ann.): -2.02%   t = -0.51   p = 0.6089
    Conclusion:   NOT significant

  2012–latest (177 months)
    Alpha (ann.): +0.09%   t = 0.02   p = 0.9869
    Conclusion:   NOT significant
Compare estimated slopes with the CAPM reference; do not assume their signs.
A significant spread intercept is conditional on this model and sample; this is not published BAB.
Changes in access to leverage could affect demand for high-beta stocks, but this two-period comparison cannot identify that causal mechanism.
A fitted cross-sectional line through ten noisy estimated betas is descriptive, without an errors-in-variables correction or pricing test.
Bringing the answers back to the investment question
The exercises establish a sequence: calculate an estimator, examine its uncertainty, check the time-series setting, and interpret factor exposures under a stated model. Historical diversification and a statistically significant result each answer a narrower question than whether a fund will outperform in the future.
Use that sequence in Chapter 5’s ETF case study. The data and methods reference explains the common conventions.