Question: If a fund’s estimated exposure or average excess return is nonzero, how much of that result could be sampling noise?
We build the tools for answering this question: descriptive statistics, sampling distributions, hypothesis tests, ordinary least squares, and covariance estimators that allow unequal variance and serial dependence. Small examples make the algebra checkable by hand; simulations show where asymptotic approximations remain imperfect.
By the end you should be able to derive , explain the difference between a coefficient and its standard error, and assemble the HC and Newey–West sandwich covariance estimators.
Background: random variables, expectation and variance, matrix multiplication and inversion. Python verifies the calculations, but the mathematical argument can be read independently.
First-pass route: follow Sections 1–3.2, then hypothesis testing and OLS in Sections 4–5, followed by robust inference in Sections 6–9. The generalised CLTs in Sections 3.3–3.6 explain how the assumptions change; revisit them when studying dependence in Chapter 2.
Source
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
from scipy import stats
import statsmodels.api as sm
import warnings


try:
    plt.style.use('seaborn-v0_8-darkgrid')
except OSError:
    plt.style.use('default')
plt.rcParams["font.family"] = "DejaVu Sans"

np.random.seed(42)
print("Libraries loaded.")
Libraries loaded.
Section 1: Descriptive Statistics — A Hand-Checkable Example
We start with a dataset small enough to compute everything on paper. Suppose we observe 5 monthly excess returns (in percent):
1.1 Sample Mean
1.2 Sample Variance (with Bessel’s correction)
The deviations from the mean are:
| 1 | 2 | 1 | 1 |
| 2 | −1 | −2 | 4 |
| 3 | 3 | 2 | 4 |
| 4 | 0 | −1 | 1 |
| 5 | 1 | 0 | 0 |
| Sum | 10 |
1.3 Why ? (Bessel’s Correction)
If we knew the true population mean , we would divide by . But we estimated from the same data (using ), which “uses up” one degree of freedom. Dividing by corrects for this, making an unbiased estimator of the population variance:
With only observations, the difference between dividing by 4 vs. 5 is 25% — far from negligible!
# ============================================================================
# Section 1: Verify hand calculations
# ============================================================================

x = np.array([2, -1, 3, 0, 1], dtype=float)
n = len(x)

mean = x.sum() / n
var = ((x - mean)**2).sum() / (n - 1)
std = np.sqrt(var)

print("Hand-checkable dataset: x =", x)
print(f"\nSample size n = {n}")
print(f"Sum = {x.sum()}")
print(f"Mean = {x.sum()}/{n} = {mean}")
print(f"\nDeviations from mean: {x - mean}")
print(f"Squared deviations:   {(x - mean)**2}")
print(f"Sum of squared devs:  {((x - mean)**2).sum()}")
print(f"\nSample variance s² = {((x - mean)**2).sum()}/{n-1} = {var}")
print(f"Sample std dev s   = √{var} = {std:.4f}")

# Verify against numpy (which uses n-1 by default in pandas, but n in numpy)
print(f"\nVerification:")
print(f"  np.mean(x) = {np.mean(x)}")
print(f"  np.var(x, ddof=1) = {np.var(x, ddof=1)}")  # ddof=1 => Bessel's
print(f"  np.std(x, ddof=1) = {np.std(x, ddof=1):.4f}")
Hand-checkable dataset: x = [ 2. -1. 3. 0. 1.]
Sample size n = 5
Sum = 5.0
Mean = 5.0/5 = 1.0
Deviations from mean: [ 1. -2. 2. -1. 0.]
Squared deviations: [1. 4. 4. 1. 0.]
Sum of squared devs: 10.0
Sample variance s² = 10.0/4 = 2.5
Sample std dev s = √2.5 = 1.5811
Verification:
np.mean(x) = 1.0
np.var(x, ddof=1) = 2.5
np.std(x, ddof=1) = 1.5811
1.4 Covariance and Correlation (Two Variables)
Now suppose we have a second variable — say, the market excess return for the same 5 months:
Sample covariance:
| Product | |||
|---|---|---|---|
| 1 | 1 | 1.8 | 1.8 |
| 2 | −2 | −3.2 | 6.4 |
| 3 | 2 | 2.8 | 5.6 |
| 4 | −1 | −0.2 | 0.2 |
| 5 | 0 | −1.2 | 0.0 |
| Sum | 14.0 |
Sample correlation:
We already know . For : the squared deviations are , so and .
This strong positive correlation () means and move together closely.
# ============================================================================
# Verify covariance and correlation
# ============================================================================

y = np.array([3, -2, 4, 1, 0], dtype=float)
y_mean = y.mean()
s_y2 = np.var(y, ddof=1)
s_y = np.std(y, ddof=1)

cov_xy = ((x - mean) * (y - y_mean)).sum() / (n - 1)
corr_xy = cov_xy / (std * s_y)

print(f"y = {y}")
print(f"ȳ = {y_mean}")
print(f"s_y² = {s_y2:.2f},  s_y = {s_y:.4f}")
print(f"\nProducts (x_i - x̄)(y_i - ȳ): {(x - mean) * (y - y_mean)}")
print(f"Sum of products: {((x - mean) * (y - y_mean)).sum()}")
print(f"Covariance s_xy = {cov_xy}")
print(f"Correlation r_xy = {cov_xy} / ({std:.4f} × {s_y:.4f}) = {corr_xy:.4f}")
print(f"\nVerification: np.corrcoef(x, y)[0,1] = {np.corrcoef(x, y)[0, 1]:.4f}")
y = [ 3. -2. 4. 1. 0.]
ȳ = 1.2
s_y² = 5.70, s_y = 2.3875
Products (x_i - x̄)(y_i - ȳ): [ 1.8 6.4 5.6 0.2 -0. ]
Sum of products: 14.0
Covariance s_xy = 3.5
Correlation r_xy = 3.5 / (1.5811 × 2.3875) = 0.9272
Verification: np.corrcoef(x, y)[0,1] = 0.9272
Section 2: Random Variables, Expectation, and the Population–Sample Distinction
2.1 Population vs. Sample
A crucial distinction underlies all of statistics:
The population is the entire (usually infinite or very large) set of possible outcomes. For example, “all possible monthly returns that SPY could ever produce.”
A sample is a finite collection of observations drawn from the population. For example, “the 168 monthly returns we actually observed from 2010–2023.”
We use sample statistics (, , etc.) to estimate population parameters (, , etc.). The sample mean is our best guess of the true mean , but it comes with uncertainty because different samples would give different values.
2.2 The Standard Error of the Mean
If are independent draws from a population with mean and variance , then the sample mean
has:
Why and not here? In Section 1.3 we used Bessel’s correction () when estimating the population variance from a sample — that corrects for the bias introduced by using in place of the unknown . Here the situation is different: we are not estimating anything. The formula is an exact algebraic result that follows directly from the properties of variance. Since the are independent, , and dividing a random variable by scales its variance by , giving . The here simply counts how many observations are being averaged — it has nothing to do with degrees of freedom or bias correction.
The standard error of the mean is therefore:
In practice is unknown, so we replace it with the sample standard deviation (computed with the Bessel-corrected denominator from Section 1.2). Note that the inside and the inside play completely different roles: corrects the bias when estimating the variance, while reflects the number of observations being averaged. The estimated standard error is:
Hand calculation with our data (, , ):
This tells us: “If we repeatedly drew samples of size 5 from this population and computed the mean each time, those means would have a standard deviation of about 0.71.”
# ============================================================================
# Standard error of the mean — hand calculation verification
# ============================================================================

se_mean = std / np.sqrt(n)
print(f"s = {std:.4f}")
print(f"n = {n}")
print(f"SE(x̄) = s / √n = {std:.4f} / √{n} = {se_mean:.4f}")
print(f"Verification: √(s²/n) = √({var}/{n}) = √{var/n:.4f} = {np.sqrt(var/n):.4f}")
s = 1.5811
n = 5
SE(x̄) = s / √n = 1.5811 / √5 = 0.7071
Verification: √(s²/n) = √(2.5/5) = √0.5000 = 0.7071
Section 3: The Central Limit Theorem — The Engine of Inference
The CLT is the single most important result in statistics. It is the reason we can do hypothesis testing, build confidence intervals, and compute p-values. In this section we state the classical version first, then progressively relax its assumptions toward versions that actually apply to financial time series. By the end, you will understand exactly which CLT variant underwrites the Newey-West standard errors used throughout the Fama-French tutorials.
Reading guide. Sections 3.1–3.2 (classical CLT) and Section 3.7 (visual demo) are essential for everyone. Sections 3.3–3.5 develop the theoretical machinery that justifies Newey-West for time-series data — they can be skimmed on a first reading and revisited after working through Section 7.
What are Newey-West standard errors? In short, they are a method for computing standard errors that remain valid even when the data are serially correlated and/or heteroscedastic — two features that are ubiquitous in financial time series. Where ordinary standard errors assume each observation is independent, Newey-West standard errors account for the fact that nearby observations may be correlated, allowing intervals to become wider or narrower depending on the covariance structure. We develop the full theory and a hand-checkable example in Section 7.
3.1 Version 1: The Classical CLT (Lindeberg-Lévy)
Theorem. Let be independent and identically distributed (i.i.d.) random variables with mean and finite variance . Then as :
In words: the standardized sample mean converges in distribution to a standard normal, regardless of the shape of the underlying distribution.
Assumptions: (1) identical distributions, (2) independence, (3) finite variance.
What this buys us: We can compute the distribution of without knowing the shape of the . This is extraordinary — we need no parametric model for the data.
Relevance for finance: If monthly returns were truly i.i.d. (same distribution every month, no dependence across time), this version would be all we need. But they are not — so we need to relax the assumptions.
3.2 Why This Is Revolutionary
The CLT tells us something extraordinary:
The might follow any distribution — uniform, exponential, chi-squared, a bizarre bimodal shape, anything with finite variance.
Yet the average of many such observations will be approximately normal.
The approximation improves as grows.
This is why the normal distribution appears everywhere in statistics: it governs the behavior of averages and sums, not necessarily of individual observations.
3.3 Version 2: Dropping “Identical” — The Lindeberg-Feller CLT
The problem with “identically distributed.” In a regression , the coefficient estimator is a weighted average of the — where the weights depend on the values and differ across observations. Even if the errors are i.i.d., the weighted terms are not identically distributed. The classical CLT does not directly apply.
The solution. The Lindeberg-Feller CLT drops the “identically distributed” requirement:
Theorem (Lindeberg-Feller). Let be independent (but not necessarily identically distributed) random variables with and . If the Lindeberg tail condition holds — for every , , where — then:
Assumptions: (1) independence, (2) finite variances, (3) the Lindeberg tail condition (variance non-dominance alone is insufficient).
What this buys us: Regression coefficients are asymptotically normal even when the regressors take different values across observations. This is why OLS inference works even for regression (not just sample means).
Relevance for finance: This handles the “weighted average” structure of , but still requires independence — which financial time series violate.
3.4 Version 3: Dropping “Independent” (Partially) — The Martingale Difference CLT
The problem with “independent.” Monthly stock returns exhibit volatility clustering — periods of high volatility (like 2008–2009 or March 2020) alternate with calm periods. Even if returns themselves are nearly unpredictable (weak autocorrelation), they are not independent, because knowing yesterday’s return magnitude tells you something about today’s volatility.
A useful middle ground. Many financial models assume that returns are a martingale difference sequence (MDS). This means:
In words: the conditional mean of the next return is zero (given past data), even though other aspects of the conditional distribution (like the variance) may depend on the past. This is weaker than independence — it says returns are unpredictable in conditional mean (including nonlinear functions of past information) but not necessarily independent.
Theorem (MDS-CLT). Let be a stationary, ergodic martingale difference sequence with . Then:
Assumptions: (1) MDS property (unpredictability), (2) stationarity and ergodicity, (3) finite variance. Independence is not required.
What this buys us: We can handle volatility clustering. Even though changes over time (GARCH effects), as long as returns themselves are unpredictable, is asymptotically normal with variance where is the unconditional variance.
Relevance for finance: An MDS can model demeaned innovations. Market efficiency by itself does not imply zero or constant conditional expected raw returns; risk premia can vary. This CLT version is what makes standard hypothesis tests on mean returns valid — even with GARCH-type volatility clustering — as long as the standard errors are computed correctly (i.e., using the unconditional variance, or better yet, a HAC estimator).
3.5 Version 4: Allowing Mild Dependence — The CLT for Mixing Processes
The problem with MDS. In reality, monthly returns may exhibit mild autocorrelation (short-run momentum or reversal effects), and regression residuals may be serially correlated. If , we can’t use the MDS-CLT.
The solution. One useful class of CLTs for finance allows weak dependence — observations can be correlated, but observations far apart in time must be nearly independent. This is formalized by mixing conditions (such as -mixing or strong mixing):
Theorem (CLT for stationary mixing sequences). One sufficient version assumes strict stationarity, for some , and strong-mixing coefficients satisfying , with positive long-run variance. Write . Then:
The asymptotic variance is not simply . It is the long-run variance:
This equals times the spectral density at frequency zero — the “DC component” of the time series.
Assumptions: stationarity, a sufficiently fast mixing rate and suitable moments. Summable autocovariances alone do not imply mixing or a CLT. In regressions, these conditions concern the score process and the regressor moments, not only the residuals.
What this buys us: A useful sufficient framework for weakly dependent time series. The sample mean is still asymptotically normal, but its variance is , not . If autocovariances are positive, and the “naive” standard error understates the true uncertainty.
Relevance for finance: This is the CLT that Newey-West standard errors are built on. Newey-West estimates from the data using a weighted sum of sample autocovariances. We will derive this in full detail in Section 7.
3.6 Summary: Which CLT Do We Need?
| Version | Assumes | Allows | Variance of | Used for |
|---|---|---|---|---|
| Lindeberg-Lévy (3.1) | i.i.d. | Non-normality | Textbook examples | |
| Lindeberg-Feller (3.3) | Independent (not identical) | Weighted averages, regression | OLS with known | |
| MDS-CLT (3.4) | Unpredictable (MDS) | Volatility clustering | Returns under EMH | |
| Mixing CLT (3.5) | Decaying dependence | Serial correlation + heteroscedasticity | Newey-West / HAC |
For empirical asset pricing with financial time series, we need the Mixing CLT (or at minimum the MDS-CLT). The classical i.i.d. version is a pedagogical starting point — useful for intuition — but it does not match the properties of real financial data.
The key takeaway: When its assumptions hold, a CLT delivers asymptotic normality of the sample mean (or regression coefficients). What changes across versions is the variance expression. Getting the variance right is the entire game — and it is exactly what robust standard errors (Newey-West) are designed to do.
3.7 A Visual Demonstration
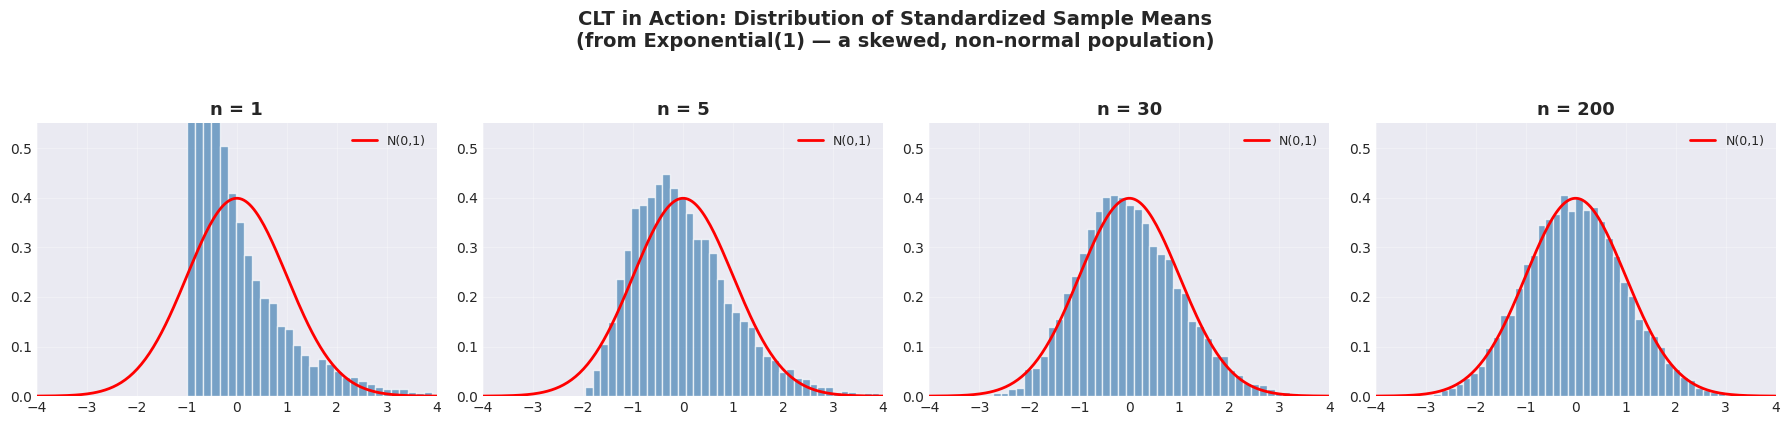
Let us verify the CLT by repeatedly drawing samples from a decidedly non-normal distribution — the exponential distribution (which is right-skewed with skewness = 2) — and examining the distribution of sample means.
Source
# ============================================================================
# CLT Demonstration: Sample means from an Exponential(1) distribution
# True mean μ = 1, true variance σ² = 1
# ============================================================================

np.random.seed(42)
num_simulations = 10_000
sample_sizes = [1, 5, 30, 200]

fig, axes = plt.subplots(1, 4, figsize=(18, 4))

for ax, n_sim in zip(axes, sample_sizes):
    # Draw all samples at once (vectorized — much faster than a Python loop)
    sample_means = np.random.exponential(scale=1.0, size=(num_simulations, n_sim)).mean(axis=1)

    # Standardize: z = (x̄ - μ) / (σ/√n)
    z_scores = (sample_means - 1.0) / (1.0 / np.sqrt(n_sim))

    ax.hist(z_scores, bins=50, density=True, alpha=0.7, color='steelblue', edgecolor='white')

    # Overlay standard normal
    t_grid = np.linspace(-4, 4, 200)
    ax.plot(t_grid, stats.norm.pdf(t_grid), 'r-', linewidth=2, label='N(0,1)')

    ax.set_title(f'n = {n_sim}', fontweight='bold', fontsize=13)
    ax.set_xlim(-4, 4)
    ax.set_ylim(0, 0.55)
    ax.legend(fontsize=9)
    ax.grid(True, alpha=0.3)

fig.suptitle('CLT in Action: Distribution of Standardized Sample Means\n'
             '(from Exponential(1) — a skewed, non-normal population)',
             fontsize=14, fontweight='bold', y=1.05)
plt.tight_layout()
plt.show()

print("""
OBSERVATIONS:
• n = 1:   The sample mean IS the single draw → looks exponential (right-skewed)
• n = 5:   Already much more symmetric, but still visibly non-normal
• n = 30:  Nearly indistinguishable from the standard normal curve
• n = 200: Essentially perfect normal bell curve

KEY INSIGHT: The population is exponential (skewness = 2), yet the sample
mean's distribution converges to N(0,1) as n grows. This is the CLT.
""")
OBSERVATIONS:
• n = 1:   The sample mean IS the single draw → looks exponential (right-skewed)
• n = 5:   Already much more symmetric, but still visibly non-normal
• n = 30:  Nearly indistinguishable from the standard normal curve
• n = 200: Essentially perfect normal bell curve

KEY INSIGHT: The population is exponential (skewness = 2), yet the sample
mean's distribution converges to N(0,1) as n grows. This is the CLT.
3.8 Why the Long-Run Variance Matters — A Quick Demonstration
The classical CLT says . But when data are autocorrelated, the true variance of the sample mean is , where can be much larger than .
The following simulation makes this concrete. We draw from an AR(1) process with autocorrelation and compare the actual dispersion of sample means against what the naive formula predicts.
Source
# ============================================================================
# Mixing CLT: naive SE vs true SE for autocorrelated data
# ============================================================================

np.random.seed(123)
n_ar = 100
rho_demo = 0.5
num_mc = 5000

# Generate num_mc independent AR(1) series, each of length n_ar
means_ar = np.zeros(num_mc)
for sim in range(num_mc):
    eps = np.random.randn(n_ar)
    ar_series = np.zeros(n_ar)
    ar_series[0] = eps[0] / np.sqrt(1 - rho_demo**2)  # stationary initial draw
    for t in range(1, n_ar):
        ar_series[t] = rho_demo * ar_series[t - 1] + eps[t]
    means_ar[sim] = ar_series.mean()

# Theoretical values
gamma0 = 1.0 / (1 - rho_demo**2)          # Var(X_t) for AR(1)
sigma_lr_sq = gamma0 * (1 + rho_demo) / (1 - rho_demo)  # long-run variance
naive_se = np.sqrt(gamma0 / n_ar)
true_se = np.sqrt(sigma_lr_sq / n_ar)

fig, ax = plt.subplots(figsize=(9, 4.5))
ax.hist(means_ar, bins=60, density=True, alpha=0.6, color='steelblue',
        edgecolor='white', label='Simulated $\\bar{X}_n$')

grid = np.linspace(means_ar.min(), means_ar.max(), 300)
ax.plot(grid, stats.norm.pdf(grid, 0, naive_se), 'r--', linewidth=2,
        label=f'Naive: $\\sigma / \\sqrt{{n}}$ = {naive_se:.3f}')
ax.plot(grid, stats.norm.pdf(grid, 0, true_se), 'g-', linewidth=2,
        label=f'True:  $\\sigma_{{LR}} / \\sqrt{{n}}$ = {true_se:.3f}')

ax.set_title(f'AR(1) with ρ = {rho_demo}: Naive SE Understates Uncertainty',
             fontweight='bold', fontsize=13)
ax.set_xlabel('$\\bar{X}_n$')
ax.set_ylabel('Density')
ax.legend(fontsize=10)
ax.grid(True, alpha=0.3)
plt.tight_layout()
plt.show()

print(f"Naive SE (σ/√n):              {naive_se:.4f}")
print(f"True SE  (σ_LR/√n):           {true_se:.4f}")
print(f"Empirical SD of sample means:  {means_ar.std():.4f}")
print(f"\nThe naive SE underestimates uncertainty by a factor of "
      f"{true_se / naive_se:.2f}x.")
print("This is exactly the problem that Newey-West standard errors fix (Section 7).")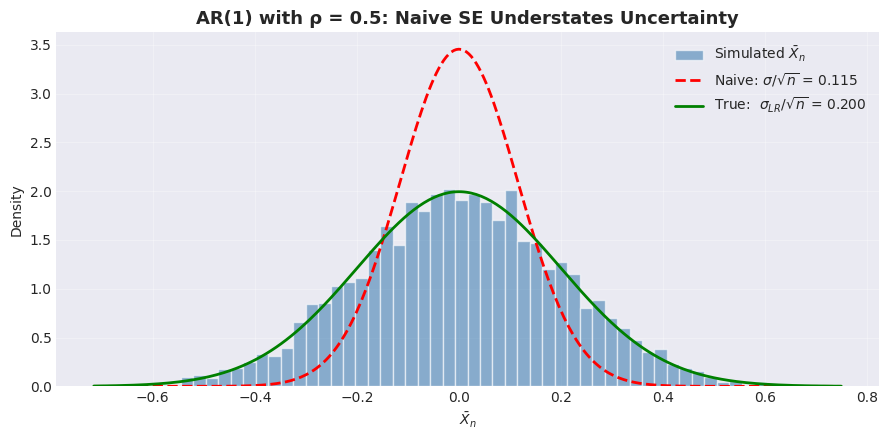
Naive SE (σ/√n):              0.1155
True SE  (σ_LR/√n):           0.2000
Empirical SD of sample means:  0.2034

The naive SE underestimates uncertainty by a factor of 1.73x.
This is exactly the problem that Newey-West standard errors fix (Section 7).
Section 4: Hypothesis Testing, t-Statistics, and p-Values — and the CLT Connection
4.1 The Framework
Hypothesis testing asks: “Could this result have arisen by chance?”
Suppose we observe a sample mean for a set of monthly excess returns. That sounds like a positive return — but with only 5 noisy observations, maybe the true mean is actually zero and we just got an unlucky draw. Hypothesis testing gives us a principled way to weigh the evidence.
We set up two competing hypotheses:
(null hypothesis): The effect is zero. For example, (“the true mean excess return is zero — the asset earns no premium”).
(alternative hypothesis): The effect is nonzero. For example, .
The logic compares the statistic with its null distribution, allowing a controlled probability of false rejection: we temporarily assume is true and ask how surprising our observed data would be under that assumption. If the data would be very surprising (low probability), we reject . If the data is not particularly unusual under , we have no grounds to reject it.
This is analogous to a courtroom trial: the null hypothesis is “innocent until proven guilty.” We need sufficient evidence (data) to reject this default presumption. Importantly, failing to reject does not prove is true — it merely means we lack enough evidence to overturn it.
4.2 The t-Distribution — What It Is and Where It Comes From
Before constructing our test statistic, we need to understand a distribution that plays a central role in small-sample inference: the Student’s -distribution.
The problem. If are i.i.d. and we knew the true , then
But we almost never know . When we replace it with the sample standard deviation , we introduce extra randomness in the denominator — itself varies from sample to sample. The resulting ratio is no longer standard normal.
The solution (Student, 1908). William Sealy Gosset (writing under the pseudonym “Student”) showed that if the underlying data are normally distributed, then
follows a -distribution with degrees of freedom. The parameter (degrees of freedom) matches the denominator in Bessel’s correction, for the same reason: we used up one degree of freedom by estimating with .
Key properties of the -distribution:
| Property | Description |
|---|---|
| Shape | Bell-shaped and symmetric around zero, like the standard normal |
| Tails | Heavier than the normal — extreme values are more likely |
| Parameter | Single parameter: degrees of freedom |
| Convergence | As , |
| Variance | for (always , so wider than ) |
The heavier tails reflect the extra uncertainty from estimating with . With small samples, can differ substantially from , so the -distribution is noticeably wider than the normal. With large samples, and the -distribution is nearly indistinguishable from .
For our data with , we have degrees of freedom. The distribution has variance — double that of the standard normal. This matters: using the normal instead of the would make us overconfident.
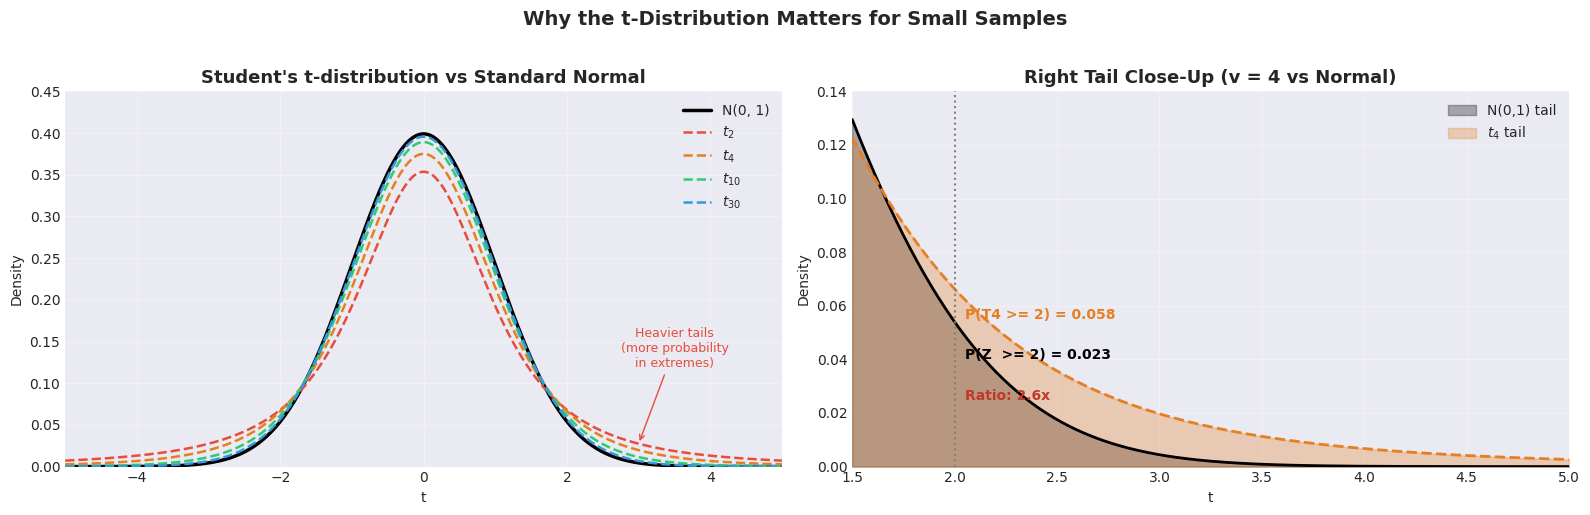
The plot below visualizes exactly this — notice how the distribution spreads more probability into the tails compared to , and how larger brings the -distribution closer to the normal.
Source
# ============================================================================
# Visualizing the t-distribution vs the standard normal
# ============================================================================

fig, axes = plt.subplots(1, 2, figsize=(16, 5))

# --- Left panel: overlay several t-distributions against N(0,1) ---
t_grid = np.linspace(-5, 5, 500)
dfs = [2, 4, 10, 30]
colors = ['#e74c3c', '#e67e22', '#2ecc71', '#3498db']

ax = axes[0]
ax.plot(t_grid, stats.norm.pdf(t_grid), 'k-', linewidth=2.5, label='N(0, 1)')
for df_val, color in zip(dfs, colors):
    ax.plot(t_grid, stats.t.pdf(t_grid, df=df_val), '--', linewidth=1.8,
            color=color, label=f'$t_{{{df_val}}}$')

ax.set_title('Student\'s t-distribution vs Standard Normal', fontweight='bold', fontsize=13)
ax.set_xlabel('t')
ax.set_ylabel('Density')
ax.legend(fontsize=10)
ax.set_xlim(-5, 5)
ax.set_ylim(0, 0.45)
ax.grid(True, alpha=0.3)
ax.annotate('Heavier tails\n(more probability\nin extremes)',
            xy=(3.0, stats.t.pdf(3.0, df=2)), xytext=(3.5, 0.12),
            fontsize=9, ha='center',
            arrowprops=dict(arrowstyle='->', color='#e74c3c'),
            color='#e74c3c')

# --- Right panel: zoom into the right tail to highlight the difference ---
ax2 = axes[1]
tail_grid = np.linspace(1.5, 5, 300)
ax2.fill_between(tail_grid, stats.norm.pdf(tail_grid), alpha=0.3, color='black', label='N(0,1) tail')
ax2.fill_between(tail_grid, stats.t.pdf(tail_grid, df=4), alpha=0.3, color='#e67e22', label='$t_4$ tail')
ax2.plot(tail_grid, stats.norm.pdf(tail_grid), 'k-', linewidth=2)
ax2.plot(tail_grid, stats.t.pdf(tail_grid, df=4), '--', linewidth=2, color='#e67e22')

# Mark the t = 2 line and show the p-value difference
ax2.axvline(x=2.0, color='gray', linestyle=':', linewidth=1.5)
p_norm_tail = 1 - stats.norm.cdf(2.0)
p_t4_tail = 1 - stats.t.cdf(2.0, df=4)
ax2.annotate(f'P(T4 >= 2) = {p_t4_tail:.3f}', xy=(2.05, 0.055), fontsize=10, color='#e67e22', fontweight='bold')
ax2.annotate(f'P(Z  >= 2) = {p_norm_tail:.3f}', xy=(2.05, 0.04), fontsize=10, color='black', fontweight='bold')
ax2.annotate(f'Ratio: {p_t4_tail/p_norm_tail:.1f}x', xy=(2.05, 0.025), fontsize=10, color='#c0392b', fontweight='bold')

ax2.set_title('Right Tail Close-Up (v = 4 vs Normal)', fontweight='bold', fontsize=13)
ax2.set_xlabel('t')
ax2.set_ylabel('Density')
ax2.legend(fontsize=10)
ax2.set_xlim(1.5, 5)
ax2.set_ylim(0, 0.14)
ax2.grid(True, alpha=0.3)

fig.suptitle('Why the t-Distribution Matters for Small Samples',
             fontsize=14, fontweight='bold', y=1.02)
plt.tight_layout()
plt.show()

print("""
KEY OBSERVATIONS:
- The t-distribution is bell-shaped and symmetric like the normal, but with heavier tails.
- With v = 4 (our n = 5 example), the tails are substantially heavier -- the t4 allocates
  about 2.5x more probability beyond t = 2 than the standard normal.
- As v increases (v = 10, 30, ...), the t-distribution rapidly approaches N(0, 1).
- For v >= 30, the two are nearly indistinguishable in practice.
- This is why we MUST use the t-distribution for small samples: using the normal would
  make us overconfident (p-values too small, confidence intervals too narrow).
""")
KEY OBSERVATIONS:
- The t-distribution is bell-shaped and symmetric like the normal, but with heavier tails.
- With v = 4 (our n = 5 example), the tails are substantially heavier -- the t4 allocates
  about 2.5x more probability beyond t = 2 than the standard normal.
- As v increases (v = 10, 30, ...), the t-distribution rapidly approaches N(0, 1).
- For v >= 30, the two are nearly indistinguishable in practice.
- This is why we MUST use the t-distribution for small samples: using the normal would
  make us overconfident (p-values too small, confidence intervals too narrow).
4.3 The t-Statistic
Under , the test statistic is:
This measures how many standard errors the sample mean is away from zero. The intuition is simple:
If is far from 0 (the null value) relative to its own uncertainty, that is strong evidence against .
If is close to 0 relative to the noise, the data are consistent with .
The -statistic standardizes the sample mean into a “signal-to-noise ratio”: the numerator is the signal () and the denominator is the noise ().
Hand calculation with our data:
So our observed mean is about 1.41 standard errors above zero — present, but not overwhelmingly so.
4.4 The p-Value
The p-value is the probability of observing a test statistic at least as extreme as the one we got, assuming is true. “At least as extreme” means at least as far from zero in either direction (for a two-sided test).
Formally, for a two-sided test with degrees of freedom:
where denotes a random variable following a -distribution with 4 degrees of freedom.
How to interpret the p-value:
A small p-value (e.g., ) means: “Data this extreme would be very unlikely if were true.” This is evidence against .
A large p-value means: “Data this extreme is not unusual under .” We have no strong reason to reject .
The p-value is not the probability that is true. It is the probability of seeing data this extreme given that is true — a crucial distinction.
The conventional significance level is , meaning we reject if . This corresponds to a threshold of about 2 (more precisely, for the relevant degrees of freedom). The “rule of thumb” you often hear — “a -statistic above 2 is significant” — comes from this.
4.5 Why a t-Distribution Instead of the Standard Normal?
When the sample size is small and we estimate with , the ratio does not exactly follow . As derived in Section 4.2, it follows a -distribution with degrees of freedom under i.i.d. normal sampling. Small sample size alone does not justify that distribution.
Using the standard normal when you should use the -distribution would understate the p-value — you’d think data is more significant than it actually is. This is because the -distribution allocates more probability to the tails.
For example, under the standard normal, but under . That is a factor of 2.5 difference. With 4 degrees of freedom, the normal would mislead you substantially.
As , the distribution converges to . For , the difference is already small. This convergence is related to the CLT: with enough data, estimating with introduces negligible additional uncertainty, and the extra randomness in the denominator vanishes.
4.6 Confidence Intervals
A confidence interval inverts the hypothesis test. Instead of asking “Is ?”, it asks: “What range of values are consistent with our data?”
A 95% confidence interval for is:
where is the 97.5th percentile of the distribution. We use the -distribution (not the normal) for the same reason as above: we are estimating from a small sample.
The critical value 2.776 is notably larger than the 1.96 we would use from the standard normal. This makes the confidence interval wider, appropriately reflecting our greater uncertainty with .
Hand calculation:
Since this interval contains zero, we cannot reject at the 5% level — consistent with our p-value being above 0.05.
Interpretation. “If we repeated this experiment many times and computed a 95% CI each time, about 95% of those intervals would contain the true .” It does not mean there is a 95% probability that lies in this particular interval — is a fixed (unknown) number, not a random variable.
# ============================================================================
# Hand-checkable hypothesis test
# Uses: mean, se_mean, n from Sections 1–2 (cells above)
# ============================================================================

t_stat = mean / se_mean
df_t = n - 1
p_value = 2 * (1 - stats.t.cdf(abs(t_stat), df=df_t))
t_crit = stats.t.ppf(0.975, df=df_t)
ci_low = mean - t_crit * se_mean
ci_high = mean + t_crit * se_mean

print("HYPOTHESIS TEST: H₀: μ = 0  vs  H₁: μ ≠ 0")
print("=" * 55)
print(f"  x̄ = {mean}")
print(f"  SE(x̄) = {se_mean:.4f}")
print(f"  t = x̄ / SE = {mean} / {se_mean:.4f} = {t_stat:.4f}")
print(f"  Degrees of freedom = n - 1 = {df_t}")
print(f"\n  p-value (two-sided) = {p_value:.4f}")
print(f"  t-critical (α=0.05, df={df_t}) = ±{t_crit:.3f}")
print(f"  95% CI = [{ci_low:.3f}, {ci_high:.3f}]")
print(f"\n  Decision: {'Reject H₀' if p_value < 0.05 else 'Fail to reject H₀'} at 5% level")
print(f"  (CI {'does NOT contain' if ci_low > 0 or ci_high < 0 else 'contains'} zero — consistent with p-value)")
HYPOTHESIS TEST: H₀: μ = 0 vs H₁: μ ≠ 0
=======================================================
x̄ = 1.0
SE(x̄) = 0.7071
t = x̄ / SE = 1.0 / 0.7071 = 1.4142
Degrees of freedom = n - 1 = 4
p-value (two-sided) = 0.2302
t-critical (α=0.05, df=4) = ±2.776
95% CI = [-0.963, 2.963]
Decision: Fail to reject H₀ at 5% level
(CI contains zero — consistent with p-value)
4.7 Why the CLT Justifies Normal p-Values
Let us pause and appreciate the deep connection between the CLT and hypothesis testing. It is the intellectual heart of this entire notebook and fundamental to understanding how Newey-West works.
Above we used the t-distribution to compute the p-value. This was exact — it required that the are normally distributed (or that we use an exact finite-sample result). But in practice, financial returns are not normally distributed: they have fat tails, skewness, and time-varying volatility.
So why do our p-values still work?
The answer is the CLT. Here is the argument, spelled out carefully:
4.8 The Argument in Five Steps
Step 1. We want to test . Our test statistic is:
Step 2. By the CLT, for large :
Under (): .
Step 3. By the Law of Large Numbers, , i.e. the sample variance converges in probability to the true variance.
Step 4. By Slutsky’s theorem, replacing with in the denominator does not change the limiting distribution.
Slutsky’s Theorem. If and (a constant), then , and more generally for any continuous .
Applying this with and :
Step 5. Therefore, for large , we can compute p-values using the standard normal table (or the distribution, which is nearly identical for large ).
4.9 What “Nonparametric” Means Here
Notice what we did not assume in Steps 1–5:
We did not assume the are normally distributed.
We did not assume the have any particular distributional shape.
We only assumed they have a finite mean and variance and are (approximately) independent.
This is what makes the CLT-based inference nonparametric (more precisely, semiparametric; it is not an exact finite-sample distribution-free test): it works regardless of the population distribution, provided is large enough.
4.10 How Large is “Large Enough”?
The speed of CLT convergence depends on the distribution’s skewness and kurtosis:
| Distribution | Skewness | Kurtosis | needed for good approximation |
|---|---|---|---|
| Normal | 0 | 3 | Any (exact) |
| Uniform | 0 | 1.8 | |
| Exponential | 2 | 9 | |
| Highly skewed (e.g., Pareto) | Large | Very large | |
| Financial returns (mild fat tails) | ~0 | 4–6 |
The table is only heuristic: no fixed observation count guarantees a good approximation. Heavy tails, persistent scores and high leverage can make inference inaccurate even with hundreds of observations. This is why finance researchers can use standard-normal-based p-values with Newey-West standard errors even though returns are not normally distributed.
4.11 A Subtle but Critical Point
The CLT tells us that is approximately normal. This does not mean:
❌ Individual observations are normal
❌ Residuals from a regression are normal
❌ The error term is normal
It does mean:
✅ This works even when the underlying data is decidedly non-normal
✅ Functions of averages (like regression coefficients , which are weighted averages of the data) are approximately normal for large
✅ We can use the normal distribution to compute p-values for these statistics
# ============================================================================
# Demonstration: CLT-based p-value vs exact t-distribution p-value
# As n grows, they converge — showing the CLT justification in action
# ============================================================================

print("COMPARISON: t-distribution vs standard normal p-values")
print("=" * 65)
print(f"{'n':>6}  {'t-stat':>8}  {'p (t-dist)':>12}  {'p (normal)':>12}  {'Δp':>10}")
print("-" * 65)

# For each sample size, compute p-value under both distributions
for n_demo in [5, 10, 30, 50, 100, 200, 500]:
    t_val = 2.0  # Fix t-statistic at 2.0 for comparison
    p_t = 2 * (1 - stats.t.cdf(t_val, df=n_demo - 1))
    p_z = 2 * (1 - stats.norm.cdf(t_val))
    print(f"{n_demo:6d}  {t_val:8.2f}  {p_t:12.6f}  {p_z:12.6f}  {abs(p_t - p_z):10.6f}")

print(f"\nAs n → ∞, the t-distribution p-values converge to the normal p-values.")
print(f"The t-versus-normal difference is reported above; it does not measure finite-sample HAC accuracy.")
print(f"\nThis is why Newey-West uses the standard normal: with n ≈ 100-200 months,")
print(f"normal inference is an asymptotic approximation under the stated assumptions.")
COMPARISON: t-distribution vs standard normal p-values
=================================================================
n t-stat p (t-dist) p (normal) Δp
-----------------------------------------------------------------
5 2.00 0.116117 0.045500 0.070616
10 2.00 0.076553 0.045500 0.031053
30 2.00 0.054944 0.045500 0.009443
50 2.00 0.051059 0.045500 0.005559
100 2.00 0.048240 0.045500 0.002739
200 2.00 0.046860 0.045500 0.001360
500 2.00 0.046042 0.045500 0.000542
As n → ∞, the t-distribution p-values converge to the normal p-values.
The t-versus-normal difference is reported above; it does not measure finite-sample HAC accuracy.
This is why Newey-West uses the standard normal: with n ≈ 100-200 months,
normal inference is an asymptotic approximation under the stated assumptions.
Section 5: Linear Regression and OLS
We now shift from testing a single mean to analyzing the relationship between variables. This is the core of empirical finance: the Fama-French model asks whether exposure to market, size, and value factors explains the cross-section of expected returns — a question that is fundamentally about regression.
5.1 What Is Regression?
Regression answers the question: how does one variable change, on average, when another variable changes?
Concretely, given paired observations , we model:
where:
(the intercept) is the expected value of when ,
(the slope) is the expected change in per one-unit change in ,
(the error or residual) captures everything about that is not explained by .
In the Fama-French context, is the excess return of a portfolio, is the excess return of the market (or a factor), and measures the portfolio’s sensitivity (or loading) on that factor. A positive on the market factor means the portfolio tends to go up when the market goes up, and vice versa. The intercept — often called Jensen’s alpha — measures the average return that is not explained by factor exposure. If , the portfolio earns a premium beyond what its risk exposure would predict.
5.2 The Idea: Minimizing Squared Errors
How do we choose and ? The Ordinary Least Squares (OLS) principle says: choose the line that makes the residuals as small as possible, in the sense of minimizing the sum of squared residuals:
Why squared errors rather than absolute errors? Three reasons:
Differentiability — Squared errors are smooth, so we can use calculus to find the minimum.
Unique solution — The squared-error problem always has exactly one solution (for non-degenerate data).
Connection to the CLT — Under standard assumptions, the OLS estimator is the best linear unbiased estimator (BLUE), and its sampling distribution is governed by the CLT.
5.3 Deriving the OLS Formulas (Scalar Case)
To minimize , we take partial derivatives with respect to and and set them to zero.
Derivative with respect to :
This yields the first normal equation:
Derivative with respect to :
Substituting and simplifying gives the second normal equation:
This is an elegant result: the slope equals the sample covariance of and divided by the sample variance of . This makes intuitive sense — measures how much moves per unit of -variability.
5.4 A Geometric Intuition
Think of the observed -values as a point in -dimensional space. The set of all vectors of the form (where is the column of ones) traces out a 2-dimensional plane within that -dimensional space.
OLS finds the point on that plane that is closest to — that is, the orthogonal projection of onto the column space of . The residual vector is perpendicular to the column space, which is precisely the condition — the normal equations in matrix form.
This geometric picture explains several properties of OLS that can otherwise seem mysterious:
The residuals sum to zero (because is perpendicular to the constant column ).
The fitted values and residuals are uncorrelated (because lies in the column space while is perpendicular to it).
With an intercept, measures the cosine squared of the angle between the centered vectors and .
5.5 Hand Calculation with Our Data
Using the dataset from Section 1: and .
From Section 1 we already computed: , .
Step 1: Compute the deviations.
| 1 | 2 | 3 | 1.0 | 1.8 | 1.80 | 1.00 |
| 2 | −1 | −2 | −2.0 | −3.2 | 6.40 | 4.00 |
| 3 | 3 | 4 | 2.0 | 2.8 | 5.60 | 4.00 |
| 4 | 0 | 1 | −1.0 | −0.2 | 0.20 | 1.00 |
| 5 | 1 | 0 | 0.0 | −1.2 | 0.00 | 0.00 |
| Sum = 14.0 | Sum = 10.0 |
Step 2: Compute and .
So the fitted line is .
Interpretation: Each additional unit of is associated with a 1.4-unit increase in . The intercept -0.2 is the predicted value of when .
5.6 Visualizing the Fit
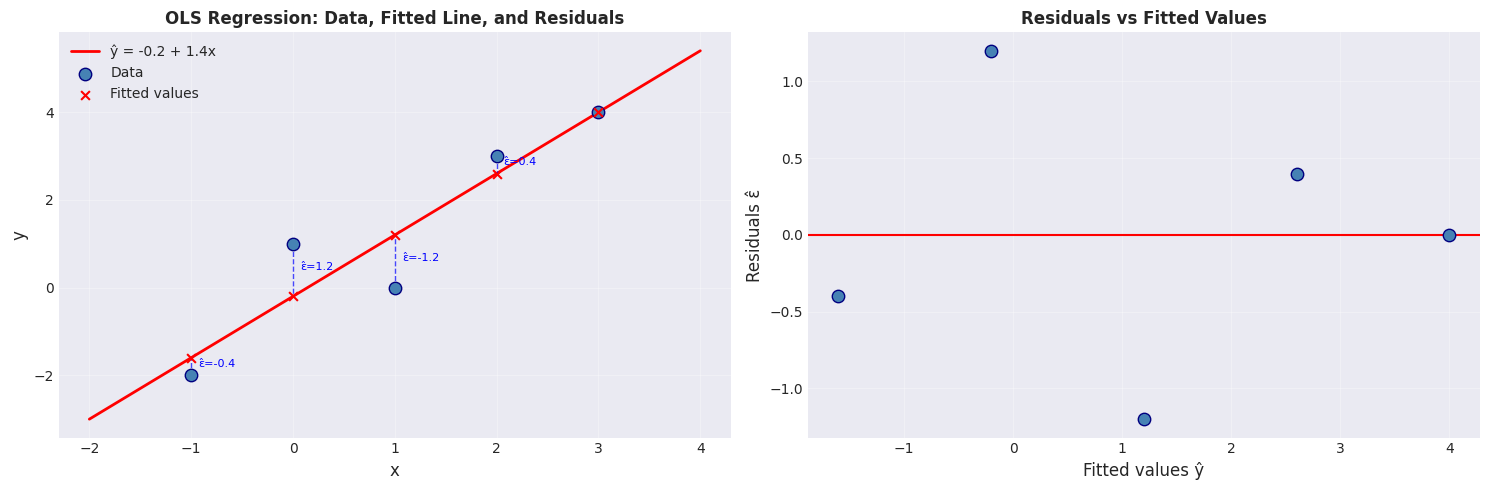
The code below plots the data and the fitted regression line, and marks the residuals as vertical distances from each point to the line — making concrete the idea that OLS minimizes the sum of these squared vertical distances.
# ============================================================================
# Section 5: Linear Regression and OLS — Hand calculation & visualization
# ============================================================================

# Regression data — same x, y from Section 1, renamed to avoid shadowing
# the single-variable analysis (mean, std, se_mean used in Section 4).
x_reg = np.array([2, -1, 3, 0, 1], dtype=float)
y_reg = np.array([3, -2, 4, 1, 0], dtype=float)
n_reg = len(x_reg)

# --- Step 1: Compute β̂ and α̂ using the scalar formulas ---
x_bar = x_reg.mean()
y_bar = y_reg.mean()

numerator = np.sum((x_reg - x_bar) * (y_reg - y_bar))   # Cov(x,y) * (n-1)
denominator = np.sum((x_reg - x_bar) ** 2)                # Var(x) * (n-1)

beta_hat = numerator / denominator
alpha_hat = y_bar - beta_hat * x_bar

print("SCALAR OLS — HAND VERIFICATION")
print("=" * 55)
print(f"  x̄ = {x_bar},  ȳ = {y_bar}")
print(f"  Σ(xᵢ - x̄)(yᵢ - ȳ) = {numerator}")
print(f"  Σ(xᵢ - x̄)²         = {denominator}")
print(f"\n  β̂ = {numerator}/{denominator} = {beta_hat}")
print(f"  α̂ = {y_bar} − {beta_hat}×{x_bar} = {alpha_hat}")

# --- Step 2: Fitted values and residuals ---
y_hat = alpha_hat + beta_hat * x_reg
residuals = y_reg - y_hat
RSS = np.sum(residuals ** 2)

print(f"\n  Fitted values ŷ: {y_hat}")
print(f"  Residuals ε̂:     {residuals}")
print(f"  Σε̂ᵢ = {residuals.sum():.10f}  (should ≈ 0)")
print(f"  RSS = Σε̂ᵢ² = {RSS:.2f}")

# --- Step 3: R² ---
SS_tot = np.sum((y_reg - y_bar) ** 2)
R_squared = 1 - RSS / SS_tot
print(f"\n  SS_tot = {SS_tot:.2f}")
print(f"  R² = 1 − RSS/SS_tot = 1 − {RSS:.2f}/{SS_tot:.2f} = {R_squared:.4f}")
print(f"  → {R_squared*100:.1f}% of the variation in y is explained by x.")

# ============================================================================
# Visualization: data, fitted line, and residuals
# ============================================================================

fig, axes = plt.subplots(1, 2, figsize=(15, 5))

# --- Left panel: scatter + fitted line + residuals ---
ax = axes[0]
x_grid = np.linspace(-2, 4, 100)
y_grid = alpha_hat + beta_hat * x_grid

ax.plot(x_grid, y_grid, 'r-', linewidth=2, label=f'ŷ = {alpha_hat:.1f} + {beta_hat:.1f}x')

# Draw residuals as vertical lines
for xi, yi, yhi in zip(x_reg, y_reg, y_hat):
    ax.plot([xi, xi], [yi, yhi], 'b--', linewidth=1, alpha=0.7)

ax.scatter(x_reg, y_reg, s=80, c='steelblue', edgecolors='navy', zorder=5, label='Data')
ax.scatter(x_reg, y_hat, s=40, c='red', marker='x', zorder=5, label='Fitted values')

ax.set_xlabel('x', fontsize=12)
ax.set_ylabel('y', fontsize=12)
ax.set_title('OLS Regression: Data, Fitted Line, and Residuals', fontweight='bold')
ax.legend(fontsize=10)
ax.grid(True, alpha=0.3)

# Annotate residuals
for i, (xi, yi, ei) in enumerate(zip(x_reg, y_reg, residuals)):
    if abs(ei) > 0.05:
        ax.annotate(f'ε̂={ei:.1f}', xy=(xi, (yi + y_hat[i])/2),
                    fontsize=8, color='blue', ha='left',
                    xytext=(5, 0), textcoords='offset points')

# --- Right panel: residuals vs fitted values ---
ax2 = axes[1]
ax2.scatter(y_hat, residuals, s=80, c='steelblue', edgecolors='navy', zorder=5)
ax2.axhline(y=0, color='red', linestyle='-', linewidth=1.5)
ax2.set_xlabel('Fitted values ŷ', fontsize=12)
ax2.set_ylabel('Residuals ε̂', fontsize=12)
ax2.set_title('Residuals vs Fitted Values', fontweight='bold')
ax2.grid(True, alpha=0.3)

plt.tight_layout()
plt.show()

print("""
KEY OBSERVATIONS:
• The fitted line passes through (x̄, ȳ) = (1.0, 1.2) — always true for OLS with an intercept.
• Residuals sum to zero — a consequence of including an intercept.
• The residual plot (right) shows no obvious pattern — consistent with a
  reasonable linear fit (though with only 5 points, diagnostics are limited).
• R² = {:.1f}%: most of the variation in y is captured by the linear relationship.
""".format(R_squared * 100))
SCALAR OLS — HAND VERIFICATION
=======================================================
x̄ = 1.0, ȳ = 1.2
Σ(xᵢ - x̄)(yᵢ - ȳ) = 14.0
Σ(xᵢ - x̄)² = 10.0
β̂ = 14.0/10.0 = 1.4
α̂ = 1.2 − 1.4×1.0 = -0.19999999999999996
Fitted values ŷ: [ 2.6 -1.6 4. -0.2 1.2]
Residuals ε̂: [ 4.0000000e-01 -4.0000000e-01 8.8817842e-16 1.2000000e+00
-1.2000000e+00]
Σε̂ᵢ = 0.0000000000 (should ≈ 0)
RSS = Σε̂ᵢ² = 3.20
SS_tot = 22.80
R² = 1 − RSS/SS_tot = 1 − 3.20/22.80 = 0.8596
→ 86.0% of the variation in y is explained by x.
KEY OBSERVATIONS:
• The fitted line passes through (x̄, ȳ) = (1.0, 1.2) — always true for OLS with an intercept.
• Residuals sum to zero — a consequence of including an intercept.
• The residual plot (right) shows no obvious pattern — consistent with a
  reasonable linear fit (though with only 5 points, diagnostics are limited).
• R² = 86.0%: most of the variation in y is captured by the linear relationship.
5.7 The Matrix Formulation
The scalar formulas from Section 5.3 work for simple regression (one regressor). But the Fama-French model has three regressors (market, size, value) — and in general we need to handle regressors simultaneously. Matrix algebra provides a compact, general framework that works for any number of regressors. It also sets up the variance formulas we will need for robust standard errors in subsequent sections.
The model in matrix form. Stack all observations into a single equation:
where:
is the vector of outcomes,
is the design matrix — its first column is a column of ones (the intercept), and the remaining columns are the regressors,
is the vector of parameters ,
is the vector of errors.
For our 5-observation simple regression, (intercept + one slope):
Deriving the OLS estimator. The residual sum of squares in matrix form is:
Expanding:
To minimize, we take the matrix derivative (gradient) and set it to zero. The key matrix calculus identities are:
, for any constant vector ;
, for any symmetric matrix .
Applying these:
Rearranging gives the normal equations:
This is a system of linear equations in unknowns. If is invertible (which requires that no regressor is a perfect linear combination of the others), we can solve directly:
Interpreting the components. Each piece of this formula has a clear meaning:
| Expression | Dimension | Meaning |
|---|---|---|
| Information matrix — measures the total “variation” in the regressors. Larger values (more spread in ) mean more precise estimates. | ||
| Cross-moment vector — measures how each regressor covaries with the outcome. | ||
| Inverts the information matrix, converting raw covariation into properly scaled regression coefficients. |
The formula says: equals the covariation of regressors with outcomes, scaled by the inverse of the regressors’ own variation. This is the multivariate generalization of .
Connection to projection (Section 5.4 revisited). The normal equations can be rewritten as:
This says the residual vector is orthogonal to every column of — exactly the geometric projection condition from Section 5.4. The fitted values are the orthogonal projection of onto the column space of :
where is the hat matrix (or projection matrix). It “puts the hat on .” The hat matrix is symmetric () and idempotent () — properties that projections always have.
5.8 From Coefficients to Standard Errors: Deriving 
Computing is only half the job. To do inference (test hypotheses, build confidence intervals), we need to know how uncertain our estimates are. This requires deriving the variance of the estimator.
Step 1 — Express in terms of the true errors. Substituting into the OLS formula:
This is a fundamental decomposition: equals the truth plus a noise term that depends on the errors. Two immediate consequences:
Unbiasedness: If , then .
Consistency: As , the noise term vanishes (under regularity conditions), so .
Step 2 — The variance-covariance matrix: what it is and why we need it. For a scalar random variable , its variance is — a single number. But is a vector of random variables . We need a matrix that captures the variance of each component and the covariances between components. This is the variance-covariance matrix, defined as:
This is a matrix. Its structure is:
The diagonal entries are the variances — the standard errors come directly from these: .
The off-diagonal entries are covariances between different coefficient estimates — these matter when testing joint hypotheses (e.g., are multiple coefficients simultaneously zero?).
“Conditional on ” means we treat the regressor matrix as fixed (non-random) and ask: over repeated samples of drawn from the same error distribution, how much would vary? This is the standard frequentist perspective — the randomness comes only from , not from .
Step 3 — Derive the formula. From Step 1, we know . Since (unbiasedness), we can substitute directly into the definition:
Using the transpose rule :
Since is treated as fixed, only is random, so the expectation passes through:
Here is the variance-covariance matrix of the errors — its entry is . The diagonal entries are the individual error variances , and the off-diagonals capture any correlation between errors at different observations.
This gives us the sandwich formula — so named for its bread-meat-bread structure:
The bread comes from the OLS mechanics and is the same no matter what the errors look like. The meat captures the actual error structure — their variances, their correlations, everything.
5.9 Classic OLS: The Homoscedastic Special Case
Under the classic assumptions — errors are homoscedastic and uncorrelated:
the meat simplifies dramatically:
Substituting into the sandwich formula:
This is the classic OLS variance formula. The cancellation occurs because when , the bread and meat share the same structure, and one copy cancels. But when — for instance, if errors are heteroscedastic or autocorrelated — this cancellation does not occur, and the classic formula gives wrong standard errors. This is exactly the problem that robust methods (Section 6) will fix.
Estimating . Since is unknown, we estimate it from residuals:
We divide by (not ) because the OLS fit “uses up” degrees of freedom — same logic as dividing by for sample variance. The standard errors are then:
5.10 Numerical Verification
Applying the matrix formulas to our 5-observation example confirms the scalar results from Section 5.5: , , , , and . The code below carries out the full matrix computation and cross-checks against statsmodels.
# ============================================================================
# Verify the matrix OLS formulas from Sections 5.7–5.10
# ============================================================================

# Our data
x_reg = np.array([2, -1, 3, 0, 1], dtype=float)
y_reg = np.array([3, -2, 4, 1, 0], dtype=float)
n_reg = len(x_reg)
k_reg = 2  # intercept + one slope

# Design matrix  (n × k)
X_mat = np.column_stack([np.ones(n_reg), x_reg])

# OLS via the normal equations:  β̂ = (X'X)⁻¹ X'y
XtX     = X_mat.T @ X_mat
XtX_inv = np.linalg.inv(XtX)
beta_hat = XtX_inv @ (X_mat.T @ y_reg)

# Residuals and RSS
y_hat = X_mat @ beta_hat
resid = y_reg - y_hat
RSS   = resid @ resid

# Classic variance estimate:  Var(β̂) = σ̂²(X'X)⁻¹
sigma2_hat = RSS / (n_reg - k_reg)
var_beta   = sigma2_hat * XtX_inv
se_classic = np.sqrt(np.diag(var_beta))

# t-statistics and p-values
t_stats = beta_hat / se_classic
p_vals  = 2 * (1 - stats.t.cdf(np.abs(t_stats), df=n_reg - k_reg))

# Verify orthogonality condition:  X'ε̂ = 0  (the normal equations)
ortho_check = X_mat.T @ resid

print("MATRIX OLS — NUMERICAL VERIFICATION")
print("=" * 55)
print(f"  β̂ = (X'X)⁻¹X'y = [{beta_hat[0]:.1f}, {beta_hat[1]:.1f}]")
print(f"  α̂ = {beta_hat[0]:.1f},  β̂ = {beta_hat[1]:.1f}")
print(f"\n  X'ε̂ = {ortho_check}  (orthogonality check — should be ≈ 0)")
print(f"  Σε̂ = {resid.sum():.10f}  (residuals sum to zero ✓)")
print(f"  RSS = {RSS:.2f}")
print(f"\n  σ̂² = RSS/(n−k) = {RSS:.2f}/{n_reg - k_reg} = {sigma2_hat:.4f}")
print(f"\n  Var(β̂) = σ̂²·(X'X)⁻¹ =")
print(f"    {var_beta}")
print(f"\n  SE(α̂) = {se_classic[0]:.4f},   SE(β̂) = {se_classic[1]:.4f}")
print(f"  t(α̂)  = {t_stats[0]:.3f}  (p = {p_vals[0]:.4f})")
print(f"  t(β̂)  = {t_stats[1]:.3f}  (p = {p_vals[1]:.4f})")

# Cross-check with statsmodels
model_check = sm.OLS(y_reg, X_mat).fit()
print(f"\n  statsmodels match — coefficients: {np.allclose(beta_hat, model_check.params)}")
print(f"  statsmodels match — std errors:   {np.allclose(se_classic, model_check.bse)}")
MATRIX OLS — NUMERICAL VERIFICATION
=======================================================
β̂ = (X'X)⁻¹X'y = [-0.2, 1.4]
α̂ = -0.2, β̂ = 1.4
X'ε̂ = [-4.44089210e-16 1.33226763e-15] (orthogonality check — should be ≈ 0)
Σε̂ = -0.0000000000 (residuals sum to zero ✓)
RSS = 3.20
σ̂² = RSS/(n−k) = 3.20/3 = 1.0667
Var(β̂) = σ̂²·(X'X)⁻¹ =
[[ 0.32 -0.10666667]
[-0.10666667 0.10666667]]
SE(α̂) = 0.5657, SE(β̂) = 0.3266
t(α̂) = -0.354 (p = 0.7471)
t(β̂) = 4.287 (p = 0.0233)
statsmodels match — coefficients: True
statsmodels match — std errors: True
Section 6: Nonparametric Robust Inference
6.1 Why Variance Estimation Is the Key Problem
In Section 4 we showed that the CLT justifies using normal p-values for hypothesis tests — provided we plug the right variance into the denominator of the t-statistic. In Section 3 we saw that for weakly dependent time series (the Mixing CLT, Section 3.5), the relevant variance is the long-run variance , not simply .
Here is the crux of the problem:
The naive sample variance converges to , not to . So if we use in the denominator, Slutsky’s theorem plugs in the wrong variance, and the resulting -statistic has incorrect size — typically too large, leading to false rejections.
The fix: Replace with a HAC (heteroscedasticity and autocorrelation consistent) estimator — specifically, the Newey-West estimator — which consistently estimates by including weighted sample autocovariances:
With this correction, Slutsky’s theorem gives us .
The punchline: A suitable CLT handles non-normality and dependence under its stated assumptions. A consistent covariance estimator supplies the denominator. Both parts, plus identification and exogeneity, are needed; robust covariance alone cannot make a misspecified regression valid.
6.2 What Does “Nonparametric” Mean in This Context?
In the classic OLS framework, we assume:
This is a parametric assumption — it specifies the exact distribution of the errors.
A nonparametric (or semiparametric) approach to inference relaxes this assumption. Instead of assuming errors are normal with constant variance, we say:
“We do not specify an exact error distribution, but require exogeneity, appropriate moments, weak dependence and a full-rank, stable design for asymptotic inference.”
Changing the covariance estimator leaves the OLS coefficients unchanged. Unbiasedness requires ; consistency needs valid moment conditions and an LLN. What changes is how we estimate the uncertainty — i.e., the standard errors.
6.3 Why Classic Standard Errors Can Fail
Recall the classic OLS covariance formula:
This assumes two things simultaneously:
Homoscedasticity: for all (constant variance)
No autocorrelation: for
If either assumption fails:
The coefficient estimates are still consistent (the CLT still applies to them)
But the standard errors are wrong — typically too small
Which makes t-statistics too large and p-values too small
Leading to false discoveries (rejecting when you shouldn’t)
6.3½ Seeing the Problem: A Quick Simulation
Before deriving the fix, let’s see the problem in action. The cell below generates data with heteroscedastic errors and checks whether classic 95% confidence intervals actually achieve 95% coverage. If classic SEs are too small, the intervals will be too narrow — and coverage will fall below 95%.
# ============================================================================
# Quick demo: classic SEs understate uncertainty under heteroscedasticity
# ============================================================================

np.random.seed(99)
n_motiv = 100
num_sims = 2000
beta_true_m = 1.0
cover_classic = 0
cover_hc1 = 0

for _ in range(num_sims):
    x_m = np.random.randn(n_motiv)
    # Heteroscedastic errors: variance proportional to x²
    eps_m = np.random.randn(n_motiv) * (0.5 + 2.0 * np.abs(x_m))
    y_m = beta_true_m * x_m + eps_m

    X_m = sm.add_constant(x_m)
    res_m = sm.OLS(y_m, X_m).fit()
    res_hc1 = res_m.get_robustcov_results(cov_type='HC1', use_t=False)

    # Classic 95% CI for beta
    ci_c = res_m.conf_int(alpha=0.05)[1]
    if ci_c[0] <= beta_true_m <= ci_c[1]:
        cover_classic += 1

    # HC1 95% CI for beta
    ci_h = res_hc1.conf_int(alpha=0.05)[1]
    if ci_h[0] <= beta_true_m <= ci_h[1]:
        cover_hc1 += 1

print("COVERAGE OF 95% CONFIDENCE INTERVALS (2000 simulations)")
print("=" * 55)
print(f"  Data:  n={n_motiv}, heteroscedastic errors (σᵢ ∝ |xᵢ|)")
print(f"  True β = {beta_true_m}")
print(f"")
print(f"  Classic OLS coverage: {cover_classic/num_sims*100:.1f}%  (should be 95%)")
print(f"  HC1 robust coverage:  {cover_hc1/num_sims*100:.1f}%  (should be 95%)")
print(f"")
if cover_classic / num_sims < 0.93:
    print(f"  ⚠ Classic SEs give UNDER-COVERAGE: the intervals are too narrow.")
    print(f"    You'd think you have 95% confidence, but you really have ~{cover_classic/num_sims*100:.0f}%.")
print("  Compare HC1 coverage with 95%; residual finite-sample error remains possible.")
print(f"\nThis motivates the sandwich formula derived next.")
COVERAGE OF 95% CONFIDENCE INTERVALS (2000 simulations)
=======================================================
Data: n=100, heteroscedastic errors (σᵢ ∝ |xᵢ|)
True β = 1.0
Classic OLS coverage: 78.3% (should be 95%)
HC1 robust coverage: 92.3% (should be 95%)
⚠ Classic SEs give UNDER-COVERAGE: the intervals are too narrow.
You'd think you have 95% confidence, but you really have ~78%.
Compare HC1 coverage with 95%; residual finite-sample error remains possible.
This motivates the sandwich formula derived next.
6.4 The True Variance Formula
Without the homoscedasticity/independence assumptions, the exact variance of the OLS estimator is:
where is the true covariance matrix of the error vector.
This is called the sandwich formula — and the name is worth remembering, because it encodes the entire logic of robust inference:
The two outer copies of are the bread. They come from the OLS mechanics and are the same whether you use classic or robust standard errors.
The inner term is the meat. It captures what the errors actually look like — their variances, their correlations across time, their entire dependence structure. Classic OLS replaces the meat with the crude approximation (assuming all errors are identical and independent). The sandwich estimator instead lets the residuals speak for themselves.
Every robust SE method you encounter — HC0, HC1, HC3, Newey-West — is just a different recipe for the meat. The bread never changes.
Under homoscedasticity and zero conditional cross-observation covariances, , and the meat simplifies to , recovering the classic formula. The sandwich formula is the general case; classic OLS is a special case.
6.5 HC0 (White’s Heteroscedasticity-Consistent Estimator)
White (1980) proposed replacing the unknown with the diagonal matrix of squared residuals:
The HC0 estimator is:
where is the -th row of (as a column vector).
Key idea: Instead of assuming all errors have the same variance, let each residual “speak for itself.” The squared residual is a (noisy) estimate of .
6.6 Hand Calculation: HC0 for Our 5-Observation Regression
Let’s compute the HC0 “meat” matrix:
Each and was computed in Section 5.9:
| 1 | 0.16 | |
| 2 | 0.16 | |
| 3 | 0.00 | |
| 4 | 1.44 | |
| 5 | 1.44 |
Computing element-by-element (top-left as example):
You can verify the full meat matrix is:
Then the HC0 variance:
6.7 Finite-Sample Corrections: HC1, HC2, HC3
HC0 is consistent (correct as ) but tends to underestimate the variance in finite samples. Several corrections exist:
HC1 multiplies HC0 by the factor (a degrees-of-freedom correction analogous to Bessel’s correction for the variance). This is the most common variant in applied work: .
HC2 rescales each squared residual by , where is the -th diagonal element of the hat matrix .
HC3 uses , providing an even more conservative correction. HC3 is popular in econometrics because it approximates a jackknife estimator.
For our 5-observation example with : , so HC1 standard errors are about 29% larger than HC0 — a non-negligible correction for small samples. In the Fama-French tutorials (where ), the difference between HC0 and HC1 is only about 1.2%, so the choice matters much less.
All of these HC variants handle heteroscedasticity but not autocorrelation. For time-series data, we need Newey-West — the subject of the next section.
# ============================================================================
# Hand-checkable HC0 sandwich estimator
# Uses: X_mat, resid, n_reg, k_reg, XtX_inv, se_classic, model_check
#       from Section 5 matrix OLS cell above
# ============================================================================

print("HC0 (WHITE) SANDWICH ESTIMATOR — HAND VERIFICATION")
print("=" * 60)

# Meat matrix: sum of e_i^2 * x_i x_i'
meat_HC0 = np.zeros((k_reg, k_reg))
for i in range(n_reg):
    xi = X_mat[i, :].reshape(-1, 1)  # column vector
    meat_HC0 += resid[i]**2 * (xi @ xi.T)

print(f"Squared residuals: {resid**2}")
print(f"\nMeat matrix M = Σ ε̂²ᵢ xᵢxᵢ' =\n{meat_HC0}")

# Sandwich
var_HC0 = XtX_inv @ meat_HC0 @ XtX_inv
se_HC0 = np.sqrt(np.diag(var_HC0))

print(f"\nHC0 Var(β̂) = (X'X)⁻¹ M (X'X)⁻¹ =\n{var_HC0}")
print(f"\nComparison of standard errors:")
print(f"  {'':15s}  {'Classic':>10s}  {'HC0':>10s}  {'% Change':>10s}")
print(f"  {'SE(α̂)':15s}  {se_classic[0]:10.4f}  {se_HC0[0]:10.4f}  {(se_HC0[0]-se_classic[0])/se_classic[0]*100:+10.1f}%")
print(f"  {'SE(β̂)':15s}  {se_classic[1]:10.4f}  {se_HC0[1]:10.4f}  {(se_HC0[1]-se_classic[1])/se_classic[1]*100:+10.1f}%")

# Verify with statsmodels HC0
results_hc0 = model_check.get_robustcov_results(cov_type='HC0')
print(f"\nStatsmodels HC0 SEs: {results_hc0.bse}")
print(f"Our HC0 SEs:         {se_HC0}")
print(f"Match: {np.allclose(se_HC0, results_hc0.bse)}")
HC0 (WHITE) SANDWICH ESTIMATOR — HAND VERIFICATION
============================================================
Squared residuals: [1.60000000e-01 1.60000000e-01 1.97215226e-31 1.44000000e+00
1.44000000e+00]
Meat matrix M = Σ ε̂²ᵢ xᵢxᵢ' =
[[3.2 1.6 ]
[1.6 2.24]]
HC0 Var(β̂) = (X'X)⁻¹ M (X'X)⁻¹ =
[[ 0.2144 -0.0544]
[-0.0544 0.0224]]
Comparison of standard errors:
Classic HC0 % Change
SE(α̂) 0.5657 0.4630 -18.1%
SE(β̂) 0.3266 0.1497 -54.2%
Statsmodels HC0 SEs: [0.46303348 0.1496663 ]
Our HC0 SEs: [0.46303348 0.1496663 ]
Match: True
# ============================================================================
# HC0 / HC1 / HC2 / HC3 comparison on our 5-observation regression
# ============================================================================

# Hat matrix: H = X (X'X)^{-1} X'
H_mat = X_mat @ XtX_inv @ X_mat.T
h_ii = np.diag(H_mat)  # leverage values

print("HC VARIANT COMPARISON (n=5, k=2)")
print("=" * 65)
print(f"Leverage values h_ii: {h_ii}")
print(f"Residuals:            {resid}")
print()

# HC0: standard White
var_hc0 = XtX_inv @ meat_HC0 @ XtX_inv

# HC1: degrees-of-freedom correction
dof_factor = n_reg / (n_reg - k_reg)
var_hc1 = dof_factor * var_hc0

# HC2: rescale by 1/(1 - h_ii)
meat_hc2 = np.zeros((k_reg, k_reg))
for i in range(n_reg):
    xi = X_mat[i, :].reshape(-1, 1)
    meat_hc2 += (resid[i]**2 / (1 - h_ii[i])) * (xi @ xi.T)
var_hc2 = XtX_inv @ meat_hc2 @ XtX_inv

# HC3: rescale by 1/(1 - h_ii)^2
meat_hc3 = np.zeros((k_reg, k_reg))
for i in range(n_reg):
    xi = X_mat[i, :].reshape(-1, 1)
    meat_hc3 += (resid[i]**2 / (1 - h_ii[i])**2) * (xi @ xi.T)
var_hc3 = XtX_inv @ meat_hc3 @ XtX_inv

# Standard errors
se_hc0 = np.sqrt(np.diag(var_hc0))
se_hc1 = np.sqrt(np.diag(var_hc1))
se_hc2 = np.sqrt(np.diag(var_hc2))
se_hc3 = np.sqrt(np.diag(var_hc3))

print(f"{'':15s}  {'Classic':>9s}  {'HC0':>9s}  {'HC1':>9s}  {'HC2':>9s}  {'HC3':>9s}")
print("-" * 65)
for j, name in enumerate(['SE(α̂)', 'SE(β̂)']):
    print(f"  {name:13s}  {se_classic[j]:9.4f}  {se_hc0[j]:9.4f}  "
          f"{se_hc1[j]:9.4f}  {se_hc2[j]:9.4f}  {se_hc3[j]:9.4f}")

print(f"\nDOF factor n/(n-k) = {n_reg}/{n_reg - k_reg} = {dof_factor:.3f}")
print(f"HC1 = HC0 × √({dof_factor:.3f}) in SE terms")
print(f"\nWith n=5, HC3 is notably larger than HC0 (conservative small-sample correction).")
print(f"With larger samples differences often shrink, but high leverage can keep them material.")

# Verify against statsmodels
for hc_type in ['HC0', 'HC1', 'HC2', 'HC3']:
    res_check = model_check.get_robustcov_results(cov_type=hc_type)
    our_se = {'HC0': se_hc0, 'HC1': se_hc1, 'HC2': se_hc2, 'HC3': se_hc3}[hc_type]
    match = np.allclose(our_se, res_check.bse)
    print(f"  {hc_type} matches statsmodels: {match}")
HC VARIANT COMPARISON (n=5, k=2)
=================================================================
Leverage values h_ii: [0.3 0.6 0.6 0.3 0.2]
Residuals: [ 4.0000000e-01 -4.0000000e-01 4.4408921e-16 1.2000000e+00
-1.2000000e+00]
Classic HC0 HC1 HC2 HC3
-----------------------------------------------------------------
SE(α̂) 0.5657 0.4630 0.5978 0.5687 0.7196
SE(β̂) 0.3266 0.1497 0.1932 0.1971 0.2695
DOF factor n/(n-k) = 5/3 = 1.667
HC1 = HC0 × √(1.667) in SE terms
With n=5, HC3 is notably larger than HC0 (conservative small-sample correction).
With larger samples differences often shrink, but high leverage can keep them material.
HC0 matches statsmodels: True
HC1 matches statsmodels: True
HC2 matches statsmodels: True
HC3 matches statsmodels: True
Section 7: Newey-West HAC Standard Errors — Complete Derivation
7.1 The Problem Newey-West Solves
The HC0 estimator handles heteroscedasticity (non-constant error variance) but still assumes no autocorrelation — that is, for .
In financial time-series, this assumption often fails. Monthly returns can be correlated across time due to:
Stale prices and illiquidity
Overlapping data (e.g., overlapping holding periods)
Slow information diffusion
Volatility clustering concerns squared returns; it need not create serial correlation in returns or regression scores. HC can suffice for serially uncorrelated scores.
Newey and West (1987) proposed an estimator that is consistent in the presence of both heteroscedasticity and autocorrelation — hence HAC (Heteroscedasticity and Autocorrelation Consistent).
7.2 The Newey-West Meat
The Newey-West estimator modifies the “meat” of the sandwich to include cross-products of residuals at different lags:
where:
= maximum lag (the “bandwidth” or “truncation lag”)
are Bartlett kernel weights (linearly declining from 1 to 0)
The full Newey-West variance is then:
7.3 Understanding the Bartlett Weights
The Bartlett weights have two important properties:
Monotone decline: Nearby lags get more weight than distant ones, reflecting the empirical fact that autocorrelation typically decays with distance.
Guaranteed positive semi-definiteness: The resulting variance estimate is always a valid (non-negative) covariance matrix. This is not guaranteed by all kernel choices.
For example, with :
| Lag | Weight |
|---|---|
| 0 | 1.000 (this is the HC0 part) |
| 1 | 0.750 |
| 2 | 0.500 |
| 3 | 0.250 |
7.4 Lag Selection
The choice of involves a bias-variance tradeoff:
Too small : May not capture all autocorrelation → biased (direction depends on omitted covariance signs)
Too large : Includes noisy estimates of near-zero autocorrelations → inefficient
A common sample-size bandwidth heuristic is:
For typical Fama-French samples:
:
:
:
:
7.5 Hand Calculation: Newey-West with 
Let us compute the Newey-West estimator for our 5-observation regression using (one lag of autocorrelation). This keeps the arithmetic manageable.
Step 1: The lag-0 (HC0) meat — already computed:
Step 2: The lag-1 cross-term
We need for :
| Product | |||
|---|---|---|---|
| 2 | −0.4 | 0.4 | −0.16 |
| 3 | 0.0 | −0.4 | 0.00 |
| 4 | 1.2 | 0.0 | 0.00 |
| 5 | −1.2 | 1.2 | −1.44 |
Now compute the sum :
Each term is a product of a scalar () times a symmetric matrix. Note that for and , the product is zero (because and ), so only and contribute.
:
Contribution:
:
Contribution:
Lag-1 sum (before weighting):
Step 3: Apply Bartlett weight with :
Step 4: Assemble the Newey-West meat:
Step 5: Compute the Newey-West variance
We already know .
This is not the data-dependent plug-in bandwidth of Andrews (1991). See statsmodels HAC documentation. The hand calculation below uses the uncorrected covariance; subsequent applied regressions explicitly use the correction and normal reference p-values.
# ============================================================================
# Hand-checkable Newey-West with L = 1
# Uses: meat_HC0, X_mat, resid, n_reg, k_reg, XtX_inv, se_classic, se_HC0,
#       beta_hat from Sections 5–6 cells above
# ============================================================================

print("NEWEY-WEST HAC ESTIMATOR (L = 1) — HAND VERIFICATION")
print("=" * 60)

L_nw = 1  # One lag

# Step 1: HC0 meat (lag 0) — already computed
print("Step 1: HC0 meat (lag 0) — from Section 6")
print(f"  M₀ =\n{meat_HC0}\n")

# Step 2: Lag-1 cross-terms
print("Step 2: Lag-1 cross-products")
G1 = np.zeros((k_reg, k_reg))
print(f"  Residuals: {resid}")
print(f"  Lag-1 products ε̂ᵢε̂ᵢ₋₁:")
for i in range(1, n_reg):
    cross = resid[i] * resid[i - 1]
    xi = X_mat[i, :].reshape(-1, 1)
    xi_lag = X_mat[i - 1, :].reshape(-1, 1)
    outer = xi @ xi_lag.T + xi_lag @ xi.T
    contribution = cross * outer
    G1 += contribution
    print(f"    i={i+1}: ε̂_{i+1}·ε̂_{i} = {resid[i]:.1f} × {resid[i-1]:.1f} = {cross:.2f}")

print(f"\n  G₁ (lag-1 sum, unweighted) =\n{G1}")

# Step 3: Bartlett weight
w1 = 1 - 1 / (L_nw + 1)
print(f"\nStep 3: Bartlett weight w₁ = 1 - 1/{L_nw + 1} = {w1}")

# Step 4: Newey-West meat
meat_NW = meat_HC0 + w1 * G1
print(f"\nStep 4: M_NW = M₀ + w₁·G₁ =\n{meat_NW}")

# Step 5: Newey-West variance
var_NW = XtX_inv @ meat_NW @ XtX_inv
se_NW = np.sqrt(np.diag(var_NW))
print(f"\nStep 5: Var_NW(β̂) = (X'X)⁻¹ M_NW (X'X)⁻¹ =\n{var_NW}")

# Comparison table
print(f"\n{'='*60}")
print(f"STANDARD ERROR COMPARISON")
print(f"{'='*60}")
print(f"  {'':15s}  {'Classic':>10s}  {'HC0':>10s}  {'NW(L=1)':>10s}")
print(f"  {'SE(α̂)':15s}  {se_classic[0]:10.4f}  {se_HC0[0]:10.4f}  {se_NW[0]:10.4f}")
print(f"  {'SE(β̂)':15s}  {se_classic[1]:10.4f}  {se_HC0[1]:10.4f}  {se_NW[1]:10.4f}")

# t-statistics and p-values under each method
print(f"\n  {'':15s}  {'Classic':>10s}  {'HC0':>10s}  {'NW(L=1)':>10s}")
for idx, name in enumerate(['t(α̂)', 't(β̂)']):
    t_c = beta_hat[idx] / se_classic[idx]
    t_h = beta_hat[idx] / se_HC0[idx]
    t_n = beta_hat[idx] / se_NW[idx]
    print(f"  {name:15s}  {t_c:10.3f}  {t_h:10.3f}  {t_n:10.3f}")

# Compare the exact hand calculation with the uncorrected library estimator.
nw_check = model_check.get_robustcov_results(cov_type='HAC', maxlags=1,
                                            use_correction=False, use_t=False)
np.testing.assert_allclose(var_NW, nw_check.cov_params(), atol=1e-12)
print("Hand-computed HAC covariance matches statsmodels (uncorrected).")
print("Five observations illustrate arithmetic, not reliable asymptotic inference.")
NEWEY-WEST HAC ESTIMATOR (L = 1) — HAND VERIFICATION
============================================================
Step 1: HC0 meat (lag 0) — from Section 6
M₀ =
[[3.2 1.6 ]
[1.6 2.24]]
Step 2: Lag-1 cross-products
Residuals: [ 4.0000000e-01 -4.0000000e-01 4.4408921e-16 1.2000000e+00
-1.2000000e+00]
Lag-1 products ε̂ᵢε̂ᵢ₋₁:
i=2: ε̂_2·ε̂_1 = -0.4 × 0.4 = -0.16
i=3: ε̂_3·ε̂_2 = 0.0 × -0.4 = -0.00
i=4: ε̂_4·ε̂_3 = 1.2 × 0.0 = 0.00
i=5: ε̂_5·ε̂_4 = -1.2 × 1.2 = -1.44
G₁ (lag-1 sum, unweighted) =
[[-3.2 -1.6 ]
[-1.6 0.64]]
Step 3: Bartlett weight w₁ = 1 - 1/2 = 0.5
Step 4: M_NW = M₀ + w₁·G₁ =
[[1.6 0.8 ]
[0.8 2.56]]
Step 5: Var_NW(β̂) = (X'X)⁻¹ M_NW (X'X)⁻¹ =
[[ 0.1216 -0.0416]
[-0.0416 0.0256]]
============================================================
STANDARD ERROR COMPARISON
============================================================
Classic HC0 NW(L=1)
SE(α̂) 0.5657 0.4630 0.3487
SE(β̂) 0.3266 0.1497 0.1600
Classic HC0 NW(L=1)
t(α̂) -0.354 -0.432 -0.574
t(β̂) 4.287 9.354 8.750
Hand-computed HAC covariance matches statsmodels (uncorrected).
Five observations illustrate arithmetic, not reliable asymptotic inference.
Section 8: Newey-West on a Realistic Sample — CLT in Action
The 5-observation example above showed the mechanics. But with , the CLT has barely begun to work. Let’s now see Newey-West on a realistic sample where the asymptotic theory actually applies.
We’ll generate 200 observations from a deliberately non-normal regression with:
Heteroscedastic errors (variance depends on )
Autocorrelated errors (AR(1) structure)
Fat-tailed errors (t-distributed innovations)
This scenario represents a stylized version of what real financial data looks like. The simulation lets us compare classic and HAC uncertainty estimates. A single realization cannot establish coverage accuracy.
# ============================================================================
# Newey-West on a realistic simulated dataset
# ============================================================================

np.random.seed(42)
n_sim = 200

# Generate regressor
x_sim = np.random.randn(n_sim) * 0.04  # Scale like monthly factor returns

# Generate errors with heteroscedasticity + autocorrelation + fat tails
innovations = stats.t.rvs(df=5, size=n_sim)  # fat-tailed (t with 5 df)
errors = np.zeros(n_sim)
rho = 0.3  # AR(1) coefficient
for t in range(n_sim):
    if t == 0:
        errors[t] = innovations[t]
    else:
        errors[t] = rho * errors[t-1] + innovations[t]
# Add heteroscedasticity: variance proportional to |x|
errors = errors * (0.01 + 0.5 * np.abs(x_sim))

# True model: y = 0.001 + 1.0 * x + error
alpha_true, beta_true = 0.001, 1.0
y_sim = alpha_true + beta_true * x_sim + errors

# Fit OLS
X_sim = sm.add_constant(x_sim)
model_sim = sm.OLS(y_sim, X_sim).fit()

# Compute Newey-West with sample-size bandwidth heuristic
lag_sim = int(np.floor(4 * (n_sim / 100) ** (2/9)))
model_nw = model_sim.get_robustcov_results(cov_type='HAC', maxlags=lag_sim, use_correction=True, use_t=False)

print("REALISTIC SIMULATION: n=200, heteroscedastic + autocorrelated + fat-tailed errors")
print("=" * 75)
print(f"True parameters: α = {alpha_true}, β = {beta_true}")
print(f"Newey-West lag length (sample-size bandwidth heuristic): L = {lag_sim}")

print(f"\n{'':15s}  {'Estimate':>10s}  {'Classic SE':>10s}  {'NW SE':>10s}  {'Classic t':>10s}  {'NW t':>10s}")
print("-" * 75)
for i, name in enumerate(['α (intercept)', 'β (slope)']):
    coef = model_sim.params[i]
    se_c = model_sim.bse[i]
    se_nw_val = model_nw.bse[i]
    t_c = model_sim.tvalues[i]
    t_nw = model_nw.tvalues[i]
    print(f"  {name:13s}  {coef:10.5f}  {se_c:10.5f}  {se_nw_val:10.5f}  {t_c:10.3f}  {t_nw:10.3f}")

print(f"\nEstimated uncertainty comparison:")
print(f"  SE(β) ratio (NW / Classic): {model_nw.bse[1] / model_sim.bse[1]:.2f}x")
print(f"\n  Classic p-value for β: {model_sim.pvalues[1]:.4f}")
print(f"  NW p-value for β:     {model_nw.pvalues[1]:.4f}")

# Visualize
fig, axes = plt.subplots(1, 3, figsize=(16, 4.5))

# Plot 1: Residuals vs fitted
axes[0].scatter(model_sim.fittedvalues, model_sim.resid, alpha=0.5, s=20)
axes[0].axhline(0, color='red', linewidth=1, linestyle='--')
axes[0].set_xlabel('Fitted values')
axes[0].set_ylabel('Residuals')
axes[0].set_title('Residuals vs Fitted\n(Heteroscedasticity visible)', fontweight='bold')
axes[0].grid(True, alpha=0.3)

# Plot 2: Autocorrelation of residuals
acf_vals = [pd.Series(model_sim.resid).autocorr(lag=l) for l in range(1, 11)]
axes[1].bar(range(1, 11), acf_vals, color='steelblue', alpha=0.7)
axes[1].axhline(1.96/np.sqrt(n_sim), color='red', linestyle='--', alpha=0.5, label='95% band')
axes[1].axhline(-1.96/np.sqrt(n_sim), color='red', linestyle='--', alpha=0.5)
axes[1].set_xlabel('Lag')
axes[1].set_ylabel('Autocorrelation')
axes[1].set_title('Residual Autocorrelation\n(Pointwise reference bands)', fontweight='bold')
axes[1].legend(fontsize=9)
axes[1].grid(True, alpha=0.3)

# Plot 3: Confidence intervals comparison
coef_val = model_sim.params[1]
ci_classic = model_sim.conf_int()[1]
ci_nw = [coef_val - 1.96 * model_nw.bse[1], coef_val + 1.96 * model_nw.bse[1]]
axes[2].barh(['NW HAC', 'Classic'],
             [ci_nw[1] - ci_nw[0], ci_classic[1] - ci_classic[0]],
             left=[ci_nw[0], ci_classic[0]], height=0.4, alpha=0.6,
             color=['darkred', 'steelblue'])
axes[2].axvline(beta_true, color='green', linewidth=2, linestyle='--', label=f'True β = {beta_true}')
axes[2].axvline(coef_val, color='black', linewidth=1.5, label=f'Estimate = {coef_val:.3f}')
axes[2].set_xlabel('β coefficient')
axes[2].set_title('95% Confidence Intervals\n(Classical t versus asymptotic HAC)', fontweight='bold')
axes[2].legend(fontsize=9)
axes[2].grid(True, alpha=0.3)

plt.tight_layout()
plt.show()

print("\nInterval widths depend on estimated score covariances and do not establish")
print("heteroscedasticity and autocorrelation that classic OLS ignores.")
REALISTIC SIMULATION: n=200, heteroscedastic + autocorrelated + fat-tailed errors
===========================================================================
True parameters: α = 0.001, β = 1.0
Newey-West lag length (sample-size bandwidth heuristic): L = 4
Estimate Classic SE NW SE Classic t NW t
---------------------------------------------------------------------------
α (intercept) -0.00451 0.00262 0.00320 -1.721 -1.407
β (slope) 0.94084 0.07045 0.11402 13.355 8.252
Estimated uncertainty comparison:
SE(β) ratio (NW / Classic): 1.62x
Classic p-value for β: 0.0000
NW p-value for β: 0.0000
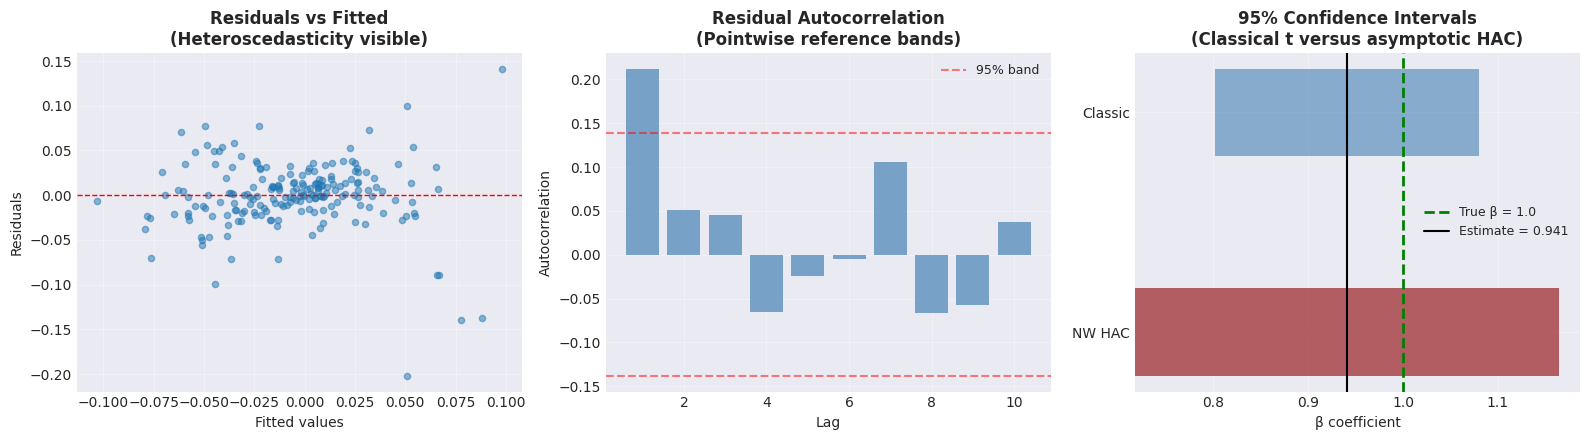
Interval widths depend on estimated score covariances and do not establish
heteroscedasticity and autocorrelation that classic OLS ignores.
Section 9: Putting It All Together — From CLT to Newey-West to p-Values
9.1 The Grand Argument
We can now state the complete logical chain that justifies using the standard normal distribution for p-values in Fama-French regressions, even though the data is non-normal, heteroscedastic, and autocorrelated:
Step 1 (OLS coefficients are weighted averages). The OLS estimator is a linear function of . Since each , the estimator is ultimately a weighted average of the error terms .
Step 2 (CLT applies to weighted averages). A CLT for the score process, together with exogeneity and convergence of the regressor second moments, guarantees that is asymptotically normal as , provided the errors are not too dependent or too heavy-tailed:
This holds regardless of the distribution of : no normality needed.
Step 3 (Newey-West consistently estimates the variance). Even though depends on the unknown error structure (heteroscedasticity + autocorrelation), the Newey-West estimator converges to the true variance as .
Step 4 (Slutsky’s theorem combines Steps 2–3). The t-statistic
under . Therefore, p-values can be computed from the standard normal distribution.
9.2 What This Does NOT Require
❌ Normally distributed errors
❌ Constant error variance (homoscedasticity)
❌ Independent errors (no autocorrelation)
❌ Any specific parametric distribution for the errors
9.3 What This DOES Require
✅ Enough data for the approximation to be useful; there is no universal minimum
✅ Exogeneity/orthogonality, a nonsingular regressor second-moment matrix and sufficiently strong moment bounds on
✅ Errors that are “not too dependent” (appropriate mixing rates and moment conditions; a small sample ACF does not prove them)
✅ A consistent lag length (grows with but slower than )
9.4 The Classification: Is This “Nonparametric”?
Technically, the approach is semiparametric:
| Aspect | Parametric or not? |
|---|---|
| Model for the mean ($E[y | x] = \alpha + \beta x$) |
| Distribution of errors | Nonparametric — no distributional assumption |
| Variance estimation | Nonparametric — Newey-West uses the data directly (squared residuals and cross-products), not any parametric formula |
| Inference (p-values) | Based on asymptotic normality via CLT, not on any parametric distributional assumption |
In the finance literature, this is often loosely called “nonparametric” or “robust” inference. The key point: the limiting reference distribution does not require a specified error density, only on the CLT.
# ============================================================================
# Monte Carlo: Verify that Newey-West p-values are correctly calibrated
# under H₀, even with non-normal, heteroscedastic, autocorrelated errors
# ============================================================================
# If the theory is correct:
#   - Under H₀: β = 0, we should reject at 5% level exactly 5% of the time
#   - Classic OLS will over-reject (too many false positives)

np.random.seed(0)
num_mc = 2000
n_mc = 150  # Typical Fama-French sample size
reject_classic = 0
reject_nw = 0

for sim in range(num_mc):
    # Generate x (factor)
    x_mc = np.random.randn(n_mc) * 0.04

    # Generate non-normal, heteroscedastic, AR(1) errors
    innov = stats.t.rvs(df=5, size=n_mc)
    eps = np.zeros(n_mc)
    for t in range(n_mc):
        eps[t] = 0.3 * eps[t-1] + innov[t] if t > 0 else innov[t]
    eps = eps * (0.01 + 0.4 * np.abs(x_mc))  # heteroscedasticity

    # True β = 0 (null hypothesis is true)
    y_mc = 0.0 + 0.0 * x_mc + eps

    X_mc = sm.add_constant(x_mc)
    res_mc = sm.OLS(y_mc, X_mc).fit()
    lag_mc = int(np.floor(4 * (n_mc / 100) ** (2/9)))
    res_nw_mc = res_mc.get_robustcov_results(cov_type='HAC', maxlags=lag_mc, use_correction=True, use_t=False)

    # Test β = 0 at 5% level (two-sided)
    if res_mc.pvalues[1] < 0.05:
        reject_classic += 1
    if res_nw_mc.pvalues[1] < 0.05:
        reject_nw += 1

print("MONTE CARLO: FALSE REJECTION RATES UNDER H₀ (β = 0)")
print("=" * 60)
print(f"Number of simulations:     {num_mc}")
print(f"Sample size per sim:       {n_mc}")
print(f"Errors: t(5) innovations, AR(1) ρ=0.3, heteroscedastic")
print(f"\nNominal size (α):          5.0%")
print(f"Classic OLS rejection rate: {reject_classic/num_mc*100:.1f}%")
print(f"Newey-West rejection rate:  {reject_nw/num_mc*100:.1f}%")
print(f"\nINTERPRETATION:")
if reject_classic / num_mc > 0.07:
    print(f"  Classic OLS OVER-REJECTS: {reject_classic/num_mc*100:.1f}% >> 5%")
    print(f"    → Using classic SEs, you'd get too many false positives!")
for method, count in [('Classic', reject_classic), ('HAC', reject_nw)]:
    rate = count / num_mc
    mc_se = np.sqrt(rate * (1 - rate) / num_mc)
    print(f"{method}: {rate:.2%}; Monte Carlo SE {mc_se:.2%}")
print("Compare both rates with 5%; HAC need not achieve nominal size at n=150.")

# ── Visualize the result: rejection-rate bar chart ──
rate_classic = reject_classic / num_mc * 100
rate_nw = reject_nw / num_mc * 100

fig, ax = plt.subplots(figsize=(7, 4.5))
bars = ax.bar(['Classic OLS', 'Newey-West HAC'], [rate_classic, rate_nw],
              color=['#d9534f', '#5cb85c'], width=0.5, edgecolor='black', linewidth=0.8)
ax.axhline(5, color='black', linestyle='--', linewidth=1.5, label='Nominal 5 % level')
ax.set_ylabel('Rejection rate (%)', fontsize=12)
ax.set_title('Monte Carlo Rejection Rates Under $H_0$\n'
             f'({num_mc} simulations, n = {n_mc}, AR(1) ρ = 0.3, heteroscedastic t(5) errors)',
             fontweight='bold', fontsize=11)
ax.set_ylim(0, max(rate_classic, rate_nw) * 1.35)

# Annotate bars
for bar, rate in zip(bars, [rate_classic, rate_nw]):
    ax.text(bar.get_x() + bar.get_width() / 2, bar.get_height() + 0.4,
            f'{rate:.1f} %', ha='center', va='bottom', fontweight='bold', fontsize=12)

ax.legend(fontsize=10)
ax.grid(True, alpha=0.3, axis='y')
plt.tight_layout()
plt.show()
MONTE CARLO: FALSE REJECTION RATES UNDER H₀ (β = 0)
============================================================
Number of simulations:     2000
Sample size per sim:       150
Errors: t(5) innovations, AR(1) ρ=0.3, heteroscedastic

Nominal size (α):          5.0%
Classic OLS rejection rate: 18.4%
Newey-West rejection rate:  7.4%

INTERPRETATION:
  Classic OLS OVER-REJECTS: 18.4% >> 5%
    → Using classic SEs, you'd get too many false positives!
Classic: 18.35%; Monte Carlo SE 0.87%
HAC: 7.40%; Monte Carlo SE 0.59%
Compare both rates with 5%; HAC need not achieve nominal size at n=150.
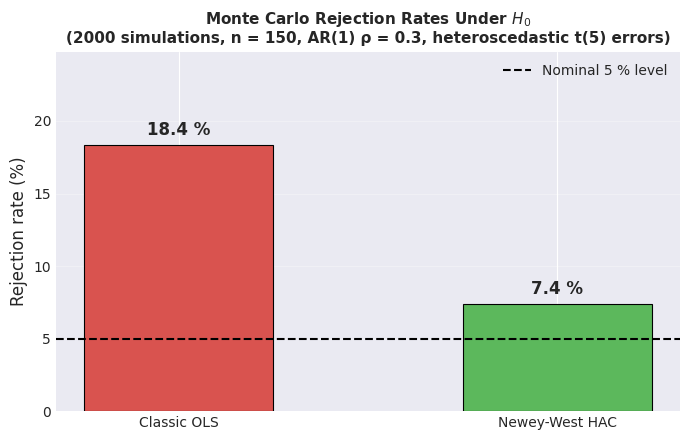
Section 10: Summary and Connection to the Fama-French Tutorials
10.1 What We’ve Shown
| Section | Key Result |
|---|---|
| 1. Descriptive Stats | Mean, variance, covariance computed by hand on 5 data points |
| 2. Population vs. Sample | Standard error of the mean = measures estimation uncertainty |
| 3. CLT | Sample means are approximately normal for large , under the relevant finite-moment and independence or dependence conditions |
| 4. Hypothesis Testing & CLT | t-statistics, p-values, confidence intervals, and why the normal approximation works |
| 5. Linear Regression & OLS | Scalar and matrix derivations, residuals, and classic standard errors on a 5-observation regression |
| 6. Nonparametric Inference | The sandwich formula: HC0 replaces scalar with observation-specific |
| 7. Newey-West | Extends HC0 by adding Bartlett-weighted cross-lag terms — handles autocorrelation too |
| 8. Realistic Simulation | HAC changes covariance estimates; the direction and finite-sample accuracy depend on the data |
| 9. Monte Carlo | Classic OLS over-rejects under ; HAC reduces distortion in this experiment but can still over-reject |
10.2 How This Connects to the Fama-French Notebooks
In the 3-Factor Tutorial:
Section 9 uses Newey-West standard errors for the Fama-French regression — now you understand exactly what that estimator computes and why it works.
Section 10 interprets t-statistics and p-values — now you know these are justified by the CLT, not by assuming normally distributed errors.
The sample-size bandwidth heuristic is the same practical heuristic used here.
In the Advanced Tutorial:
Full-sample inference uses HAC; rolling windows show OLS point estimates only.
The
run_ff_regression()helper function computes the Newey-West estimator automatically.The Monte Carlo experiment illustrates both the usefulness and the finite-sample limits of HAC inference. Non-normality alone does not invalidate it, but heavy tails and dependence still require appropriate moment and stability assumptions.
10.3 Quick Reference
When to Use What:
| Situation | Standard Errors | Why |
|---|---|---|
| Cross-sectional data, homoscedastic | Classic OLS | All assumptions hold |
| Cross-sectional, possible heteroscedasticity | HC0/HC1/HC3 | Sandwich estimator handles non-constant variance |
| Time-series data (financial returns) | Newey-West | Handles both heteroscedasticity and autocorrelation |
| Stable, sufficiently informative samples with valid moment/dependence assumptions | Asymptotic normal inference | Check sensitivity; sample size alone is not enough |
The Newey-West Recipe:
Fit OLS:
Compute residuals:
Choose lag
Compute the meat:
Sandwich:
Standard errors:
t-statistics: under
p-values: where is the standard normal CDF
10.4 Next Steps
Continue to Time Series Foundations, where we examine the ordering, persistence and volatility of financial observations. That chapter prepares us to apply regression inference to factor returns in Chapter 3.
Exercises
Test your understanding of the statistical foundations developed in this notebook.
Exercise 1: Hand Computation (Pencil & Paper)
Consider the dataset and .
Compute the sample mean, variance, and standard deviation of and .
Compute and by hand.
Set up the design matrix (with a constant column) and compute using the normal equations. Verify your answer with numpy.
Exercise 2: CLT in Action (Hands-On)
The CLT was demonstrated in Section 3.7 using an Exponential(1) distribution. Repeat the experiment with a qualitatively different non-normal distribution:
Draw samples of size from a Beta(0.5, 0.5) distribution (use
np.random.beta(0.5, 0.5, size=n)). This distribution is bimodal — most of the mass is near 0 and 1.Compute 5 000 sample means for each and plot the histograms.
At what sample size does the distribution of start looking approximately normal? Is this faster or slower than for Exponential(1)?
Why might a bimodal distribution converge faster than a heavily skewed one?
# Starter code:
from scipy import stats
n_sims = 5000
mu_beta = 0.5  # E[Beta(0.5, 0.5)] = a/(a+b) = 0.5
var_beta = 0.5 * 0.5 / (1.0 * 2.0) # a*b / ((a+b)^2 * (a+b+1)) = 0.125
for n in [5, 30, 100]:
    means = np.array([np.random.beta(0.5, 0.5, size=n).mean() for _ in range(n_sims)])
    z = (means - mu_beta) / np.sqrt(var_beta / n)
    # ... plot histogram of z and overlay N(0, 1) density
Exercise 3: Sandwich Estimator Comparison (Hands-On)
Using the 5-observation dataset from Section 5:
Perturb the observed outcomes by multiplying by (i.e., inflate the last two observations). Refit by OLS.
Compute the classic SE, HC0 SE, and Newey-West SE for .
Which estimator changes the most? Why?
Exercise 4: Monte Carlo — Varying the Autocorrelation (Challenge)
Extend the Monte Carlo simulation from Section 9:
Run the same experiment with autocorrelation coefficients .
For each , record the empirical rejection rate of the classic t-test and the Newey-West t-test at the 5% level.
Plot rejection rate vs. for both methods. At what does the classic test start seriously over-rejecting?
# Starter code:
rho_values = [0.0, 0.3, 0.6, 0.9]
for rho in rho_values:
    # Generate AR(1) errors: e_t = rho * e_{t-1} + v_t
    # Fit OLS, compute classic and NW t-stats, check rejection at 5%
    pass
Exercise 5: Why Does the Mixing CLT Matter? (Discussion)
Explain in your own words why the standard CLT (Lindeberg-Lévy) cannot be applied directly to time-series data.
What additional condition does the Mixing CLT require, and why might it be a reasonable working assumption for financial returns?
If the mixing condition were not satisfied (e.g., a random walk), what would go wrong with the Newey-West estimator?
For Exercise 3, changing outcomes changes both the fitted mean and residuals; this is a sensitivity calculation, not a controlled heteroscedastic data-generating process.