Question: Can market, size and value exposures explain why diversified equity funds behave differently?
We now combine the regression algebra of Chapter 1 with the time-series reasoning of Chapter 2. SPY, IWN and VTV provide contrasting US equity portfolios: a broad large-cap benchmark, small-cap value, and large-cap value. We construct the factor definitions, align returns, estimate coefficients by hand and in Python, and interpret uncertainty and residuals.
By the end you should be able to explain an estimated factor loading, distinguish alpha from realised outperformance, and say what a time-series regression does—and does not—establish about expected returns across assets.
Prerequisites: OLS, standard errors and the diagnostics in Chapter 2. The code uses complete monthly USD returns; sample dates are printed below and conventions are collected in Data and methods.
Previous: Financial time series · Next: Beyond three factors
Source
# Import Required Libraries
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
import seaborn as sns
from scipy import stats
import statsmodels.api as sm
from statsmodels.stats.stattools import jarque_bera
from statsmodels.stats.outliers_influence import variance_inflation_factor


# Set visualization style
try:
    plt.style.use('seaborn-v0_8-darkgrid')
except OSError:
    plt.style.use('default')
sns.set_palette("husl")
plt.rcParams["font.family"] = "DejaVu Sans"
np.random.seed(42)

print("All libraries imported successfully!")
from analysis_utils import AS_OF, END_EXCLUSIVE, load_french, load_prices, monthly_returns, coverage, fit_hac, mean_hac, nw_lags, load_beta_portfolios
All libraries imported successfully!
Section 1: Understanding the Fama-French 3-Factor Model
The Theory Behind Factor Models
The Fama-French 3-Factor Model is a framework developed by economists Eugene Fama and Kenneth French to explain stock returns. It extends the simpler Capital Asset Pricing Model (CAPM) by including two additional factors beyond just the market risk premium.
The model answers this question: Why do some stocks or portfolios outperform others?
The Mathematical Model
Where:
= Return of the asset (stock, ETF, or portfolio) at time
= Risk-free rate (typically the 1-month U.S. Treasury bill rate)
= Return of the overall market portfolio
= Alpha (Jensen’s alpha): The model-relative return not explained by the three factors. A positive alpha suggests the asset outperformed this specific model, but it can also reflect omitted risk factors, misspecification, or mispricing.
= Market Beta: Sensitivity to market risk. A beta of 1 means the asset moves with the market; >1 means stronger conditional market sensitivity; total volatility also depends on other exposures and residual risk.
= SMB Beta: Sensitivity to the small-minus-big factor, which captures the size effect (small firms tend to outperform large firms).
= HML Beta: Sensitivity to the high-minus-low factor, which captures the value effect (value stocks tend to outperform growth stocks).
= Small Minus Big factor: The return difference between portfolios of small-cap and large-cap stocks
= High Minus Low factor: The return difference between portfolios of high book-to-market (value) and low book-to-market (growth) stocks
= Error term (random, unexplained variation)
From CAPM to multiple sources of variation
CAPM links expected excess return to market beta. Fama and French’s empirical work adds size- and book-to-market-sorted portfolios to describe common variation and differences in average stock returns. A risk-based interpretation treats the additional factors as proxies for priced risks; behavioural and mispricing explanations offer alternatives. Regression fit alone does not choose between these mechanisms. Factor definitions and the original research.
Three questions that require different evidence
Exposure: in the time-series regression, does a fund covary with HML after controlling for the other factors? This concerns .
Premium: is the expected HML return positive? This concerns , estimated with considerable uncertainty from its historical mean.
Pricing: do exposures account for differences in expected returns across many assets? For traded factors, a zero-alpha pricing restriction is . Examining that restriction requires evidence across assets and joint pricing errors, not just one high .
In this chapter we estimate time-series exposures and model-relative intercepts. With an intercept, OLS gives the sample identity . That arithmetic is useful attribution, but it is not an independent test that the estimated factor means will persist. Cross-sectional pricing tests are a further step beyond the ETF regressions developed here.
What We’ll Do (Step-by-Step)
In this tutorial, we will:
Obtain historical data on ETF returns and the three factors
Run a regression to estimate , , , and
Test the statistical significance of these coefficients
Interpret what they tell us about the ETF’s factor exposures
Section 2: Load and Explore the Data
We’ll use real, actual market data from two sources:
Fama-French Factors: Downloaded from Kenneth French’s official data library at https://
mba .tuck .dartmouth .edu /pages /faculty /ken .french /data _library .html Market risk premium (Mkt-RF)
Size effect factor (SMB)
Value effect factor (HML)
Risk-free rate (RF)
ETF Returns: Downloaded from Yahoo Finance using real historical prices for three US-listed ETFs with very different expected factor exposures:
SPY (SPDR S&P 500 ETF Trust) — a broad US market ETF tracking the S&P 500. We expect and low SMB/HML loadings.
IWN (iShares Russell 2000 Value ETF) — targets US small-cap value stocks. We expect positive SMB and HML loadings.
VTV (Vanguard Value ETF) — targets US large-cap value stocks. We expect a positive HML loading but near-zero or negative SMB loading.
Why These Three ETFs?
These ETFs are chosen deliberately because they let us see the Fama-French factors at work:
A broad US market ETF should be mostly explained by the market factor alone, with .
A US small-cap value ETF should load positively on both SMB and HML, indicating exposure to the size and value spread portfolios; the signs do not establish a future premium.
A US large-cap value ETF lets us isolate the value effect—it should load on HML but not on SMB.
Why these US equity funds? Their underlying holdings are US equities and their measured returns are in USD, matching the universe and currency of the US factors. A US listing alone would not ensure that match: a US-listed international ETF requires an appropriate international comparison. Chapter 5 repeats this reasoning for developed and emerging markets.
How Are the Fama-French Factors Constructed?
This is an important question for understanding where empirical factor data comes from. The construction is actually quite clever:
Market Risk Premium (Mkt-RF)
Construct a value-weighted portfolio of all stocks in the market
Calculate its monthly return
Subtract the risk-free rate (typically 1-month Treasury bill yield)
Result: The excess return investors earn for taking market risk
SMB and HML use six intersecting portfolios, not independent single sorts. At each June formation date, split eligible stocks into Small/Big using the NYSE median market equity, and independently into Low/Neutral/High book-to-market using NYSE 30th/70th percentiles. Returns within each of the six intersections are value weighted.
The SMB of FF5 averages size spreads across book-to-market, profitability and investment sorts, so it differs from FF3 SMB. These long-short spreads are not automatically market neutral or costlessly investable: borrowing, financing, turnover and collateral matter. Size sorts use market equity; log size is often used in cross-sectional regressions but is not required for sorting.
See the official factor definitions and FF5 construction.
Sample and units. We start in January 2010 and stop at the latest complete month shared by prices and the released factors. The cells print the exact dates and counts. French percentages are converted to decimals once. ETF returns use consecutive adjusted month-end closing prices, so dividends and splits are accounted for by the vendor and return intervals match the calendar-month factors. We fetch a preceding price month and exclude incomplete months.
Data vintage. French’s US series switched from CRSP FIZ to CIZ beginning with the January 2025 release. CIZ monthly returns compound daily returns with dividends reinvested on ex-dates; historical series can be revised. These are current-vintage analyses, not point-in-time backtests. Data Library notes.
A Note on Sample Size
Professional empirical research typically uses 10+ years of monthly data (120+ observations) to obtain reliable estimates. A larger sample:
Increases statistical power (more likely to detect true effects)
Reduces standard errors (more data = less uncertainty)
Makes diagnostic tests more reliable (e.g., the Jarque-Bera test has low power with fewer than ~50 observations)
ff_factors = load_french('F-F_Research_Data_Factors_CSV.zip', start='2010-01-01')
ff_factors = ff_factors.rename(columns={'Mkt-RF': 'Mkt_RF'})
coverage('US FF3 (decimal monthly returns)', ff_factors)
print(ff_factors.tail())
US FF3 (decimal monthly returns): 201 observations, 2010-01-01 to 2026-09-01; as of 2026-10-31
Mkt_RF SMB HML RF
Date
2026-05-01 0.0491 -0.0159 -0.0231 0.0031
2026-06-01 -0.0107 0.0339 0.0358 0.0029
2026-07-01 -0.0061 -0.0192 0.0211 0.0033
2026-08-01 0.0256 0.0034 -0.0354 0.0029
2026-09-01 -0.0107 -0.0316 -0.0155 0.0031
etf_tickers = {'SPY': 'SPY (S&P 500)', 'IWN': 'IWN (Small Cap Value)',
               'VTV': 'VTV (Large Cap Value)'}
etf_dataframes = {}
for ticker in etf_tickers:
    prices = load_prices(ticker)  # includes a close before January 2010
    returns = monthly_returns(prices).rename('ETF_Return')
    edf = ff_factors.join(returns, how='inner').dropna()
    edf['Stock_Excess_Return'] = edf['ETF_Return'] - edf['RF']
    etf_dataframes[ticker] = edf
    coverage(ticker + ' adjusted daily prices', prices)
common_idx = etf_dataframes['SPY'].index
for edf in etf_dataframes.values():
    common_idx = common_idx.intersection(edf.index)
assert len(common_idx) > 120
etf_dataframes = {t: d.loc[common_idx].copy() for t, d in etf_dataframes.items()}
df = etf_dataframes['SPY'].copy()
coverage('Common monthly regression sample', df)
print(df.head())
SPY adjusted daily prices: 6,770 observations, 1999-12-01 to 2026-10-30; as of 2026-10-31
IWN adjusted daily prices: 6,604 observations, 2000-07-28 to 2026-10-30; as of 2026-10-31
VTV adjusted daily prices: 5,725 observations, 2004-01-30 to 2026-10-30; as of 2026-10-31
Common monthly regression sample: 201 observations, 2010-01-01 to 2026-09-01; as of 2026-10-31
Mkt_RF SMB HML RF ETF_Return Stock_Excess_Return
Date
2010-01-01 -0.0335 0.0043 0.0033 0.0000 -0.036343 -0.036343
2010-02-01 0.0339 0.0118 0.0318 0.0000 0.031195 0.031195
2010-03-01 0.0630 0.0146 0.0219 0.0001 0.060880 0.060780
2010-04-01 0.0199 0.0484 0.0296 0.0001 0.015470 0.015370
2010-05-01 -0.0790 0.0013 -0.0248 0.0001 -0.079455 -0.079555
Section 3: Descriptive Statistics — Understanding Your Data
Before building a regression model, we need to understand the basic properties of our data. Descriptive statistics summarize large datasets into a few key numbers — mean, standard deviation, percentiles, and correlations.
Prerequisite recap: If any of the formulas below are unfamiliar (e.g., Bessel’s correction, the difference between and , or how sample covariance relates to population covariance), see the Statistical Foundations, Sections 1–2, where every formula is derived and verified on a 5-observation dataset.
Quick Reference
| Statistic | Formula | Financial Meaning |
|---|---|---|
| Mean | Average monthly return | |
| Std Dev | Volatility / risk | |
| Correlation | Co-movement (−1 to +1) |
Key things to look for:
Mkt_RF mean × 12 gives a rough annualized market premium
Std Dev × gives an annualized volatility estimate (typical US equity: 15–20%)
Low correlations between factors (SMB, HML, Mkt-RF) confirm they capture different dimensions of risk — this is by construction
Now let’s examine our data:
# Compute descriptive statistics
print("\nDESCRIPTIVE STATISTICS (All returns in decimal form)\n")
print(df.describe())

# Calculate correlations for numeric columns only
print("\n")
print("CORRELATION MATRIX\n")
numeric_cols = df.select_dtypes(include=[np.number]).columns
corr_matrix = df[numeric_cols].corr().round(4)
print(corr_matrix)
DESCRIPTIVE STATISTICS (All returns in decimal form)

           Mkt_RF         SMB         HML          RF  ETF_Return  \
count  201.000000  201.000000  201.000000  201.000000  201.000000
mean     0.010822   -0.000877   -0.000558    0.001184    0.011950
std      0.042944    0.025254    0.032421    0.001536    0.041402
min     -0.133700   -0.059300   -0.138300    0.000000   -0.124871
25%     -0.012000   -0.019300   -0.018800    0.000000   -0.011215
50%      0.013700    0.000600   -0.003800    0.000100    0.017011
75%      0.034500    0.013100    0.016600    0.002100    0.036838
max      0.136000    0.071400    0.128600    0.004800    0.126984

       Stock_Excess_Return
count           201.000000
mean              0.010766
std               0.041385
min              -0.126071
25%              -0.013193
50%               0.016200
75%               0.035446
max               0.126984


CORRELATION MATRIX

                     Mkt_RF     SMB     HML      RF  ETF_Return  \
Mkt_RF               1.0000  0.3279  0.0284 -0.0107      0.9942
SMB                  0.3279  1.0000  0.1041 -0.1117      0.2485
HML                  0.0284  0.1041  1.0000 -0.0369      0.0293
RF                  -0.0107 -0.1117 -0.0369  1.0000      0.0297
ETF_Return           0.9942  0.2485  0.0293  0.0297      1.0000
Stock_Excess_Return  0.9950  0.2528  0.0307 -0.0074      0.9993

                     Stock_Excess_Return
Mkt_RF                            0.9950
SMB                               0.2528
HML                               0.0307
RF                               -0.0074
ETF_Return                        0.9993
Stock_Excess_Return               1.0000
Source
# ============================================================================
# Visualize: Correlation heatmap + factor distributions
# ============================================================================

fig, axes = plt.subplots(1, 2, figsize=(16, 5.5))

# --- Left: Correlation heatmap ---
numeric_cols = df.select_dtypes(include=[np.number]).columns
corr_matrix = df[numeric_cols].corr()
mask = np.triu(np.ones_like(corr_matrix, dtype=bool), k=1)
sns.heatmap(corr_matrix, annot=True, fmt='.2f', cmap='RdBu_r', center=0,
            mask=mask, square=True, ax=axes[0], vmin=-1, vmax=1,
            linewidths=0.5)
axes[0].set_title('Correlation Matrix', fontweight='bold', fontsize=13)

# --- Right: Distribution of each factor + stock excess return ---
plot_cols = [c for c in ['Mkt_RF', 'SMB', 'HML', 'Stock_Excess_Return'] if c in df.columns]
colors = ['#2c3e50', '#e74c3c', '#2ecc71', '#3498db']
for col, color in zip(plot_cols, colors):
    axes[1].hist(df[col].dropna(), bins=30, alpha=0.5, color=color, label=col, density=True)
axes[1].set_title('Return Distributions (Monthly)', fontweight='bold', fontsize=13)
axes[1].set_xlabel('Monthly Return')
axes[1].set_ylabel('Density')
axes[1].legend(fontsize=9)
axes[1].grid(True, alpha=0.3)

plt.tight_layout()
plt.show()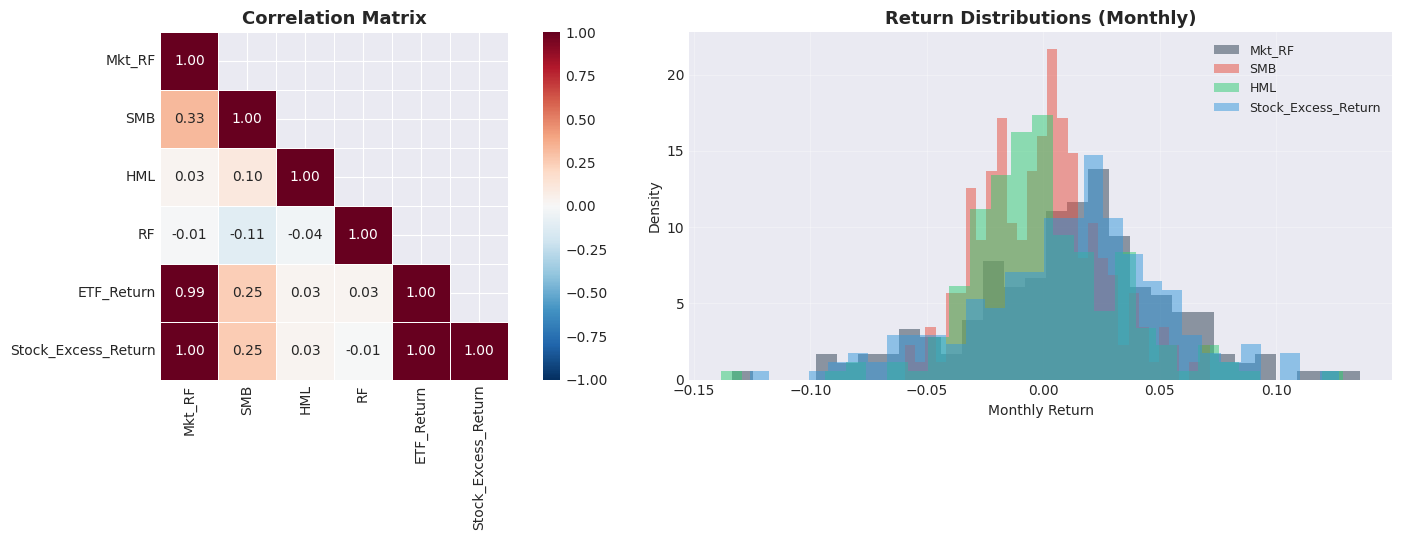
Interpreting the Descriptive Statistics
The exact numbers you see will depend on the data downloaded from Yahoo Finance. Here are the key things to look for:
Key Observations:
Count (n): Check how many months of data we have. The loading cell prints the current matched sample; more months do not by themselves guarantee valid inference.
Mean (Average Returns):
Mkt_RF: The average monthly market excess return. Multiply by 12 for a rough annualized figure (an arithmetic annualization, not realized CAGR; realized total-return CAGR uses the product of gross returns).
Stock_Excess_Return: Since SPY tracks the broad US market, its mean excess return should be close to the Mkt_RF mean.
Standard Deviation (Volatility):
Mkt_RF and Stock_Excess_Return: For a broad US market ETF like SPY, these should be similar. Multiply monthly std dev by for an annualized approximation.
A typical annualized US equity volatility is around 15–20%.
Range (Min to Max):
Look for extreme months (e.g., the COVID crash in March 2020 will appear as a large negative).
Even diversified ETFs experience significant monthly swings.
The Correlation Matrix shows how variables move together (scale: -1 to +1):
Between Factors:
Mkt-RF vs SMB: Typically weak to moderate (small and large caps move somewhat together)
Mkt-RF vs HML: Typically near zero (market and value effects are largely independent)
SMB vs HML: Typically near zero (confirming they capture different risks)
SPY’s Correlations:
Mkt-RF vs SPY: Should be very high (close to 1), since SPY tracks the US market that the Mkt-RF factor is derived from. This is exactly what we expect!
SMB vs SPY: Should be near zero or slightly negative — a large-cap-heavy index has limited small-cap exposure.
HML vs SPY: Should be near zero — a market-cap-weighted index has no particular value tilt.
# Manual calculation of statistics for Mkt-RF
mkt_returns = df['Mkt_RF'].values
n = len(mkt_returns)

# Calculate mean
mean = mkt_returns.sum() / n

# Calculate standard deviation
deviations = mkt_returns - mean
squared_deviations = deviations ** 2
variance = squared_deviations.sum() / (n - 1)
std_dev = np.sqrt(variance)

# Calculate quartiles and range
min_val = mkt_returns.min()
q1 = np.percentile(mkt_returns, 25)
median = np.percentile(mkt_returns, 50)
q3 = np.percentile(mkt_returns, 75)
max_val = mkt_returns.max()
iqr = q3 - q1

# Results
print("Manual Calculation Results (Mkt-RF):")
print(f"Count: {n}")
print(f"Mean: {mean:.6f} ({mean:.4%} monthly, {mean*12:.4%} arithmetic annualized)")
print(f"Std Dev: {std_dev:.6f} ({std_dev:.4%} monthly, {std_dev * np.sqrt(12):.2%} annualized)")
print(f"Min: {min_val:.6f} ({min_val:.2%})")
print(f"Q1: {q1:.6f} ({q1:.2%})")
print(f"Median: {median:.6f} ({median:.2%})")
print(f"Q3: {q3:.6f} ({q3:.2%})")
print(f"Max: {max_val:.6f} ({max_val:.2%})")
print(f"IQR: {iqr:.6f}")

# Manual calculation of correlation
mkt = df['Mkt_RF'].values
stock = df['Stock_Excess_Return'].values
mkt_mean = mkt.mean()
stock_mean = stock.mean()
cov_numerator = ((mkt - mkt_mean) * (stock - stock_mean)).sum()
covariance = cov_numerator / (n - 1)
mkt_std = df['Mkt_RF'].std()
stock_std = df['Stock_Excess_Return'].std()
correlation = covariance / (mkt_std * stock_std)

print(f"\nManual Correlation (Mkt-RF vs Stock_Excess_Return):")
print(f"Covariance: {covariance:.6f}")
print(f"Correlation: {correlation:.6f}")
print(f"Verification (pandas): {df['Mkt_RF'].corr(df['Stock_Excess_Return']):.6f}")
Manual Calculation Results (Mkt-RF):
Count: 201
Mean: 0.010822 (1.0822% monthly, 12.9863% arithmetic annualized)
Std Dev: 0.042944 (4.2944% monthly, 14.88% annualized)
Min: -0.133700 (-13.37%)
Q1: -0.012000 (-1.20%)
Median: 0.013700 (1.37%)
Q3: 0.034500 (3.45%)
Max: 0.136000 (13.60%)
IQR: 0.046500
Manual Correlation (Mkt-RF vs Stock_Excess_Return):
Covariance: 0.001768
Correlation: 0.995049
Verification (pandas): 0.995049
Understanding These Manual Calculations
The code above recalculates statistics “from scratch” using the raw formulas: mean = sum/count, standard deviation via , covariance, and correlation. This is the same approach used on 5 data points in the Statistical Foundations notebook (Sections 1–2) — now applied at scale to real market data. The pandas .describe() and .corr() methods compute exactly the same quantities.
Why These Matter for the Fama-French Model:
Mean — expected excess returns, i.e., compensation for taking risk
Standard deviation — volatility / risk level of each factor
Correlation — whether factors capture different risks (low correlation = good: the factors are not redundant)
For SPY vs Mkt-RF specifically, we expect correlation close to 1.0, since SPY tracks the very market that the Mkt-RF factor is derived from.
Let’s now use these factors in a regression model to explain stock returns...
Source
# Visualize the time series of returns
fig, axes = plt.subplots(3, 2, figsize=(14, 12))

# ETF Returns (one subplot per ETF)
colors_etf = {'SPY': 'darkblue', 'IWN': 'darkorange', 'VTV': 'darkgreen'}
for ax, (ticker, label) in zip(axes[:, 0], etf_tickers.items()):
    etf_df = etf_dataframes[ticker]
    ax.plot(etf_df.index, etf_df['Stock_Excess_Return']*100,
            linewidth=1.5, color=colors_etf[ticker])
    ax.set_title(f'{label} - Excess Returns', fontsize=11, fontweight='bold')
    ax.set_ylabel('Return (%)', fontsize=10)
    ax.grid(True, alpha=0.3)

# Fama-French Factors
axes[0, 1].plot(df.index, df['Mkt_RF']*100, linewidth=1.5, color='darkred')
axes[0, 1].set_title('Market Risk Premium (Mkt-RF)', fontsize=11, fontweight='bold')
axes[0, 1].set_ylabel('Return (%)', fontsize=10)
axes[0, 1].grid(True, alpha=0.3)

axes[1, 1].plot(df.index, df['SMB']*100, linewidth=1.5, color='teal')
axes[1, 1].set_title('SMB Factor (Size Effect)', fontsize=11, fontweight='bold')
axes[1, 1].set_ylabel('Return (%)', fontsize=10)
axes[1, 1].grid(True, alpha=0.3)

axes[2, 1].plot(df.index, df['HML']*100, linewidth=1.5, color='purple')
axes[2, 1].set_title('HML Factor (Value Effect)', fontsize=11, fontweight='bold')
axes[2, 1].set_ylabel('Return (%)', fontsize=10)
axes[2, 1].grid(True, alpha=0.3)

plt.tight_layout()
plt.show()

print("Time series visualization created.")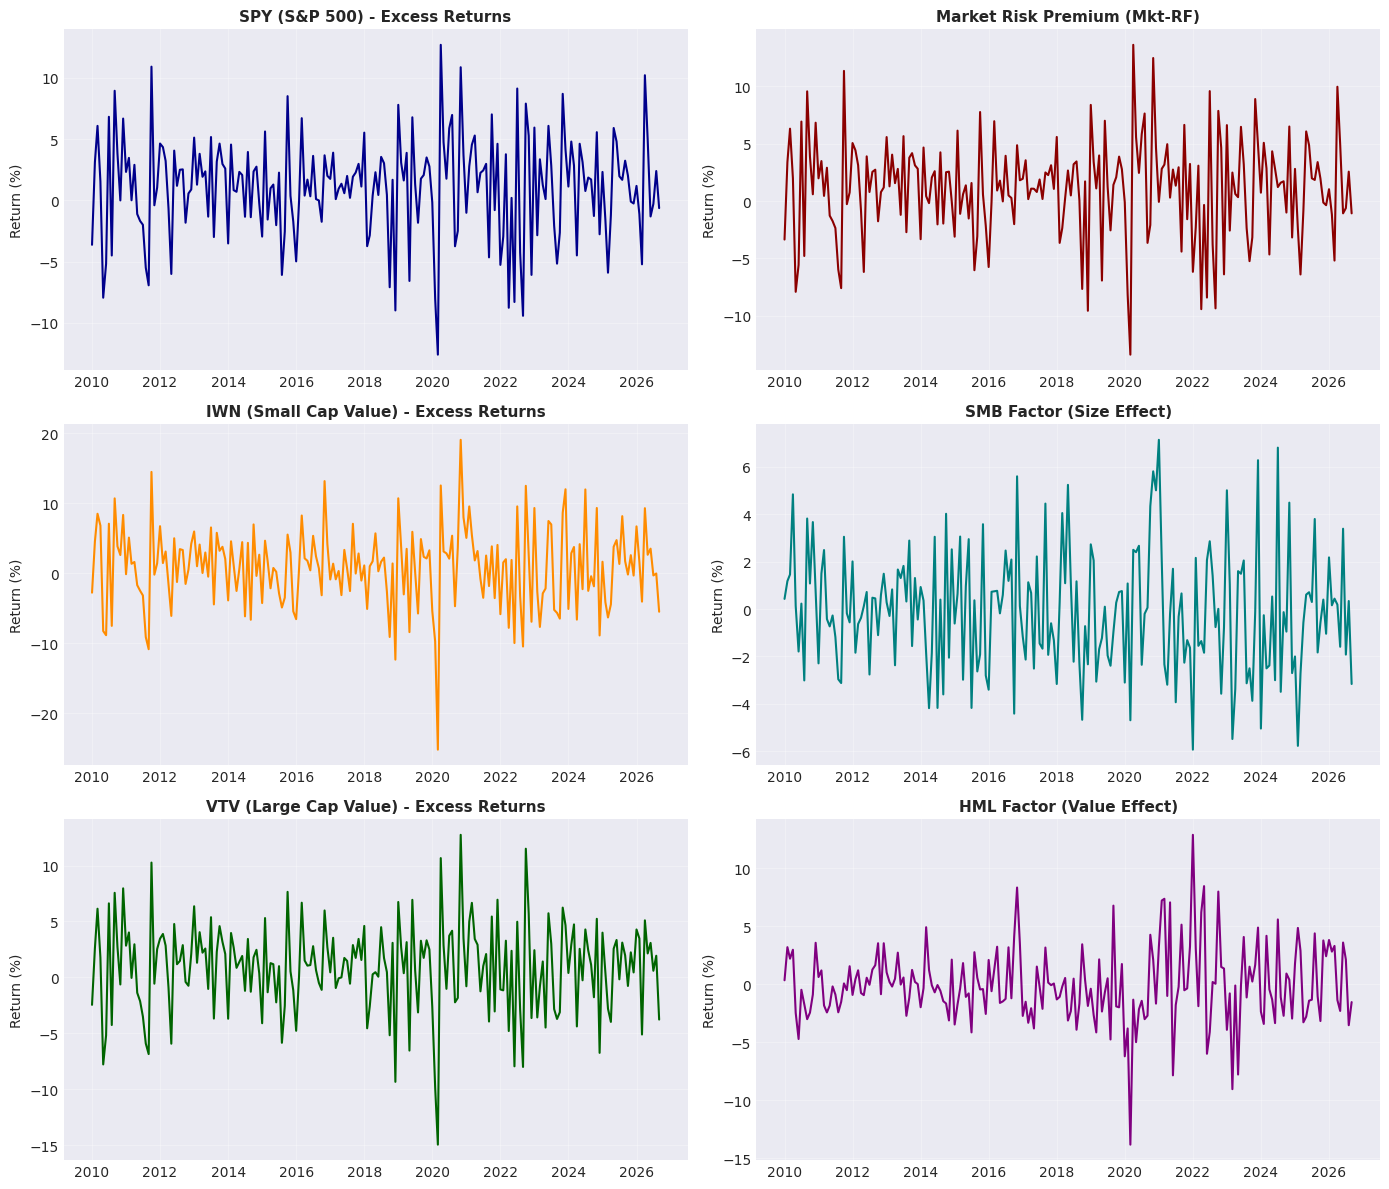
Time series visualization created.
Section 4: Understanding Excess Returns and Regression Concepts
What are Excess Returns?
In the Fama-French model, we don’t use raw returns directly. Instead, we use excess returns, which are the returns on an investment minus the risk-free rate.
The formula is:
Why do this? The risk-free rate represents the return you could get with a short-horizon USD risk-free proxy (a one-month Treasury bill return). By subtracting it, we’re asking: “How much extra return does this investment provide beyond what a safe investment would give?”
In our data:
Stock_Excess_Return= The excess return on our ETF (already calculated)Mkt_RF= The market excess return (Market return minus risk-free rate)SMBandHML= Long-short return spreads; do not subtract RF again
Multiple Linear Regression: The Concept
We want to estimate a relationship like this:
In our case:
What this means:
The ETF’s excess return () depends on three factors ()
We want to find the coefficients () that best fit the data
is the “leftover” part we can’t explain—the error term
Section 5: Ordinary Least Squares (OLS) Regression
Applying the Normal Equations to Real Factor Data
OLS finds the coefficients that minimize the sum of squared errors. In matrix form:
Full derivation: See Statistical Foundations (Section 5) for the scalar and matrix derivations of the normal equations with hand-checkable examples. Here we apply the same formula to real Fama-French data.
For our 3-factor model, the design matrix is:
The first column of 1’s gives us the intercept (). The code below walks through each matrix operation step by step on the actual data.
# Let's manually compute the OLS estimates using the normal equations
# to show exactly how this works in practice

print("="*70)
print("MANUAL OLS CALCULATION USING NORMAL EQUATIONS")
print("="*70)

# Step 1: Construct the design matrix X
# X has shape (n, 4): [intercept, Mkt_RF, SMB, HML]
X = np.column_stack([
    np.ones(len(df)),           # Column of 1's for the intercept
    df['Mkt_RF'].values,         # Market risk premium
    df['SMB'].values,            # SMB factor
    df['HML'].values             # HML factor
])

# Step 2: Extract the dependent variable (stock excess returns)
y = df['Stock_Excess_Return'].values

print(f"\nDesign matrix X shape: {X.shape}")
print(f"Dependent variable y shape: {y.shape}")
print(f"\nFirst 5 rows of X:")
print(f"   [Intercept]  [Mkt_RF]  [SMB]    [HML]")
print(X[:5])

# Step 3: Calculate X^T (transpose)
X_T = X.T
print(f"\nX^T shape: {X_T.shape}")

# Step 4: Calculate X^T * X
XTX = X_T @ X
print(f"\nX^T * X (shape {XTX.shape}):")
print(XTX)

# Step 5: Calculate (X^T * X)^-1
XTX_inv = np.linalg.inv(XTX)
print(f"\n(X^T * X)^-1:")
print(XTX_inv)

# Step 6: Calculate X^T * y
XTy = X_T @ y
print(f"\nX^T * y:")
print(XTy)

# Step 7: Calculate beta_hat = (X^T * X)^-1 * X^T * y
beta_hat = XTX_inv @ XTy

print("\n" + "="*70)
print("ESTIMATED COEFFICIENTS (β̂)")
print("="*70)
print(f"Alpha (α̂):          {beta_hat[0]:.6f} (intercept)")
print(f"Beta MKT (β̂_MKT):   {beta_hat[1]:.6f} (market sensitivity)")
print(f"Beta SMB (β̂_SMB):   {beta_hat[2]:.6f} (size sensitivity)")
print(f"Beta HML (β̂_HML):   {beta_hat[3]:.6f} (value sensitivity)")

# We will verify these manual estimates match the statsmodels output in the next section.
print("\nNote: We will compare these manual estimates with the statsmodels")
print("output in the next section to confirm they are identical.")
======================================================================
MANUAL OLS CALCULATION USING NORMAL EQUATIONS
======================================================================
Design matrix X shape: (201, 4)
Dependent variable y shape: (201,)
First 5 rows of X:
[Intercept] [Mkt_RF] [SMB] [HML]
[[ 1. -0.0335 0.0043 0.0033]
[ 1. 0.0339 0.0118 0.0318]
[ 1. 0.063 0.0146 0.0219]
[ 1. 0.0199 0.0484 0.0296]
[ 1. -0.079 0.0013 -0.0248]]
X^T shape: (4, 201)
X^T * X (shape (4, 4)):
[[ 2.0100000e+02 2.1752000e+00 -1.7630000e-01 -1.1210000e-01]
[ 2.1752000e+00 3.9238282e-01 6.9221980e-02 6.7043500e-03]
[-1.7630000e-01 6.9221980e-02 1.2771227e-01 1.7137480e-02]
[-1.1210000e-01 6.7043500e-03 1.7137480e-02 2.1028735e-01]]
(X^T * X)^-1:
[[ 5.37053236e-03 -3.43523011e-02 2.57840326e-02 1.85685532e-03]
[-3.43523011e-02 3.03797281e+00 -1.69715404e+00 2.31417509e-02]
[ 2.57840326e-02 -1.69715404e+00 8.87351111e+00 -6.55298165e-01]
[ 1.85685532e-03 2.31417509e-02 -6.55298165e-01 4.80905372e+00]]
X^T * y:
[2.16399701 0.37710663 0.0509441 0.0070265 ]
======================================================================
ESTIMATED COEFFICIENTS (β̂)
======================================================================
Alpha (α̂): -0.000006 (intercept)
Beta MKT (β̂_MKT): 0.985004 (market sensitivity)
Beta SMB (β̂_SMB): -0.136763 (size sensitivity)
Beta HML (β̂_HML): 0.013152 (value sensitivity)
Note: We will compare these manual estimates with the statsmodels
output in the next section to confirm they are identical.
Section 6: Fitting the Model with statsmodels
In Section 5 we computed the OLS coefficients manually using the normal equations. In practice, we use a statistical library — statsmodels — which does the same calculation and also computes many additional diagnostics automatically.
What Does statsmodels Do?
When we call sm.OLS(y, X).fit(), the library:
Computes the OLS estimates — exactly what we did by hand.
Estimates the error variance from the residuals.
Calculates many additional statistics — standard errors, t-statistics, p-values, , and more.
For now, we’ll only verify that statsmodels produces the same coefficients as our manual calculation. This is an important sanity check: if both methods agree, we know our math is correct.
The additional statistics (R-squared, standard errors, t-statistics, p-values, etc.) will be introduced one at a time in the sections that follow, so you can understand each one properly before moving on.
# Fit the Fama-French 3-factor regression model using statsmodels

# Prepare the data
y = df['Stock_Excess_Return'].values
X_factors = df[['Mkt_RF', 'SMB', 'HML']].values

# Add constant (intercept) term
X_with_const = sm.add_constant(X_factors)

# Fit the OLS model
model = sm.OLS(y, X_with_const)
results = model.fit()

# -----------------------------------------------------------------------
# Verify: do the statsmodels coefficients match our manual calculation?
# -----------------------------------------------------------------------
print("="*70)
print("VERIFICATION: MANUAL vs STATSMODELS COEFFICIENTS")
print("="*70)

labels = ['Alpha (intercept)', 'Beta_MKT', 'Beta_SMB', 'Beta_HML']
print(f"\n{'Coefficient':<22s}  {'Manual':>12s}  {'statsmodels':>12s}  {'Match?':>8s}")
print("-"*60)
for i, name in enumerate(labels):
    manual = beta_hat[i]
    sm_coef = results.params[i]
    match = np.isclose(manual, sm_coef)
    print(f"{name:<22s}  {manual:12.6f}  {sm_coef:12.6f}  {'Yes' if match else 'NO':>8s}")

print(f"\nAll coefficients match: {np.allclose(beta_hat, results.params)}")
print("\nThe statsmodels results object also contains standard errors,")
print("t-statistics, p-values, R-squared, and many other diagnostics.")
print("We will explore each of these in the sections that follow.")
======================================================================
VERIFICATION: MANUAL vs STATSMODELS COEFFICIENTS
======================================================================
Coefficient Manual statsmodels Match?
------------------------------------------------------------
Alpha (intercept) -0.000006 -0.000006 Yes
Beta_MKT 0.985004 0.985004 Yes
Beta_SMB -0.136763 -0.136763 Yes
Beta_HML 0.013152 0.013152 Yes
All coefficients match: True
The statsmodels results object also contains standard errors,
t-statistics, p-values, R-squared, and many other diagnostics.
We will explore each of these in the sections that follow.
Source
# ============================================================================
# Visualize the regression: fitted vs actual + scatter against main factor
# ============================================================================
# Seeing the regression visually builds intuition that tables alone cannot.

fig, axes = plt.subplots(1, 3, figsize=(17, 5))

# Panel 1: Fitted vs Actual (the classic regression-quality scatter)
fitted = results.fittedvalues * 100   # convert to %
actual = y * 100
axes[0].scatter(fitted, actual, s=20, alpha=0.55, color='steelblue', edgecolors='white', linewidth=0.3)
lo, hi = min(fitted.min(), actual.min()), max(fitted.max(), actual.max())
axes[0].plot([lo, hi], [lo, hi], color='red', linewidth=1.5, linestyle='--', label='Perfect fit')
axes[0].set_xlabel('Fitted return (%)', fontsize=11)
axes[0].set_ylabel('Actual return (%)', fontsize=11)
axes[0].set_title('Actual vs Fitted Returns\n(Closer to the red line = better fit)', fontweight='bold')
axes[0].legend(fontsize=9)
axes[0].grid(True, alpha=0.3)

# Panel 2: Excess Return vs Mkt-RF (the dominant factor)
mkt_vals = df['Mkt_RF'].values * 100
axes[1].scatter(mkt_vals, actual, s=20, alpha=0.55, color='darkorange', edgecolors='white', linewidth=0.3)
# Simple bivariate OLS line for visual reference
slope_simple = np.polyfit(mkt_vals, actual, 1)
x_line = np.linspace(mkt_vals.min(), mkt_vals.max(), 100)
axes[1].plot(x_line, np.polyval(slope_simple, x_line), color='red', linewidth=1.5, linestyle='--')
axes[1].set_xlabel('Market Excess Return, Mkt-RF (%)', fontsize=11)
axes[1].set_ylabel('SPY Excess Return (%)', fontsize=11)
axes[1].set_title('SPY vs Market Factor\n(Slope ≈ market beta)', fontweight='bold')
axes[1].grid(True, alpha=0.3)

# Panel 3: Residuals vs Fitted (preview of diagnostics)
resid = results.resid * 100
axes[2].scatter(fitted, resid, s=20, alpha=0.55, color='seagreen', edgecolors='white', linewidth=0.3)
axes[2].axhline(0, color='red', linewidth=1.5, linestyle='--')
axes[2].set_xlabel('Fitted return (%)', fontsize=11)
axes[2].set_ylabel('Residual (%)', fontsize=11)
axes[2].set_title('Residuals vs Fitted\n(Look for patterns — ideally none)', fontweight='bold')
axes[2].grid(True, alpha=0.3)

plt.tight_layout()
plt.show()

print("Left:   Points near the 45° line → model captures most variation.")
print("Center: The steep slope confirms SPY moves nearly 1-for-1 with the market.")
print("Right:  No visible pattern in residuals → model specification looks reasonable.")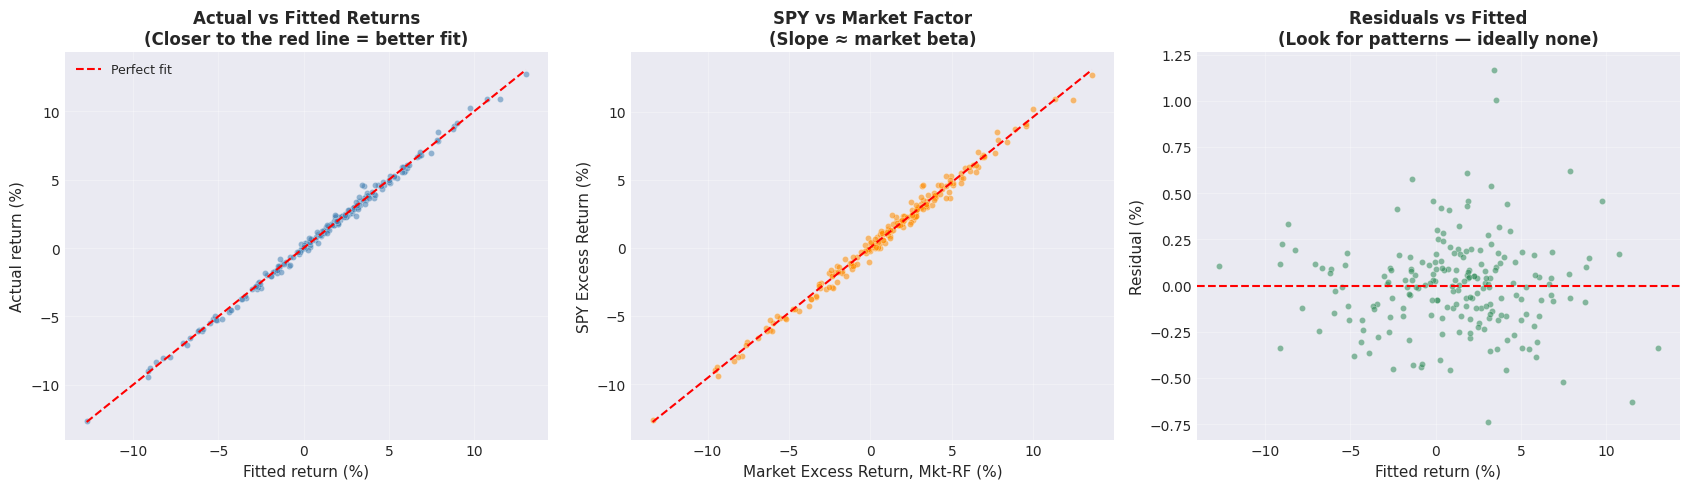
Left:   Points near the 45° line → model captures most variation.
Center: The steep slope confirms SPY moves nearly 1-for-1 with the market.
Right:  No visible pattern in residuals → model specification looks reasonable.
Section 7: Model Performance Metrics
Understanding R-squared and Other Fit Statistics
Before diving into the individual coefficients, let’s assess how well the model fits the data overall. R² and residual sums of squares describe in-sample fit. F-test p-values depend on error assumptions; we contrast classical and HAC-based tests below.
The R-squared Formula
Where:
(Residual Sum of Squares) = = Sum of squared residuals
(Total Sum of Squares) = = Total variation in
= Mean of the dependent variable
Intuition:
measures how much varies around its mean (total variation to explain)
measures how much unexplained variation remains after fitting the model
tells us what fraction of the total variation is explained by the model
ranges from 0 to 1; higher is better
Adjusted R-squared
The problem with is that adding regressors to a nested OLS model on the same sample cannot decrease it (even irrelevant variables). Adjusted penalizes for the number of variables:
Where:
= number of observations
= number of parameters (including intercept)
The denominator is called “degrees of freedom”
# Calculate model performance metrics
print("="*70)
print("MODEL PERFORMANCE METRICS - MANUAL CALCULATIONS")
print("="*70)

# Get predictions and residuals
y_actual = df['Stock_Excess_Return'].values
y_pred = np.asarray(results.fittedvalues)
residuals = np.asarray(results.resid)

# Calculate means
y_mean = np.mean(y_actual)

# Calculate sums of squares
TSS = np.sum((y_actual - y_mean)**2)           # Total Sum of Squares
RSS = np.sum(residuals**2)                     # Residual Sum of Squares
ESS = np.sum((y_pred - y_mean)**2)             # Explained Sum of Squares

print(f"\nNOTE: TSS = RSS + ESS (in-sample OLS with an intercept)")
print(f"TSS = {TSS:.8f}")
print(f"RSS = {RSS:.8f}")
print(f"ESS = {ESS:.8f}")
print(f"TSS = RSS + ESS? {np.isclose(TSS, RSS + ESS)}")

# Calculate R-squared
R2 = 1 - (RSS / TSS)
print(f"\n1. R-SQUARED (R²)")
print(f"   Formula: R² = 1 - (RSS / TSS)")
print(f"   Calculation: R² = 1 - ({RSS:.6f} / {TSS:.6f})")
print(f"   R² = {R2:.6f}")
print(f"   Interpretation: {R2*100:.2f}% of the variation in stock returns is")
print(f"   explained by the three Fama-French factors.")

# Calculate Adjusted R-squared
n = len(y_actual)
k = 4  # 4 parameters: alpha, beta_mkt, beta_smb, beta_hml
adj_R2 = 1 - ((1 - R2) * (n - 1) / (n - k))
print(f"\n2. ADJUSTED R-SQUARED (R̄²)")
print(f"   Formula: R̄² = 1 - ((1 - R²) × (n-1) / (n-k))")
print(f"   Where n = {n} observations, k = {k} parameters")
print(f"   Calculation: R̄² = 1 - ((1 - {R2:.4f}) × {n-1} / {n-k})")
print(f"   R̄² = {adj_R2:.6f}")
print(f"   Interpretation: After adjusting for the number of variables,")
print(f"   {adj_R2*100:.2f}% of variation is explained.")

# Calculate standard deviation of regression
sigma_hat_sq = RSS / (n - k)
sigma_hat = np.sqrt(sigma_hat_sq)
print(f"\n3. RESIDUAL STANDARD ERROR (σ̂)")
print(f"   Formula: σ̂² = RSS / (n - k)")
print(f"   Calculation: σ̂² = {RSS:.6f} / {n - k}")
print(f"   σ̂² = {sigma_hat_sq:.8f}")
print(f"   σ̂ = {sigma_hat:.6f}")
print(f"   Interpretation: Residual SD (not mean absolute prediction error) is {sigma_hat:.6f}")
print(f"   ({sigma_hat*100:.4f}% per month in this case).")

# Calculate F-statistic
MSR = ESS / (k - 1)  # Mean Squared Regression
MSE = RSS / (n - k)  # Mean Squared Error
F_stat = MSR / MSE
# Calculate p-value for F-statistic
from scipy.stats import f
p_value_F = f.sf(F_stat, k-1, n-k)
print(f"\n4. F-STATISTIC")
print(f"   Formula: F = (ESS / (k-1)) / (RSS / (n-k)) = MSR / MSE")
print(f"   MSR = {MSR:.8f}, MSE = {MSE:.8f}")
print(f"   F-statistic = {F_stat:.4f}")
print(f"   p-value = {p_value_F:.2e}")
print(f"   Interpretation: This tests the null hypothesis that ALL coefficients")
print(f"   (except intercept) equal zero. If p-value < 0.05, we reject this,")
print(f"   meaning the model IS statistically significant.")
if p_value_F < 0.05:
    print(f"   The model IS statistically significant (p < 0.05)")
else:
    print(f"   The model is NOT statistically significant")

# Compare with statsmodels values
print("\n" + "="*70)
print("COMPARISON WITH STATSMODELS OUTPUT")
print("="*70)
print(f"Our R²:               {R2:.6f}")
print(f"Statsmodels R²:       {results.rsquared:.6f}")
print(f"Match? {np.isclose(R2, results.rsquared)}")
print(f"\nOur Adjusted R²:      {adj_R2:.6f}")
print(f"Statsmodels Adj R²:   {results.rsquared_adj:.6f}")
print(f"Match? {np.isclose(adj_R2, results.rsquared_adj)}")
print(f"\nOur F-statistic:      {F_stat:.4f}")
print(f"Statsmodels F-stat:   {results.fvalue:.4f}")
print(f"Match? {np.isclose(F_stat, results.fvalue)}")
print("The classical F reference needs its classical error assumptions; use the HAC Wald test below for robust joint inference.")
======================================================================
MODEL PERFORMANCE METRICS - MANUAL CALCULATIONS
======================================================================
NOTE: TSS = RSS + ESS (in-sample OLS with an intercept)
TSS = 0.34253926
RSS = 0.00127362
ESS = 0.34126564
TSS = RSS + ESS? True
1. R-SQUARED (R²)
Formula: R² = 1 - (RSS / TSS)
Calculation: R² = 1 - (0.001274 / 0.342539)
R² = 0.996282
Interpretation: 99.63% of the variation in stock returns is
explained by the three Fama-French factors.
2. ADJUSTED R-SQUARED (R̄²)
Formula: R̄² = 1 - ((1 - R²) × (n-1) / (n-k))
Where n = 201 observations, k = 4 parameters
Calculation: R̄² = 1 - ((1 - 0.9963) × 200 / 197)
R̄² = 0.996225
Interpretation: After adjusting for the number of variables,
99.62% of variation is explained.
3. RESIDUAL STANDARD ERROR (σ̂)
Formula: σ̂² = RSS / (n - k)
Calculation: σ̂² = 0.001274 / 197
σ̂² = 0.00000647
σ̂ = 0.002543
Interpretation: Residual SD (not mean absolute prediction error) is 0.002543
(0.2543% per month in this case).
4. F-STATISTIC
Formula: F = (ESS / (k-1)) / (RSS / (n-k)) = MSR / MSE
MSR = 0.11375521, MSE = 0.00000647
F-statistic = 17595.3389
p-value = 5.34e-239
Interpretation: This tests the null hypothesis that ALL coefficients
(except intercept) equal zero. If p-value < 0.05, we reject this,
meaning the model IS statistically significant.
The model IS statistically significant (p < 0.05)
======================================================================
COMPARISON WITH STATSMODELS OUTPUT
======================================================================
Our R²: 0.996282
Statsmodels R²: 0.996282
Match? True
Our Adjusted R²: 0.996225
Statsmodels Adj R²: 0.996225
Match? True
Our F-statistic: 17595.3389
Statsmodels F-stat: 17595.3389
Match? True
The classical F reference needs its classical error assumptions; use the HAC Wald test below for robust joint inference.
Source
# ============================================================================
# Visualize: Model performance metrics
# ============================================================================

fig, axes = plt.subplots(1, 2, figsize=(14, 5))

# --- Left: Variance decomposition (TSS = ESS + RSS) ---
ax = axes[0]
labels = ['Explained\n(ESS)', 'Residual\n(RSS)']
sizes = [ESS, RSS]
colors_pie = ['#3498db', '#e74c3c']
wedges, texts, autotexts = ax.pie(sizes, labels=labels, colors=colors_pie,
                                   autopct='%1.1f%%', startangle=90,
                                   textprops={'fontsize': 11})
for at in autotexts:
    at.set_fontweight('bold')
ax.set_title(f'Variance Decomposition (R² = {R2:.4f})', fontweight='bold', fontsize=12)

# --- Right: Key metrics summary ---
ax2 = axes[1]
metric_names = ['R²', 'Adj R²', f'σ̂ (×100)']
metric_vals = [R2, adj_R2, sigma_hat * 100]
bar_colors = ['#3498db', '#2980b9', '#e67e22']
bars = ax2.barh(metric_names, metric_vals, color=bar_colors, edgecolor='white', height=0.5)
for bar, val in zip(bars, metric_vals):
    ax2.text(bar.get_width() + 0.01, bar.get_y() + bar.get_height()/2,
             f'{val:.4f}', va='center', fontsize=11, fontweight='bold')
ax2.set_xlabel('Value')
ax2.set_title('Model Performance Metrics', fontweight='bold', fontsize=12)
ax2.set_xlim(0, max(metric_vals) * 1.25)
ax2.grid(True, alpha=0.3, axis='x')

plt.tight_layout()
plt.show()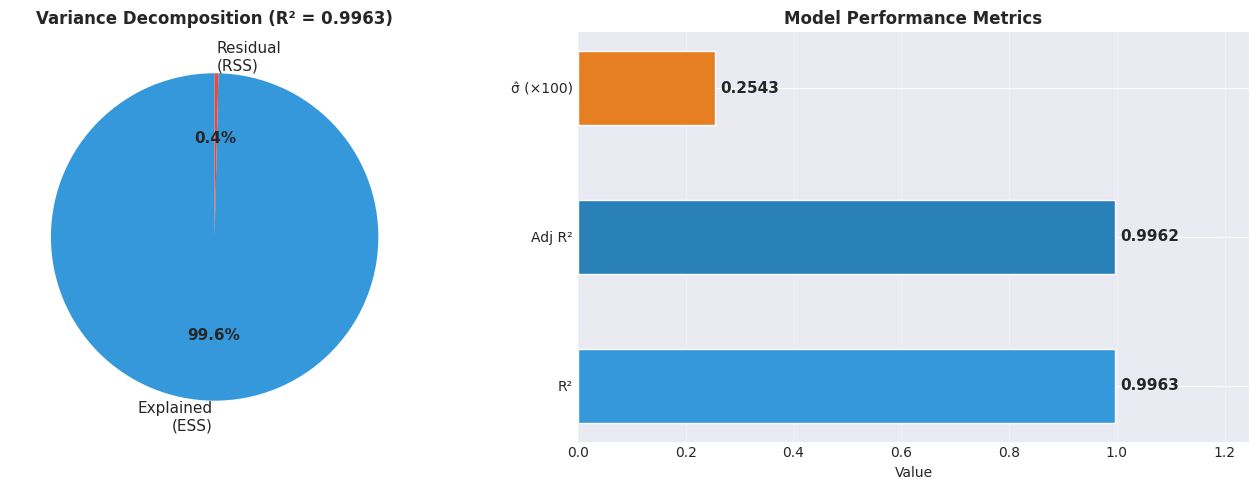
Section 8: Validating Regression Assumptions and Diagnostics
Why This Section Matters
The regression in Section 6 gave us coefficient estimates (, , etc.) and the performance metrics in Section 7 told us how well the model fits. But those numbers come with a hidden catch: the standard errors, t-statistics, and p-values printed alongside the coefficients are only trustworthy if certain assumptions about the error term hold.
If those assumptions fail — and they often do for financial data — then:
The coefficient estimates themselves are typically still fine (unbiased and consistent).
But the uncertainty measures are wrong: standard errors tend to be too small, t-statistics too large, and p-values too optimistic. In other words, you might conclude a factor is statistically significant when it really isn’t.
Connection to earlier notebooks: The Time-Series Foundations notebook examined evidence about whether financial return data is compatible with stationarity (Section 2), has weak autocorrelation but strong volatility clustering (Sections 3–4), and explores dependence diagnostics without proving mixing (Section 5). The summary “assumption stack” (Section 6) distinguished diagnostics from assumptions that remain unverified. Here we check the same assumptions directly on the Fama-French regression residuals.
This section checks the assumptions; the next section (Section 9) will show how to fix things when they fail.
Source
# Create diagnostic plots
fig = plt.figure(figsize=(16, 12))

# Get residuals and fitted values
residuals = np.asarray(results.resid)
fitted_values = np.asarray(results.fittedvalues)
y_actual = df['Stock_Excess_Return'].values

# 1. Residuals vs Fitted Values (checks linearity and homoscedasticity)
ax1 = plt.subplot(2, 3, 1)
ax1.scatter(fitted_values, residuals, alpha=0.6, s=50)
ax1.axhline(y=0, color='r', linestyle='--', linewidth=2)
ax1.set_xlabel('Fitted Values')
ax1.set_ylabel('Residuals')
ax1.set_title('Residuals vs Fitted Values\n(Should show random scatter around 0)', fontweight='bold')
ax1.grid(True, alpha=0.3)

# 2. Q-Q Plot (checks normality of residuals)
ax2 = plt.subplot(2, 3, 2)
stats.probplot(residuals, dist="norm", plot=ax2)
ax2.set_title('Q-Q Plot\n(Points should lie on diagonal line)', fontweight='bold')
ax2.grid(True, alpha=0.3)

# 3. Scale-Location Plot (checks homoscedasticity)
ax3 = plt.subplot(2, 3, 3)
standardized_residuals = residuals / np.std(residuals)
ax3.scatter(fitted_values, np.sqrt(np.abs(standardized_residuals)), alpha=0.6, s=50)
ax3.set_xlabel('Fitted Values')
ax3.set_ylabel('|Standardized Residuals|')
ax3.set_title('Scale-Location Plot\n(Should show random scatter)', fontweight='bold')
ax3.grid(True, alpha=0.3)

# 4. Histogram of residuals (checks normality)
ax4 = plt.subplot(2, 3, 4)
ax4.hist(residuals, bins=30, edgecolor='black', alpha=0.7, density=True)
# Overlay normal distribution
mu, sigma = residuals.mean(), residuals.std()
x = np.linspace(residuals.min(), residuals.max(), 100)
ax4.plot(x, stats.norm.pdf(x, mu, sigma), 'r-', linewidth=2, label='Normal Distribution')
ax4.set_xlabel('Residuals')
ax4.set_ylabel('Density')
ax4.set_title('Histogram of Residuals\n(Should look bell-shaped)', fontweight='bold')
ax4.legend()
ax4.grid(True, alpha=0.3)

# 5. Actual vs Fitted
ax5 = plt.subplot(2, 3, 5)
ax5.scatter(y_actual, fitted_values, alpha=0.6, s=50)
min_val = min(y_actual.min(), fitted_values.min())
max_val = max(y_actual.max(), fitted_values.max())
ax5.plot([min_val, max_val], [min_val, max_val], 'r--', linewidth=2, label='Perfect Fit')
ax5.set_xlabel('Actual Values')
ax5.set_ylabel('Fitted Values')
ax5.set_title('Actual vs Fitted Values\n(Should lie on diagonal line)', fontweight='bold')
ax5.legend()
ax5.grid(True, alpha=0.3)

# 6. Residuals over time (checks independence)
ax6 = plt.subplot(2, 3, 6)
ax6.plot(range(len(residuals)), residuals, marker='o', linestyle='-', alpha=0.6, markersize=4)
ax6.axhline(y=0, color='r', linestyle='--', linewidth=2)
ax6.set_xlabel('Observation Number')
ax6.set_ylabel('Residuals')
ax6.set_title('Residuals Over Time\n(Should show no pattern)', fontweight='bold')
ax6.grid(True, alpha=0.3)

plt.tight_layout()
plt.show()

print("Diagnostic plots created.")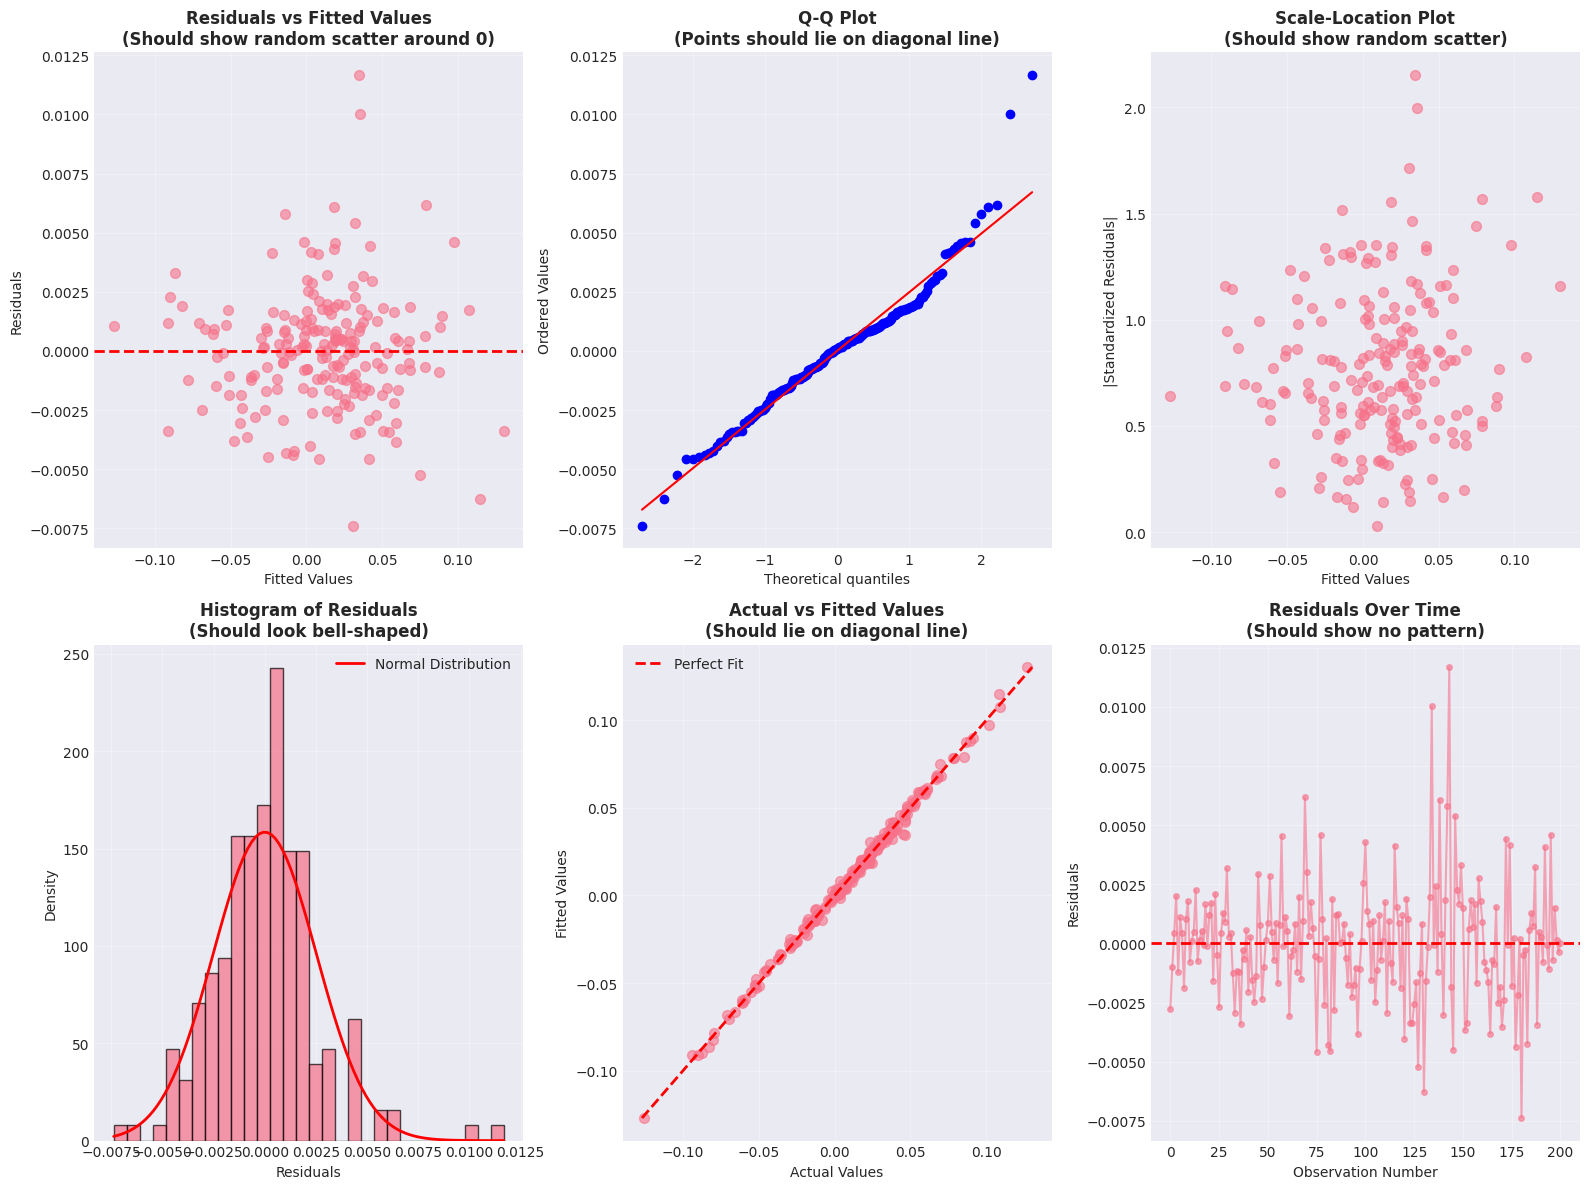
Diagnostic plots created.
Formal Statistical Tests for Assumptions
Visual inspection gives us intuition, but formal statistical tests provide rigorous evidence. Each test below has a null hypothesis () representing the “ideal” scenario and an alternative that flags a violation.
print("="*70)
print("FORMAL TESTS FOR REGRESSION ASSUMPTIONS")
print("="*70)

# 1. Normality Test: Jarque-Bera
print("\n1. JARQUE-BERA TEST FOR NORMALITY")
print("   Null Hypothesis (H0): Residuals are normally distributed")
print("   Alternative Hypothesis (H1): Residuals are NOT normally distributed")
print("   Caveat: With ~100+ observations, JB can detect departures in financial")
print("   data that has mild fat tails (excess kurtosis), even when the")
print("   departure from normality is too small to meaningfully affect OLS.")
print("   This is one reason we use robust standard errors regardless.")
jb_result = jarque_bera(residuals)
jb_statistic, jb_pvalue = jb_result[0], jb_result[1]
print(f"   Test Statistic: {jb_statistic:.6f}")
print(f"   p-value: {jb_pvalue:.6f}")
if jb_pvalue > 0.05:
    print(f"   CONCLUSION: We fail to reject H0 (p > 0.05)")
    print(f"     Residuals appear to be normally distributed.")
else:
    print(f"   CONCLUSION: We reject H0 (p < 0.05)")
    print(f"     Residuals appear to NOT be normally distributed.")

# 2. Breusch-Pagan Test for Heteroscedasticity
print("\n2. BREUSCH-PAGAN TEST FOR HOMOSCEDASTICITY")
print("   Null Hypothesis (H0): Constant variance of residuals (homoscedasticity)")
print("   Alternative Hypothesis (H1): Variance is NOT constant (heteroscedasticity)")
from statsmodels.stats.diagnostic import het_breuschpagan
bp_test = het_breuschpagan(residuals, X_with_const)
bp_statistic, bp_pvalue = bp_test[0], bp_test[1]
print(f"   Test Statistic: {bp_statistic:.6f}")
print(f"   p-value: {bp_pvalue:.6f}")
if bp_pvalue > 0.05:
    print(f"   CONCLUSION: We fail to reject H0 (p > 0.05)")
    print(f"     The variance appears to be constant across fitted values.")
else:
    print(f"   CONCLUSION: We reject H0 (p < 0.05)")
    print(f"     There appears to be heteroscedasticity.")

# 3. Durbin-Watson Test for Autocorrelation
print("\n3. DURBIN-WATSON TEST FOR AUTOCORRELATION")
print("   Tests for correlation between consecutive residuals")
from statsmodels.stats.stattools import durbin_watson
dw_statistic = durbin_watson(residuals)
print(f"   Durbin-Watson Statistic: {dw_statistic:.6f}")
print(f"   Interpretation:")
print(f"      DW ~ 2: No autocorrelation (ideal)")
print(f"      DW < 2: Positive autocorrelation")
print(f"      DW > 2: Negative autocorrelation")
if 1.5 < dw_statistic < 2.5:
    print(f"   CONCLUSION: DW is near 2; this heuristic is not a significance test of independence.")
else:
    print(f"   CONCLUSION: Possible autocorrelation detected (DW = {dw_statistic:.4f})")

# 4. Variance Inflation Factor (VIF) for Multicollinearity
print("\n4. VARIANCE INFLATION FACTOR (VIF) FOR MULTICOLLINEARITY")
print("   VIF measures how much the variance of a coefficient is")
print("   inflated due to correlation with other variables.")
print("   Interpretation: VIF > 5 suggests multicollinearity problem")
print()
vif_values = []
for i in range(1, X_with_const.shape[1]):  # Skip the constant
    vif = variance_inflation_factor(X_with_const, i)
    var_name = ['Mkt_RF', 'SMB', 'HML'][i-1]
    vif_values.append((var_name, vif))
    print(f"   {var_name:10s}: VIF = {vif:.4f}", end="")
    if vif < 5:
        print(" (Below the heuristic VIF threshold)")
    else:
        print(" (MULTICOLLINEARITY WARNING)")

print("\n" + "="*70)
print("SUMMARY OF ASSUMPTIONS")
print("="*70)
print(f"Normality (Jarque-Bera):      {'Not rejected' if jb_pvalue > 0.05 else 'Rejected'}")
print(f"Homoscedasticity (BP test):   {'Not rejected' if bp_pvalue > 0.05 else 'Rejected'}")
print(f"Lag-1 dependence (DW heuristic): {'PASS' if 1.5 < dw_statistic < 2.5 else 'WARNING'}")
print(f"Multicollinearity (VIF):      {'PASS' if all(vif < 5 for _, vif in vif_values) else 'WARNING'}")

print("\nNote: Even if all tests pass, robust standard errors are still")
print("recommended for financial time-series data. Financial returns exhibit")
print("time-varying volatility (conditional heteroscedasticity) that the")
print("Breusch-Pagan test may not detect. This motivates the next section.")
from statsmodels.stats.diagnostic import acorr_ljungbox
print("Residual Ljung-Box diagnostics (approximate reference):")
print(acorr_ljungbox(residuals, lags=[6, 12], return_df=True))
print("A non-rejection is not proof that an assumption holds.")
======================================================================
FORMAL TESTS FOR REGRESSION ASSUMPTIONS
======================================================================
1. JARQUE-BERA TEST FOR NORMALITY
Null Hypothesis (H0): Residuals are normally distributed
Alternative Hypothesis (H1): Residuals are NOT normally distributed
Caveat: With ~100+ observations, JB can detect departures in financial
data that has mild fat tails (excess kurtosis), even when the
departure from normality is too small to meaningfully affect OLS.
This is one reason we use robust standard errors regardless.
Test Statistic: 87.952962
p-value: 0.000000
CONCLUSION: We reject H0 (p < 0.05)
Residuals appear to NOT be normally distributed.
2. BREUSCH-PAGAN TEST FOR HOMOSCEDASTICITY
Null Hypothesis (H0): Constant variance of residuals (homoscedasticity)
Alternative Hypothesis (H1): Variance is NOT constant (heteroscedasticity)
Test Statistic: 9.673128
p-value: 0.021559
CONCLUSION: We reject H0 (p < 0.05)
There appears to be heteroscedasticity.
3. DURBIN-WATSON TEST FOR AUTOCORRELATION
Tests for correlation between consecutive residuals
Durbin-Watson Statistic: 1.738673
Interpretation:
DW ~ 2: No autocorrelation (ideal)
DW < 2: Positive autocorrelation
DW > 2: Negative autocorrelation
CONCLUSION: DW is near 2; this heuristic is not a significance test of independence.
4. VARIANCE INFLATION FACTOR (VIF) FOR MULTICOLLINEARITY
VIF measures how much the variance of a coefficient is
inflated due to correlation with other variables.
Interpretation: VIF > 5 suggests multicollinearity problem
Mkt_RF : VIF = 1.1205 (Below the heuristic VIF threshold)
SMB : VIF = 1.1319 (Below the heuristic VIF threshold)
HML : VIF = 1.0110 (Below the heuristic VIF threshold)
======================================================================
SUMMARY OF ASSUMPTIONS
======================================================================
Normality (Jarque-Bera): Rejected
Homoscedasticity (BP test): Rejected
Lag-1 dependence (DW heuristic): PASS
Multicollinearity (VIF): PASS
Note: Even if all tests pass, robust standard errors are still
recommended for financial time-series data. Financial returns exhibit
time-varying volatility (conditional heteroscedasticity) that the
Breusch-Pagan test may not detect. This motivates the next section.
Residual Ljung-Box diagnostics (approximate reference):
lb_stat lb_pvalue
6 7.090766 0.312535
12 9.848872 0.629217
A non-rejection is not proof that an assumption holds.
Source
# ============================================================================
# Visualize: Assumption test dashboard
# ============================================================================

fig, axes = plt.subplots(1, 3, figsize=(17, 5))

# --- Panel 1: p-value summary for normality & homoscedasticity tests ---
test_names = ['Jarque-Bera\n(Normality)', 'Breusch-Pagan\n(Homoscedasticity)']
p_values = [jb_pvalue, bp_pvalue]
bar_colors = ['#2ecc71' if p > 0.05 else '#e74c3c' for p in p_values]

ax = axes[0]
bars = ax.bar(test_names, p_values, color=bar_colors, edgecolor='white', width=0.5)
ax.axhline(y=0.05, color='black', linestyle='--', linewidth=1.5, label='α = 0.05')
for bar, pv in zip(bars, p_values):
    ax.text(bar.get_x() + bar.get_width()/2, bar.get_height() + 0.01,
            f'p = {pv:.4f}', ha='center', fontsize=10, fontweight='bold')
ax.set_ylabel('p-value')
ax.set_title('Hypothesis Test p-Values', fontweight='bold', fontsize=12)
ax.set_ylim(0, max(p_values) * 1.3 + 0.05)
ax.legend(fontsize=9)
ax.grid(True, alpha=0.3, axis='y')

# --- Panel 2: Durbin-Watson gauge ---
ax2 = axes[1]
dw_range = np.linspace(0, 4, 300)
# Color gradient: red at 0 and 4, green at 2
dw_colors_map = plt.cm.RdYlGn(1 - np.abs(dw_range - 2) / 2)
for i in range(len(dw_range) - 1):
    ax2.barh(0, dw_range[i+1] - dw_range[i], left=dw_range[i], height=0.6,
             color=dw_colors_map[i])
ax2.axvline(x=dw_statistic, color='black', linewidth=3, label=f'DW = {dw_statistic:.3f}')
ax2.axvline(x=2.0, color='gray', linewidth=1, linestyle=':', alpha=0.7)
ax2.set_xlim(0, 4)
ax2.set_yticks([])
ax2.set_xlabel('Durbin-Watson Statistic')
ax2.set_title('Autocorrelation: Durbin-Watson', fontweight='bold', fontsize=12)
ax2.legend(fontsize=10, loc='upper left')
ax2.text(0.3, -0.4, 'Positive\nautocorrelation', ha='center', fontsize=8, color='#c0392b')
ax2.text(2.0, -0.4, 'No\nautocorrelation', ha='center', fontsize=8, color='#27ae60')
ax2.text(3.7, -0.4, 'Negative\nautocorrelation', ha='center', fontsize=8, color='#c0392b')

# --- Panel 3: VIF bar chart ---
ax3 = axes[2]
vif_names = [name for name, _ in vif_values]
vif_vals = [vif for _, vif in vif_values]
vif_colors = ['#2ecc71' if v < 5 else '#e74c3c' for v in vif_vals]
bars3 = ax3.bar(vif_names, vif_vals, color=vif_colors, edgecolor='white', width=0.5)
ax3.axhline(y=5, color='black', linestyle='--', linewidth=1.5, label='VIF = 5 threshold')
for bar, v in zip(bars3, vif_vals):
    ax3.text(bar.get_x() + bar.get_width()/2, bar.get_height() + 0.05,
            f'{v:.2f}', ha='center', fontsize=10, fontweight='bold')
ax3.set_ylabel('VIF')
ax3.set_title('Multicollinearity: VIF', fontweight='bold', fontsize=12)
ax3.set_ylim(0, max(max(vif_vals) * 1.3, 6))
ax3.legend(fontsize=9)
ax3.grid(True, alpha=0.3, axis='y')

fig.suptitle('Regression Assumption Diagnostics Dashboard', fontsize=14, fontweight='bold', y=1.02)
plt.tight_layout()
plt.show()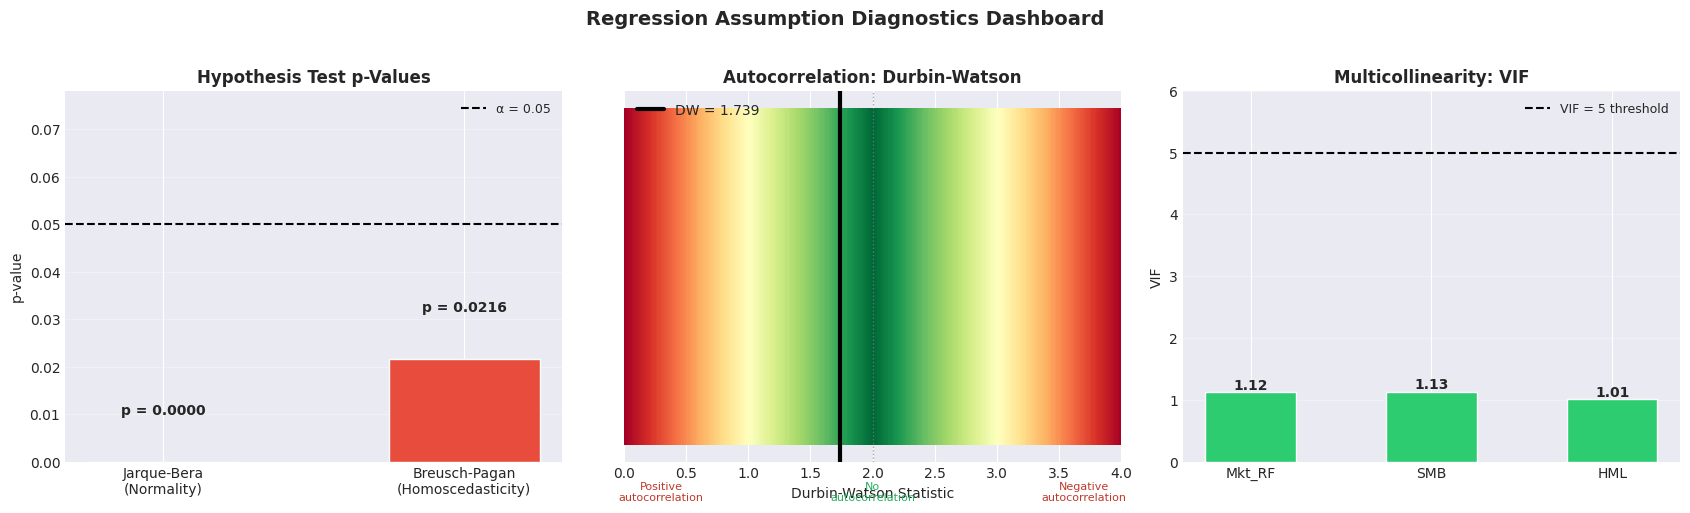
Section 9: Robust Standard Errors — The Standard in Empirical Finance
Why This Matters
The diagnostic tests above may or may not have flagged violations. But here’s the key insight: in financial time-series, we almost always use robust standard errors regardless of what the tests say.
Why? Because:
Financial returns exhibit stochastic volatility — variance changes over time. This often carries over to regression residuals, and simple tests may miss it.
Monthly returns can show mild autocorrelation, so treating a time-series regression as i.i.d. is risky.
Classic OLS standard errors assume constant variance and no autocorrelation. If those assumptions fail, your coefficient estimates () are still unbiased, but your standard errors, t-statistics, p-values, and confidence intervals are wrong.
Full derivation and intuition: The sandwich formula (HC0), its small-sample variants (HC1–HC3), and the Newey-West extension are derived step-by-step — with hand calculations on a 5-observation dataset — in the Statistical Foundations (Sections 6–9). The Monte Carlo evidence there demonstrates that classic OLS over-rejects under while Newey-West maintains the correct 5 % size.
An Intuitive Picture: Why Autocorrelation Inflates False Positives
Imagine 100 monthly residuals. If each were truly independent, you’d have 100 independent pieces of information. But with positive autocorrelation, consecutive residuals are partially redundant: your 100 observations effectively contain fewer than 100 independent pieces. Classic OLS doesn’t know this — it treats all 100 as fully independent, producing standard errors that are too small, t-statistics that are too large, and p-values that are too optimistic.
Section 5 of the Time-Series Foundations notebook studied the dependence structure of the raw return series. That evidence motivates HAC inference, but the direct evidence for the present regression comes from the residual diagnostics in Section 8 above.
The Solution: Let the Data Determine the Variance
Instead of assuming a rigid error structure, robust methods let the residuals themselves determine the variance estimate:
| Method | Corrects for | When to use |
|---|---|---|
| HC1 / HC3 | Heteroscedasticity only | Cross-sectional data |
| Newey-West HAC | Heteroscedasticity + autocorrelation | Time-series data (our case) |
We use Newey–West as a working covariance specification and check sensitivity. The code below compares all four methods side-by-side.
# Demonstrate the effects of heteroscedasticity and autocorrelation on standard errors
# and compare different robust methods

print("="*80)
print("COMPARING STANDARD ERROR ESTIMATES: CLASSIC VS. ROBUST METHODS")
print("="*80)

# Fit the model again (same as before)
y = df['Stock_Excess_Return'].values
X_factors = df[['Mkt_RF', 'SMB', 'HML']].values
X_with_const = sm.add_constant(X_factors)

model = sm.OLS(y, X_with_const)
results = model.fit()

# Get classic standard errors
print("\n1. CLASSIC OLS STANDARD ERRORS (assumes homoscedastic, independent errors)")
print("-" * 80)
classic_summary = results.summary()
print(classic_summary.tables[1])

classic_se = np.asarray(results.bse)

# HC1 (Heteroscedasticity Consistent)
print("\n" + "="*80)
print("2. HC1 STANDARD ERRORS (corrects for heteroscedasticity only)")
print("-" * 80)
results_hc1 = results.get_robustcov_results(cov_type='HC1', use_t=False)
print(results_hc1.summary().tables[1])

hc1_se = np.asarray(results_hc1.bse)

# HC3 Huber-White sandwich estimator
print("\n" + "="*80)
print("3. HC3 STANDARD ERRORS (alternative HC correction)")
print("-" * 80)
results_hc3 = results.get_robustcov_results(cov_type='HC3', use_t=False)
print(results_hc3.summary().tables[1])

hc3_se = np.asarray(results_hc3.bse)

# Newey-West Standard Errors (optimal lag selection)
print("\n" + "="*80)
print("4. NEWEY-WEST STANDARD ERRORS (corrects for heteroscedasticity + autocorrelation)")
print("-" * 80)

# Calculate appropriate lag length
n_obs = len(y)
lag_length = int(np.floor(4 * (n_obs / 100) ** (2/9)))
print(f"Sample size: {n_obs} observations")
print(f"Heuristic lag length: {lag_length} (using sample-size bandwidth heuristic)")

results_nw = results.get_robustcov_results(cov_type='HAC', maxlags=lag_length, use_correction=True, use_t=False)
print(results_nw.summary().tables[1])

nw_se = np.asarray(results_nw.bse)

# Create comparison table
print("\n" + "="*80)
print("DETAILED COMPARISON OF STANDARD ERRORS")
print("="*80)

var_names = ['Intercept (a)', 'Mkt_RF (B_MKT)', 'SMB (B_SMB)', 'HML (B_HML)']
comparison_data = {
    'Variable': var_names,
    'Classic SE': classic_se,
    'HC1 SE': hc1_se,
    'HC3 SE': hc3_se,
    'Newey-West SE': nw_se,
    'HC1 % Change': (hc1_se - classic_se) / classic_se * 100,
    'NW % Change': (nw_se - classic_se) / classic_se * 100
}

comparison_df = pd.DataFrame(comparison_data)
print(comparison_df.to_string(index=False))

print("\n" + "="*80)
print("INTERPRETING THE COMPARISON")
print("="*80)
# Also report autocorrelation so the reader can interpret the direction of SE changes
from statsmodels.stats.stattools import durbin_watson as dw_test
resid_check = np.asarray(results.resid)
dw_val = dw_test(resid_check)
ac_lag1 = np.corrcoef(resid_check[1:], resid_check[:-1])[0, 1]

print(f"""
% Change Interpretation:
- Positive: Robust method gives LARGER standard errors
- Negative: Robust method gives SMALLER standard errors
- |Change| > 10%: Notable difference — using classic SE could mislead

Residual autocorrelation structure (explains WHY some NW SEs differ):
  Durbin-Watson = {dw_val:.3f}  (2 = none, <2 = positive, >2 = negative)
  Lag-1 autocorrelation = {ac_lag1:+.4f}

The covariance estimator depends on the scores x_t * residual_t, not just
residual autocorrelation. Robust SEs may be larger or smaller than classical
SEs; neither sign is a guarantee of accuracy. Compare the actual table above.
HAC remains an asymptotic estimate under exogeneity and weak dependence.
""")
================================================================================
COMPARING STANDARD ERROR ESTIMATES: CLASSIC VS. ROBUST METHODS
================================================================================
1. CLASSIC OLS STANDARD ERRORS (assumes homoscedastic, independent errors)
--------------------------------------------------------------------------------
==============================================================================
coef std err t P>|t| [0.025 0.975]
------------------------------------------------------------------------------
const -6.073e-06 0.000 -0.033 0.974 -0.000 0.000
x1 0.9850 0.004 222.259 0.000 0.976 0.994
x2 -0.1368 0.008 -18.057 0.000 -0.152 -0.122
x3 0.0132 0.006 2.359 0.019 0.002 0.024
==============================================================================
================================================================================
2. HC1 STANDARD ERRORS (corrects for heteroscedasticity only)
--------------------------------------------------------------------------------
==============================================================================
coef std err z P>|z| [0.025 0.975]
------------------------------------------------------------------------------
const -6.073e-06 0.000 -0.035 0.972 -0.000 0.000
x1 0.9850 0.005 210.044 0.000 0.976 0.994
x2 -0.1368 0.009 -16.008 0.000 -0.154 -0.120
x3 0.0132 0.007 2.016 0.044 0.000 0.026
==============================================================================
================================================================================
3. HC3 STANDARD ERRORS (alternative HC correction)
--------------------------------------------------------------------------------
==============================================================================
coef std err z P>|z| [0.025 0.975]
------------------------------------------------------------------------------
const -6.073e-06 0.000 -0.035 0.972 -0.000 0.000
x1 0.9850 0.005 204.999 0.000 0.976 0.994
x2 -0.1368 0.009 -15.619 0.000 -0.154 -0.120
x3 0.0132 0.007 1.954 0.051 -4.23e-05 0.026
==============================================================================
================================================================================
4. NEWEY-WEST STANDARD ERRORS (corrects for heteroscedasticity + autocorrelation)
--------------------------------------------------------------------------------
Sample size: 201 observations
Heuristic lag length: 4 (using sample-size bandwidth heuristic)
==============================================================================
coef std err z P>|z| [0.025 0.975]
------------------------------------------------------------------------------
const -6.073e-06 0.000 -0.035 0.972 -0.000 0.000
x1 0.9850 0.005 184.512 0.000 0.975 0.995
x2 -0.1368 0.010 -14.323 0.000 -0.155 -0.118
x3 0.0132 0.007 1.952 0.051 -5.11e-05 0.026
==============================================================================
================================================================================
DETAILED COMPARISON OF STANDARD ERRORS
================================================================================
Variable Classic SE HC1 SE HC3 SE Newey-West SE HC1 % Change NW % Change
Intercept (a) 0.000186 0.000172 0.000174 0.000174 -7.950544 -6.470338
Mkt_RF (B_MKT) 0.004432 0.004690 0.004805 0.005338 5.815530 20.457891
SMB (B_SMB) 0.007574 0.008543 0.008756 0.009549 12.794545 26.069101
HML (B_HML) 0.005576 0.006524 0.006732 0.006737 17.009315 20.815533
================================================================================
INTERPRETING THE COMPARISON
================================================================================
% Change Interpretation:
- Positive: Robust method gives LARGER standard errors
- Negative: Robust method gives SMALLER standard errors
- |Change| > 10%: Notable difference — using classic SE could mislead
Residual autocorrelation structure (explains WHY some NW SEs differ):
Durbin-Watson = 1.739 (2 = none, <2 = positive, >2 = negative)
Lag-1 autocorrelation = +0.1280
The covariance estimator depends on the scores x_t * residual_t, not just
residual autocorrelation. Robust SEs may be larger or smaller than classical
SEs; neither sign is a guarantee of accuracy. Compare the actual table above.
HAC remains an asymptotic estimate under exogeneity and weak dependence.
Quick-Reference: The Sandwich Formula
All robust standard errors share the same sandwich structure:
What differs between methods is the meat :
| Method | Meat | Key feature |
|---|---|---|
| HC0 | Uses squared residuals; no autocorrelation correction | |
| Newey-West | Adds Bartlett-weighted cross-lag terms up to lag |
Lag selection (critical for Newey-West): — the sample-size bandwidth heuristic. Too few lags misses correlation; too many introduces noise.
For the complete hand calculation of each formula — HC0, HC1, HC2, HC3, and Newey-West with Bartlett weights — see the Statistical Foundations, Sections 6–7.
Decision Guide — Which Standard Errors?
Is this TIME-SERIES data?
  ├─ NO  (cross-sectional)  →  HC1 or HC3
  └─ YES (monthly returns, etc.)  →  Newey-West HAC  ✓
For the Fama-French model: Our data is monthly returns (time-series), so Newey-West is the correct choice. Many finance journals now require robust standard errors. Let’s see how much the choice matters:
Source
# Visualize the impact on inference: how p-values change
print("\n" + "="*80)
print("IMPACT ON HYPOTHESIS TESTING: HOW P-VALUES CHANGE")
print("="*80)

coefficients = np.asarray(results.params)

# Classic method
classic_pvalues = np.asarray(results.pvalues)

# Robust methods
hc1_tstats = coefficients / hc1_se
hc1_pvalues = results_hc1.pvalues

nw_tstats = coefficients / nw_se
nw_pvalues = results_nw.pvalues

print("\nP-value Comparison (Two-tailed test, a = 0.05)")
print("-" * 80)

pvalue_data = {
    'Variable': var_names,
    'Coefficient': coefficients,
    'Classic p-val': classic_pvalues,
    'HC1 p-val': hc1_pvalues,
    'Newey-West p-val': nw_pvalues,
    'Significance Change?': []
}

for i in range(len(var_names)):
    classic_sig = "Yes" if classic_pvalues[i] < 0.05 else "No"
    nw_sig = "Yes" if nw_pvalues[i] < 0.05 else "No"
    change = "YES!" if classic_sig != nw_sig else ""
    pvalue_data['Significance Change?'].append(change)

pvalue_df = pd.DataFrame(pvalue_data)
print(pvalue_df.to_string(index=False))

print("""
CRITICAL: If a variable is significant under classic but NOT under robust SEs
(or vice versa), using the classic method could lead to wrong conclusions!
""")

# Create visualization comparing confidence intervals
fig, axes = plt.subplots(1, 2, figsize=(15, 6))

# Left plot: Coefficient estimates with different confidence intervals
ax = axes[0]
y_pos = np.arange(len(var_names))

# Classic 95% CI
classic_ci_lower, classic_ci_upper = results.conf_int().T

# Newey-West 95% CI
nw_ci_lower = coefficients - 1.96 * nw_se
nw_ci_upper = coefficients + 1.96 * nw_se

ax.scatter(coefficients, y_pos, s=100, color='black', zorder=3, label='Point Estimate')
ax.hlines(y_pos, classic_ci_lower, classic_ci_upper, colors='blue', linewidth=2, label='Classic 95% CI')
ax.hlines(y_pos, nw_ci_lower, nw_ci_upper, colors='red', linewidth=3, alpha=0.6, label='Newey-West 95% CI')
ax.axvline(x=0, color='gray', linestyle='--', alpha=0.5)
ax.set_yticks(y_pos)
ax.set_yticklabels(var_names)
ax.set_xlabel('Coefficient Value')
ax.set_title('95% Confidence Intervals: Classic vs. Newey-West\n(Wider intervals = more conservative)',
             fontweight='bold', fontsize=12)
ax.legend(loc='best')
ax.grid(True, alpha=0.3, axis='x')

# Right plot: Standard error comparison
ax = axes[1]
x_pos = np.arange(len(var_names))
width = 0.25

ax.bar(x_pos - width, classic_se, width, label='Classic', alpha=0.8)
ax.bar(x_pos, hc1_se, width, label='HC1', alpha=0.8)
ax.bar(x_pos + width, nw_se, width, label='Newey-West', alpha=0.8)

ax.set_xlabel('Variables')
ax.set_ylabel('Standard Error')
ax.set_title('Standard Error Comparison\n(Higher = More Uncertainty)', fontweight='bold', fontsize=12)
ax.set_xticks(x_pos)
ax.set_xticklabels(var_names, rotation=45, ha='right')
ax.legend()
ax.grid(True, alpha=0.3, axis='y')

plt.tight_layout()
plt.show()

print("\nFigure: Confidence interval and standard error comparison")
================================================================================
IMPACT ON HYPOTHESIS TESTING: HOW P-VALUES CHANGE
================================================================================

P-value Comparison (Two-tailed test, a = 0.05)
--------------------------------------------------------------------------------
      Variable  Coefficient  Classic p-val    HC1 p-val  Newey-West p-val Significance Change?
 Intercept (a)    -0.000006   9.740323e-01 9.717544e-01      9.722013e-01
Mkt_RF (B_MKT)     0.985004  1.813046e-238 0.000000e+00      0.000000e+00
   SMB (B_SMB)    -0.136763   1.215965e-43 1.117937e-57      1.578528e-46
   HML (B_HML)     0.013152   1.931426e-02 4.381160e-02      5.089316e-02                 YES!

CRITICAL: If a variable is significant under classic but NOT under robust SEs
(or vice versa), using the classic method could lead to wrong conclusions!
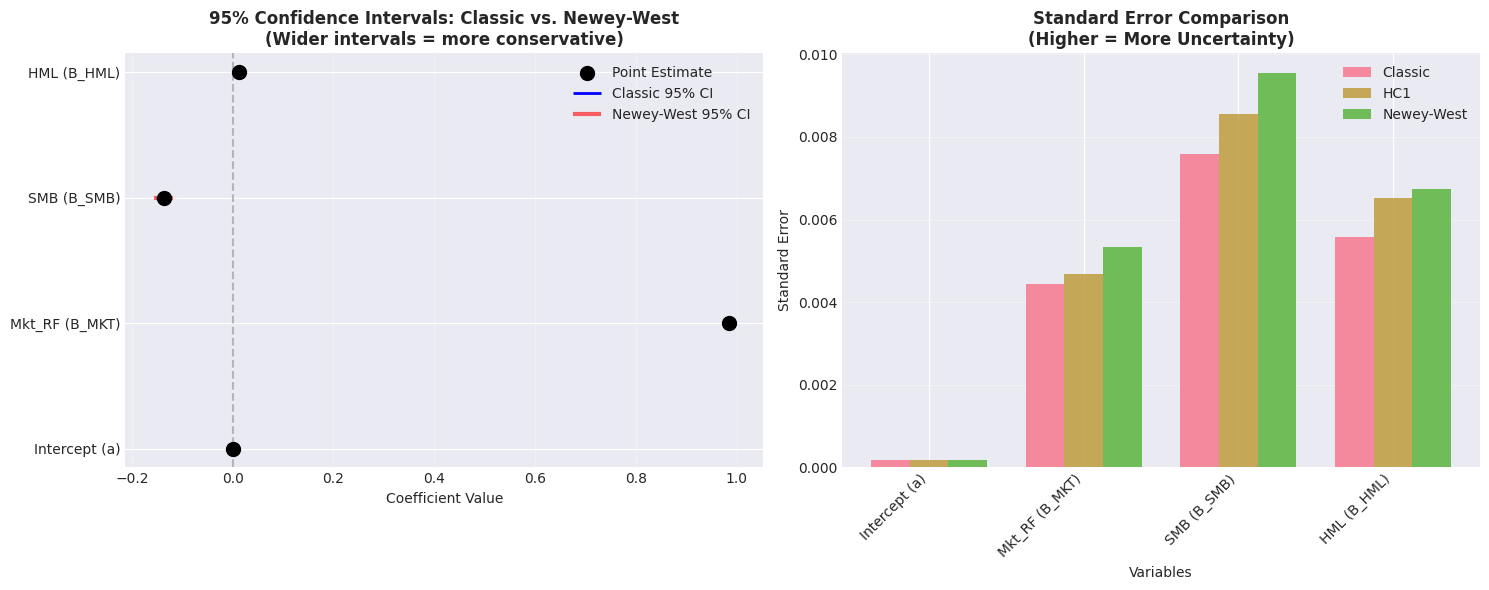
Figure: Confidence interval and standard error comparison
# Demonstrate the RECOMMENDED approach: Newey-West for Fama-French analysis

print("="*80)
print("RECOMMENDED APPROACH: FAMA-FRENCH 3-FACTOR WITH NEWEY-WEST SEs")
print("="*80)

print(f"\nOur data: Monthly ETF returns (time-series)")
print(f"Sample: {df.index[0].strftime('%B %Y')} to {df.index[-1].strftime('%B %Y')}")
print(f"Number of observations: {len(df)}")

# Fit with Newey-West standard errors
lag_length = int(np.floor(4 * (len(df) / 100) ** (2/9)))
results_recommended = results.get_robustcov_results(cov_type='HAC', maxlags=lag_length, use_correction=True, use_t=False)

print(f"\nNewey-West lag length (sample-size bandwidth heuristic): {lag_length}")
print("\nFull Results with Newey-West HAC Standard Errors:")
print("="*80)
print(results_recommended.summary())

joint_test = results_recommended.wald_test(np.eye(4)[1:], use_f=False, scalar=True)
print(f"HAC joint Wald test of all slopes = 0: chi-square={float(joint_test.statistic):.3f}, p={float(joint_test.pvalue):.3g}")
print("HAC: Bartlett weights, n/(n-k) correction, asymptotic normal coefficient tests.")
print("Point estimates are unchanged; compare SEs and confidence intervals above.")
print("A beta measures conditional sensitivity, not the asset's total volatility.")
print("Non-significant alpha means insufficient evidence against zero, not proof of zero.")
================================================================================
RECOMMENDED APPROACH: FAMA-FRENCH 3-FACTOR WITH NEWEY-WEST SEs
================================================================================
Our data: Monthly ETF returns (time-series)
Sample: January 2010 to September 2026
Number of observations: 201
Newey-West lag length (sample-size bandwidth heuristic): 4
Full Results with Newey-West HAC Standard Errors:
================================================================================
OLS Regression Results
==============================================================================
Dep. Variable: y R-squared: 0.996
Model: OLS Adj. R-squared: 0.996
Method: Least Squares F-statistic: 1.313e+04
Date: Sat, 31 Oct 2026 Prob (F-statistic): 1.56e-226
Time: 17:06:03 Log-Likelihood: 917.70
No. Observations: 201 AIC: -1827.
Df Residuals: 197 BIC: -1814.
Df Model: 3
Covariance Type: HAC
==============================================================================
coef std err z P>|z| [0.025 0.975]
------------------------------------------------------------------------------
const -6.073e-06 0.000 -0.035 0.972 -0.000 0.000
x1 0.9850 0.005 184.512 0.000 0.975 0.995
x2 -0.1368 0.010 -14.323 0.000 -0.155 -0.118
x3 0.0132 0.007 1.952 0.051 -5.11e-05 0.026
==============================================================================
Omnibus: 33.723 Durbin-Watson: 1.739
Prob(Omnibus): 0.000 Jarque-Bera (JB): 87.953
Skew: 0.708 Prob(JB): 7.97e-20
Kurtosis: 5.915 Cond. No. 43.5
==============================================================================
Notes:
[1] Standard Errors are heteroscedasticity and autocorrelation robust (HAC) using 4 lags and with small sample correction
HAC joint Wald test of all slopes = 0: chi-square=39393.388, p=0
HAC: Bartlett weights, n/(n-k) correction, asymptotic normal coefficient tests.
Point estimates are unchanged; compare SEs and confidence intervals above.
A beta measures conditional sensitivity, not the asset's total volatility.
Non-significant alpha means insufficient evidence against zero, not proof of zero.
Section 10: Interpreting the Results — t-Statistics, p-Values, and Confidence Intervals
Now that we have reliable standard errors (Newey-West), we can properly interpret each coefficient and its statistical significance.
Why can we use the normal distribution for p-values here? A score-process CLT gives asymptotic normality under exogeneity, suitable moments, dependence conditions and a nonsingular regressor moment matrix; arbitrary error distributions are not covered. Combined with Newey-West and Slutsky’s theorem, the t-statistic converges to . For the full five-step argument, see the Statistical Foundations Tutorial, Section 4 (Subsections 4.7–4.8), which is then restated in the applied-inference context in Section 9.
Quick Refresher (detailed derivations: Statistical Foundations, Section 4)
| Statistic | Formula | Rule of thumb |
|---|---|---|
| t-statistic | $ | |
| p-value | Prob of result this extreme under | → reject |
| 95 % CI | CI excludes 0 → significant |
Statistical vs economic significance: A tiny but precisely estimated effect can be statistically significant (small ) without being economically meaningful. For example, (0.02 %/month ≈ 0.24 %/year) may matter statistically but is smaller than most transaction costs. Always ask: Is the magnitude large enough to matter in practice?
Interpreting the Fama-French Coefficients
| Coefficient | What it measures | Positive means | Negative means |
|---|---|---|---|
| (Jensen’s Alpha) | Abnormal return beyond factor exposure | Outperformance | Underperformance |
| Conditional market sensitivity | Moves with the market, holding other factors fixed | Moves against the market, holding other factors fixed | |
| Size tilt | Small-cap tilt | Large-cap tilt | |
| Value tilt | Value tilt | Growth tilt |
Let’s Now Interpret Our Fama-French Results Using Newey-West Standard Errors
# Interpret each coefficient using Newey-West robust standard errors
print("="*70)
print("DETAILED INTERPRETATION OF COEFFICIENTS (NEWEY-WEST SEs)")
print("="*70)

coef_nw = results_recommended.params
se_nw = results_recommended.bse
pval_nw = results_recommended.pvalues
ci_nw = results_recommended.conf_int()

# Extract each coefficient
alpha = coef_nw[0]
beta_mkt = coef_nw[1]
beta_smb = coef_nw[2]
beta_hml = coef_nw[3]

print(f"\n1. ALPHA (Jensen's Alpha)")
print(f"   Estimate: {alpha:.6f} ({alpha*100:.4f}% per month)")
print(f"   Newey-West Std Error: {se_nw[0]:.6f}")
print(f"   t-statistic: {alpha/se_nw[0]:.4f}")
print(f"   p-value: {pval_nw[0]:.4f}")
print(f"   95% CI: [{ci_nw[0, 0]:.6f}, {ci_nw[0, 1]:.6f}]")
print(f"   Interpretation: This is Jensen's alpha. It represents the abnormal")
print(f"   monthly return not explained by the three factors. A value of {alpha:.4f}")
print(f"   ({alpha*100:.2f}% per month) means this ETF earns an excess return of")
print(f"   {alpha*100:.2f}% per month beyond what the model predicts.")
if pval_nw[0] < 0.05:
    print(f"   STATISTICALLY SIGNIFICANT (p < 0.05): The ETF appears to have abnormal alpha.")
else:
    print(f"   NOT statistically significant (p >= 0.05): Cannot distinguish alpha from zero.")

print(f"\n2. BETA_MKT (Market Beta)")
print(f"   Estimate: {beta_mkt:.6f}")
print(f"   Newey-West Std Error: {se_nw[1]:.6f}")
print(f"   t-statistic: {beta_mkt/se_nw[1]:.4f}")
print(f"   p-value: {pval_nw[1]:.4f}")
print(f"   95% CI: [{ci_nw[1, 0]:.6f}, {ci_nw[1, 1]:.6f}]")
print(f"   Interpretation: For every 1% increase in the market excess return,")
print(f"   the ETF's excess return changes by {beta_mkt:.4f}% (holding other")
print(f"   factors constant). This is market sensitivity, not total volatility relative to")
print(f"   the market. Other factors and residual risk also contribute to volatility.")
if pval_nw[1] < 0.05:
    print(f"   STATISTICALLY SIGNIFICANT: Market exposure is real.")
else:
    print(f"   NOT statistically significant.")

print(f"\n3. BETA_SMB (Size Factor)")
print(f"   Estimate: {beta_smb:.6f}")
print(f"   Newey-West Std Error: {se_nw[2]:.6f}")
print(f"   t-statistic: {beta_smb/se_nw[2]:.4f}")
print(f"   p-value: {pval_nw[2]:.4f}")
print(f"   95% CI: [{ci_nw[2, 0]:.6f}, {ci_nw[2, 1]:.6f}]")
print(f"   Interpretation: For every 1% increase in the SMB factor (small")
print(f"   relative to big), the ETF's excess return changes by {beta_smb:.4f}%.")
print(f"   A positive value means the ETF tilts toward SMALL-cap exposure.")
print(f"   A negative value would mean it tilts toward LARGE-cap exposure.")
if pval_nw[2] < 0.05:
    print(f"   STATISTICALLY SIGNIFICANT: Real size effect exposure.")
else:
    print(f"   NOT statistically significant: Size effect not clearly present.")

print(f"\n4. BETA_HML (Value Factor)")
print(f"   Estimate: {beta_hml:.6f}")
print(f"   Newey-West Std Error: {se_nw[3]:.6f}")
print(f"   t-statistic: {beta_hml/se_nw[3]:.4f}")
print(f"   p-value: {pval_nw[3]:.4f}")
print(f"   95% CI: [{ci_nw[3, 0]:.6f}, {ci_nw[3, 1]:.6f}]")
print(f"   Interpretation: For every 1% increase in the HML factor (value")
print(f"   relative to growth), the ETF's excess return changes by {beta_hml:.4f}%.")
print(f"   A positive value means the ETF tilts toward VALUE exposure.")
print(f"   A negative value would mean it tilts toward GROWTH exposure.")
if pval_nw[3] < 0.05:
    print(f"   STATISTICALLY SIGNIFICANT: Real value effect exposure.")
else:
    print(f"   NOT statistically significant: Value effect not clearly present.")

print("\n" + "="*70)
print("KEY TAKEAWAY")
print("="*70)
print("""
All the standard errors, t-statistics, p-values, and confidence intervals
above use Newey-West HAC estimation. This means:

- They account for heteroscedasticity (time-varying volatility)
- They account for autocorrelation (serial dependence in returns)
- Robust covariance relaxes classical variance assumptions; finite-sample accuracy remains uncertain

When reporting Fama-French results:
  - Choose covariance assumptions explicitly and check HAC lag sensitivity
  - Report the lag length used (here: sample-size bandwidth heuristic)
  - Discuss economic significance separately from statistical significance
  - Compare with classic SEs as a robustness check
""")
======================================================================
DETAILED INTERPRETATION OF COEFFICIENTS (NEWEY-WEST SEs)
======================================================================
1. ALPHA (Jensen's Alpha)
Estimate: -0.000006 (-0.0006% per month)
Newey-West Std Error: 0.000174
t-statistic: -0.0348
p-value: 0.9722
95% CI: [-0.000348, 0.000336]
Interpretation: This is Jensen's alpha. It represents the abnormal
monthly return not explained by the three factors. A value of -0.0000
(-0.00% per month) means this ETF earns an excess return of
-0.00% per month beyond what the model predicts.
NOT statistically significant (p >= 0.05): Cannot distinguish alpha from zero.
2. BETA_MKT (Market Beta)
Estimate: 0.985004
Newey-West Std Error: 0.005338
t-statistic: 184.5117
p-value: 0.0000
95% CI: [0.974541, 0.995467]
Interpretation: For every 1% increase in the market excess return,
the ETF's excess return changes by 0.9850% (holding other
factors constant). This is market sensitivity, not total volatility relative to
the market. Other factors and residual risk also contribute to volatility.
STATISTICALLY SIGNIFICANT: Market exposure is real.
3. BETA_SMB (Size Factor)
Estimate: -0.136763
Newey-West Std Error: 0.009549
t-statistic: -14.3227
p-value: 0.0000
95% CI: [-0.155478, -0.118048]
Interpretation: For every 1% increase in the SMB factor (small
relative to big), the ETF's excess return changes by -0.1368%.
A positive value means the ETF tilts toward SMALL-cap exposure.
A negative value would mean it tilts toward LARGE-cap exposure.
STATISTICALLY SIGNIFICANT: Real size effect exposure.
4. BETA_HML (Value Factor)
Estimate: 0.013152
Newey-West Std Error: 0.006737
t-statistic: 1.9524
p-value: 0.0509
95% CI: [-0.000051, 0.026356]
Interpretation: For every 1% increase in the HML factor (value
relative to growth), the ETF's excess return changes by 0.0132%.
A positive value means the ETF tilts toward VALUE exposure.
A negative value would mean it tilts toward GROWTH exposure.
NOT statistically significant: Value effect not clearly present.
======================================================================
KEY TAKEAWAY
======================================================================
All the standard errors, t-statistics, p-values, and confidence intervals
above use Newey-West HAC estimation. This means:
- They account for heteroscedasticity (time-varying volatility)
- They account for autocorrelation (serial dependence in returns)
- Robust covariance relaxes classical variance assumptions; finite-sample accuracy remains uncertain
When reporting Fama-French results:
- Choose covariance assumptions explicitly and check HAC lag sensitivity
- Report the lag length used (here: sample-size bandwidth heuristic)
- Discuss economic significance separately from statistical significance
- Compare with classic SEs as a robustness check
Section 11: Complete Worked Example - Using the Model to Make Predictions
Now let’s use our fitted model to make a prediction and see how the model works in practice.
The Prediction Formula
For any month with known factor values, we can predict the ETF’s excess return using:
Let’s make a prediction for a specific month and compare it to the actual return.
This is an in-sample conditional fitted value, using realized factors and coefficients estimated on the full sample. It is not a forecast made before the month began and does not measure out-of-sample predictive performance.
print("="*70)
print("WORKED EXAMPLE: PREDICTING ETF RETURN FOR A SPECIFIC MONTH")
print("="*70)

# Let's use the first month in our data
month_idx = 50  # Choose a month in the middle of data
date = df.index[month_idx]

# Get the actual values for this month
mkt_rf_actual = df['Mkt_RF'].iloc[month_idx]
smb_actual = df['SMB'].iloc[month_idx]
hml_actual = df['HML'].iloc[month_idx]
stock_return_actual = df['Stock_Excess_Return'].iloc[month_idx]

print(f"\nDate: {date.strftime('%B %Y')}")
print(f"\nFactor values for this month:")
print(f"  Market Risk Premium (Mkt_RF): {mkt_rf_actual:.4f} ({mkt_rf_actual*100:.2f}%)")
print(f"  SMB Factor:                    {smb_actual:.4f} ({smb_actual*100:.2f}%)")
print(f"  HML Factor:                    {hml_actual:.4f} ({hml_actual*100:.2f}%)")

# Get our estimated coefficients
alpha_hat = results.params[0]
beta_mkt_hat = results.params[1]
beta_smb_hat = results.params[2]
beta_hml_hat = results.params[3]

print(f"\nOur estimated model coefficients:")
print(f"  α̂ (Alpha):     {alpha_hat:.6f}")
print(f"  β̂_MKT:         {beta_mkt_hat:.6f}")
print(f"  β̂_SMB:         {beta_smb_hat:.6f}")
print(f"  β̂_HML:         {beta_hml_hat:.6f}")

# Make the prediction manually showing all steps
print(f"\n" + "="*70)
print("PREDICTION CALCULATION (STEP BY STEP)")
print("="*70)

print(f"\nFormula: R̂_i = α̂ + β̂_MKT × Mkt_RF + β̂_SMB × SMB + β̂_HML × HML")
print(f"\nR̂_i = {alpha_hat:.6f}")
print(f"     + {beta_mkt_hat:.6f} × {mkt_rf_actual:.6f}")
print(f"     + {beta_smb_hat:.6f} × {smb_actual:.6f}")
print(f"     + {beta_hml_hat:.6f} × {hml_actual:.6f}")

# Calculate each component
component_alpha = alpha_hat
component_mkt = beta_mkt_hat * mkt_rf_actual
component_smb = beta_smb_hat * smb_actual
component_hml = beta_hml_hat * hml_actual

print(f"\nComponent breakdown:")
print(f"  α̂:                    {component_alpha:.6f} ({component_alpha*100:.4f}%)")
print(f"  β̂_MKT × Mkt_RF:       {component_mkt:.6f} ({component_mkt*100:.4f}%)")
print(f"  β̂_SMB × SMB:          {component_smb:.6f} ({component_smb*100:.4f}%)")
print(f"  β̂_HML × HML:          {component_hml:.6f} ({component_hml*100:.4f}%)")

# Total prediction
stock_return_pred = component_alpha + component_mkt + component_smb + component_hml

print(f"\nPredicted return (sum): {stock_return_pred:.6f} ({stock_return_pred*100:.4f}%)")
print(f"Actual return:          {stock_return_actual:.6f} ({stock_return_actual*100:.4f}%)")

# Calculate prediction error (residual)
residual = stock_return_actual - stock_return_pred
print(f"\nPrediction error (residual): {residual:.6f} ({residual*100:.4f}%)")
print(f"\nInterpretation:")
if abs(residual) < 0.01:
    print(f"  The model predicted very accurately for this month!")
elif residual > 0:
    print(f"  The ETF OUTPERFORMED the model's prediction by {abs(residual)*100:.4f}%")
    print(f"  This positive residual means the ETF did better than expected")
    print(f"  given its exposure to the three factors.")
else:
    print(f"  The ETF UNDERPERFORMED the model's prediction by {abs(residual)*100:.4f}%")
    print(f"  This negative residual means the ETF did worse than expected")
    print(f"  given its exposure to the three factors.")

# Verify using statsmodels
pred_check = results.fittedvalues[month_idx]
pred_error_check = results.resid[month_idx]
print(f"\nVerification with statsmodels:")
print(f"  Fitted value from statsmodels:  {pred_check:.6f}")
print(f"  Residual from statsmodels:      {pred_error_check:.6f}")
print(f"  Match? {np.isclose(stock_return_pred, pred_check) and np.isclose(residual, pred_error_check)}")
======================================================================
WORKED EXAMPLE: PREDICTING ETF RETURN FOR A SPECIFIC MONTH
======================================================================
Date: March 2014
Factor values for this month:
Market Risk Premium (Mkt_RF): 0.0043 (0.43%)
SMB Factor: -0.0186 (-1.86%)
HML Factor: 0.0490 (4.90%)
Our estimated model coefficients:
α̂ (Alpha): -0.000006
β̂_MKT: 0.985004
β̂_SMB: -0.136763
β̂_HML: 0.013152
======================================================================
PREDICTION CALCULATION (STEP BY STEP)
======================================================================
Formula: R̂_i = α̂ + β̂_MKT × Mkt_RF + β̂_SMB × SMB + β̂_HML × HML
R̂_i = -0.000006
+ 0.985004 × 0.004300
+ -0.136763 × -0.018600
+ 0.013152 × 0.049000
Component breakdown:
α̂: -0.000006 (-0.0006%)
β̂_MKT × Mkt_RF: 0.004236 (0.4236%)
β̂_SMB × SMB: 0.002544 (0.2544%)
β̂_HML × HML: 0.000644 (0.0644%)
Predicted return (sum): 0.007418 (0.7418%)
Actual return: 0.008295 (0.8295%)
Prediction error (residual): 0.000877 (0.0877%)
Interpretation:
The model predicted very accurately for this month!
Verification with statsmodels:
Fitted value from statsmodels: 0.007418
Residual from statsmodels: 0.000877
Match? True
Source
# Visualize predictions vs actual returns
fig, axes = plt.subplots(2, 1, figsize=(14, 8))

# Plot 1: Actual vs Predicted
axes[0].plot(df.index, df['Stock_Excess_Return']*100, label='Actual Returns',
             linewidth=2, alpha=0.7, color='darkblue')
axes[0].plot(df.index, results.fittedvalues*100, label='In-sample fitted values',
             linewidth=2, alpha=0.7, color='darkred', linestyle='--')
axes[0].set_ylabel('Return (%)', fontsize=11)
axes[0].set_title('Actual vs In-Sample Fitted ETF Excess Returns', fontsize=12, fontweight='bold')
axes[0].legend(fontsize=10)
axes[0].grid(True, alpha=0.3)

# Plot 2: Residuals (prediction errors)
axes[1].bar(df.index, results.resid*100, alpha=0.7, color='steelblue', width=20)
axes[1].axhline(y=0, color='r', linestyle='--', linewidth=2)
axes[1].set_ylabel('Residual (%)', fontsize=11)
axes[1].set_xlabel('Date', fontsize=11)
axes[1].set_title('In-Sample Residuals Over Time', fontsize=12, fontweight='bold')
axes[1].grid(True, alpha=0.3, axis='y')

plt.tight_layout()
plt.show()

print("Prediction visualization created.")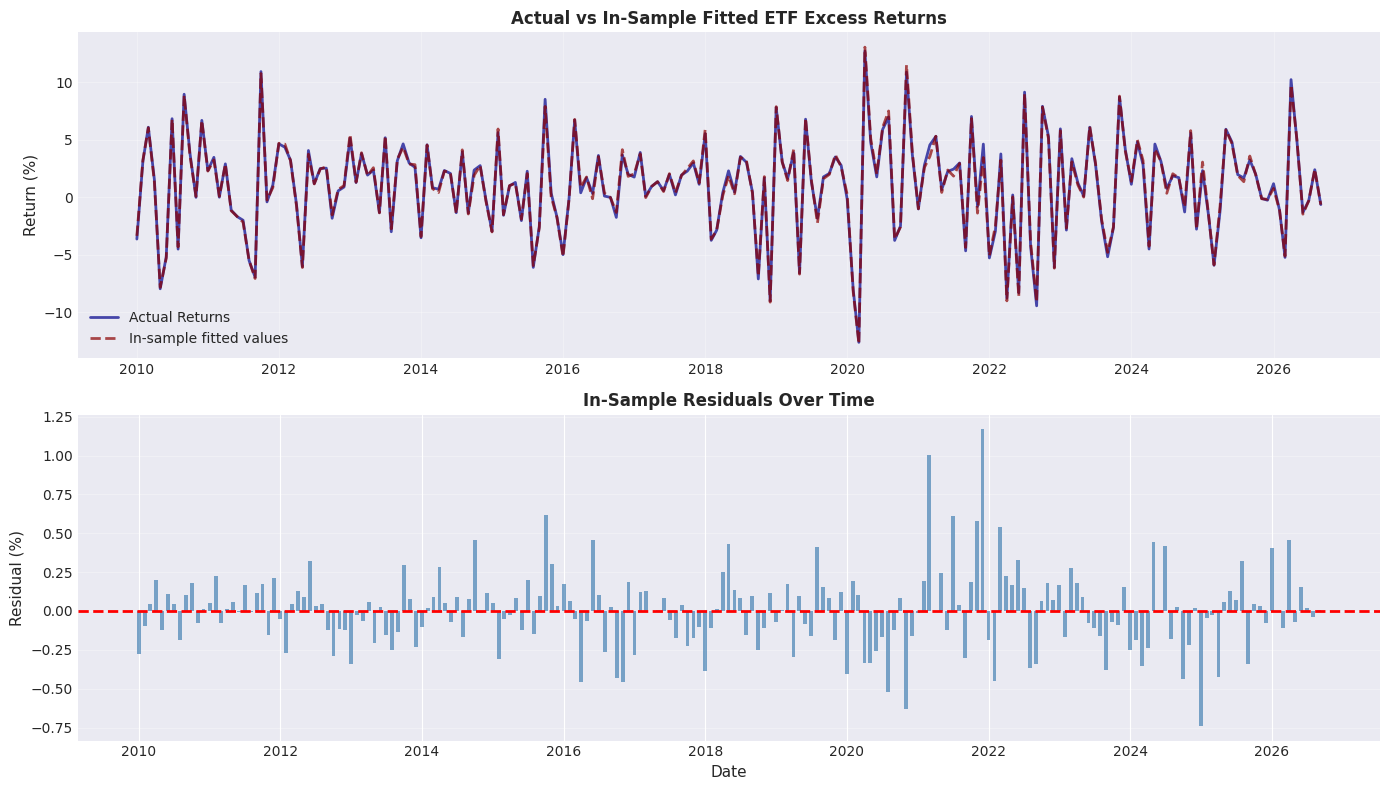
Prediction visualization created.
What the three-fund comparison teaches
SPY, IWN and VTV separate broad equity exposure from size and value tilts. Compare their estimated coefficients and intervals, then their alphas under the same model and sample. High R² means that the factors describe much of a fund’s return variation; it does not mean the fund has a higher expected return.
The reusable function below collects the same steps in one place. Use it for the exercises, preserving the units, dates and covariance assumptions. The next chapter asks whether this three-factor benchmark omits economically relevant information.
Appendix: Reusing the data workflow
from analysis_utils import load_french, load_prices, monthly_returns, fit_hac
ff = load_french('F-F_Research_Data_Factors_CSV.zip', start='2010-01-01')
r = monthly_returns(load_prices('AAPL')).rename('Return')
d = ff.join(r, how='inner').dropna()
res = fit_hac(d['Return'] - d['RF'], d[['Mkt-RF', 'SMB', 'HML']])
print(res.summary())
Match the investment universe, currency, return frequency and sample before fitting. US listing alone does not imply US stock exposure. French supplies Developed, Europe and Emerging Markets datasets; use the definitions in the Data Library.
Report sample dates, N, units, factor version, estimates and intervals, covariance method and lag length, and sensitivity to specification. A low R², large p-value or rejected diagnostic each requires investigation, not automatic variable selection or outlier deletion.
# ============================================================================
# REUSABLE FAMA-FRENCH ANALYSIS TEMPLATE
# ============================================================================
# Use this template as a starting point for analyzing your own stock/portfolio
# ============================================================================

def fama_french_analysis(stock_excess_returns, mkt_rf, smb, hml, stock_name="Stock", use_robust_se=True):
    """
    Complete Fama-French 3-factor analysis in one function.

    Parameters:
    -----------
    stock_excess_returns : array-like
        Excess returns of the stock/portfolio (length n)
    mkt_rf : array-like
        Market risk premium (length n)
    smb : array-like
        SMB factor returns (length n)
    hml : array-like
        HML factor returns (length n)
    stock_name : str
        Name of the stock for display purposes
    use_robust_se : bool
        If True, use Newey-West HAC standard errors (recommended for time-series)
        If False, use classic OLS standard errors

    Returns:
    --------
    results : OLS regression results object (always the same type)
    """

    print("="*70)
    print(f"FAMA-FRENCH 3-FACTOR ANALYSIS: {stock_name}")
    print("="*70)

    # Prepare data
    y = np.array(stock_excess_returns)
    X = np.column_stack([mkt_rf, smb, hml])
    X = sm.add_constant(X)

    # Fit model
    model = sm.OLS(y, X)
    r = model.fit()

    # Apply robust standard errors if requested
    if use_robust_se:
        n_obs = len(y)
        lag_length = int(np.floor(4 * (n_obs / 100) ** (2/9)))
        r = r.get_robustcov_results(cov_type='HAC', maxlags=lag_length, use_correction=True, use_t=False)
        se_type = f"Newey-West HAC (lags={lag_length})"
    else:
        se_type = "Classic OLS"

    # Print summary
    print(f"\nUsing {se_type} standard errors\n")
    print(r.summary())

    # Extract key statistics
    print("\n" + "="*70)
    print("KEY FINDINGS")
    print("="*70)

    alpha, beta_mkt, beta_smb, beta_hml = r.params
    p_vals = r.pvalues

    print(f"\nalpha:     {alpha:9.6f}  p-value: {p_vals[0]:.4f}  {'***' if p_vals[0] < 0.01 else ('**' if p_vals[0] < 0.05 else '')}")
    print(f"beta_mkt:  {beta_mkt:9.6f}  p-value: {p_vals[1]:.4f}  {'***' if p_vals[1] < 0.01 else ('**' if p_vals[1] < 0.05 else '')}")
    print(f"beta_smb:  {beta_smb:9.6f}  p-value: {p_vals[2]:.4f}  {'***' if p_vals[2] < 0.01 else ('**' if p_vals[2] < 0.05 else '')}")
    print(f"beta_hml:  {beta_hml:9.6f}  p-value: {p_vals[3]:.4f}  {'***' if p_vals[3] < 0.01 else ('**' if p_vals[3] < 0.05 else '')}")

    print(f"\nR-squared: {r.rsquared:.6f}")
    print(f"Adj R-squared: {r.rsquared_adj:.6f}")
    print(f"F-statistic: {r.fvalue:.4f} (p < {r.f_pvalue:.2e})")

    print("\nNote: *** p<0.01, ** p<0.05, * p<0.10")

    return r

# ============================================================================
# COMPARISON OF ALL THREE ETFs
# ============================================================================
print("\n" + "#"*70)
print("# COMPARING FACTOR EXPOSURES: SPY vs. IWN vs. VTV")
print("#"*70)
print()
print("We now run the same Fama-French regression on all three ETFs and")
print("compare their factor loadings. This reveals how each investment")
print("style maps onto the market, size, and value dimensions.\n")

all_results = {}
for ticker, label in etf_tickers.items():
    edf = etf_dataframes[ticker]
    res = fama_french_analysis(
        edf['Stock_Excess_Return'].values,
        edf['Mkt_RF'].values,
        edf['SMB'].values,
        edf['HML'].values,
        stock_name=label,
        use_robust_se=True
    )
    all_results[ticker] = res
    print("\n")

# Summary comparison table
print("="*70)
print("SIDE-BY-SIDE FACTOR LOADING COMPARISON")
print("="*70)

header = f"{'':20s}  {'SPY':>10s}  {'IWN':>10s}  {'VTV':>10s}"
print(header)
print("-" * len(header))

labels_short = list(etf_tickers.keys())
row_names = ['Alpha (a)', 'Beta MKT', 'Beta SMB', 'Beta HML', 'R-squared', 'Adj R-squared']

for i, name in enumerate(row_names):
    vals = []
    for t in labels_short:
        r = all_results[t]
        if i < 4:
            vals.append(f"{r.params[i]:10.4f}")
        elif i == 4:
            vals.append(f"{r.rsquared:10.4f}")
        else:
            vals.append(f"{r.rsquared_adj:10.4f}")
    print(f"{name:20s}  {'  '.join(vals)}")

# Significance markers
print()
for i, name in enumerate(['Alpha', 'Beta MKT', 'Beta SMB', 'Beta HML']):
    sigs = []
    for t in labels_short:
        p = all_results[t].pvalues[i]
        star = '***' if p < 0.01 else ('**' if p < 0.05 else ('*' if p < 0.10 else ''))
        sigs.append(f"{star:>10s}")
    print(f"{'  p-sig ' + name:20s}  {'  '.join(sigs)}")

print("\n" + "="*70)
print("INTERPRETATION")
print("="*70)
print("""
What to look for in the table above:

- SPY (S&P 500): Should have beta_MKT very close to 1.0, with low/insignificant
  SMB and HML loadings. It tracks large US companies, whereas the French market includes smaller stocks.
  Meaningful style loadings can remain. Expect high R-squared.

- IWN (Small Cap Value): Should have POSITIVE beta_SMB (small-cap tilt) AND
  POSITIVE beta_HML (value tilt). This ETF explicitly targets small companies
  with high book-to-market ratios -- exactly the stocks that drive the SMB
  and HML factors.

- VTV (Large Cap Value): Should have near-zero or NEGATIVE beta_SMB (large-cap)
  and POSITIVE beta_HML (value tilt). This isolates the value effect from
  the size effect, showing that HML captures something distinct from SMB.
""")
######################################################################
# COMPARING FACTOR EXPOSURES: SPY vs. IWN vs. VTV
######################################################################

We now run the same Fama-French regression on all three ETFs and
compare their factor loadings. This reveals how each investment
style maps onto the market, size, and value dimensions.

======================================================================
FAMA-FRENCH 3-FACTOR ANALYSIS: SPY (S&P 500)
======================================================================

Using Newey-West HAC (lags=4) standard errors

                            OLS Regression Results
==============================================================================
Dep. Variable:                      y   R-squared:                       0.996
Model:                            OLS   Adj. R-squared:                  0.996
Method:                 Least Squares   F-statistic:                 1.313e+04
Date:                Sat, 31 Oct 2026   Prob (F-statistic):          1.56e-226
Time:                        17:06:03   Log-Likelihood:                 917.70
No. Observations:                 201   AIC:                            -1827.
Df Residuals:                     197   BIC:                            -1814.
Df Model:                           3
Covariance Type:                  HAC
==============================================================================
                 coef    std err          z      P>|z|      [0.025      0.975]
------------------------------------------------------------------------------
const      -6.073e-06      0.000     -0.035      0.972      -0.000       0.000
x1             0.9850      0.005    184.512      0.000       0.975       0.995
x2            -0.1368      0.010    -14.323      0.000      -0.155      -0.118
x3             0.0132      0.007      1.952      0.051   -5.11e-05       0.026
==============================================================================
Omnibus:                       33.723   Durbin-Watson:                   1.739
Prob(Omnibus):                  0.000   Jarque-Bera (JB):               87.953
Skew:                           0.708   Prob(JB):                     7.97e-20
Kurtosis:                       5.915   Cond. No.                         43.5
==============================================================================

Notes:
[1] Standard Errors are heteroscedasticity and autocorrelation robust (HAC) using 4 lags and with small sample correction

======================================================================
KEY FINDINGS
======================================================================

alpha:     -0.000006  p-value: 0.9722
beta_mkt:   0.985004  p-value: 0.0000  ***
beta_smb:  -0.136763  p-value: 0.0000  ***
beta_hml:   0.013152  p-value: 0.0509

R-squared: 0.996282
Adj R-squared: 0.996225
F-statistic: 13131.1294 (p < 1.56e-226)

Note: *** p<0.01, ** p<0.05, * p<0.10


======================================================================
FAMA-FRENCH 3-FACTOR ANALYSIS: IWN (Small Cap Value)
======================================================================

Using Newey-West HAC (lags=4) standard errors

                            OLS Regression Results
==============================================================================
Dep. Variable:                      y   R-squared:                       0.982
Model:                            OLS   Adj. R-squared:                  0.982
Method:                 Least Squares   F-statistic:                     3108.
Date:                Sat, 31 Oct 2026   Prob (F-statistic):          1.41e-165
Time:                        17:06:03   Log-Likelihood:                 698.03
No. Observations:                 201   AIC:                            -1388.
Df Residuals:                     197   BIC:                            -1375.
Df Model:                           3
Covariance Type:                  HAC
==============================================================================
                 coef    std err          z      P>|z|      [0.025      0.975]
------------------------------------------------------------------------------
const         -0.0011      0.001     -1.852      0.064      -0.002    6.26e-05
x1             0.9749      0.015     66.738      0.000       0.946       1.004
x2             0.8255      0.029     28.653      0.000       0.769       0.882
x3             0.5263      0.022     23.625      0.000       0.483       0.570
==============================================================================
Omnibus:                        5.348   Durbin-Watson:                   1.919
Prob(Omnibus):                  0.069   Jarque-Bera (JB):                7.234
Skew:                          -0.115   Prob(JB):                       0.0269
Kurtosis:                       3.900   Cond. No.                         43.5
==============================================================================

Notes:
[1] Standard Errors are heteroscedasticity and autocorrelation robust (HAC) using 4 lags and with small sample correction

======================================================================
KEY FINDINGS
======================================================================

alpha:     -0.001073  p-value: 0.0640
beta_mkt:   0.974912  p-value: 0.0000  ***
beta_smb:   0.825485  p-value: 0.0000  ***
beta_hml:   0.526309  p-value: 0.0000  ***

R-squared: 0.982417
Adj R-squared: 0.982149
F-statistic: 3108.2145 (p < 1.41e-165)

Note: *** p<0.01, ** p<0.05, * p<0.10


======================================================================
FAMA-FRENCH 3-FACTOR ANALYSIS: VTV (Large Cap Value)
======================================================================

Using Newey-West HAC (lags=4) standard errors

                            OLS Regression Results
==============================================================================
Dep. Variable:                      y   R-squared:                       0.937
Model:                            OLS   Adj. R-squared:                  0.936
Method:                 Least Squares   F-statistic:                     849.5
Date:                Sat, 31 Oct 2026   Prob (F-statistic):          2.16e-112
Time:                        17:06:03   Log-Likelihood:                 639.39
No. Observations:                 201   AIC:                            -1271.
Df Residuals:                     197   BIC:                            -1258.
Df Model:                           3
Covariance Type:                  HAC
==============================================================================
                 coef    std err          z      P>|z|      [0.025      0.975]
------------------------------------------------------------------------------
const       8.819e-06      0.001      0.014      0.989      -0.001       0.001
x1             0.8681      0.022     39.563      0.000       0.825       0.911
x2            -0.0915      0.029     -3.140      0.002      -0.149      -0.034
x3             0.3796      0.027     14.271      0.000       0.327       0.432
==============================================================================
Omnibus:                        5.161   Durbin-Watson:                   2.044
Prob(Omnibus):                  0.076   Jarque-Bera (JB):                7.378
Skew:                          -0.026   Prob(JB):                       0.0250
Kurtosis:                       3.937   Cond. No.                         43.5
==============================================================================

Notes:
[1] Standard Errors are heteroscedasticity and autocorrelation robust (HAC) using 4 lags and with small sample correction

======================================================================
KEY FINDINGS
======================================================================

alpha:      0.000009  p-value: 0.9890
beta_mkt:   0.868123  p-value: 0.0000  ***
beta_smb:  -0.091525  p-value: 0.0017  ***
beta_hml:   0.379632  p-value: 0.0000  ***

R-squared: 0.937001
Adj R-squared: 0.936041
F-statistic: 849.5143 (p < 2.16e-112)

Note: *** p<0.01, ** p<0.05, * p<0.10


======================================================================
SIDE-BY-SIDE FACTOR LOADING COMPARISON
======================================================================
                             SPY         IWN         VTV
--------------------------------------------------------
Alpha (a)                -0.0000     -0.0011      0.0000
Beta MKT                  0.9850      0.9749      0.8681
Beta SMB                 -0.1368      0.8255     -0.0915
Beta HML                  0.0132      0.5263      0.3796
R-squared                 0.9963      0.9824      0.9370
Adj R-squared             0.9962      0.9821      0.9360

  p-sig Alpha                              *
  p-sig Beta MKT             ***         ***         ***
  p-sig Beta SMB             ***         ***         ***
  p-sig Beta HML               *         ***         ***

======================================================================
INTERPRETATION
======================================================================

What to look for in the table above:

- SPY (S&P 500): Should have beta_MKT very close to 1.0, with low/insignificant
  SMB and HML loadings. It tracks large US companies, whereas the French market includes smaller stocks.
  Meaningful style loadings can remain. Expect high R-squared.

- IWN (Small Cap Value): Should have POSITIVE beta_SMB (small-cap tilt) AND
  POSITIVE beta_HML (value tilt). This ETF explicitly targets small companies
  with high book-to-market ratios -- exactly the stocks that drive the SMB
  and HML factors.

- VTV (Large Cap Value): Should have near-zero or NEGATIVE beta_SMB (large-cap)
  and POSITIVE beta_HML (value tilt). This isolates the value effect from
  the size effect, showing that HML captures something distinct from SMB.
Source
# ============================================================================
# VISUALIZE FACTOR LOADINGS ACROSS ALL THREE ETFs
# ============================================================================

fig, ax = plt.subplots(figsize=(10, 6))

var_names_bar = ['Beta MKT', 'Beta SMB', 'Beta HML']
x_pos = np.arange(len(var_names_bar))
width = 0.25
colors_bar = {'SPY': 'darkblue', 'IWN': 'darkorange', 'VTV': 'darkgreen'}

for i, (ticker, label) in enumerate(etf_tickers.items()):
    r = all_results[ticker]
    betas = [r.params[1], r.params[2], r.params[3]]  # MKT, SMB, HML
    pvals = [r.pvalues[1], r.pvalues[2], r.pvalues[3]]
    bars = ax.bar(x_pos + i * width, betas, width, label=label,
                  color=colors_bar[ticker], alpha=0.85)
    # Add significance stars
    for j, bar in enumerate(bars):
        p = pvals[j]
        star = '***' if p < 0.01 else ('**' if p < 0.05 else ('*' if p < 0.10 else ''))
        if star:
            ax.text(bar.get_x() + bar.get_width()/2, bar.get_height(),
                    star, ha='center', va='bottom', fontsize=9)

ax.set_xticks(x_pos + width)
ax.set_xticklabels(var_names_bar)
ax.set_ylabel('Factor Loading (β)')
ax.set_title('Fama-French 3-Factor Loadings: SPY vs IWN vs VTV\n'
             '(*** p<0.01, ** p<0.05, * p<0.10 — Newey-West SEs)',
             fontweight='bold', fontsize=12)
ax.axhline(0, color='black', linewidth=0.5)
ax.legend()
ax.grid(True, alpha=0.3, axis='y')

plt.tight_layout()
plt.show()

print("""
This chart makes the factor exposures immediately visible:
- SPY: Compare its market and style loadings; the S&P 500 is not the full CRSP market
- IWN: Positive loadings on ALL three factors, especially SMB and HML
- VTV: Strong market and value exposure, but low/negative size exposure
""")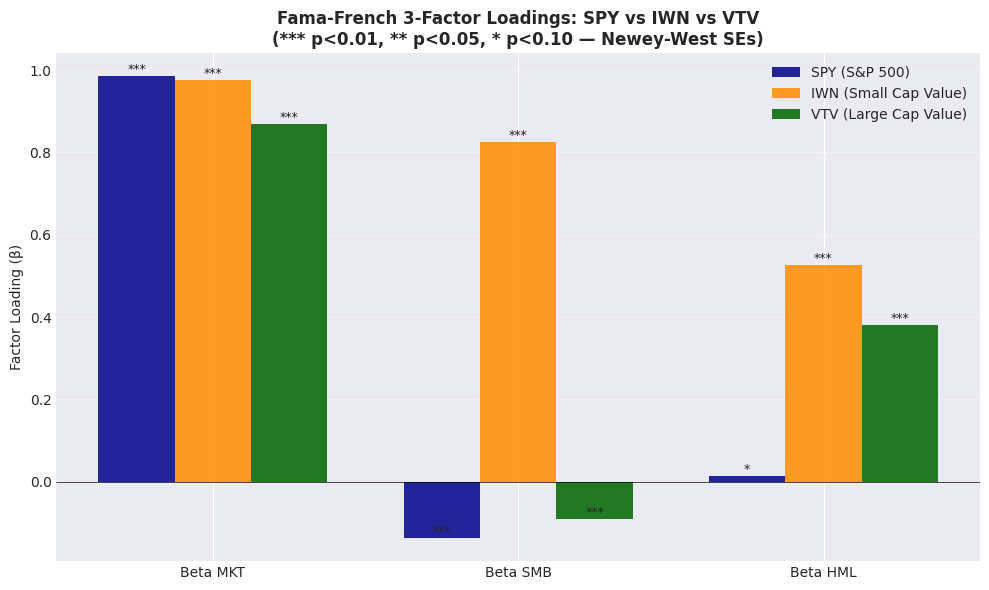
This chart makes the factor exposures immediately visible:
- SPY: Compare its market and style loadings; the S&P 500 is not the full CRSP market
- IWN: Positive loadings on ALL three factors, especially SMB and HML
- VTV: Strong market and value exposure, but low/negative size exposure
Exercises
Test your understanding by working through these exercises. They range from conceptual questions to hands-on coding tasks.
Exercise 1: Predicting Factor Loadings (Conceptual)
Before running any code, predict the factor loadings for the following hypothetical ETFs. For each, state whether you expect , , and to be positive, negative, or near zero, and briefly explain why.
QQQ (Invesco Nasdaq-100 ETF) -- tracks large-cap US technology/growth stocks
IWM (iShares Russell 2000 ETF) -- tracks US small-cap stocks (no value/growth tilt)
A leveraged 2x S&P 500 ETF
Exercise 2: Comparing ETFs (Hands-On)
Using the fama_french_analysis() template function defined above:
Re-run the analysis for IWN (Small Cap Value) only. Is the higher or lower than for SPY? Why might that be?
Compare the values between SPY, IWN, and VTV. Do they match your intuition about each fund’s size exposure?
Hint: The data is already loaded in etf_dataframes. You can access it as etf_dataframes['IWN'].
Exercise 3: Sensitivity of Newey-West Standard Errors (Hands-On)
The Newey-West lag length affects the standard errors. Try the following:
Re-fit the SPY regression using
maxlags=0(no autocorrelation correction, only heteroscedasticity). How do the standard errors compare to classic OLS?Re-fit using
maxlags=8(more lags). How do the standard errors change compared to the default lag length?What does this tell you about the sensitivity of your conclusions to lag choice?
# Starter code for Exercise 3:
model_ex3 = sm.OLS(df['Stock_Excess_Return'].values, sm.add_constant(df[['Mkt_RF', 'SMB', 'HML']].values))
results_ex3 = model_ex3.fit()

# Try different lag lengths:
results_lag0 = results_ex3.get_robustcov_results(cov_type='HAC', maxlags=0, use_correction=True, use_t=False)
results_lag8 = results_ex3.get_robustcov_results(cov_type='HAC', maxlags=8, use_correction=True, use_t=False)

print("Lag 0 SEs:", results_lag0.bse)
print("Lag 8 SEs:", results_lag8.bse)
Exercise 4: Economic vs. Statistical Significance (Discussion)
Suppose you find that (0.03% per month) with a p-value of 0.04.
Is this result statistically significant at the 5% level?
Is it economically significant? (Hint: What does 0.03% per month translate to annually? Would an investor change their portfolio based on this?)
What might happen to the p-value if you used Newey-West standard errors instead of classic OLS?
Exercise 5: Extending to Another Asset (Challenge)
Download return data for a stock or ETF of your choice and run the full Fama-French 3-factor analysis:
Download the data using
yfinanceCompute monthly excess returns
Run the regression with Newey-West standard errors
Interpret the coefficients -- what does the asset’s factor exposure tell you about its risk characteristics?
Check the diagnostic plots -- are the regression assumptions satisfied?
# Starter code for Exercise 5:
# Replace 'AAPL' with any US-listed ticker
import yfinance as yf
my_returns = monthly_returns(load_prices('AAPL')).loc['2010-01-01':]
# ... compute monthly returns, align with ff_factors, and run fama_french_analysis()
From three factors to the next question
You can now estimate exposures, report uncertainty, and distinguish within-sample fit from a pricing claim. If a value fund has nonzero alpha, one possibility is that the benchmark omits relevant exposures. Another is sampling noise.
Chapter 4 asks what profitability, investment and momentum add, beginning with the economics of valuation rather than simply adding regressors. Return to the solutions after attempting the exercises above.