Question: Why do the dates and dependence structure of returns change how we estimate uncertainty?
Chapter 1 derived estimators and sampling uncertainty. Here we examine the environment in which asset-pricing regressions are fitted: return transformations, stationarity, autocorrelation, volatility clustering, ergodicity and mixing. The examples use monthly Fama–French data, turning abstract assumptions into questions we can investigate.
By the end you should be able to interpret ADF, ACF/PACF, Ljung–Box and ARCH results; explain why uncorrelated observations can still be dependent; and identify which assumptions remain unverified after plotting the data.
Prerequisite: the CLT, regression and covariance-estimation ideas in Chapter 1. This chapter motivates the checks used before and after the fund regressions in Chapter 3. Sample coverage is reported with the data; Data and methods explains the conventions.
Previous: Statistical foundations · Next: The three-factor model
Source
# ============================================================================
# Setup: Import libraries and download Fama-French factor data
# ============================================================================

import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
from scipy import stats
import statsmodels.api as sm
from statsmodels.tsa.stattools import acf, pacf, adfuller
from statsmodels.stats.diagnostic import acorr_ljungbox


try:
    plt.style.use('seaborn-v0_8-darkgrid')
except OSError:
    plt.style.use('default')
plt.rcParams["font.family"] = "DejaVu Sans"

np.random.seed(42)

from analysis_utils import AS_OF, END_EXCLUSIVE, load_french, load_prices, coverage
ff3 = load_french('F-F_Research_Data_Factors_CSV.zip', start='2000-01-01')
coverage('US FF3 monthly (decimal returns)', ff3)
print(ff3.head())
US FF3 monthly (decimal returns): 321 observations, 2000-01-01 to 2026-09-01; as of 2026-10-31
Mkt-RF SMB HML RF
Date
2000-01-01 -0.0474 0.0512 -0.0110 0.0041
2000-02-01 0.0246 0.2134 -0.0973 0.0043
2000-03-01 0.0521 -0.1739 0.0848 0.0047
2000-04-01 -0.0639 -0.0603 0.0645 0.0046
2000-05-01 -0.0439 -0.0607 0.0458 0.0050
Section 1: Prices vs. Returns — Why We Transform the Data
1.1 The Problem with Prices
Price levels can change persistently over time, so a stationary regression model cannot be applied to them without justification. Below we construct a total-return market index from the released factor data and compare its behaviour with returns. A higher price level does not itself prove nonstationarity; the model and diagnostics matter.
Many models treat stock-price levels as nonstationary. The simple stationary LLN/CLT framework used here is then inappropriate for levels; more specialised nonstationary methods would be needed. Transforming prices into returns makes a stationary model more plausible without establishing it.
1.2 The Solution: Returns
The simple return over one period is:
The log return (continuously compounded return) is:
For small returns, (by the Taylor expansion ). The Fama-French factors are reported as simple returns.
Why returns are a useful starting point:
Returns are scale-free: a 2% return in 2003 and a 2% return in 2023 are directly comparable, even though the price levels differ by a factor of 5.
Returns can be modelled as approximately stationary over some windows. Stable moments remain a working assumption to examine, not an automatic consequence of differencing.
Log returns are additive: the multi-period log return is . This makes aggregation clean.
1.3 Excess Returns
In asset pricing, we typically work with excess returns:
where is the risk-free rate (e.g., 1-month Treasury bill rate). This is what the Fama-French factors represent: Mkt-RF is the market excess return.
An excess return is a realised return relative to the risk-free asset. Its expectation is the corresponding expected premium; an individual month also contains unexpected news.
Source
# ============================================================================
# Section 1: Prices vs. Returns — Visual demonstration
# ============================================================================

# Construct a cumulative "price" series from the market excess returns
mkt = ff3['Mkt-RF']
cumulative_price = (1 + mkt + ff3['RF']).cumprod() * 100  # Start at 100

fig, axes = plt.subplots(2, 2, figsize=(16, 8))

# --- Top left: Cumulative "price" level ---
ax = axes[0, 0]
ax.plot(cumulative_price.index, cumulative_price.values, color='#2c3e50', linewidth=1.2)
ax.set_title('Market Total-Return Index (initial value $100)', fontweight='bold', fontsize=12)
ax.set_ylabel('Value ($)')
ax.grid(True, alpha=0.3)

# --- Top right: Monthly returns ---
ax = axes[0, 1]
ax.bar(mkt.index, mkt.values, color=np.where(mkt >= 0, '#2ecc71', '#e74c3c'), width=25, alpha=0.7)
ax.set_title('Monthly Excess Returns (Mkt-RF)', fontweight='bold', fontsize=12)
ax.set_ylabel('Return')
ax.axhline(y=0, color='black', linewidth=0.5)
ax.grid(True, alpha=0.3)

# --- Bottom left: Rolling 12-month std of cumulative value ---
ax = axes[1, 0]
rolling_price_std = cumulative_price.rolling(12).std()
ax.plot(rolling_price_std.index, rolling_price_std.values, color='#e74c3c', linewidth=1.2)
ax.set_title('Rolling 12-Month Std Dev of Price Level', fontweight='bold', fontsize=12)
ax.set_ylabel('Std Dev ($)')
ax.grid(True, alpha=0.3)
ax.annotate('Changing level and dispersion\n(assess the model assumptions)', xy=(0.5, 0.85),
            xycoords='axes fraction', ha='center', fontsize=10, color='#c0392b', fontweight='bold')

# --- Bottom right: Rolling 12-month std of returns ---
ax = axes[1, 1]
rolling_ret_std = mkt.rolling(12).std()
ax.plot(rolling_ret_std.index, rolling_ret_std.values, color='#3498db', linewidth=1.2)
ax.set_title('Rolling 12-Month Std Dev of Returns', fontweight='bold', fontsize=12)
ax.set_ylabel('Std Dev')
ax.grid(True, alpha=0.3)
ax.annotate('Time-varying sample volatility\n(not a stationarity proof)', xy=(0.5, 0.85),
            xycoords='axes fraction', ha='center', fontsize=10, color='#2980b9', fontweight='bold')

fig.suptitle('Why We Use Returns, Not Prices', fontsize=14, fontweight='bold', y=1.02)
plt.tight_layout()
plt.show()

print("Rolling dispersion differs between price levels and returns; these plots do not prove stationarity.")
print("This is why these stationary factor regressions use returns. Other financial models can explicitly study nonstationary price levels.")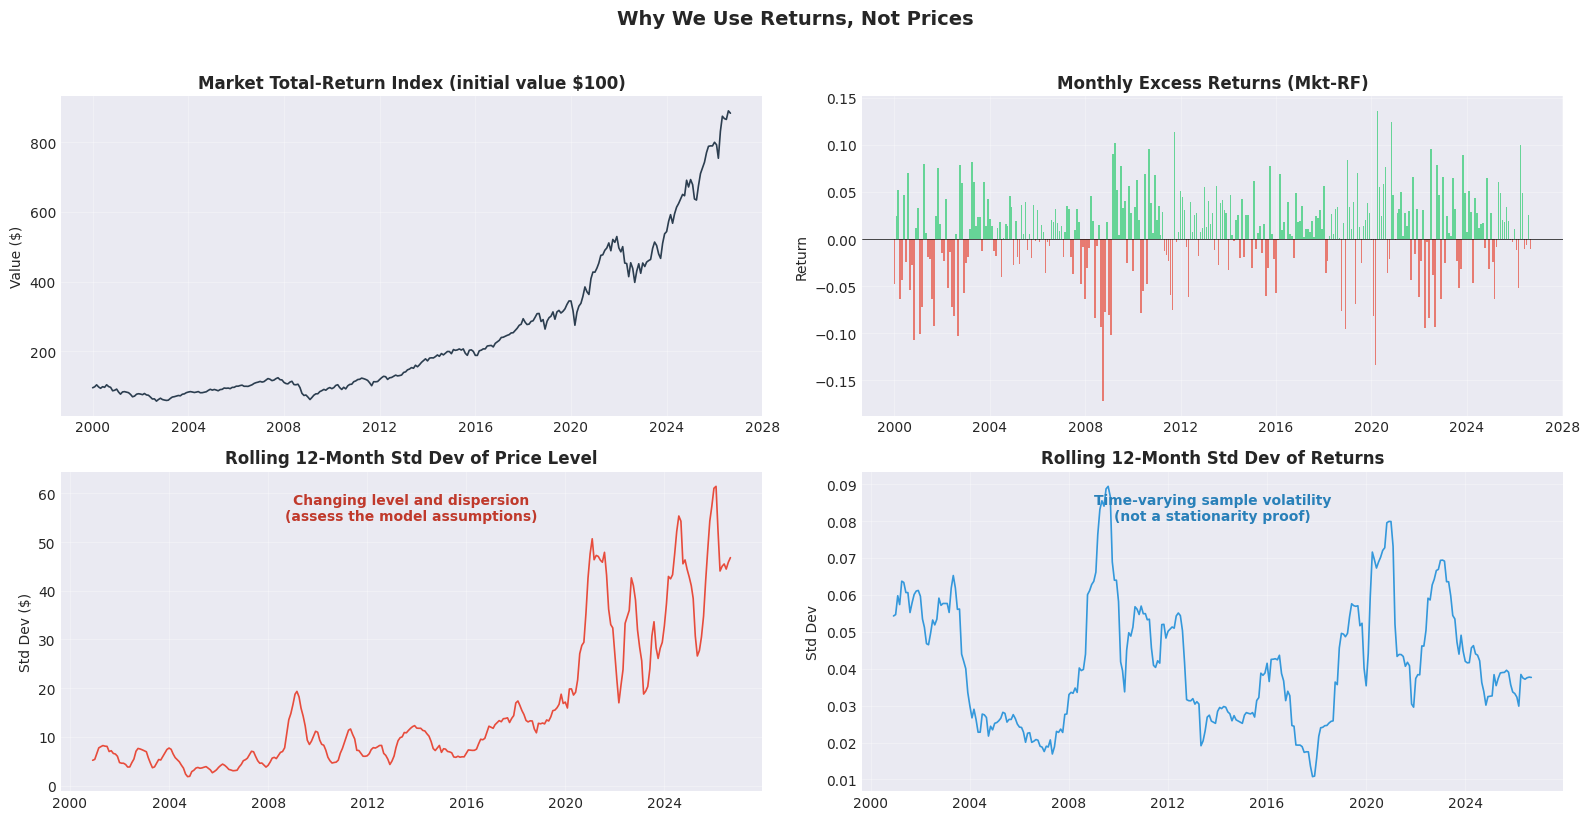
Rolling dispersion differs between price levels and returns; these plots do not prove stationarity.
This is why these stationary factor regressions use returns. Other financial models can explicitly study nonstationary price levels.
Section 2: Stationarity — The Foundation of Time Series Inference
2.1 What Is Stationarity?
A time series is (weakly / covariance) stationary if:
Constant mean: for all
Constant variance: for all
Autocovariance depends only on lag: for all
In words: the statistical properties of the process do not change depending on when you observe it. A stationary process “looks the same” whether you examine it in 2005 or 2019.
There is also a stronger notion — strict (strong) stationarity — which requires that the entire joint distribution of is invariant to time shifts. For most financial applications, weak stationarity is sufficient.
2.2 Why Stationarity Matters
Stationarity is not just a mathematical nicety — it is essential for inference:
| What we want to do | Why stationarity is needed |
|---|---|
| Estimate a mean | If changes over time, “the mean” is not well-defined. estimates... what? |
| Estimate a variance | If drifts, the sample variance does not converge to anything meaningful |
| Apply the CLT | The stationary time-series CLT used here needs stable moments and weak dependence; other CLTs allow non-identically distributed data |
| Run a regression | OLS assumes the coefficients are constant. If the relationship between and changes over time, is an average of a moving target |
| Use Newey-West | The autocovariance structure must be constant over time; otherwise the HAC estimator has no fixed target |
The bottom line: Nearly every statistical tool we use in the Fama-French tutorials assumes either weak stationarity or a close approximation to it over the sample at hand. If returns were strongly non-stationary, our regressions, t-statistics, and p-values would not have a stable interpretation.
2.3 Are Stock Returns Stationary?
Approximately, yes — and this is why financial econometrics works at all.
Prices are non-stationary (they trend, they have unit roots).
Returns are approximately stationary: their mean and autocovariance structure are roughly constant over long periods.
The qualification “approximately” is important:
Volatility is not perfectly constant — it clusters (Section 4). But the unconditional variance can still be constant even if the conditional variance fluctuates (this is the GARCH framework).
The mean return may shift slowly over very long horizons (structural breaks, changing risk premia). Even within 10–25 year windows, structural changes can matter and should be investigated.
2.4 Testing for Stationarity: The Augmented Dickey-Fuller Test
The Augmented Dickey-Fuller (ADF) test is the standard tool for detecting non-stationarity. It tests:
: The series has a unit root (non-stationary — behaves like a random walk)
: The series is stationary
The test fits a regression:
and tests (unit root) vs. (stationary / mean-reverting).
If the -value is small, we reject the null of a unit root. That is evidence consistent with stationarity, but it is not a complete proof of weak stationarity.
# ============================================================================
# Section 2: Stationarity tests — prices vs. returns
# ============================================================================

print("AUGMENTED DICKEY-FULLER TESTS FOR STATIONARITY")
print("=" * 65)
print(f"{'Series':<30} {'ADF Stat':>10} {'p-value':>10} {'Reject unit root?':>18}")
print("-" * 65)

# Test the cumulative "price" series
adf_price = adfuller(cumulative_price.dropna(), autolag='AIC')
print(f"{'Cumulative price level':<30} {adf_price[0]:>10.4f} {adf_price[1]:>10.4f} {'NO' if adf_price[1] > 0.05 else 'YES':>14}")

# Test each factor's returns
for col in ['Mkt-RF', 'SMB', 'HML']:
    adf_result = adfuller(ff3[col].dropna(), autolag='AIC')
    stationary = 'YES' if adf_result[1] < 0.05 else 'NO'
    print(f"{col + ' (returns)':<30} {adf_result[0]:>10.4f} {adf_result[1]:>10.4f} {stationary:>14}")

# Also test log of cumulative price
log_price = np.log(cumulative_price)
adf_log = adfuller(log_price.dropna(), autolag='AIC')
print(f"{'Log(price level)':<30} {adf_log[0]:>10.4f} {adf_log[1]:>10.4f} {'NO' if adf_log[1] > 0.05 else 'YES':>14}")

print("A rejection is evidence against a unit root under the chosen ADF specification.")
print("Failure to reject does not prove a unit root. Neither outcome establishes")
print("constant variance, mixing, exogeneity, or validity of a particular regression.")
AUGMENTED DICKEY-FULLER TESTS FOR STATIONARITY
=================================================================
Series ADF Stat p-value Reject unit root?
-----------------------------------------------------------------
Cumulative price level 3.5467 1.0000 NO
Mkt-RF (returns) -17.3409 0.0000 YES
SMB (returns) -15.1095 0.0000 YES
HML (returns) -15.8023 0.0000 YES
Log(price level) 1.1736 0.9958 NO
A rejection is evidence against a unit root under the chosen ADF specification.
Failure to reject does not prove a unit root. Neither outcome establishes
constant variance, mixing, exogeneity, or validity of a particular regression.
Section 3: Autocorrelation — Does Today Predict Tomorrow?
3.1 The Autocorrelation Function (ACF)
For a stationary series, the autocorrelation at lag is:
This measures the linear dependence between observations periods apart. Key values:
always (a series is perfectly correlated with itself)
For i.i.d. data, for all
The sample ACF at lag is:
3.2 The Partial Autocorrelation Function (PACF)
The PACF at lag measures the correlation between and after removing the linear effects of the intervening observations .
If the PACF cuts off after lag , this suggests an AR() model: the current observation depends directly on only the last observations.
If the ACF cuts off after lag , this suggests an MA() model.
3.3 What Does This Mean for Returns?
Under a model with constant conditional expected returns, demeaned return innovations are a martingale difference sequence. Weak-form market efficiency alone does not imply this, because expected risk compensation can vary. In that simplified model:
for all (returns are a white noise or a martingale difference sequence)
The ACF of returns should be flat — no significant spikes after lag 0
In practice, monthly returns show very small autocorrelations — typically — consistent with near-efficiency. But even small autocorrelations can matter for standard errors, which is why we use Newey-West.
3.4 The Ljung-Box Test
The Ljung-Box test is a formal test for whether any of the first autocorrelations are significantly different from zero:
: The first autocorrelations are all zero (not a test of independence)
: At least one autocorrelation is nonzero
This is important: even if no individual looks large, there might be a collective pattern.
Source
# ============================================================================
# Section 3: Autocorrelation analysis of Fama-French factor returns
# ============================================================================

fig, axes = plt.subplots(3, 3, figsize=(18, 12))

factors = ['Mkt-RF', 'SMB', 'HML']
colors = ['#2c3e50', '#e74c3c', '#2ecc71']
max_lags = 24

for i, (factor, color) in enumerate(zip(factors, colors)):
    series = ff3[factor].dropna()

    # --- Column 1: Time series ---
    ax = axes[i, 0]
    ax.plot(series.index, series.values, color=color, linewidth=0.8, alpha=0.8)
    ax.axhline(y=0, color='gray', linewidth=0.5)
    ax.set_title(f'{factor} — Monthly Returns', fontweight='bold', fontsize=11)
    ax.set_ylabel('Return')
    ax.grid(True, alpha=0.3)

    # --- Column 2: ACF ---
    ax = axes[i, 1]
    acf_vals = acf(series, nlags=max_lags, fft=True)
    conf_bound = 1.96 / np.sqrt(len(series))
    ax.bar(range(max_lags + 1), acf_vals, color=color, width=0.6, alpha=0.7)
    ax.axhline(y=conf_bound, color='red', linestyle='--', linewidth=1, label=f'95% CI (±{conf_bound:.3f})')
    ax.axhline(y=-conf_bound, color='red', linestyle='--', linewidth=1)
    ax.axhline(y=0, color='black', linewidth=0.5)
    ax.set_title(f'{factor} — ACF', fontweight='bold', fontsize=11)
    ax.set_xlabel('Lag (months)')
    ax.set_ylabel('Autocorrelation')
    ax.legend(fontsize=8)
    ax.set_ylim(-0.25, 1.05)
    ax.grid(True, alpha=0.3)

    # --- Column 3: PACF ---
    ax = axes[i, 2]
    pacf_vals = pacf(series, nlags=max_lags, method='ywm')
    ax.bar(range(max_lags + 1), pacf_vals, color=color, width=0.6, alpha=0.7)
    ax.axhline(y=conf_bound, color='red', linestyle='--', linewidth=1, label=f'95% CI')
    ax.axhline(y=-conf_bound, color='red', linestyle='--', linewidth=1)
    ax.axhline(y=0, color='black', linewidth=0.5)
    ax.set_title(f'{factor} — PACF', fontweight='bold', fontsize=11)
    ax.set_xlabel('Lag (months)')
    ax.set_ylabel('Partial Autocorrelation')
    ax.legend(fontsize=8)
    ax.set_ylim(-0.25, 1.05)
    ax.grid(True, alpha=0.3)

fig.suptitle('Autocorrelation Structure of Fama-French Factor Returns',
             fontsize=14, fontweight='bold', y=1.02)
plt.tight_layout()
plt.show()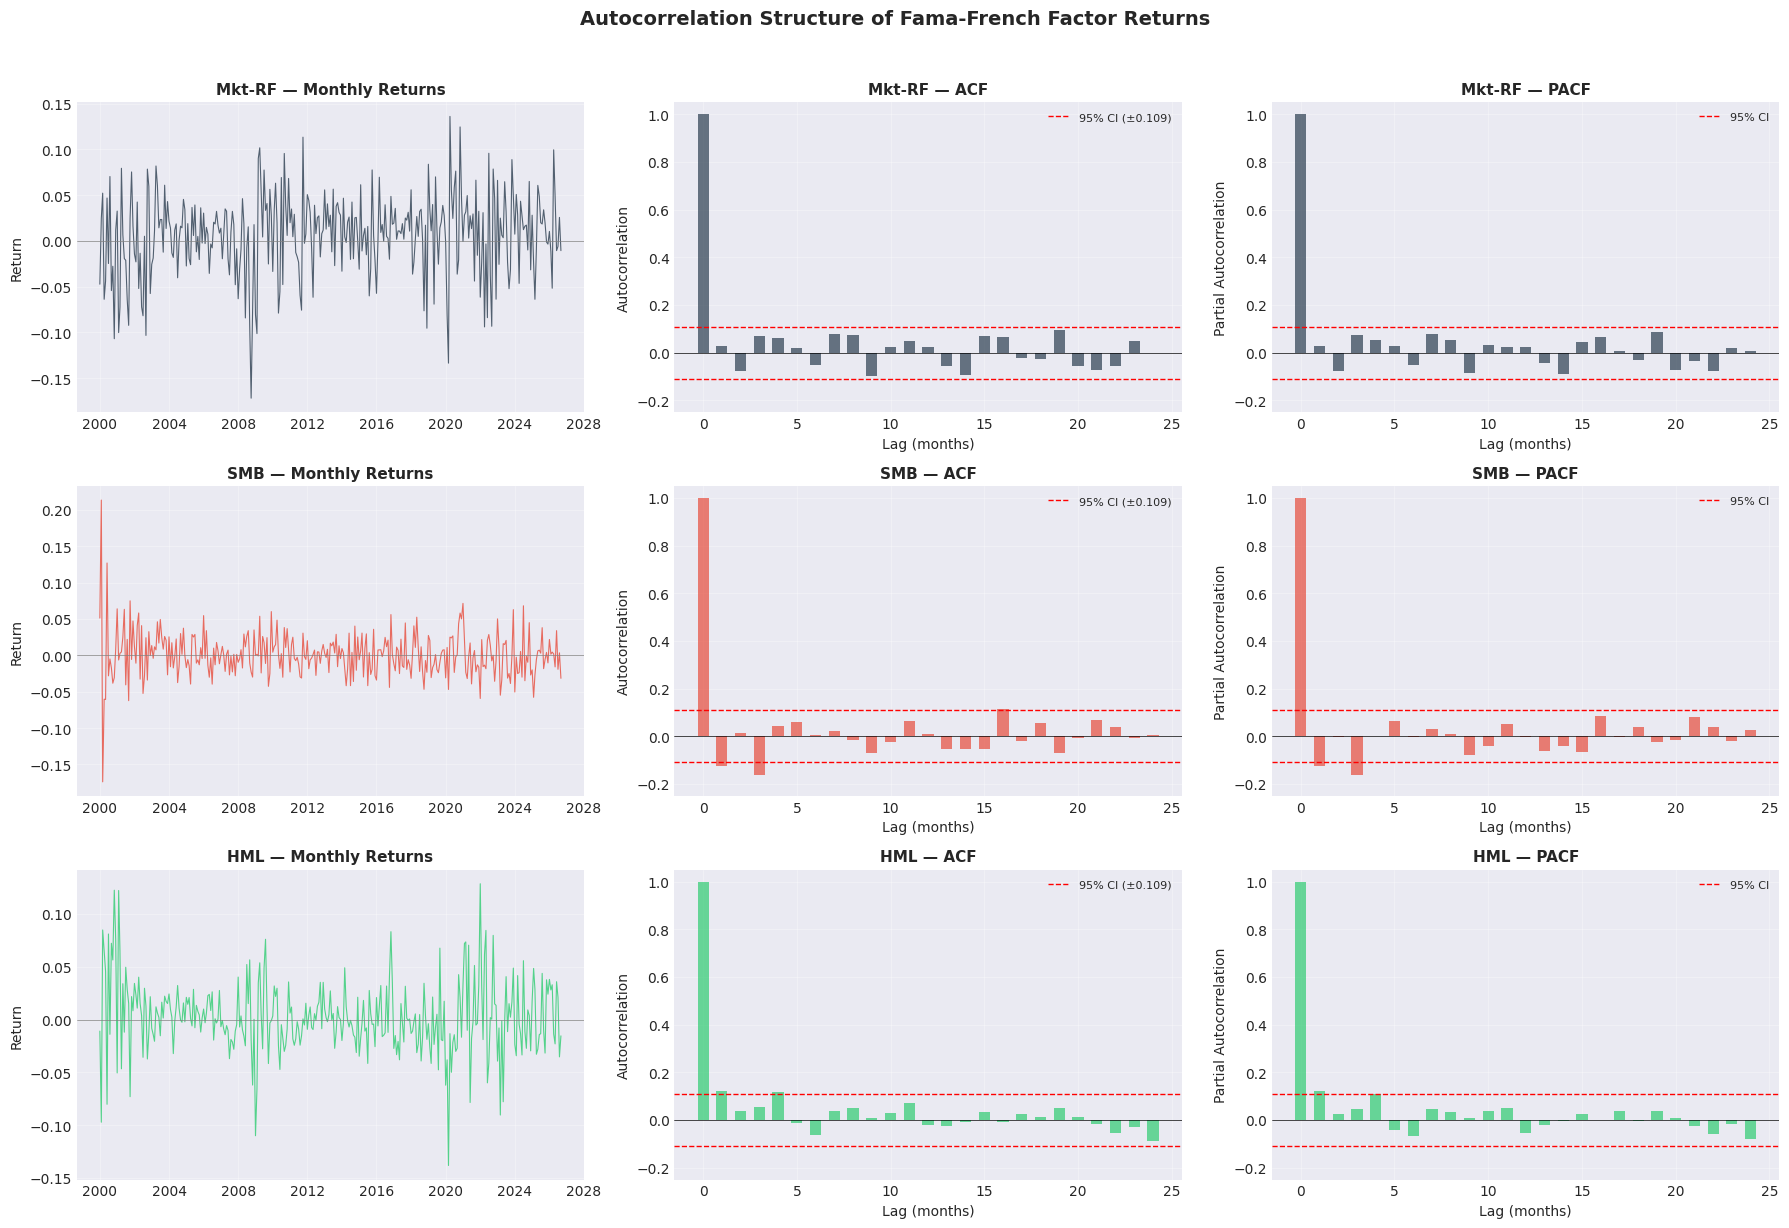
# ============================================================================
# Ljung-Box tests for autocorrelation in returns
# ============================================================================

print("LJUNG-BOX TESTS FOR AUTOCORRELATION IN RETURNS")
print("=" * 70)
print("H0: No autocorrelation up to lag m")
print("H1: At least one autocorrelation is nonzero\n")

for factor in ['Mkt-RF', 'SMB', 'HML']:
    series = ff3[factor].dropna()
    print(f"--- {factor} ---")

    # Print first few autocorrelations
    acf_vals = acf(series, nlags=6, fft=True)
    print(f"  ACF lags 1-6: {', '.join(f'{a:.4f}' for a in acf_vals[1:7])}")

    # Ljung-Box at different lag horizons
    for m in [6, 12, 24]:
        lb = acorr_ljungbox(series, lags=m, return_df=True)
        q_stat = lb['lb_stat'].iloc[-1]
        p_val = lb['lb_pvalue'].iloc[-1]
        sig = '***' if p_val < 0.01 else '**' if p_val < 0.05 else '*' if p_val < 0.10 else ''
        print(f"  Q({m:2d}) = {q_stat:8.3f},  p-value = {p_val:.4f} {sig}")
    print()

print("INTERPRETATION:")
print("- Mkt-RF: Individual autocorrelations are tiny. Ljung-Box may or may")
print("  not reject — even small autocorrelations can be jointly significant.")
print("- SMB and HML: May show slightly more autocorrelation (factor portfolios")
print("  are rebalanced less frequently than individual stocks).")
print("\nEven when autocorrelation is small, Newey-West corrects for it.")
print("The key insight: returns are NEARLY uncorrelated but NOT independent.")
LJUNG-BOX TESTS FOR AUTOCORRELATION IN RETURNS
======================================================================
H0: No autocorrelation up to lag m
H1: At least one autocorrelation is nonzero
--- Mkt-RF ---
ACF lags 1-6: 0.0299, -0.0770, 0.0696, 0.0620, 0.0209, -0.0517
Q( 6) = 6.077, p-value = 0.4146
Q(12) = 14.097, p-value = 0.2946
Q(24) = 29.276, p-value = 0.2099
--- SMB ---
ACF lags 1-6: -0.1258, 0.0120, -0.1622, 0.0412, 0.0586, 0.0074
Q( 6) = 15.454, p-value = 0.0170 **
Q(12) = 18.853, p-value = 0.0921 *
Q(24) = 31.413, p-value = 0.1422
--- HML ---
ACF lags 1-6: 0.1200, 0.0387, 0.0537, 0.1195, -0.0143, -0.0620
Q( 6) = 12.093, p-value = 0.0599 *
Q(12) = 15.680, p-value = 0.2064
Q(24) = 21.739, p-value = 0.5948
INTERPRETATION:
- Mkt-RF: Individual autocorrelations are tiny. Ljung-Box may or may
not reject — even small autocorrelations can be jointly significant.
- SMB and HML: May show slightly more autocorrelation (factor portfolios
are rebalanced less frequently than individual stocks).
Even when autocorrelation is small, Newey-West corrects for it.
The key insight: returns are NEARLY uncorrelated but NOT independent.
Section 4: Volatility Clustering — The Hidden Dependence
4.1 The Key Distinction: Uncorrelated ≠ Independent
Section 3 showed that factor returns have very weak autocorrelation: for all . A naive conclusion might be: “Returns are independent, so the classical CLT applies and we don’t need Newey-West.”
This would be wrong.
Uncorrelated means — there is no linear dependence between returns at different times. But independent means no dependence of any kind — not even in higher moments.
The crucial observation: while , we typically see:
Large returns (of either sign) tend to be followed by large returns, and small returns by small returns. This is volatility clustering — the variance of returns changes over time in a persistent way.
4.2 Conditional vs. Unconditional Variance
This introduces a distinction that is crucial for understanding when standard errors need correction:
Unconditional variance: — a single number, constant over time (by stationarity)
Conditional variance: — varies over time, depending on recent history
A GARCH(1,1) model makes this explicit:
Even though fluctuates period-to-period, its long-run average is constant. So the series is still weakly stationary — the unconditional variance exists — but the conditional variance changes.
4.3 Why This Matters for Standard Errors
Volatility clustering in the return series is a warning sign that a regression run on those data can easily inherit conditional heteroscedasticity in its residuals, even if the series is stationary in the unconditional sense.
This violates the “constant variance” assumption of classical OLS. Under appropriate exogeneity and regularity conditions, the consequences are:
| OLS coefficients () | Classic standard errors | Newey-West standard errors | |
|---|---|---|---|
| Affected? | No — OLS is still unbiased and consistent | Yes — can be too small or too large | No — designed for this |
OLS coefficients remain valid (unbiased, consistent) regardless of heteroscedasticity. But the standard errors — and therefore the t-statistics, p-values, and confidence intervals — can be badly wrong with classic OLS. This is exactly what heteroscedasticity-consistent (HC) and HAC (Newey-West) standard errors fix.
4.4 The ARCH Test
To formally test for volatility clustering, we use Engle’s ARCH test (1982). The idea is simple: regress the squared residuals on their own lags:
The null hypothesis is:
If we reject , the squared residuals are predictable from their own past — evidence of ARCH effects, i.e. volatility clustering.
In a pure time-series setting like this section, those residuals come from an auxiliary mean equation for the series itself. In a Fama-French regression, the same logic gets applied later to the regression residuals, not directly to raw returns.
Source
# ============================================================================
# Section 4: Volatility clustering — the smoking gun
# ============================================================================

fig, axes = plt.subplots(3, 3, figsize=(18, 12))

factors = ['Mkt-RF', 'SMB', 'HML']
colors = ['#2c3e50', '#e74c3c', '#2ecc71']

for i, (factor, color) in enumerate(zip(factors, colors)):
    series = ff3[factor].dropna()
    sq_series = series ** 2
    abs_series = series.abs()

    # --- Column 1: Absolute returns (shows clustering visually) ---
    ax = axes[i, 0]
    ax.bar(series.index, abs_series.values, color=color, width=25, alpha=0.6)
    ax.plot(series.index, abs_series.rolling(12).mean().values, color='black',
            linewidth=2, label='12-month MA')
    ax.set_title(f'{factor} — |Returns| (Volatility Proxy)', fontweight='bold', fontsize=11)
    ax.set_ylabel('|Return|')
    ax.legend(fontsize=8)
    ax.grid(True, alpha=0.3)

    # --- Column 2: ACF of returns (should be near zero) ---
    ax = axes[i, 1]
    acf_ret = acf(series, nlags=20, fft=True)
    acf_sq = acf(sq_series, nlags=20, fft=True)
    conf = 1.96 / np.sqrt(len(series))
    lags = np.arange(1, 21)
    ax.bar(lags - 0.15, acf_ret[1:21], width=0.3, color=color, alpha=0.7, label='Returns')
    ax.bar(lags + 0.15, acf_sq[1:21], width=0.3, color='orange', alpha=0.7, label='Squared returns')
    ax.axhline(y=conf, color='red', linestyle='--', linewidth=1)
    ax.axhline(y=-conf, color='red', linestyle='--', linewidth=1)
    ax.axhline(y=0, color='black', linewidth=0.5)
    ax.set_title(f'{factor} — ACF: Returns vs Squared', fontweight='bold', fontsize=11)
    ax.set_xlabel('Lag')
    ax.set_ylabel('Autocorrelation')
    ax.legend(fontsize=8)
    ax.set_ylim(-0.2, 0.5)
    ax.grid(True, alpha=0.3)

    # --- Column 3: Scatter of |X_t| vs |X_{t-1}| ---
    ax = axes[i, 2]
    ax.scatter(abs_series.iloc[:-1].values, abs_series.iloc[1:].values,
              alpha=0.4, s=20, color=color)
    # Fit a line
    slope, intercept, r, p, se = stats.linregress(abs_series.iloc[:-1], abs_series.iloc[1:])
    x_line = np.linspace(0, abs_series.max(), 100)
    ax.plot(x_line, intercept + slope * x_line, 'r-', linewidth=2,
            label=f'Descriptive r = {r:.3f}')
    ax.set_title(f'{factor} — |X_t| vs |X_{{t-1}}|', fontweight='bold', fontsize=11)
    ax.set_xlabel('|Return| at t-1')
    ax.set_ylabel('|Return| at t')
    ax.legend(fontsize=9)
    ax.grid(True, alpha=0.3)

fig.suptitle('Volatility Clustering: Comparing Return and Squared-Return Dependence',
             fontsize=14, fontweight='bold', y=1.02)
plt.tight_layout()
plt.show()

print("KEY FINDING:")
print("- Left column: Absolute returns cluster — volatile periods are followed by volatile periods.")
print("- Middle column: Returns themselves have near-zero ACF, but SQUARED returns are")
print("  strongly autocorrelated. This is the signature of volatility clustering.")
print("- Right column: |X_t| and |X_{t-1}| are positively correlated — large moves")
print("  predict large moves (of either sign).")
print("\nUncorrelated does not imply independent. HC or HAC depends on regression-score covariance.")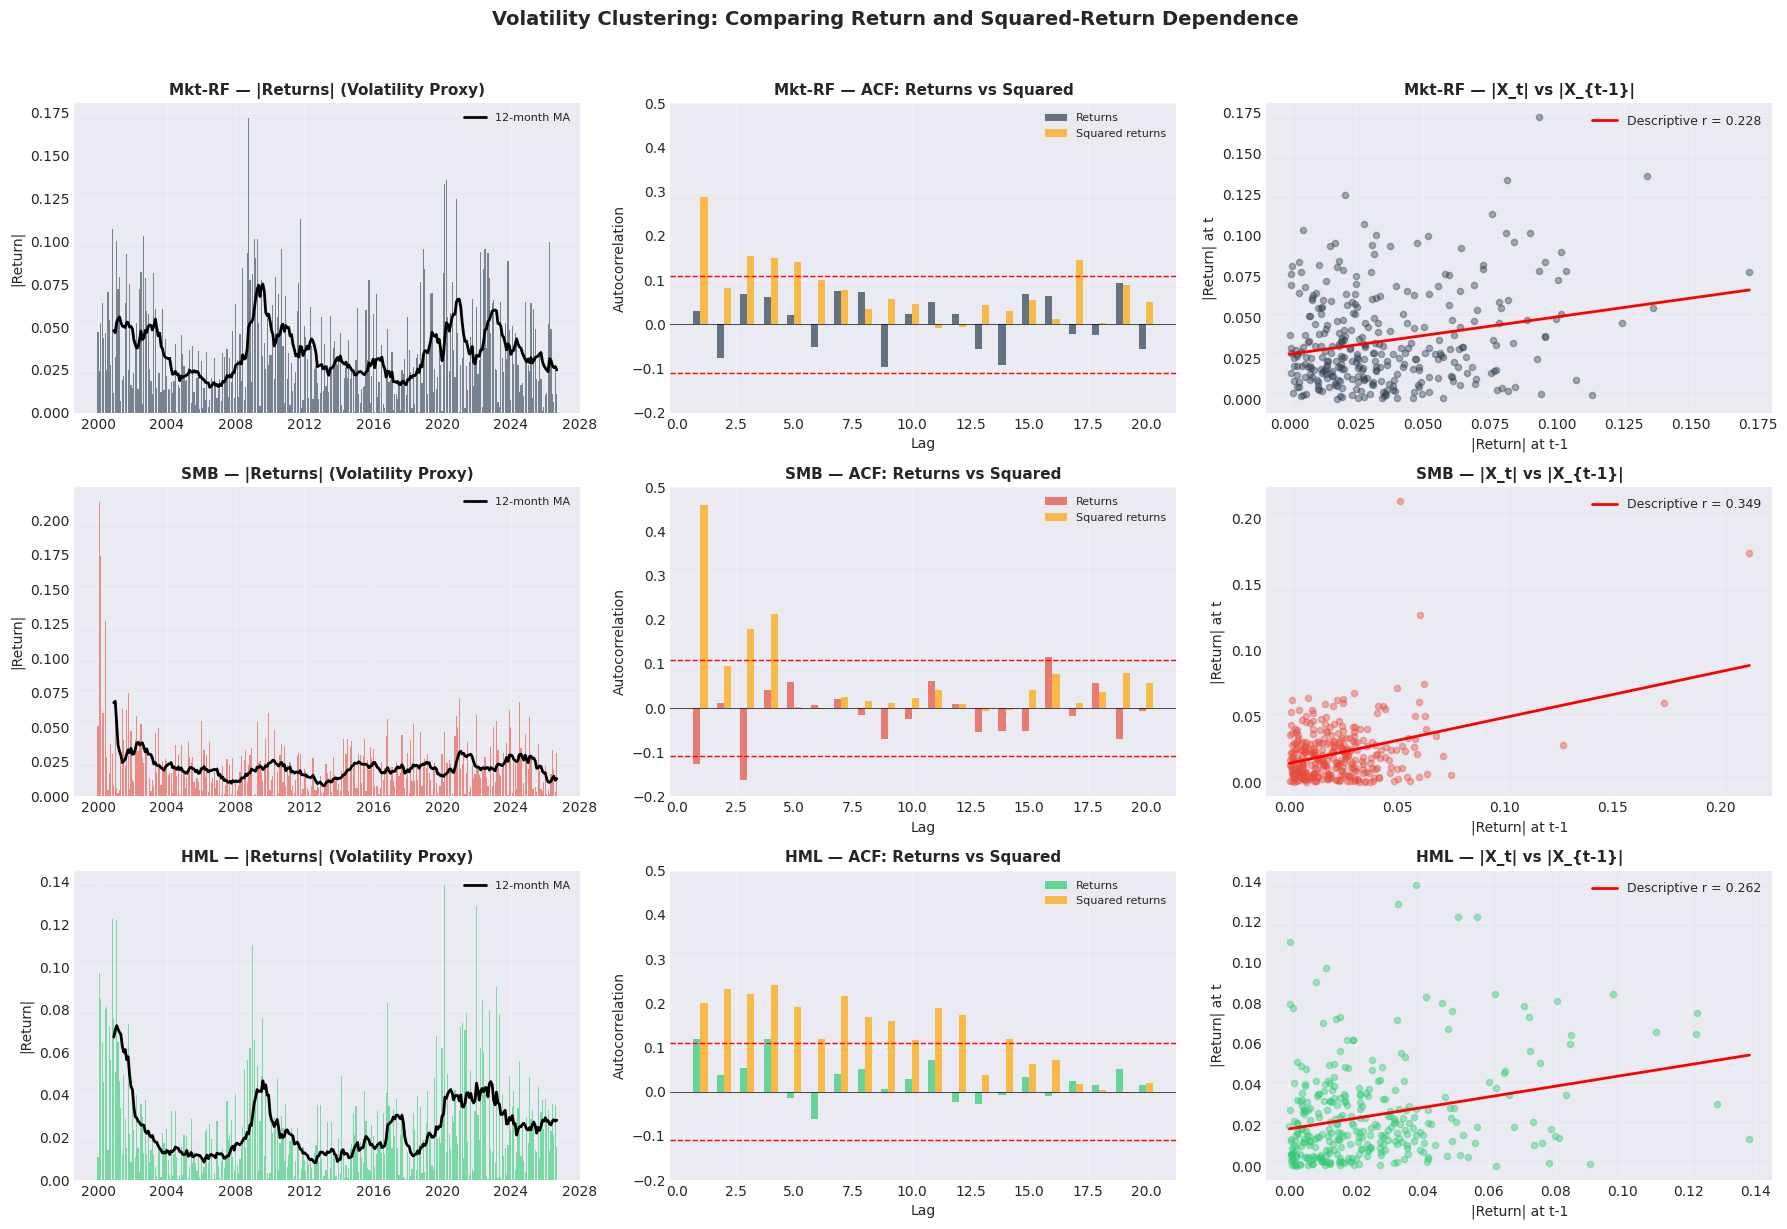
KEY FINDING:
- Left column: Absolute returns cluster — volatile periods are followed by volatile periods.
- Middle column: Returns themselves have near-zero ACF, but SQUARED returns are
  strongly autocorrelated. This is the signature of volatility clustering.
- Right column: |X_t| and |X_{t-1}| are positively correlated — large moves
  predict large moves (of either sign).

Uncorrelated does not imply independent. HC or HAC depends on regression-score covariance.
# ============================================================================
# Formal ARCH test for conditional heteroscedasticity
# ============================================================================
from statsmodels.stats.diagnostic import het_arch

print("ENGLE'S ARCH TEST FOR CONDITIONAL HETEROSCEDASTICITY")
print("=" * 65)
print("H0: No ARCH effects (constant conditional variance)")
print("H1: ARCH effects present (volatility clustering)\n")

print(f"{'Factor':<12} {'Lags':>6} {'LM Stat':>10} {'p-value':>10} {'Result':>16}")
print("-" * 65)

for factor in ['Mkt-RF', 'SMB', 'HML']:
    series = ff3[factor].dropna().values
    for nlags in [1, 6, 12]:
        lm_stat, lm_pval, fstat, f_pval = het_arch(series - series.mean(), nlags=nlags, ddof=1)
        sig = 'ARCH effects ***' if lm_pval < 0.01 else 'ARCH effects **' if lm_pval < 0.05 else 'ARCH effects *' if lm_pval < 0.10 else 'Not rejected'
        print(f"{factor:<12} {nlags:>6} {lm_stat:>10.3f} {lm_pval:>10.4f} {sig:>16}")
    print()

print("These tests use residuals from a constant-mean model, after demeaning.")
print("Small p-values support ARCH-type dependence at the tested lags; large")
print("p-values do not prove constant variance. Diagnose factor-model residuals separately.")
ENGLE'S ARCH TEST FOR CONDITIONAL HETEROSCEDASTICITY
=================================================================
H0: No ARCH effects (constant conditional variance)
H1: ARCH effects present (volatility clustering)
Factor Lags LM Stat p-value Result
-----------------------------------------------------------------
Mkt-RF 1 31.613 0.0000 ARCH effects ***
Mkt-RF 6 41.153 0.0000 ARCH effects ***
Mkt-RF 12 46.202 0.0000 ARCH effects ***
SMB 1 69.027 0.0000 ARCH effects ***
SMB 6 7.532 0.2745 Not rejected
SMB 12 28.152 0.0053 ARCH effects ***
HML 1 11.915 0.0006 ARCH effects ***
HML 6 36.453 0.0000 ARCH effects ***
HML 12 37.583 0.0002 ARCH effects ***
These tests use residuals from a constant-mean model, after demeaning.
Small p-values support ARCH-type dependence at the tested lags; large
p-values do not prove constant variance. Diagnose factor-model residuals separately.
4.5 From ARCH to GARCH(1,1): Modelling Volatility Dynamics
The ARCH test tells us volatility clustering exists, but it does not tell us how to model it. The GARCH(1,1) model (Bollerslev, 1986) is the workhorse specification:
where:
is the conditional variance at time (the variance you would forecast given information up to )
is a constant (long-run intercept)
captures the shock impact: a large (yesterday’s surprise) raises today’s variance
captures persistence: today’s variance inherits a fraction of yesterday’s variance
Finite-variance (covariance) stationarity requires for unit-variance innovations; strict stationarity has a weaker log-moment condition
Why does this matter for Fama-French regressions?
OLS coefficients are still unbiased and consistent — GARCH affects the error variance, not the expected value of the errors.
Classic standard errors are wrong — they assume (constant). Since fluctuates, classic SEs are biased.
Newey-West fixes this — the HAC estimator allows each to differ (the “heteroscedasticity” part of “HAC”), so GARCH-type patterns do not invalidate inference.
Unconditional variance still exists — if , the unconditional variance is , and the process is strictly stationary. Mixing additionally depends on conditions on the innovation distribution and the model parameters.
Typical estimates for monthly US equity returns: , , with — high persistence but strictly below 1.
Note: We do not fit a GARCH model here because our goal is running Fama-French regressions, not forecasting volatility. An ARCH rejection is evidence of conditional variance dependence, not confirmation of a particular GARCH model. HC can accommodate heteroscedasticity when regression scores are serially uncorrelated; HAC also allows score autocorrelation under its regularity conditions.
Section 5: Ergodicity and Mixing — Why a Single Time Path Is Enough
5.1 The Ergodicity Problem
Here is a deep conceptual issue that is often glossed over.
In cross-sectional statistics (e.g., polling 1,000 people), we have many independent draws from a population. The Law of Large Numbers and the CLT are straightforward: as the sample size grows, the sample mean converges to the population mean.
In time series, we have a single realization of the process. The current sample runs from 2000 to the latest released month — we cannot rewind history and observe another draw from the probability measure. All observations come from one path.
So why does converge to ? This is not obvious — the Law of Large Numbers was stated for independent draws.
5.2 Ergodicity: Time Averages = Ensemble Averages
A stationary process is ergodic if time averages converge to population averages:
and more generally, any function of has its time average converge to its expectation.
Intuition: If the process “forgets” its past quickly enough, then observations far apart in time are effectively independent, and we can treat them like multiple draws from the same distribution.
Mean convergence is weaker than mixing. Summable autocovariances give mean-square convergence of the sample mean under covariance stationarity, but do not establish full ergodicity or a CLT. The stronger mixing-rate and moment conditions in Notebook 1, Section 3.5 are sufficient for that CLT.
5.3 Mixing: How Fast Does Dependence Decay?
Mixing conditions formalize the idea that “the distant past and the distant future are approximately independent.” A process is -mixing (strongly mixing) if:
In words: events in the far past and events in the far future become independent. The rate at which decays determines which CLT version applies and what lag length Newey-West needs.
For financial returns: Short-memory ARMA/GARCH models can satisfy strong-mixing conditions under additional regularity assumptions. Observed ACFs are diagnostics of linear dependence, not estimates or tests of the mixing coefficients. Neither an ADF rejection nor a visually small ACF proves a mixing CLT applies.
5.4 What Could Go Wrong: Non-Ergodic Processes
Not all processes are ergodic. Important counterexamples:
| Process | Ergodic? | Problem |
|---|---|---|
| Random walk () | No | Variance grows without bound; no stable mean to converge to |
| Structural break (mean shifts from to at unknown time ) | No | converges to a weighted average of and , not “the” mean |
| Unit root in volatility | No | Unconditional variance does not exist |
| Stationary GARCH returns | Yes | Conditional variance changes, but the process still forgets its past fast enough |
ADF examines one kind of nonstationarity. It cannot rule out structural breaks, infinite variance or stationary non-ergodic processes. For example, with a fixed random component is stationary but not ergodic for the mean.
Source
# ============================================================================
# Section 5: Visualizing the decay of dependence (mixing)
# ============================================================================

fig, axes = plt.subplots(1, 2, figsize=(16, 5.5))

max_lag = 60
mkt = ff3['Mkt-RF'].dropna()

# --- Left: ACF of returns vs squared returns vs absolute returns ---
ax = axes[0]
acf_ret = acf(mkt, nlags=max_lag, fft=True)
acf_sq = acf(mkt**2, nlags=max_lag, fft=True)
acf_abs = acf(mkt.abs(), nlags=max_lag, fft=True)

lags = np.arange(1, max_lag + 1)
ax.plot(lags, acf_ret[1:], 'o-', color='#2c3e50', markersize=3, linewidth=1.2, label='Returns')
ax.plot(lags, acf_sq[1:], 's-', color='#e74c3c', markersize=3, linewidth=1.2, label='Squared returns')
ax.plot(lags, acf_abs[1:], '^-', color='#e67e22', markersize=3, linewidth=1.2, label='Absolute returns')
ax.axhline(y=1.96/np.sqrt(len(mkt)), color='gray', linestyle='--', linewidth=1, alpha=0.7)
ax.axhline(y=-1.96/np.sqrt(len(mkt)), color='gray', linestyle='--', linewidth=1, alpha=0.7)
ax.axhline(y=0, color='black', linewidth=0.5)
ax.set_title('Autocorrelation Decay: Returns vs Volatility (Mkt-RF)', fontweight='bold', fontsize=12)
ax.set_xlabel('Lag (months)')
ax.set_ylabel('Autocorrelation')
ax.legend(fontsize=9)
ax.grid(True, alpha=0.3)

# --- Right: Cumulative sum of absolute autocovariances (for long-run variance) ---
ax2 = axes[1]
n_obs = len(mkt)
gamma_0 = mkt.var()
cum_abs_acov = [gamma_0]
for k in range(1, max_lag + 1):
    gamma_k = np.mean((mkt.values[k:] - mkt.mean()) * (mkt.values[:-k] - mkt.mean()))
    cum_abs_acov.append(cum_abs_acov[-1] + 2 * abs(gamma_k))

ax2.plot(range(max_lag + 1), cum_abs_acov, 'b-', linewidth=2, label='$\\gamma_0 + 2\\sum|\\gamma_k|$')
ax2.axhline(y=gamma_0, color='red', linestyle='--', linewidth=1.5, label=f'$\\gamma_0$ = {gamma_0:.6f} (classical var)')
ax2.set_title('Cumulation of Absolute Autocovariances (Mkt-RF)', fontweight='bold', fontsize=12)
ax2.set_xlabel('Maximum lag included')
ax2.set_ylabel('Cumulative sum')
ax2.legend(fontsize=9)
ax2.grid(True, alpha=0.3)

fig.suptitle('Dependence Diagnostics — Not a Proof of Mixing',
             fontsize=14, fontweight='bold', y=1.02)
plt.tight_layout()
plt.show()

print("ACFs describe linear dependence; they cannot prove strong mixing.")
print("The right panel sums ABSOLUTE autocovariances. It is not the long-run variance,")
print("which uses signed autocovariances and may be above or below gamma_0.")
print("Sampling noise makes absolute sample sums rise even for independent data.")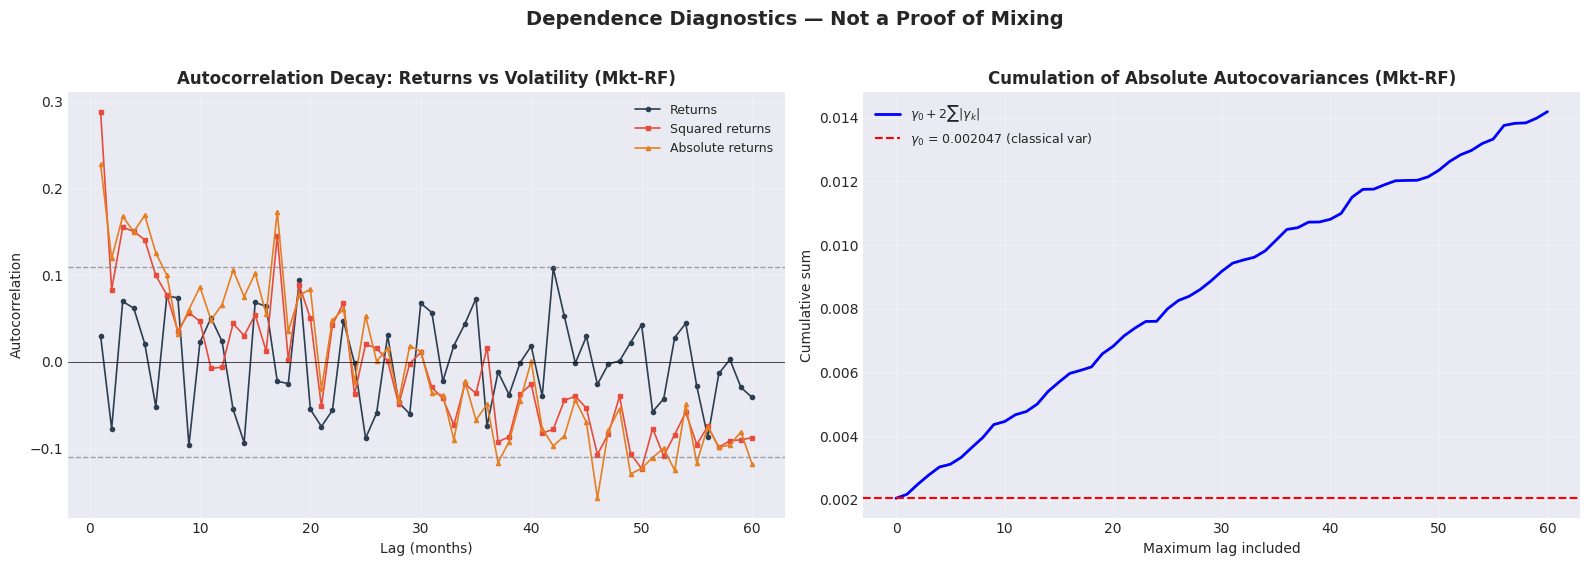
ACFs describe linear dependence; they cannot prove strong mixing.
The right panel sums ABSOLUTE autocovariances. It is not the long-run variance,
which uses signed autocovariances and may be above or below gamma_0.
Sampling noise makes absolute sample sums rise even for independent data.
Section 6: Summary — What Fama-French Regressions Actually Require
6.1 The Assumption Stack
When you run a Fama-French regression like:
it is crucial to separate two objects:
The raw return and factor series studied in Sections 2-5
The regression errors that remain after projecting returns on the factors
Sections 2-5 tell us whether the time-series environment looks compatible with modern asymptotic theory. They do not by themselves prove that the regression residuals satisfy the same properties. Residual-specific assumptions must be checked after fitting the model.
| Assumption | What it means | Needed for | Where assessed | What this notebook establishes |
|---|---|---|---|---|
| Stationarity | Statistical properties of returns/factors do not drift too much over time | LLN, CLT, consistency of | ADF test, visual inspection on returns/factors | Evidence consistent for return series (Section 2) |
| Ergodicity | Time averages converge to population quantities | Consistency of estimators | Strict stationarity + strong mixing is sufficient | Plausible background condition (Section 5) |
| Linearity | True conditional mean is linear in the factors | Correct specification of | Residual plots, Ramsey RESET after fitting the regression | Not tested here |
| No perfect multicollinearity | Factors are not exact linear combinations of each other | is invertible | Correlations, VIF after assembling regressors | Yes in principle, verify in the applied notebook |
| Errors are mean-zero given the factors | Contemporaneous orthogonality supports consistency; finite-sample unbiasedness needs exogeneity conditional on the full design | Not directly testable; economic argument | Assumed/model-based | |
| Homoscedasticity of errors | is constant | Classic OLS standard errors | Breusch-Pagan, ARCH, scale-location plots on residuals | Not determined by return diagnostics alone |
| No autocorrelation of errors | for | Classic OLS standard errors | Durbin-Watson, Ljung-Box, residual ACF | Not determined by return diagnostics alone |
| Normality of errors | is Gaussian | Exact finite-sample t/F inference | Jarque-Bera, QQ plot on residuals | Not determined by return diagnostics alone |
| Mixing / weak dependence | Suitable dependence and moments for regressors and regression scores | Newey-West consistency, mixing CLT | Return/factor dependence here; residual dependence after regression | Return-level evidence is supportive, but residuals must still be checked |
6.2 What Holds, What Fails, and What Saves Us
Working interpretation of the diagnostics:
ADF and rolling moments provide partial evidence about a stationary return model
Weak dependence/mixing remains an assumption requiring more than return ACFs
Volatility clustering and fat tails are realistic features of financial data, so textbook i.i.d. Gaussian intuition is too strong
What this notebook does not establish by itself:
Whether a particular Fama-French regression has homoscedastic residuals
Whether a particular Fama-French regression has serially uncorrelated residuals
Whether a particular Fama-French regression has approximately normal residuals
How the pieces fit together:
The mixing CLT: gives asymptotic normality of under weak dependence, without requiring Gaussian errors
Newey-West HAC standard errors: estimate long-run variance robustly when residuals are heteroscedastic and/or autocorrelated
Residual diagnostics in the applied notebooks: check the assumptions on the fitted residuals rather than on raw returns
6.3 From diagnostics to a regression
For valid Fama-French inference, the key workflow is:
Check that the return/factor environment is roughly stationary and weakly dependent
Fit the regression with an economically sensible factor specification
Diagnose the residuals if you want to talk about
Use Newey-West rather than relying on classical homoscedastic, no-autocorrelation standard errors
This is why the foundations notebook studies raw return behavior first, while the applied regression notebooks revisit the assumptions on fitted residuals. Those are related questions, but they are not the same question.
Reading forward: The 3-Factor Tutorial and the Practical Investing notebook both run residual-based diagnostics after fitting the regression. Read the time-series evidence here as motivation and background, not as a substitute for checking directly.
assumption_status = pd.DataFrame([
    ('Unit root', 'ADF tests above; specification dependent'),
    ('Stable moments / mixing', 'Working assumptions; not established by ACF or ADF'),
    ('Exogeneity', 'Model assumption; residual orthogonality does not prove it'),
    ('Full rank', 'Check each regression design'),
    ('Error variance / serial dependence', 'Check fitted residuals and use suitable covariance estimates'),
    ('Normal errors', 'Needed for classical exact tests, not asymptotic HAC inference'),
], columns=['Condition', 'Assessment'])
print(assumption_status.to_string(index=False))
Condition Assessment
Unit root ADF tests above; specification dependent
Stable moments / mixing Working assumptions; not established by ACF or ADF
Exogeneity Model assumption; residual orthogonality does not prove it
Full rank Check each regression design
Error variance / serial dependence Check fitted residuals and use suitable covariance estimates
Normal errors Needed for classical exact tests, not asymptotic HAC inference
What changes when observations arrive through time?
The examples show why return regressions require more than a cross-sectional formula. Price levels can be non-stationary; returns often provide a more workable object, but their distributions can still change. Weak return autocorrelation can coexist with strong dependence in squared returns. Unit-root tests, residual diagnostics and rolling summaries each examine different features, and none proves every condition required for valid inference.
| Tool | What it helps us investigate | What it does not establish |
|---|---|---|
| ADF test | Evidence against a specified unit-root null | Full stationarity, stable higher moments or mixing |
| Return ACF and Ljung–Box test | Linear serial dependence over selected lags | Independence or market efficiency |
| Squared-return ACF and ARCH test | Conditional variance dependence | A complete volatility model |
| Rolling moments and subsamples | Instability and sensitivity to the observation window | A unique or permanent market regime |
| HAC covariance | Sampling uncertainty under suitable moment and dependence conditions | Exogeneity, correct specification or a reliable small-sample approximation |
These distinctions connect Chapter 1’s asymptotic arguments to the regressions that follow. Non-normal errors alone need not invalidate asymptotic inference; sufficiently well-behaved moments and dependence still matter. Rolling windows can reveal changing estimates, but they also use fewer observations and produce more sampling noise.
Continue to the Fama–French three-factor model. We will ask what market, size and value exposures explain, then use diagnostics and robust covariance without treating them as proof that the model is correct.
Exercises
Exercise 1: Stationarity on a New Series (Hands-On)
Download daily prices for any stock (e.g., AAPL) using yfinance and compute daily log returns.
Run the ADF test on prices and on log returns. Do the results match what we found for Fama-French factors?
Plot the rolling 60-day mean and standard deviation of log returns. Does the series look approximately stationary?
# Starter code:
import yfinance as yf
prices = load_prices('AAPL').loc['2015-01-01':]  # adjusted close
log_returns = np.log(prices / prices.shift(1)).dropna()
Exercise 2: Interpreting ACF Plots (Conceptual)
Consider three processes:
(A) White noise:
(B) AR(1):
(C) Financial returns with GARCH volatility
For each, sketch (or describe) what you expect the ACF of and the ACF of to look like. Then explain why process (C) motivates robust inference, and discuss when HC would suffice even though its return ACF looks similar to (A).
Exercise 3: Effect of Sample Period on ARCH Tests (Hands-On)
Split the Fama-French Mkt-RF data into two sub-periods: 2000–2011 and 2012–latest available.
Run the ARCH test (with 6 lags) on each sub-period separately.
Is volatility clustering stronger in one period than the other? Which period contains the 2008 crisis?
# Starter code:
mkt_early = ff3['Mkt-RF'].loc[:'2011-12']
mkt_late  = ff3['Mkt-RF'].loc['2012-01':]
# Run het_arch(series - series.mean(), nlags=6, ddof=1) in each window
Exercise 4: Mixing Condition in Practice (Discussion)
Why does a finite-sample plot of neither prove summability nor estimate the signed long-run variance? Why is the stationary long-run variance formula inapplicable to a random-walk level?
In your own words, explain why a finite long-run variance is necessary for the Newey-West estimator to be consistent.
If an asset’s returns exhibited a structural break (e.g., a regime change in volatility after 2020), would the mixing condition still hold over the full sample? What practical step could you take?